








筛选结果
12 篇排序
 11:38EN → 简体中文
 Matthew Berman· 2025年6月12日2025 年 6 月 AI 新闻:Magistral、语音模型与图像生成Matthew Berman · Forward FutureMatthew Berman 回顾 Mistral 推理模型、语音和浏览器更新、Meta 与 Scale AI 的相关报道,以及 FLUX.1 Kontext。
 22:05EN → 简体中文Matthew Berman· 2025年6月9日Apple《思考的幻觉》:谜题实验的局限与代码辅助测试Matthew Berman, Ilya Sutskever · Forward FutureMatthew Berman 回顾 Apple 的推理模型实验,并用生成的代码测试另一种解决汉诺塔问题的方法。
 10:09EN → 简体中文Matthew Berman· 2025年5月30日DeepSeek R1 0528:基准提升与两次编程测试Matthew Berman · Forward FutureMatthew Berman 评析 DeepSeek 在 2025 年 5 月推出的推理模型更新,将公布的基准提升与自己的魔方和贪吃蛇编程测试作比较。
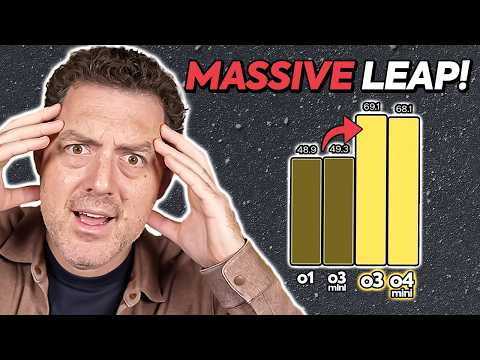 15:46EN → 简体中文Matthew Berman· 2025年4月16日OpenAI o3 与 o4-mini:工具使用、基准测试和首版 Codex CLIMatthew Berman · Forward FutureMatthew Berman 回顾 OpenAI 2025 年 4 月发布的推理模型、科学图像分析演示,以及终端编程智能体的首次亮相。
 9:35EN → 简体中文Matthew Berman· 2025年2月25日Claude 3.7 Sonnet 与 Claude Code:早期编程测试Matthew Berman · Forward FutureMatthew Berman 解读 Anthropic 2025 年发布时的基准,构建由 AI 控制的贪吃蛇游戏,并测试数学和近期信息。
 13:24EN → 简体中文Matthew Berman· 2025年2月18日Grok 3 的 2025 年发布:基准、推理与 DeepSearchMatthew Berman, Elon Musk · Forward FutureMatthew Berman 解读 xAI 的发布图表、历史用户偏好排行榜和早期产品演示。
 18:05EN → 简体中文Matthew Berman· 2025年2月16日OpenAI 编程竞赛研究:o1-ioi、o3 与结果的边界Matthew Berman, Sam Altman · Forward FutureMatthew Berman 解读 OpenAI 2025 年关于强化学习和编程竞赛的论文。模型在研究的基准上表现出色,但结果不能证明 AGI,也不意味着模型开发不再需要人。
 9:58EN → 简体中文Matthew Berman· 2025年1月31日OpenAI o3-mini 发布:推理强度、基准与贪吃蛇测试Matthew Berman · Forward Future2025 年 1 月,Matthew Berman 解读 OpenAI 报告的结果,并用不同推理设置尝试两个编码示例。
 26:23EN → 简体中文Matthew Berman· 2024年12月20日OpenAI 发布 o3:基准测试进展与 AGI 之问Matthew Berman, Sam Altman, Mark Chen, Greg Kamradt, Hongyu Ren · Forward FutureMatthew Berman 回顾 2024 年 12 月 o3 和 o3-mini 的发布,包括编程、数学与 ARC-AGI 成绩。他认为这些结果证明了 AGI,但基准测试本身无法确立这一结论。
 17:12EN → 简体中文Matthew Berman· 2024年4月30日2024 年 4 月测试神秘模型“gpt2-chatbot”Matthew Berman · Forward FutureMatthew Berman 在模型身份尚不确定时,用编程、算术和推理任务对它进行测试。
 22:17EN → 简体中文Matthew Berman· 2024年3月21日Q* 传闻、能量模型与推理研究Matthew Berman, Yann Lecun · Forward FutureMatthew Berman 审视一份未经证实的匿名 Q* 描述,并将其中的想法与训练语言模型进行推理的已发表研究作比较。
 11:05EN → 简体中文Matthew Berman· 2023年11月7日测试 Dolphin 2.2:基于 Mistral 7B 的微调模型Matthew Berman · Forward FutureMatthew Berman 用编程、格式化和推理提示测试一个小型开放权重模型,结果有好有坏。