30 秒看懂
In February 2025, Berman discusses Grok 3, xAI’s benchmark comparisons, its reasoning interface and a DeepSearch demonstration. He highlights rapid development while noting that an alternative chart adds a stronger o3 comparison; the results and rankings shown reflect the launch period.
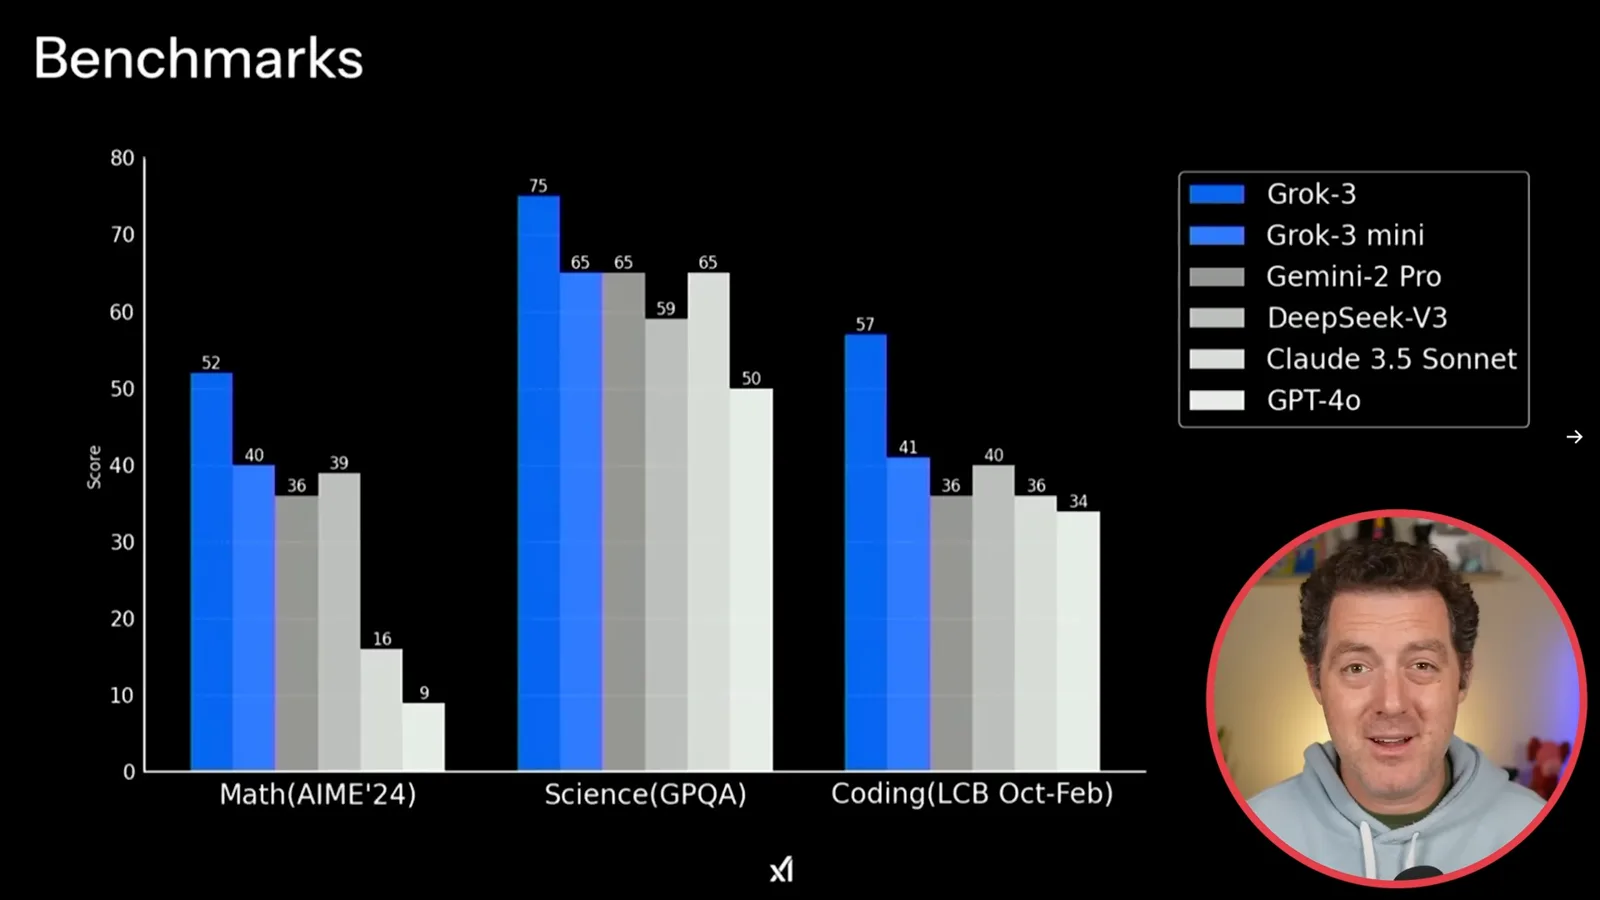
- 1Vendor benchmarksThe launch chart compares selected contemporary models on math, science and coding.
- 2User-preference rankingBerman discusses a historical LM Arena snapshot under the name “chocolate.”
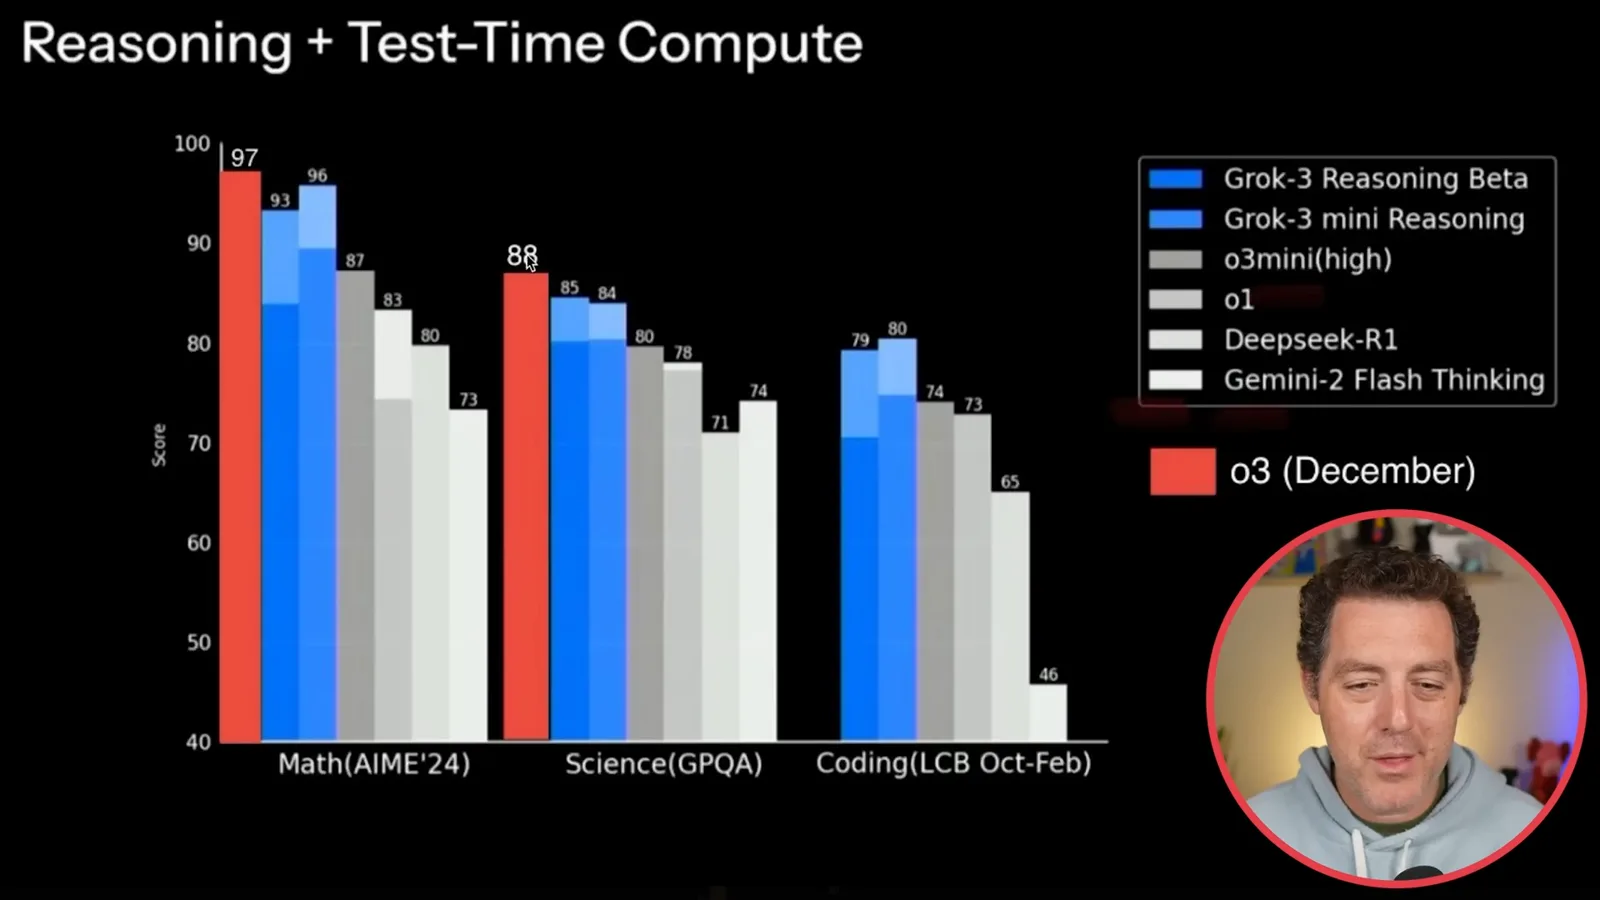
- 3Missing comparisonAn edited chart adds o3 results that were not in the original xAI comparison.
- 4Partial reasoning traceMusk says some of the displayed thinking is obscured.
- 5DeepSearch demonstrationAn xAI presenter shows searches and source summaries for a launch question.
要点建议
- xAI reported strong results on selected math, science and coding benchmarks at launch.
- A user-preference leaderboard and vendor benchmarks measure different things and change over time.
- A chart that includes additional comparison models can change the apparent ranking.
- The displayed reasoning trace is not the entire internal reasoning process, according to Musk.
- The early DeepSearch and coding demonstrations do not independently establish accuracy or broad performance.
按章节阅读整理后的全文
Launch and initial comparisons
Berman introduces Grok 3 and xAI’s reported results and recalls his predictions.
In February 2025, xAI released Grok 3. I review the launch, xAI’s reported benchmarks and a few early product features. I also note that a model under the name “chocolate” had reached the top of the user-preference LM Arena leaderboard at the time; leaderboard positions change and do not settle every question about model quality.
Before release, I predicted that xAI would reach roughly the level of o1 and might offer a distinctive personality. Based on the initial charts I consider the model competitive, but say I have not yet assessed the personality claims. I also discuss the product’s access to X data as a potential differentiator.
The launch presentation compares Grok 3 and Grok 3 mini with several contemporary non-reasoning models on selected math, science and coding tests. On the chart shown, Grok 3 leads those selected comparisons. These are xAI-reported scores under specific conditions, not independent proof that it beats every model on every task.
I describe xAI’s account of reinforcement learning focused on math and coding and its claim that the improvements generalized beyond those training domains. A small number of benchmark comparisons can suggest transfer, but do not by themselves establish broad generalization or rule out all contamination.
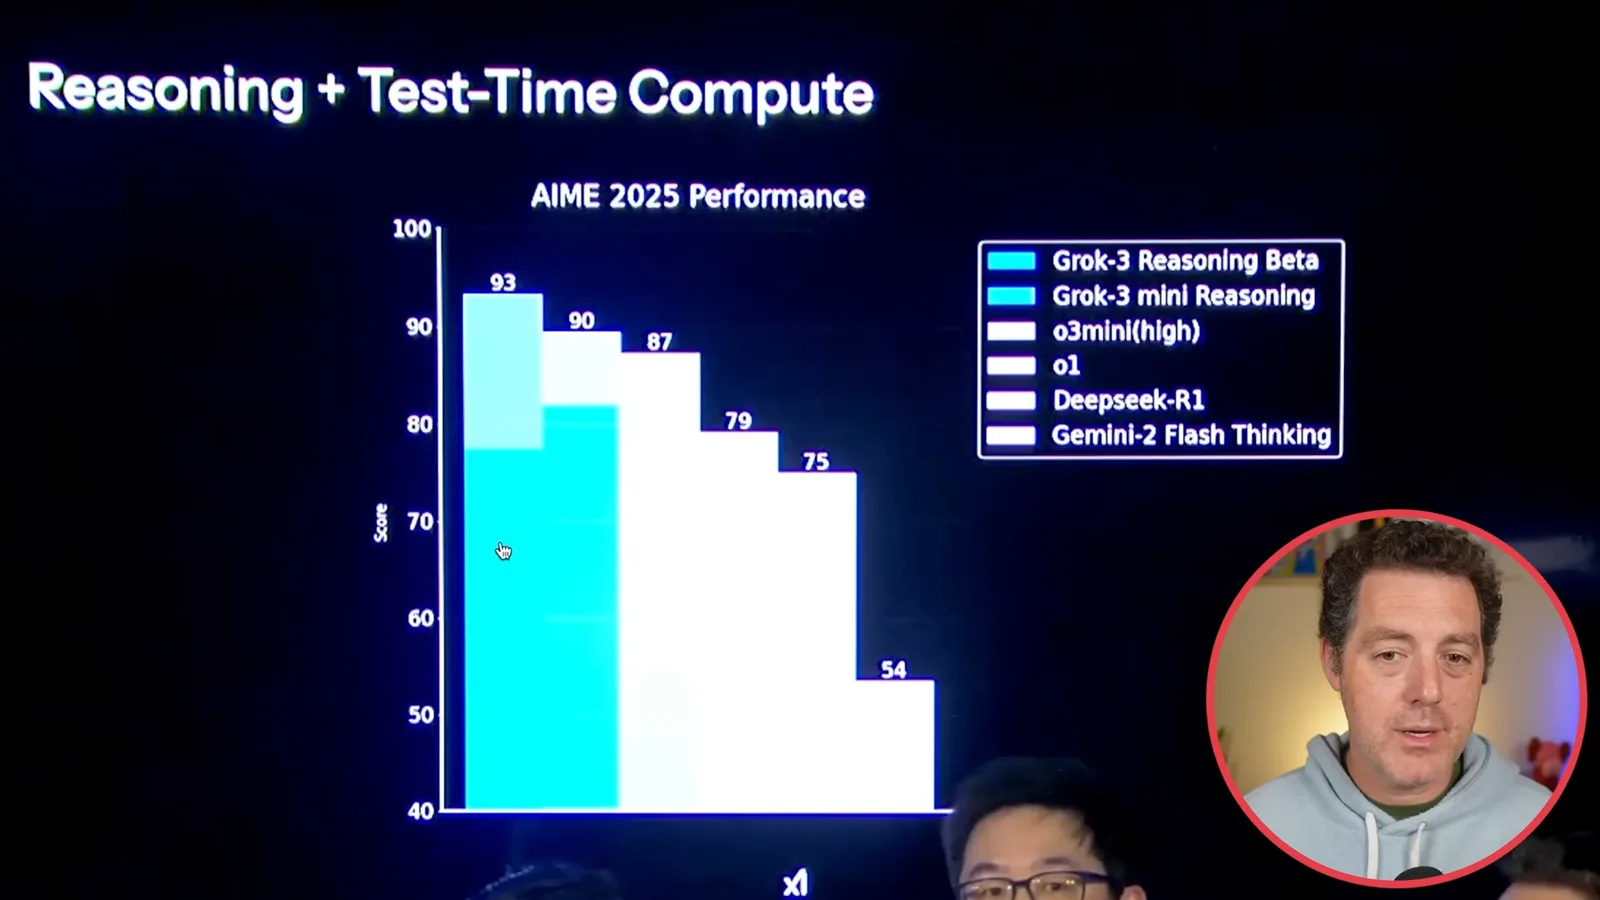
The team presents AIME 2025 results as a newer math test, with Grok reasoning variants ahead of the models listed on its chart. I regard this as encouraging; it is still a company-presented comparison and should be interpreted with its evaluation setup in mind.
Leaderboard and benchmark context
He discusses user preference, a chart with an added comparison and xAI’s development timeline.
I contrast benchmark scores with LM Arena, where users compare model responses. I note that the “chocolate” entry was identified as an early Grok 3 version and held a leading position in the snapshot I show. Such rankings reflect the users and evaluation window involved.
I then show a modified comparison that adds OpenAI’s December o3 results to an xAI chart that omitted them. On the displayed math and science tests, o3 scores higher. Selecting different comparison models can change the apparent ranking; it does not establish a single best model for all uses.
I am impressed that xAI reached competitive scores relatively quickly, and review a timeline from Grok 1 to Grok 3. I suggest access to X’s data may have helped; the video does not isolate the effect of that data from compute, training methods or other factors.
Compute and early coding test
He reviews claims about the GPU cluster and tries a Snake prompt.
Musk says xAI built a large GPU cluster after providers quoted a longer timeline. I recount his claim of around 100,000 GPUs and his description of building power, cooling and networking capacity. These are statements from the launch, not figures independently verified in this review.
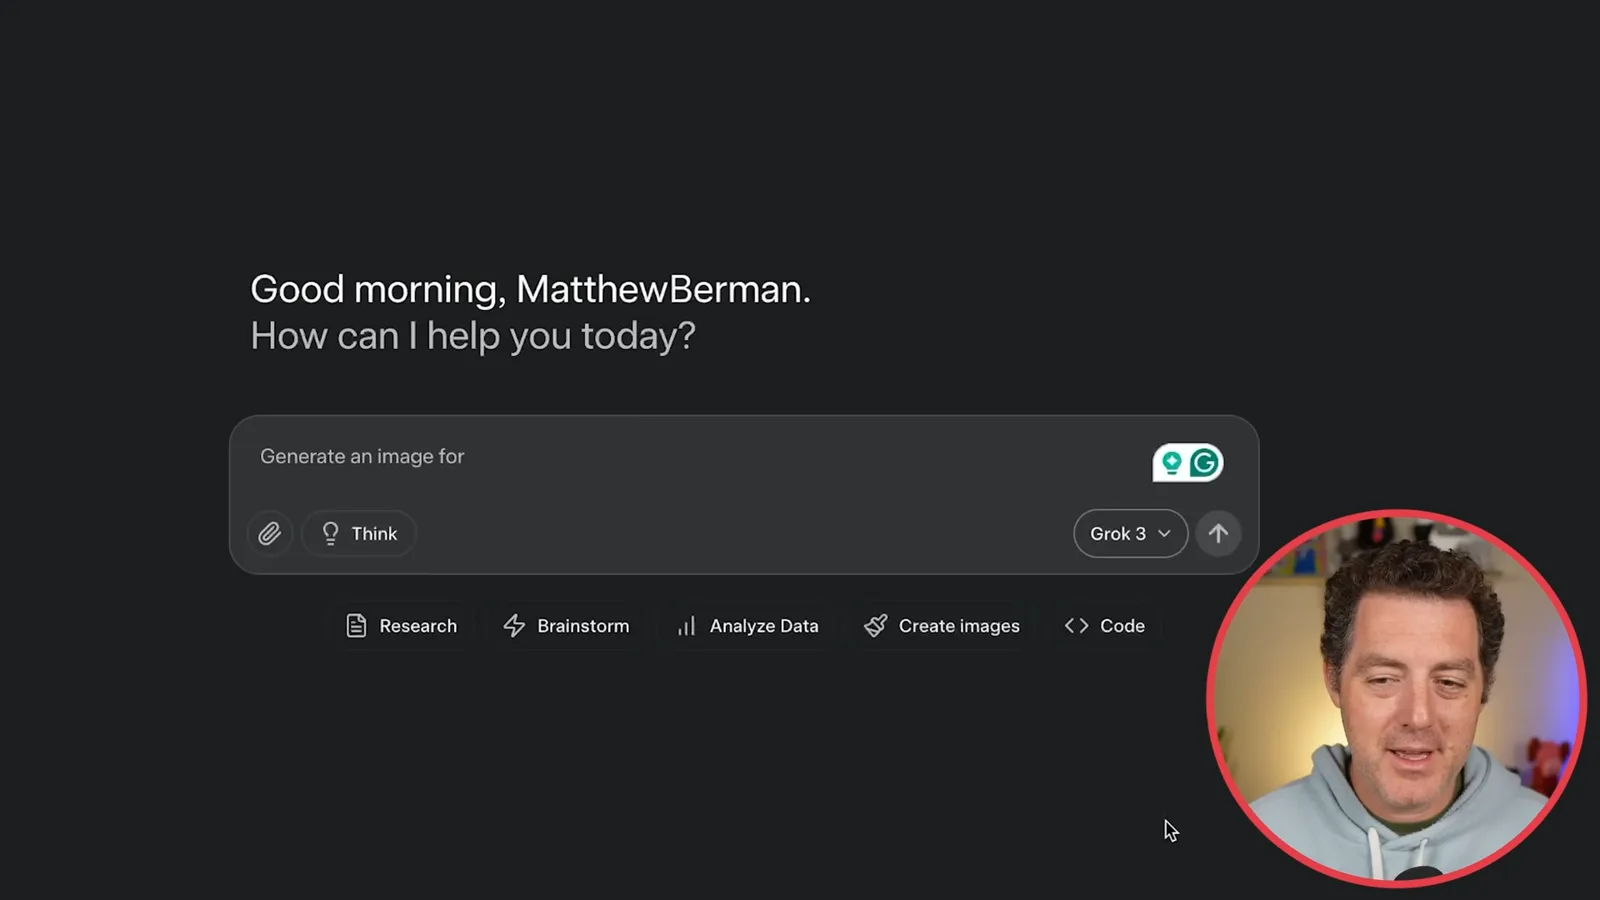
The product interface I show includes research, brainstorming, data analysis, image creation and coding options, plus a Think control. These reflect the interface at the February 2025 launch; features and access may have changed.
I ask Grok to build a Snake game in Python and observe fast text generation, though the displayed process takes around 85 seconds before code output. This is an early demonstration, not a controlled throughput measurement or a complete test of the resulting program.
In a launch clip, Elon Musk says the visible thinking is partially obscured to make immediate model copying harder. The displayed trace therefore should not be treated as a complete view of the model’s internal reasoning.
I discuss the team’s claim that reinforcement learning on math and coding improved other forms of reasoning, and predict ongoing model updates. My broader enthusiasm about reinforcement learning is interpretation, not evidence that one training technique alone explains the model’s performance.
DeepSearch and first impressions
A launch clip demonstrates research features, and Berman offers his historical first impressions.
An unnamed xAI presenter demonstrates DeepSearch with a question about a future launch. The interface shows progress, searches and source summaries. The demonstration illustrates the intended workflow, but the video does not independently verify the final answer or demonstrate that every cited source is reliable.
I conclude that the launch has several promising features and say I was unsure whether xAI planned to release the model openly. This is a February 2025 first look, not a statement about later releases, access, leaderboard positions or model capabilities.
同频道的其他文章
 25:50EN → 简体中文
 32:20EN → 简体中文
 0:22EN → 简体中文
 45:08EN → 简体中文
 0:32EN → 简体中文
 1:02EN → 简体中文