30 秒でわかる
Matthew Berman discusses Matt Shumer’s essay on the potential economic impact of AI, drawing on his own experience with coding tools and examples from AI labs. He argues that individuals should experiment with the technology and prepare for disruption, while the magnitude and timing of the changes he predicts remain uncertain.
- 1A warning about rapid changeBerman uses Matt Shumer’s essay to discuss why people outside the AI industry may underestimate the possible speed of change.
- 2Coding becomes more accessibleHe describes using coding agents to automate parts of his own work and says Shumer reports that he now writes much less code himself.
- 3Interpreting the benchmarkThe METR chart groups tasks by how long they take human experts and asks whether models succeed. It does not establish that agents can independently run any real-world project for that length of time.
- 4Agents working on a compilerAnthropic reported a multi-agent C compiler experiment; the team supplied infrastructure, tests and direction, which matter when interpreting the result.
- 5Adoption is unevenBerman cites a McKinsey chart showing that 7% of surveyed organizations using AI had fully scaled it across their enterprises, a narrower group than all companies.
ポイント
- Berman sees recent coding agents as a meaningful change in what non-specialists can build, based on his own experience.
- METR’s task-horizon benchmark measures performance on selected tasks by the time humans take to complete them; it is not a direct measure of continuous autonomous operation.
- Projects such as Anthropic’s C compiler show useful agent capabilities under human-designed tests and supervision, not proof that all programming work is automated.
- Forecasts of widespread job displacement are uncertain, and reported enterprise adoption varies greatly in depth.
- Experimenting with relevant tools, preserving financial flexibility, and developing judgment are Berman’s proposed ways to prepare.
チャプターごとに整えた全文を読む
Why the essay resonated
Berman introduces Shumer’s comparison between an emerging crisis and the early days before a broad public response. He frames the essay as a warning, not a certain forecast.
Matt Shumer wrote an essay called “Something Big Is Happening,” and I think its message deserves attention. He compares the current moment to the early stages of the pandemic, when some people were already worried but many others had not yet changed their behavior. The analogy is an argument about awareness, not proof that the two events will unfold alike.
The essay argues that AI is improving quickly while many people are still making plans as if work will remain much the same. A small group of companies and decision-makers has enormous influence over how these systems are built and deployed. I want to explain why I think the essay’s warnings are worth considering.
A change in coding
Personal examples illustrate how language models and agents have changed the way Berman and Shumer approach programming. Berman argues the impact may reach beyond software.
Shumer describes a personal change in his own coding work. Tasks that once meant writing code himself can now be delegated to an agent, with him explaining the goal and checking what comes back. That is one person’s experience, but I recognize the shift from my own work.
I use AI tools to build and automate pieces of my video workflow. I can describe an application, inspect the result, and keep asking for changes. The process still requires me to know what I want, notice mistakes, and decide whether the result actually works.
What makes this different from an autocomplete tool is the amount of a task the agent can attempt before it needs another instruction. It can explore files, make changes, run commands and iterate. It is not infallible, and its performance depends on the task, the tools available and the supervision around it.
I encourage people to try current tools on a real problem in their own field rather than rely only on old impressions. I think paid models are useful for seeing what the strongest offerings can do, although a subscription is not a prerequisite for learning or evaluating whether a tool fits your work.
The pace of recent improvements makes it hard to project the future from a single older demonstration. At the same time, a compelling demo should not be mistaken for evidence that every task in a profession can be done reliably or economically by an agent.
Benchmarks and agent projects
Berman reviews METR’s task-horizon chart, Anthropic’s compiler work, and other agent examples. Their conditions and limitations matter when extrapolating from them.
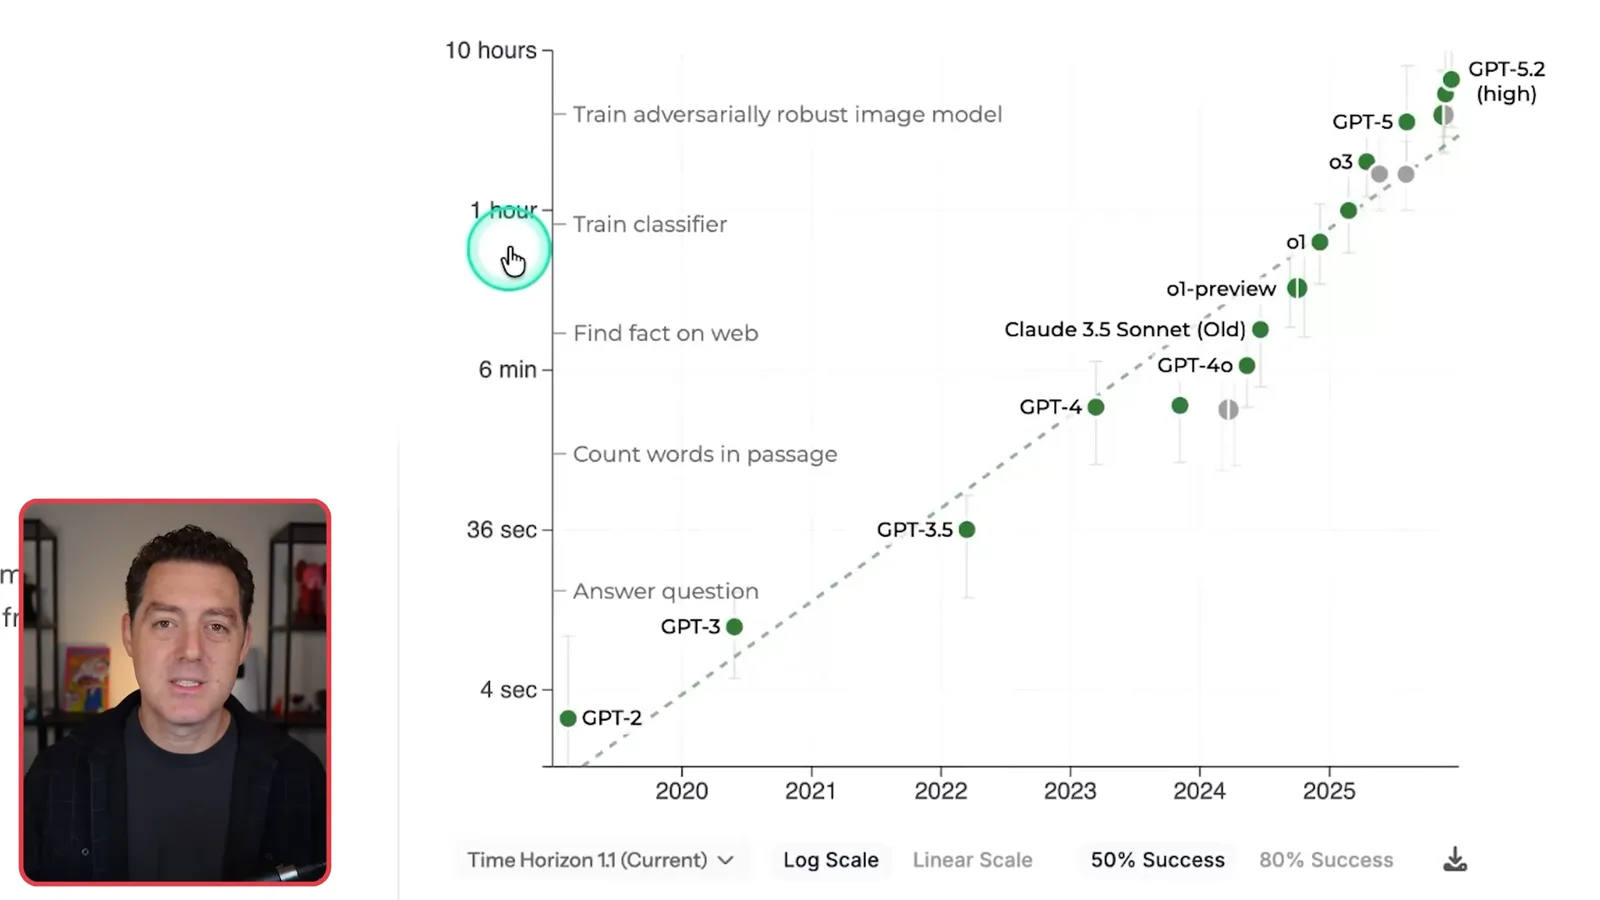
The METR chart looks at AI performance on tasks grouped by the time a human expert needs to finish them. Its 50% horizon estimates the human task duration at which a model succeeds half the time on the benchmark. It is a measure on a particular task set, not a clock showing how long an agent can autonomously run any job.
Anthropic described using multiple agents to build a C compiler over roughly two weeks, at a reported API cost around $20,000. The researchers designed the environment, tests and feedback the agents used. The experiment demonstrates a significant project under those conditions; it does not mean a model independently replaced a software team.
I also discuss Cursor’s browser-building experiment, in which agents generated a large codebase and produced something that worked to some degree. Line counts are an imperfect proxy for usefulness or quality, but the examples show why coding agents are drawing attention.
OpenAI said an early version of GPT-5.3-Codex helped with work involved in its own development and debugging. I see that as an example of AI contributing to AI research. That is different from demonstrating an unsupervised, self-sustaining loop in which a model independently improves itself.
What happens to work?
He discusses forecasts of job disruption and the role of human judgment. These are scenarios and opinions rather than established outcomes.
Shumer and other AI leaders warn that rapid improvements could disrupt white-collar employment. Those warnings are forecasts, not settled estimates of how many jobs will disappear or when. The effect will depend on reliability, cost, regulation, organizations and the choices people make.
A job is a collection of tasks, relationships and responsibilities. Automating one part can change the rest without necessarily eliminating the entire role, while some organizations may need fewer people for certain work. I think the possibility of significant disruption is serious enough to consider before it arrives.
Human judgment becomes important when a system produces plausible work that still needs to be checked. Understanding the problem, setting a goal, assessing consequences and taking responsibility for an outcome are not the same as accepting an answer because it sounds confident.
Preparing for uncertainty
Berman recommends experimenting, evaluating AI outputs, and thinking about financial resilience and education. He closes with advice to stay adaptable.
My first practical suggestion is to experiment. Choose a task you know well, ask an AI tool to help, and compare the result with what you would have done. This makes it easier to discover both useful capabilities and the mistakes that glossy demonstrations can hide.
Learn how to give context and evaluate the output. Do not put sensitive information into a service without understanding its handling of that information, and do not treat a model’s answer as a substitute for independent review when the stakes are high.
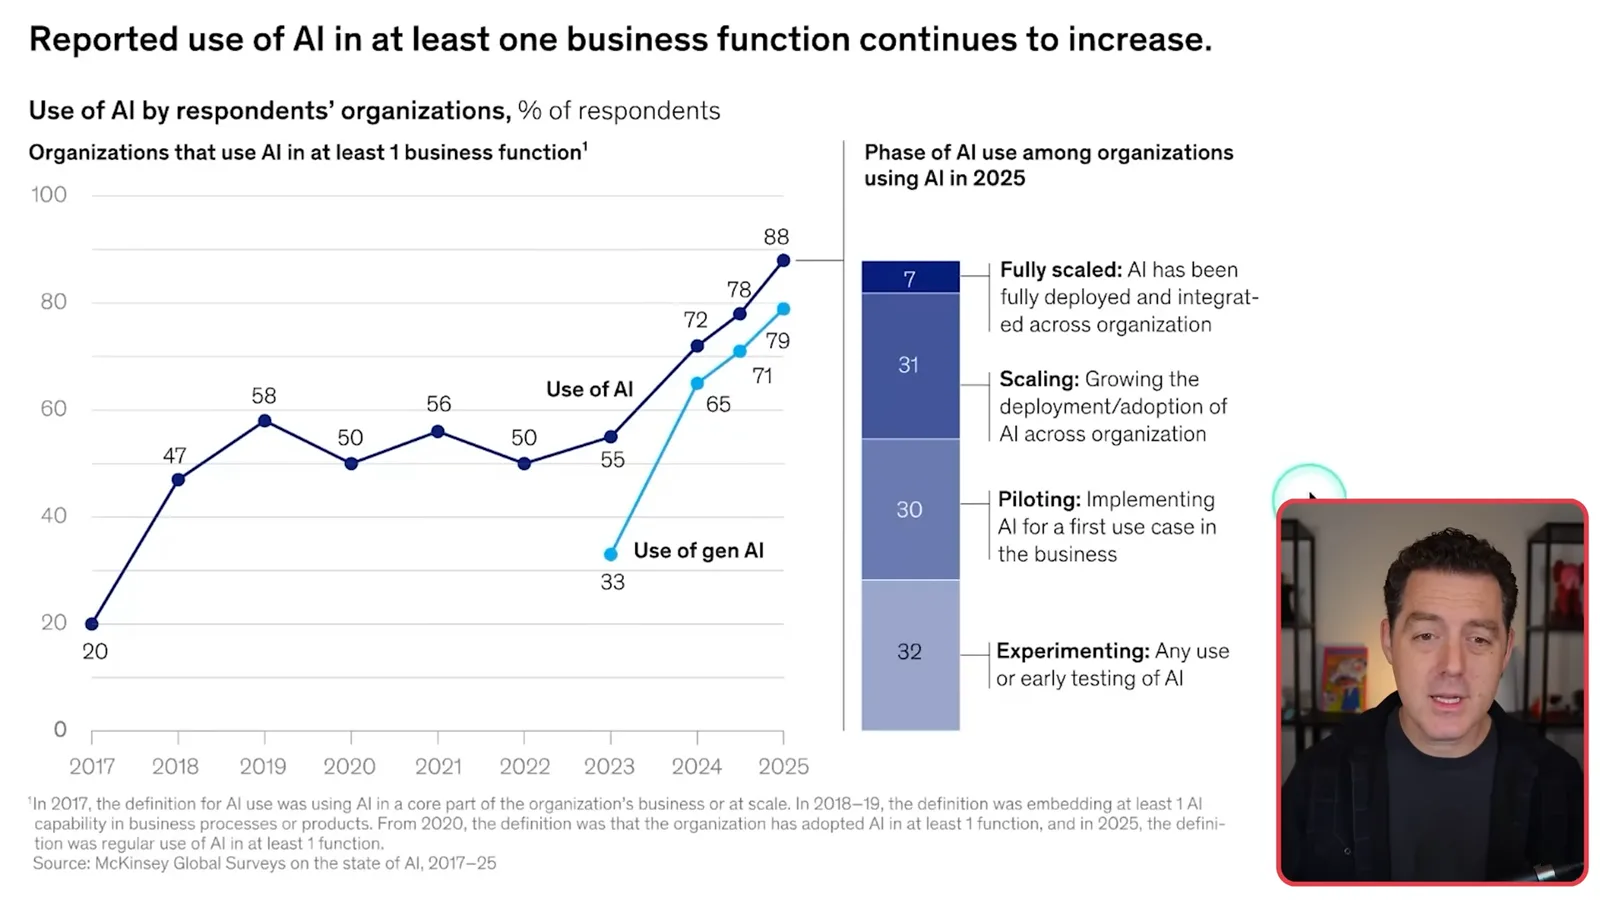
A McKinsey chart I discuss says 7% of surveyed organizations using AI had fully scaled it across their enterprises. That figure describes a subset of survey respondents, not all companies. It suggests that even where people report using AI, organization-wide deployment can lag behind experimentation.
I also suggest thinking about financial flexibility and avoiding assumptions that current employment conditions will remain unchanged. People’s circumstances differ, so the appropriate steps depend on their resources, obligations and tolerance for risk.
For families, the question is how to help children use new tools while retaining the ability to think, learn and act independently. Fundamentals and curiosity still matter: a tool is more valuable when its user can tell whether the result makes sense.
I see opportunities as well as risks. An individual or small team may be able to test ideas and build products that previously required more resources. The opportunity does not guarantee success, but it is a reason to learn by making something concrete.
The main point is not that anyone can predict the precise timetable. It is that waiting for perfect certainty may leave people less prepared. Try the tools available to you, keep your judgment engaged, and adjust as the evidence changes.
If you can afford to experiment with a paid service, I think it can be worthwhile; free options and shared resources can also provide a starting point. The goal is to understand the technology and its limits through experience.
同じチャンネルの記事
 25:50EN
 32:20EN
 45:08EN
 0:32EN
 12:14EN
 10:36EN