








Ergebnisse
686 ArtikelSortieren
 11:38EN
 Matthew Berman· 13. Aug. 2025AI News in August 2025: App Store Dispute, Claude’s Long Context and New ModelsMatthew Berman · Forward FutureMatthew Berman reviews the Musk–Altman exchange, Claude Sonnet 4’s million-token beta, Skywork’s interactive world model and other AI announcements.
 10:09ENMatthew Berman· 12. Aug. 2025Matthew Berman on Emotional Attachment to AI After GPT-5’s LaunchMatthew Berman · Forward FutureThe 2025 GPT-5 rollout prompted debate about attachment to older models, sycophancy and the effects of AI companionship.
 15:08ENMatthew Berman· 8. Aug. 2025GPT-5 at Launch: Routing, Coding, Benchmarks and ReliabilityMatthew Berman · Forward FutureMatthew Berman reviews OpenAI’s 2025 GPT-5 release, its unified ChatGPT experience, benchmark claims and the limitations of model evaluations.
 1:10ENMatthew Berman· 8. Aug. 2025Testing a GPT-5-Generated Rubik’s Cube SimulatorMatthew Berman · Forward FutureMatthew Berman prompts GPT-5 to build a Three.js cube simulator and tries its scramble and solve controls at several sizes.
 1:43:51ENMatthew Berman· 8. Aug. 2025GPT-5, Cline and SWE-bench: How to Judge AI Coding AgentsMatthew Berman, Matt Wolfe, Ray Fernando, Saoud Razwan, Nick, Ofir, Carlos, John, Kilian · Forward FutureMatthew Berman and guests discuss early GPT-5 impressions, the economics of Cline, and why coding benchmark results depend on the evaluation setup.
 40:32ENMatthew Berman· 7. Aug. 2025Mark Chen on GPT-5, Synthetic Data and the Future of AI ResearchMatthew Berman, Mark Chen · Forward FutureOpenAI’s head of research discusses training, agents, open-weight releases and evaluation with Matthew Berman in August 2025.
 25:24ENMatthew Berman· 7. Aug. 2025GPT-5 Tested on Coding, Simulations and Multimodal TasksMatthew Berman · Forward FutureMatthew Berman tries browser applications, visual simulations and image prompts, showing both successes and defects in his early hands-on tests.
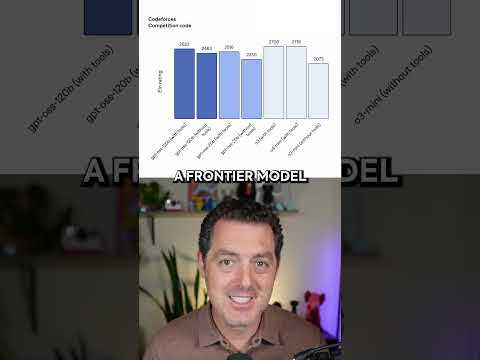 1:01ENMatthew Berman· 5. Aug. 2025OpenAI’s gpt-oss Release and a Coding BenchmarkMatthew Berman · Forward FutureMatthew Berman introduces two open-weight models and reviews a Codeforces comparison from the launch.
 10:28ENMatthew Berman· 5. Aug. 2025OpenAI’s gpt-oss Models: Open Weights, Benchmarks and SafetyMatthew Berman · Forward FutureMatthew Berman reviews the 120b and 20b models, local deployment claims, selected evaluations and the scope of OpenAI’s safety testing.
 3:13ENMatthew Berman· 5. Aug. 2025Claude Opus 4.1: Anthropic’s August 2025 Benchmark UpdateMatthew Berman · Forward FutureMatthew Berman reviews the model’s reported coding, reasoning and tool-use results, including one benchmark that declined.
 8:17ENMatthew Berman· 31. Juli 2025ASI-Arch: An Automated Search for Neural Network ArchitecturesMatthew Berman · Forward FutureMatthew Berman explains a 2025 research system that proposes, trains and evaluates model designs in an iterative loop.
 15:30ENMatthew Berman· 31. Juli 2025Qwen3 Tested: Coding Demos, Long Context and Response BehaviorMatthew Berman · Forward FutureMatthew Berman tests generated simulations, political and safety prompts, hand tracking and word puzzles using a hosted Qwen3 model.
 11:28ENMatthew Berman· 30. Juli 2025GLM-4.5: Coding Demos, Model Sizes and Z.ai’s BenchmarksMatthew Berman · Forward FutureMatthew Berman tests interactive applications built with GLM-4.5 and examines Z.ai’s reported comparisons with leading models in July 2025.
 6:53ENMatthew Berman· 24. Juli 2025Qwen3-Coder: An Open-Weight Coding Model and Its Command-Line AgentMatthew Berman · Forward FutureMatthew Berman examines Qwen’s July 2025 coding model, its training and benchmark results, and tries its command-line tool on a Snake game.
 47:05ENMatthew Berman· 21. Juli 2025Logan Kilpatrick on AI Developers, Interfaces, and the Future of ModelsMatthew Berman, Logan Kilpatrick · Forward FutureIn a July 2025 conversation, Google’s Logan Kilpatrick discusses Windsurf, agent interfaces, coding skills, Veo, and the shifting boundary between models and application scaffolding.
 49:55ENMatthew Berman· 17. Juli 2025Aravind Srinivas on Comet, AI Browsers and the Future of WorkMatthew Berman, Aravind Srinivas · Forward FuturePerplexity’s CEO explains why the company built a browser, how it evaluates models and why he expects AI to disrupt jobs.
 12:14ENMatthew Berman· 16. Juli 2025AI News: Windsurf’s Acquisition, Meta Compute Plans, Grok and VoxtralMatthew Berman · Forward FutureA July 2025 roundup examines developer-tool deals, AI infrastructure, model behavior, reward methods and speech recognition.
 15:23ENMatthew Berman· 13. Juli 2025Grok 4’s Early Reception: Impressive Demos, Safety Questions and Mixed User FeedbackMatthew Berman · Forward FutureMatthew Berman surveys early reactions to xAI’s 2025 model release, from physics simulations and benchmark results to concerns about bias, safety and speed.
 31:03ENMatthew Berman· 9. Juli 202521 Ways to Use AI for Coding, Research and Everyday TasksMatthew Berman, Alex · Forward FutureMatthew Berman and editor Alex demonstrate AI workflows for documents, creative work, decisions, travel and reminders.
 1:09ENMatthew Berman· 3. Juli 2025A Discussion of GPT-4.5’s Scaling and TrainingA speaker offers an assessment of GPT-4.5’s cost, speed and alleged training challenges.
 1:04ENMatthew Berman· 2. Juli 2025Why AI Companies Might Offer Researchers Enormous Pay PackagesMatthew Berman · Forward FutureMatthew Berman and a guest discuss the economics of competing for AI talent, comparing reported compensation offers with a hypothetical acquisition.
 59:27ENMatthew Berman· 2. Juli 2025Aaron Levie on AI Agents, Jobs and the Future of Enterprise SoftwareMatthew Berman, Aaron Levie · Forward FutureBox’s CEO explains his AI-first strategy, why he expects demand to grow and how humans may direct and review agents.
 10:20ENMatthew Berman· 1. Juli 2025Meta’s Superintelligence Labs and the Fight for AI ResearchersMatthew Berman, Sam Altman · Forward FutureMatthew Berman traces Meta’s 2025 investment in Scale AI, its recruitment from rival labs, and OpenAI’s response. The video’s claims about customer data and signing bonuses need important qualifications.
 27:40ENMatthew Berman· 28. Juni 2025Seedance 1.0 vs. Veo 3: An Informal Text-to-Video ComparisonMatthew Berman · Forward FutureMatthew Berman compares visual quality, motion and prompt adherence across gymnastics, action, animation and fantasy scenes.
Mehr laden24 von 686 angezeigt