In 30 Sekunden
Matthew Berman reviews Qwen3-Coder-480B-A35B-Instruct and Qwen Code, describing their architecture, long context, training and reported agentic coding benchmarks. He shows coding demonstrations and builds a Snake game, which works with some lag.
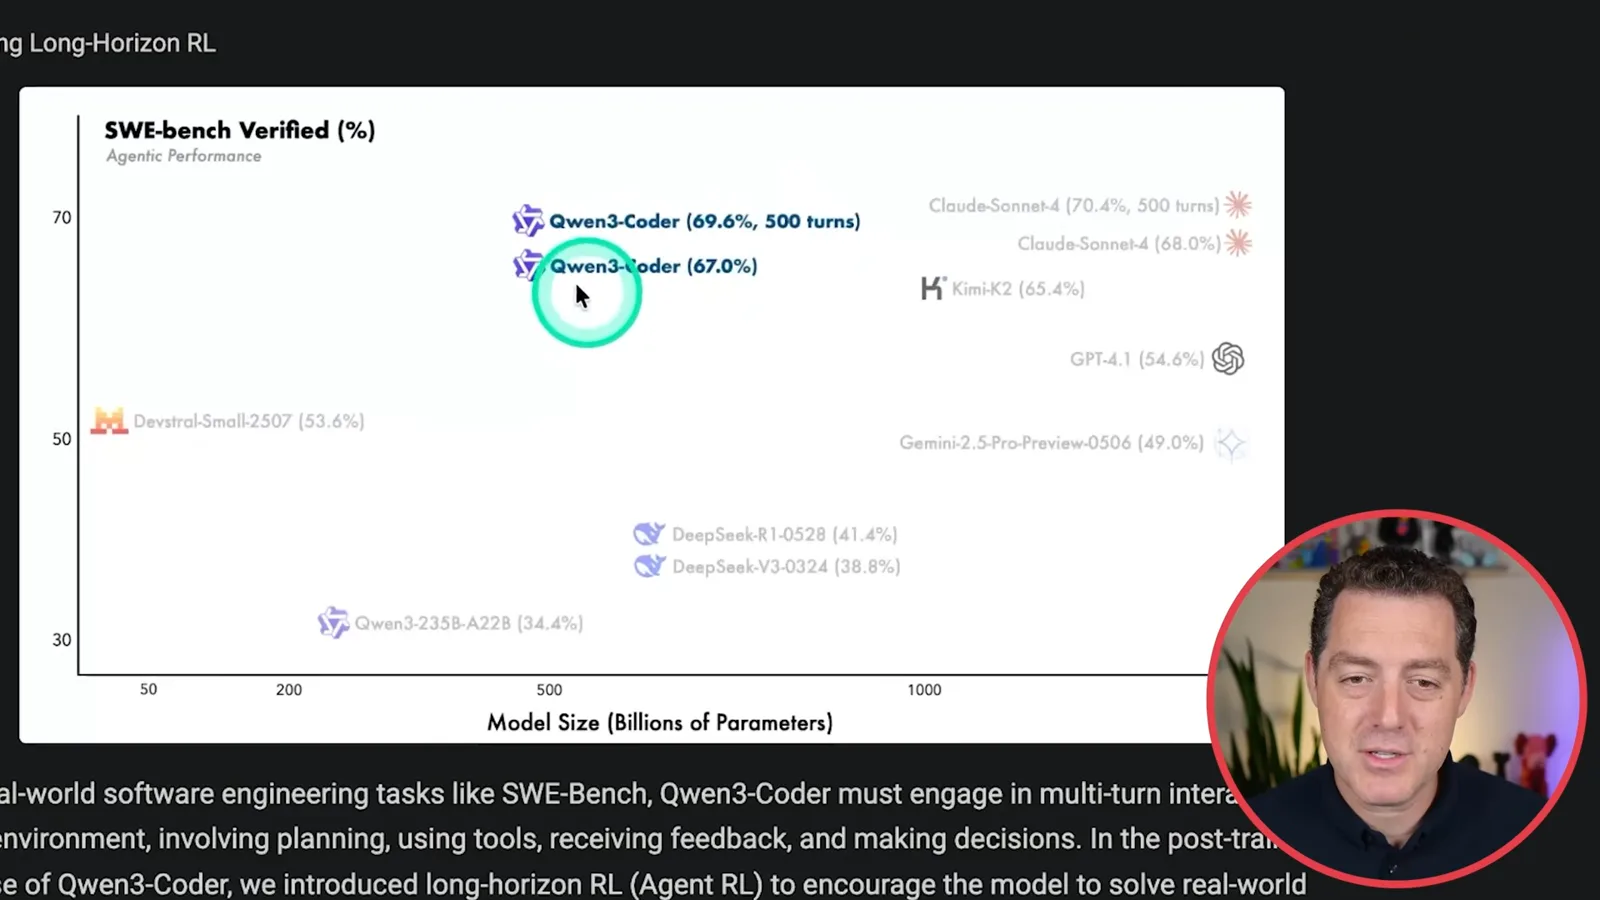
- 1A narrow benchmark comparisonQwen’s chart reports 69.6% for Qwen3-Coder and 70.4% for Claude Sonnet 4 on SWE-bench Verified with OpenHands and 500 turns. The result is specific to the stated evaluation setup.
- 2Mixture of experts and long contextThe 480B model activates 35B parameters and supports 256K tokens natively, with an advertised extension to one million using YaRN.
- 3Code-heavy trainingQwen reports 7.5 trillion pretraining tokens with a 70% code ratio and says it used Qwen2.5-Coder to clean noisy data.
- 4Long-horizon reinforcement learningQwen says its infrastructure could run 20,000 independent environments in parallel to train and evaluate tool-using agents.
- 5A quick Snake testBerman reports that his game took about a minute and 792 lines to generate. It ran, although he noticed some lag.
Das Wichtigste
- Qwen3-Coder’s released model has 480 billion total parameters, 35 billion active parameters and a 256K native context window.
- Qwen reported 69.6% on SWE-bench Verified with OpenHands and 500 turns, close to the 70.4% figure it reported for Claude Sonnet 4 under that configuration.
- Qwen describes code-focused pretraining and reinforcement learning with up to 20,000 parallel environments.
- Qwen Code is a command-line coding agent adapted from Gemini CLI.
- Berman’s single Snake game demo worked with some lag; it is an illustration rather than a comprehensive evaluation.
Den bearbeiteten Text nach Kapiteln lesen
Benchmark and model architecture
Berman compares Qwen’s reported SWE-bench result with Claude Sonnet 4. He introduces the mixture-of-experts architecture, long context and Qwen Code.
Qwen has released Qwen3-Coder, an open-weight coding model that I think belongs in the same conversation as Anthropic’s Claude models. The Qwen team’s SWE-bench Verified chart reports 69.6% for Qwen3-Coder and 70.4% for Claude Sonnet 4 using OpenHands with 500 turns. That is a close result on this particular test and configuration, not proof that the models are interchangeable across every coding task.
Qwen also released a command-line coding tool, Qwen Code, adapted from Gemini CLI with custom prompts and function-calling support. The first and largest model in the July 2025 release is Qwen3-Coder-480B-A35B-Instruct: a mixture-of-experts model with 480 billion total parameters and 35 billion active parameters. Its model card lists an Apache 2.0 license.
The model supports a 256,000-token context window natively, and Qwen says YaRN can extend it to one million tokens. A long context can be useful for coding because an agent may need to work across a repository, tool outputs and changing information. Qwen positions the model for coding, tool calls and other agentic tasks.
Pretraining and agent reinforcement learning
The Qwen team describes code-heavy pretraining, data cleaning and execution-driven reinforcement learning. Its long-horizon training infrastructure supports parallel environments.
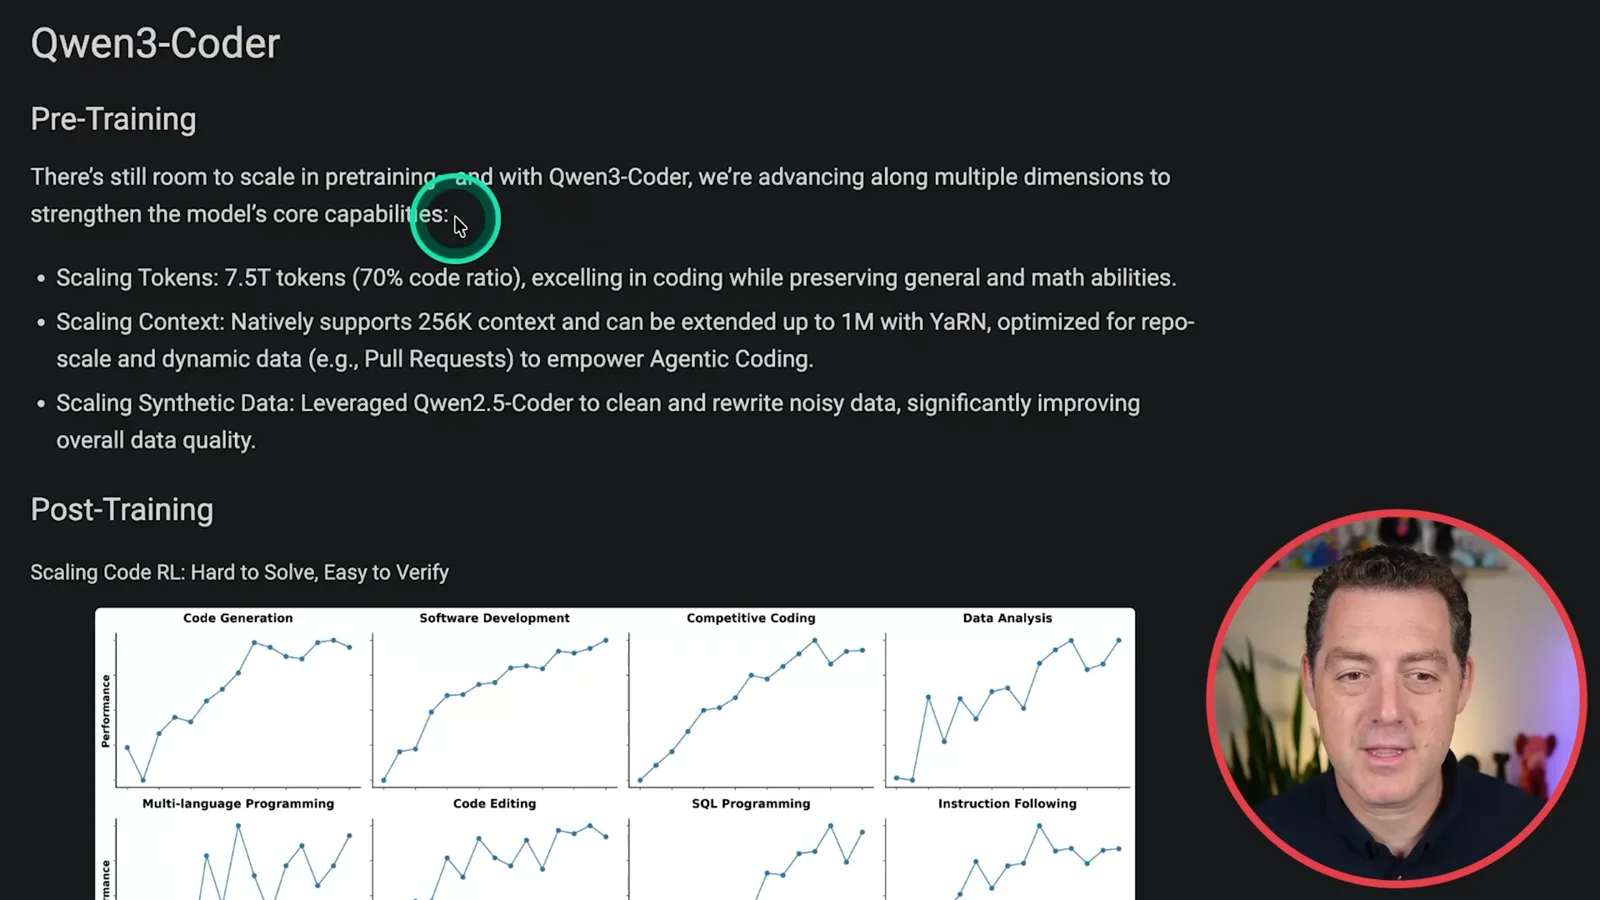
The team’s starting premise is that there is still room to scale pretraining. Qwen reports 7.5 trillion training tokens with a 70% code ratio, and says the model retains general and mathematical abilities. It also used the earlier Qwen2.5-Coder model to clean and rewrite noisy data, so one generation helped prepare training material for the next.
For post-training, Qwen describes scaling code reinforcement learning across a broader range of real-world tasks rather than focusing only on competitive programming. It generated diverse test cases to build training instances, reporting improvements in code execution and other tasks. The attraction is that a coding problem can be hard to solve while its proposed solution is comparatively easy to verify by execution.
Long-horizon agent reinforcement learning adds multi-turn interactions: planning, using tools, receiving feedback and deciding what to do next. Qwen says it built infrastructure on Alibaba Cloud capable of running 20,000 independent environments in parallel for training and evaluation. The company reports its SWE-bench result without test-time scaling; that statement alone does not establish that the model cannot reason, and my speculation about future improvements remains speculation.
Trying the model and viewing demos
Berman shows a hosted coding interface and examples of generated interactive applications. The examples include a physics simulation and several visualizations.
At the time of the video, Hugging Face hosted a way to try the model. In the example I choose a bouncing-ball task: the interface writes code and can execute it there. I then show demonstrations made with Qwen Code, starting with a physics simulation of a structure breaking apart.
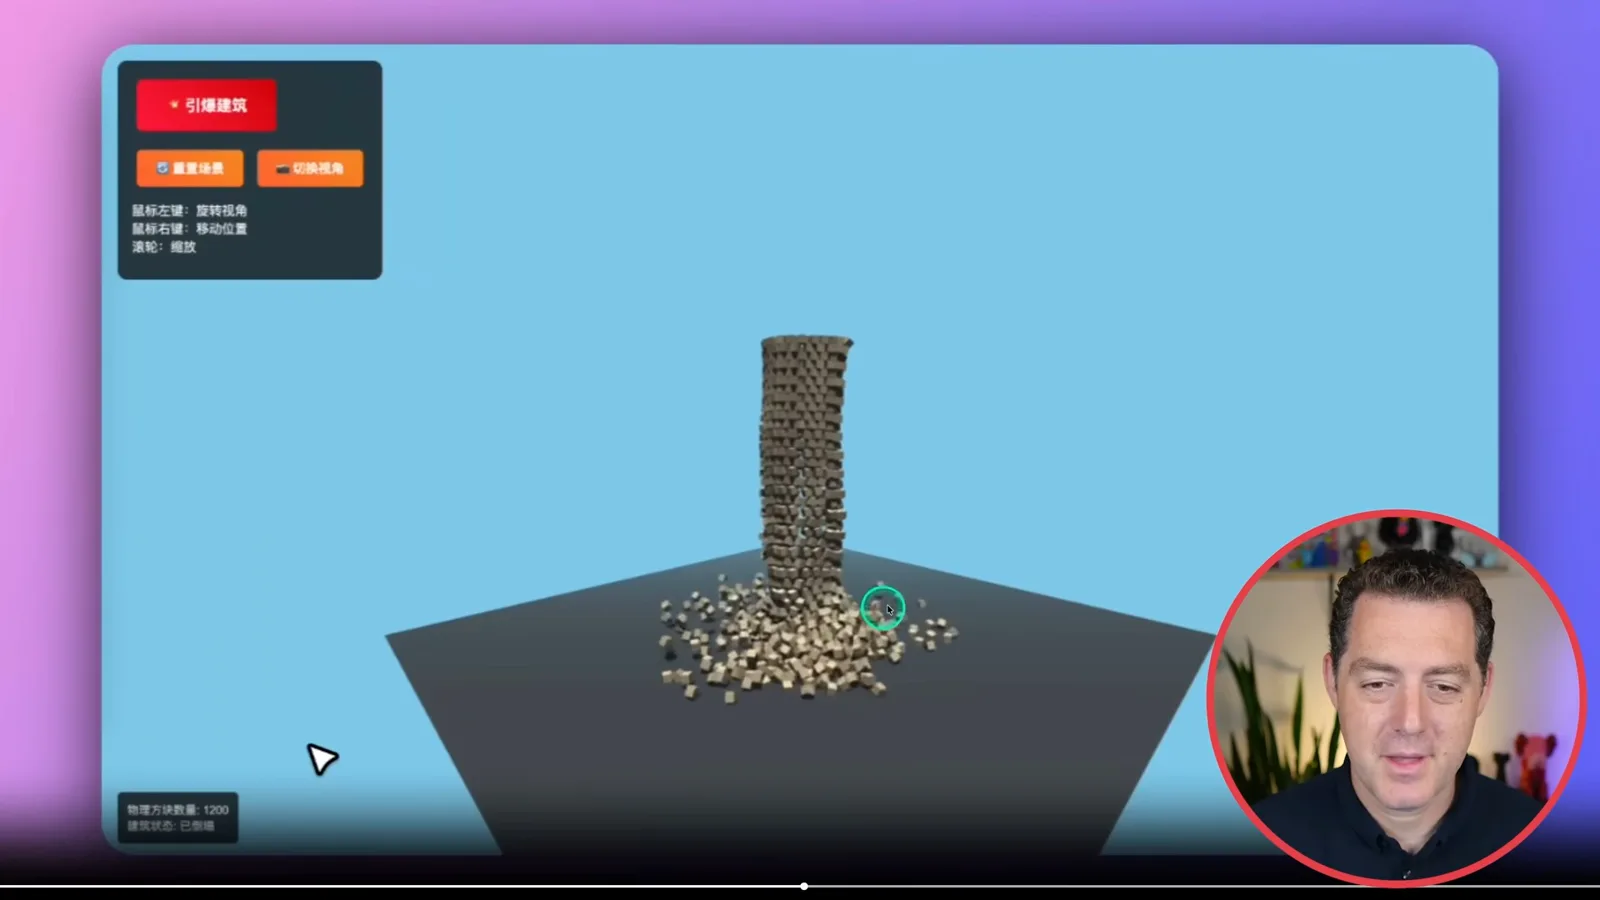
Other examples include an interactive color visualization, a 3D Earth terrain simulation, a typing-speed app, a bouncing ball and rotating hypercube, a solar system and a game called Duet. These clips show a range of applications the tool can generate, though a selected demo does not by itself measure reliability on a broader set of projects.
A Snake game test
Berman uses Qwen Code to generate a complex Snake game. He finds it functional but somewhat laggy.
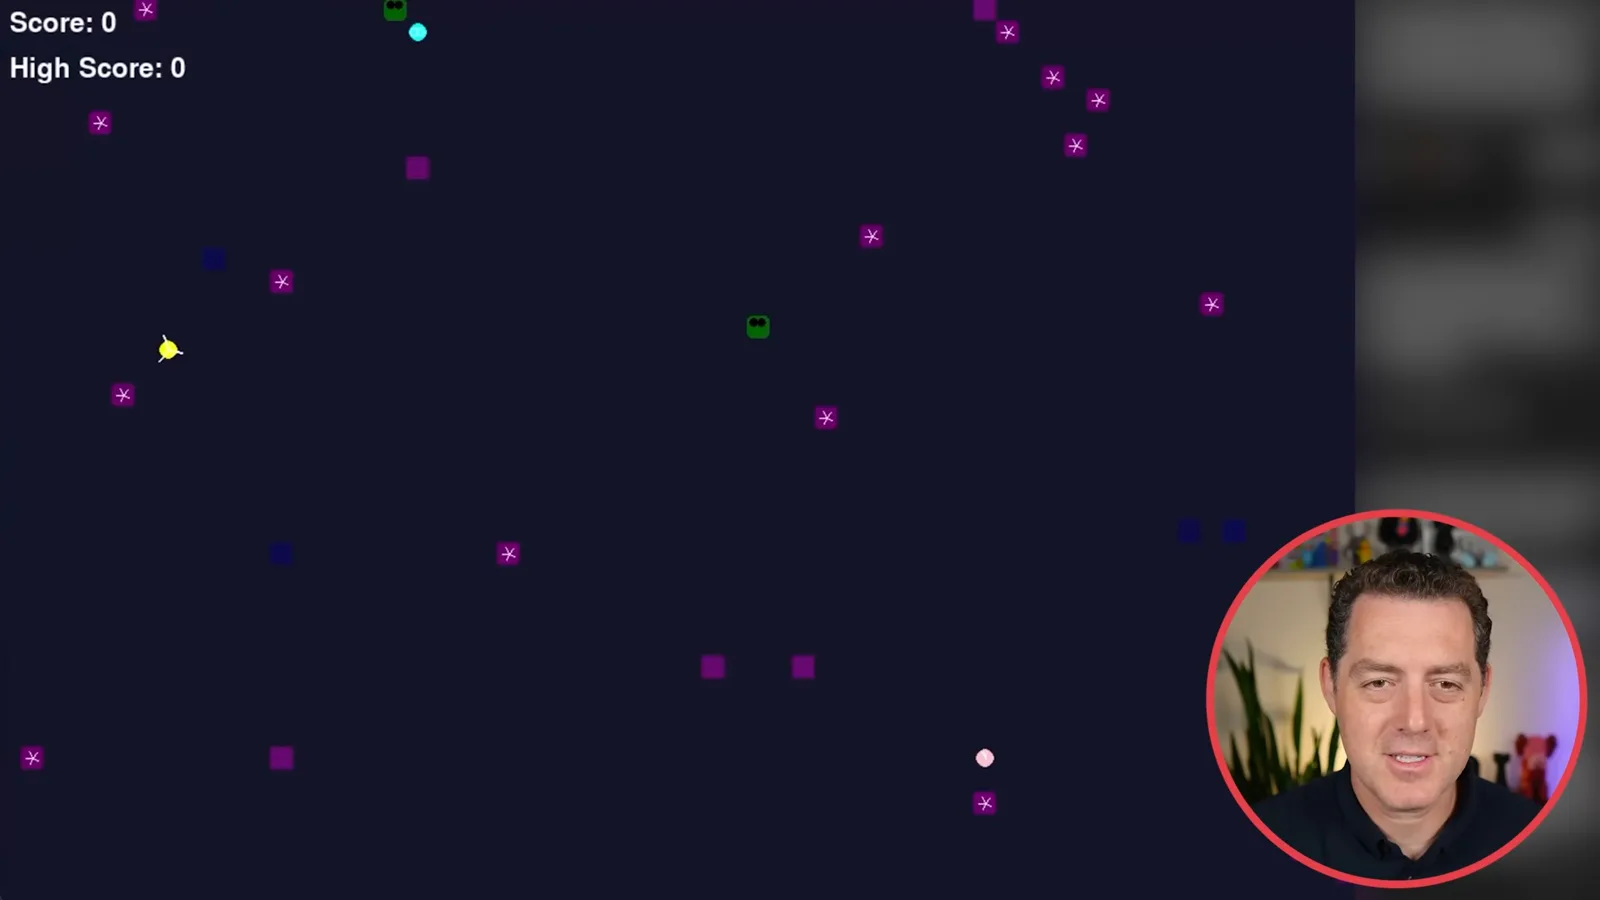
Finally, I load Qwen Code in my command line and ask it to make a complex Snake game. It takes about 60 seconds and produces 792 lines of code. The game runs when I open it; I am not sure what one object at the top is doing, and it is a little laggy, but it is still a promising quick test.
Mehr aus diesem Kanal
 34:21EN
 Matthew Berman· 27. Okt. 2026Matthew Berman Examines Anthropic’s IPO Filing, AI Growth and GovernanceMatthew Berman, Sam Altman · Forward FutureThe presenter reviews the S-1’s financial metrics, compute strategy and voting structure while questioning the tension between rapid AI development and safety.
 0:36ENMatthew Berman· 25. Okt. 2026Kimi K3.1 and a Rubik’s Cube Solver DemonstrationMatthew Berman · Forward FutureMatthew Berman shows a scrambled virtual cube being solved and gives the Kimi K3.1 test a favorable assessment.
 25:50ENMatthew Berman· 24. Okt. 2026Kimi K3.1 Pro Tested: Strong 3D Demos, Uneven Results and Competitive PricingMatthew Berman · Forward FutureMatthew Berman tests the open-weight model on coding, 3D rendering and visual explanations, then compares benchmark results and prices.
 32:20ENMatthew Berman· 23. Okt. 2026Who Is Local AI For? The Costs, Trade-offs and a Hybrid FutureMatthew Berman · Forward FutureMatthew Berman weighs data control and independence against hardware cost, setup complexity and inference speed.
 1:03:37ENMatthew Berman· 23. Okt. 2026Matthew Berman’s Team Tests Kimi K3.1 on Animation, Games, and ChartsMatthew Berman, Alex, Brian · Forward FutureA live team AMA turns into an informal test of Kimi K3.1, from personal-agent workflows to motion graphics, a browser game, and a benchmark chart.
 0:53ENMatthew Berman· 22. Okt. 2026Sam Altman on AI and the Discovery of New KnowledgeSam Altman · OpenAIAltman expects progress in mathematical discovery to extend to biology, materials and energy.