Claude Opus 4.1: Anthropic’s August 2025 Benchmark Update

Matthew Berman reviews the model’s reported coding, reasoning and tool-use results, including one benchmark that declined.

MBMatthew BermanModeration · Forward Future
Kanal
Matthew Berman
Veröffentlicht
5. Aug. 2025
Video
3:13
Lesezeit
1 Min.
Folien
1
Original
Englisch
Auf YouTube öffnen
Beim Scrollen schrumpft das Video in die rechte untere Ecke und läuft weiter. Untertitel folgen Ihrer Lesesprache.
LesespracheIn 2 Sprachen verfügbar
Diesen Artikel gibt es noch nicht auf Deutsch, daher wird das Original (Englisch) angezeigt.
ZUSAMMENFASSUNG

In 30 Sekunden

In an August 2025 video, Matthew Berman reviews Anthropic’s Claude Opus 4.1 announcement and its selected benchmark comparison. He sees gains in several coding tests but notes a lower airline tool-use score and says practical testing matters.

  1. 1Coding resultsThe displayed SWE-bench Verified result rose from 72.5% to 74.5%, a two-percentage-point increase.
  2. 2Mixed tool-use scoresTerminal-Bench increased, but the airline portion of TAU-bench fell from 59.6% to 56.0%.
  3. 3Compare by taskThe table shows other models ahead on GPQA Diamond and AIME 2025; Berman plans practical testing.

Das Wichtigste

  1. Anthropic reported 74.5% on SWE-bench Verified for Opus 4.1 versus 72.5% for Opus 4 in its displayed comparison.
  2. Terminal-Bench rose in the table, while the airline portion of TAU-bench declined.
  3. Other models led the displayed GPQA and AIME comparisons; results depend on evaluation settings and task.
  4. Berman treats real-world usage as an important complement to benchmarks.
VOLLTEXT

Den bearbeiteten Text nach Kapiteln lesen

Nur das Transkript
01

The Opus 4.1 release

Berman introduces Anthropic’s update and its stated goals.

Anthropic announced Claude Opus 4.1 in August 2025 as an update to Opus 4 for agentic work, coding and reasoning. I review the company’s reported benchmark table, which reflects its selected tests and settings at the time.

02

Benchmarks and real-world use

He reviews coding, tool-use and reasoning scores and emphasizes practical evaluation.

On SWE-bench Verified, the displayed scores rise from 72.5% for Opus 4 to 74.5% for Opus 4.1: an increase of two percentage points. Anthropic also describes improvements in research and analysis, including tracking details and agentic search.
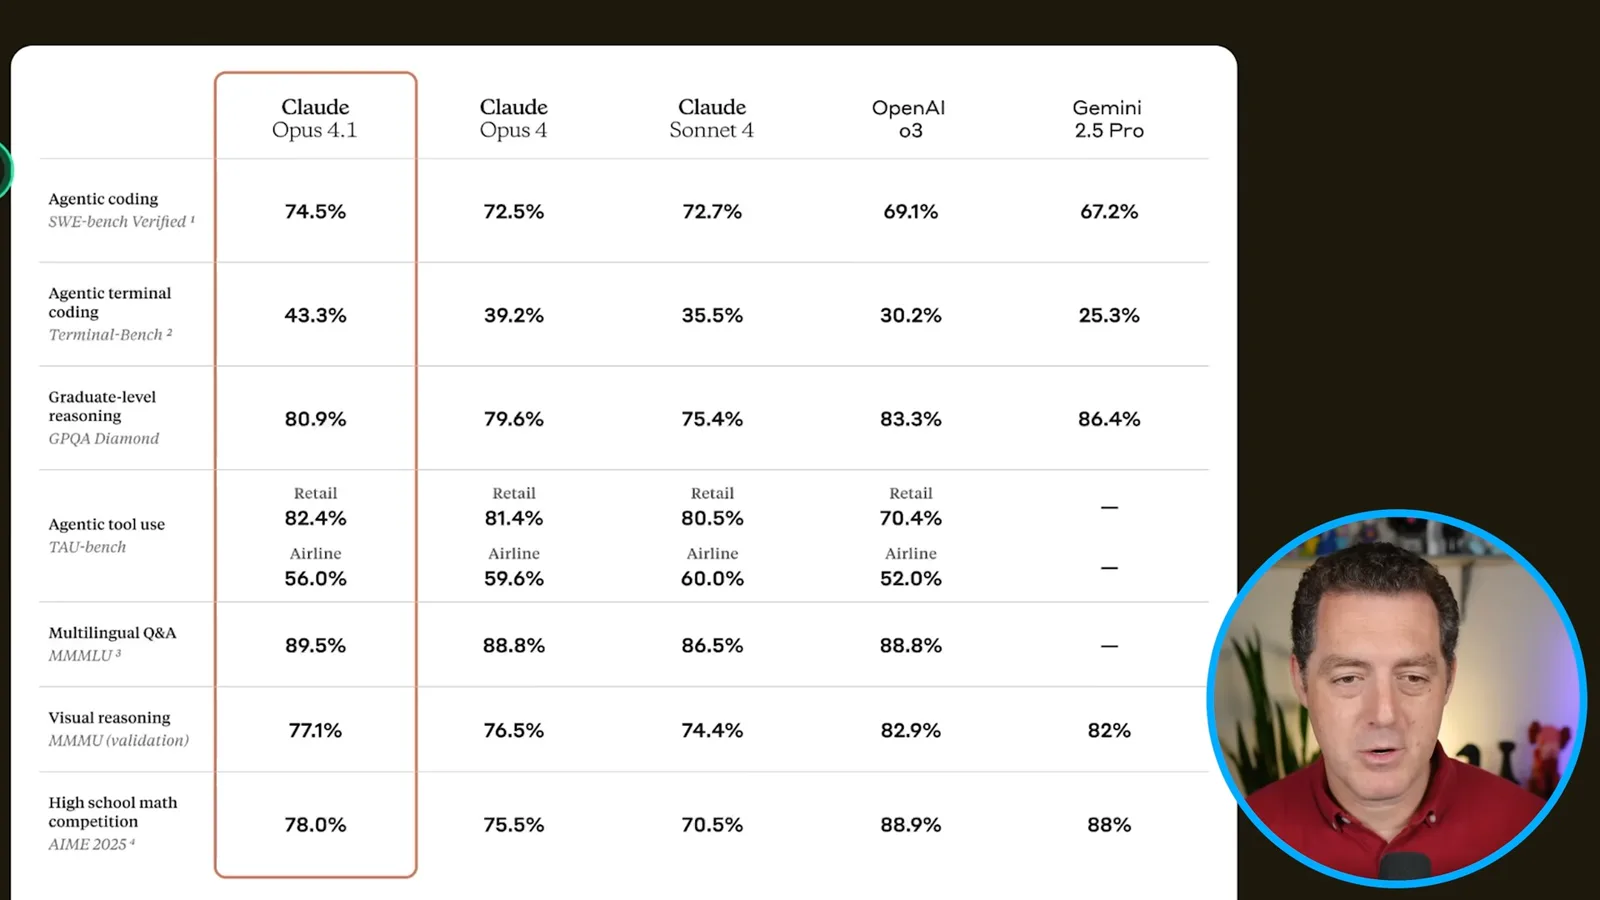
Anthropic’s selected benchmark table
FOLIE 1 / 1Anthropic’s selected benchmark tableThe table compares coding, tool use and reasoning under the reported evaluation settings; the airline score declines.

The table shows Terminal-Bench increasing from 39.2% to 43.3% and GPQA Diamond from 79.6% to 80.9%. TAU-bench retail rises from 81.4% to 82.4%, while airline falls from 59.6% to 56.0%. Other displayed categories show smaller gains.

In the displayed comparison, Opus 4.1 leads the included o3 and Gemini 2.5 Pro results on the two coding benchmarks, while those models score higher on GPQA Diamond and AIME 2025. These selected numbers do not establish a universal ranking.

I think the important question is how the model works on actual tasks, and I plan to test it. My view that Claude was particularly strong for agentic coding is an assessment from 2025, not a current leaderboard or a guarantee for every workflow.

Mehr aus diesem Kanal

6 Folien25:50EN
MBMatthew Berman· 24. Okt. 2026Kimi K3.1 Pro Tested: Strong 3D Demos, Uneven Results and Competitive PricingMatthew Berman · Forward FutureMatthew Berman tests the open-weight model on coding, 3D rendering and visual explanations, then compares benchmark results and prices.Open-weight modelsBenchmarksAI cost & performance+1
2 Folien32:20EN
MBMatthew Berman· 23. Okt. 2026Who Is Local AI For? The Costs, Trade-offs and a Hybrid FutureMatthew Berman · Forward FutureMatthew Berman weighs data control and independence against hardware cost, setup complexity and inference speed.Local inferenceOpen-weight modelsAI cost & performance+1
6 Folien1:03:37EN
MBMatthew Berman· 23. Okt. 2026Matthew Berman’s Team Tests Kimi K3.1 on Animation, Games, and ChartsMatthew Berman, Alex, Brian · Forward FutureA live team AMA turns into an informal test of Kimi K3.1, from personal-agent workflows to motion graphics, a browser game, and a benchmark chart.Coding-AgentenGenerative mediaEvals+2
Folien0:22EN
MBMatthew Berman· 21. Okt. 2026A Robot Bodyguard Video Shows Dramatic Rescue ScenariosMatthew Berman · Forward FutureMatthew Berman reacts to a short robot demonstration depicting fighting and vehicle-rescue scenarios.RoboticsEvals
45:08EN
MBMatthew Berman· 21. Okt. 2026Sam Altman on AI Discovery, Consciousness, Compute and a Human-Centered FutureMatthew Berman, Sam Altman · Forward FutureIn a conversation with Matthew Berman, Altman discusses scientific progress, personal assistants, recursive self-improvement and the importance of human agency.AI for sciencePersonal agentsConsciousness+2
0:32EN
MBMatthew Berman· 21. Okt. 2026Sam Altman on the Continuing Demand for Software WorkSam Altman, Matthew Berman · OpenAIIn a short interview excerpt, Altman says demand for software may be larger than expected even as AI changes how it is made.Future of WorkSoftware engineeringCoding-Agenten