In 30 Sekunden
In August 2025, Matthew Berman discusses OpenAI’s gpt-oss open-weight models and their mixture-of-experts architecture. He reviews the company’s reported benchmarks and safety work; the results are specific to their tests and do not guarantee safe or accurate use. Together AI sponsored the video.
- 1Two open-weight modelsThe release included 120b and 20b variants; the rumored connection to another model was unconfirmed.
- 2Mixture of expertsOpenAI reported 5.1 billion and 3.6 billion active parameters per token for the larger and smaller models respectively.
- 3Selected benchmarksThe video compares coding and reasoning results under specific conditions, including tool access.
- 4Safety evaluation scopeOpenAI reported that its fine-tuned test models did not reach a particular high-capability threshold; this is not proof of zero risk.
Das Wichtigste
- gpt-oss-120b and gpt-oss-20b were released with open weights under Apache 2.0.
- OpenAI described local deployment options with different memory requirements, subject to actual hardware and software.
- Mixture-of-experts activates a subset of parameters per token, but total memory and infrastructure still matter.
- Benchmark comparisons depend on tasks, settings and tool access; HealthBench is not a diagnosis guarantee.
- OpenAI’s worst-case fine-tuning evaluation had a defined scope and did not prove misuse impossible.
Den bearbeiteten Text nach Kapiteln lesen
Open weights and deployment
Berman introduces the models, license and reported memory requirements. He discusses reasoning settings and local use.
OpenAI released gpt-oss-120b and gpt-oss-20b, two open-weight models under Apache 2.0, in August 2025. I speculate that a previously seen mystery model might be related, but OpenAI had not confirmed that connection. This video is sponsored by Together AI.
Open weights let developers run and adapt models themselves, subject to the license and infrastructure costs. OpenAI reported that the larger model could run on a single 80 GB GPU and the smaller model on a device with 16 GB of memory; actual performance depends on software, hardware and workload.
The announcement compares the 120b model with o4-mini and the 20b model with o3-mini on selected reasoning benchmarks. I find the possibility of local deployment exciting, but these reported comparisons are not a guarantee of equal performance on every task.
The models support tool use and configurable reasoning effort. Berman discusses low, medium and high settings as a tradeoff between speed and additional work. A health benchmark is an evaluation of model responses, not a license to rely on the model for diagnosis.
Architecture and training
The models use mixture-of-experts Transformers and attention optimizations. The video includes a Together AI sponsorship.
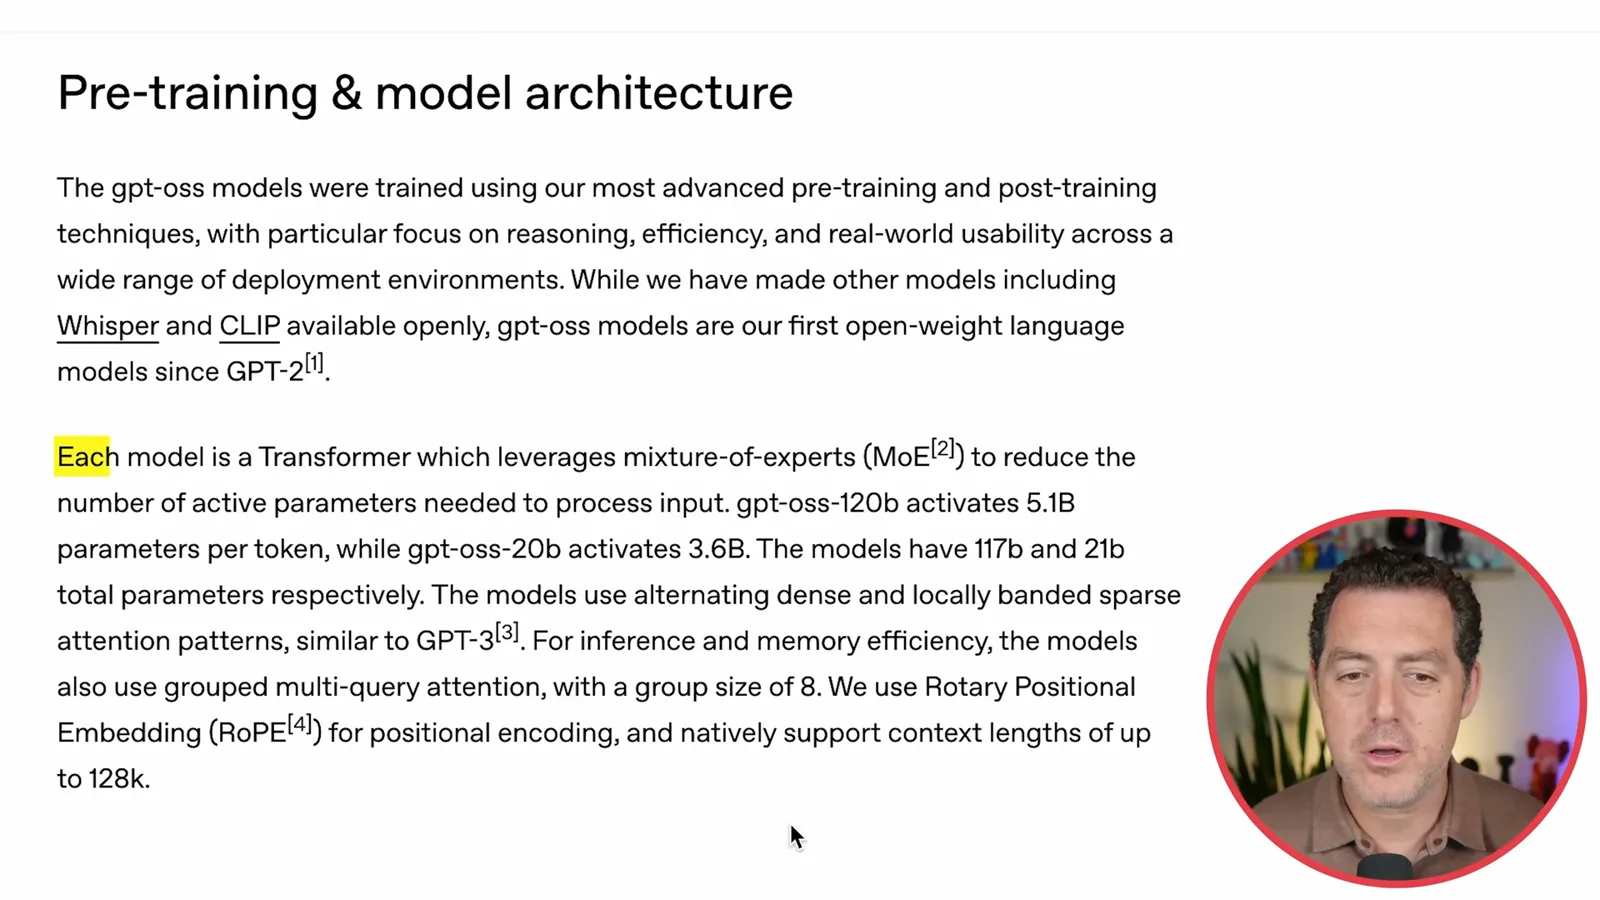
Both models use a mixture-of-experts Transformer. OpenAI reports 117 billion total parameters with 5.1 billion active per token for the 120b model, and 21 billion total with 3.6 billion active for the 20b model. Active parameters are only one part of deployment cost and performance.
The technical description mentions attention optimizations, rotary positional encoding and a context length up to 128,000 tokens. OpenAI says its pretraining data focused on text including STEM, code and general knowledge; local availability does not make model output automatically accurate.
Together AI sponsors the video and offers hosted access. Berman then describes supervised fine-tuning and reinforcement learning in post-training, intended to improve reasoning and tool use. The precise training methods should not be assumed to be identical across all model providers.
Benchmarks
Berman reviews selected coding, health and reasoning evaluations. Scores depend on test setup.
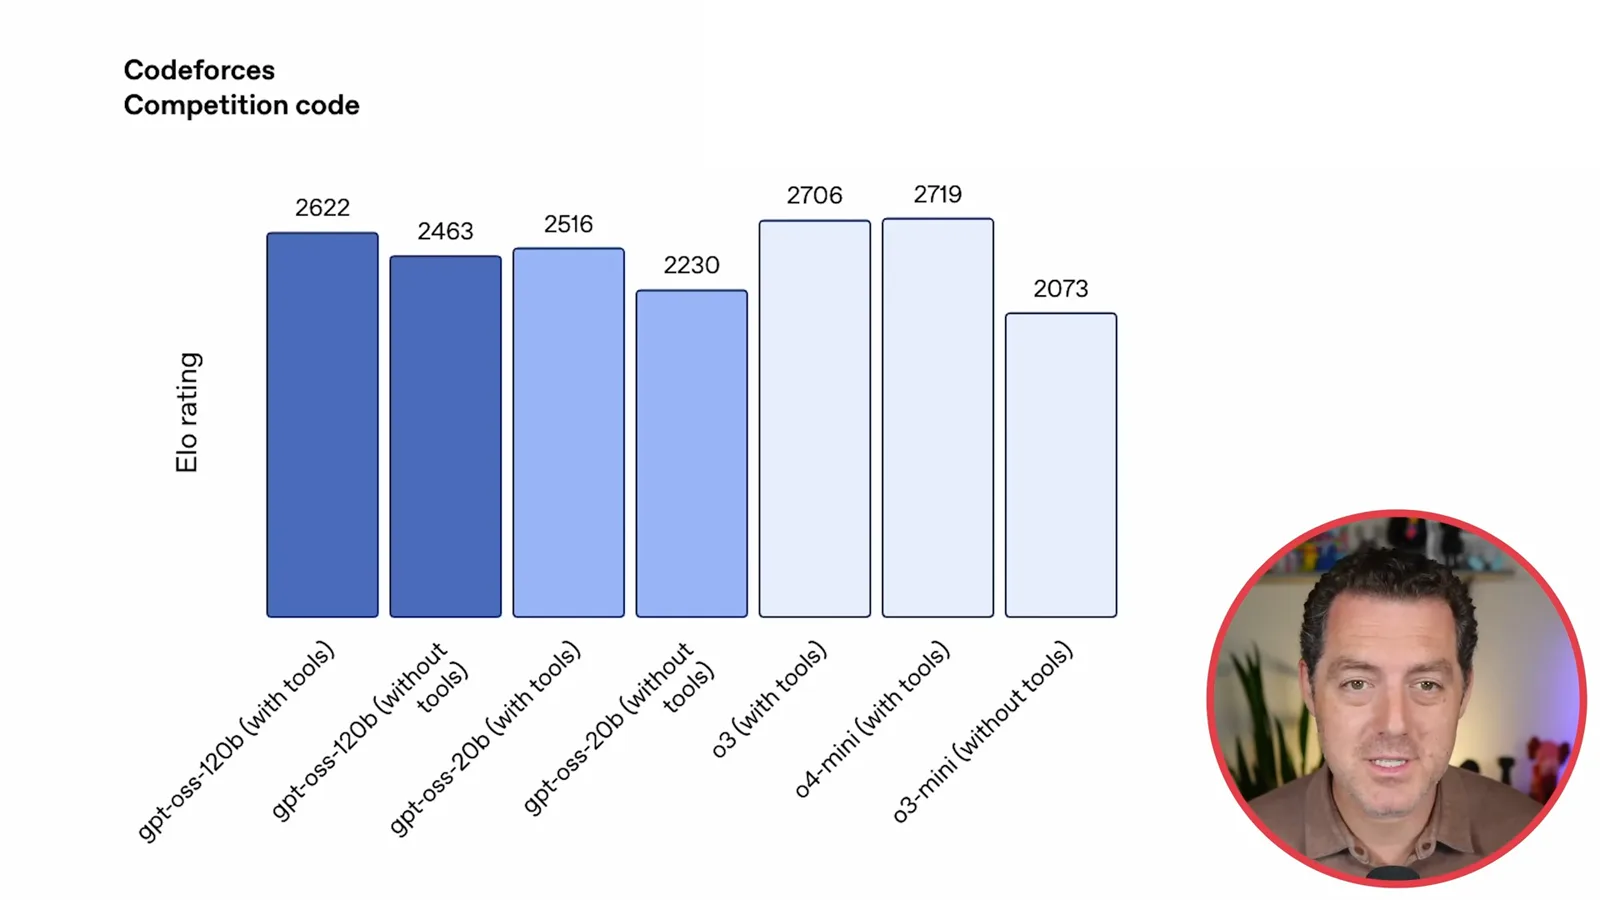
The displayed Codeforces estimates give gpt-oss-120b with tools a 2622 rating and gpt-oss-20b with tools 2516, compared with 2706 for o3 with tools. These are benchmark estimates under specified conditions, not direct proof that the models outperform most humans at every programming job.
On the displayed Humanity’s Last Exam and HealthBench comparisons, the larger model is below o3 in the examples Berman cites, though the results are close on some tests. He also reviews AIME, GPQA, MMLU and TAU-bench; test configuration and tool access matter when interpreting any score.
Safety and red teaming
OpenAI discusses monitoring, fine-tuning evaluations and a red-team challenge. The tests have a defined scope.
OpenAI said the models’ chain of thought was not directly supervised for alignment and discussed monitoring it for possible misbehavior. It cautioned developers against displaying raw reasoning directly because it may contain harmful or inaccurate content; such traces are not a complete or infallible safety monitor.
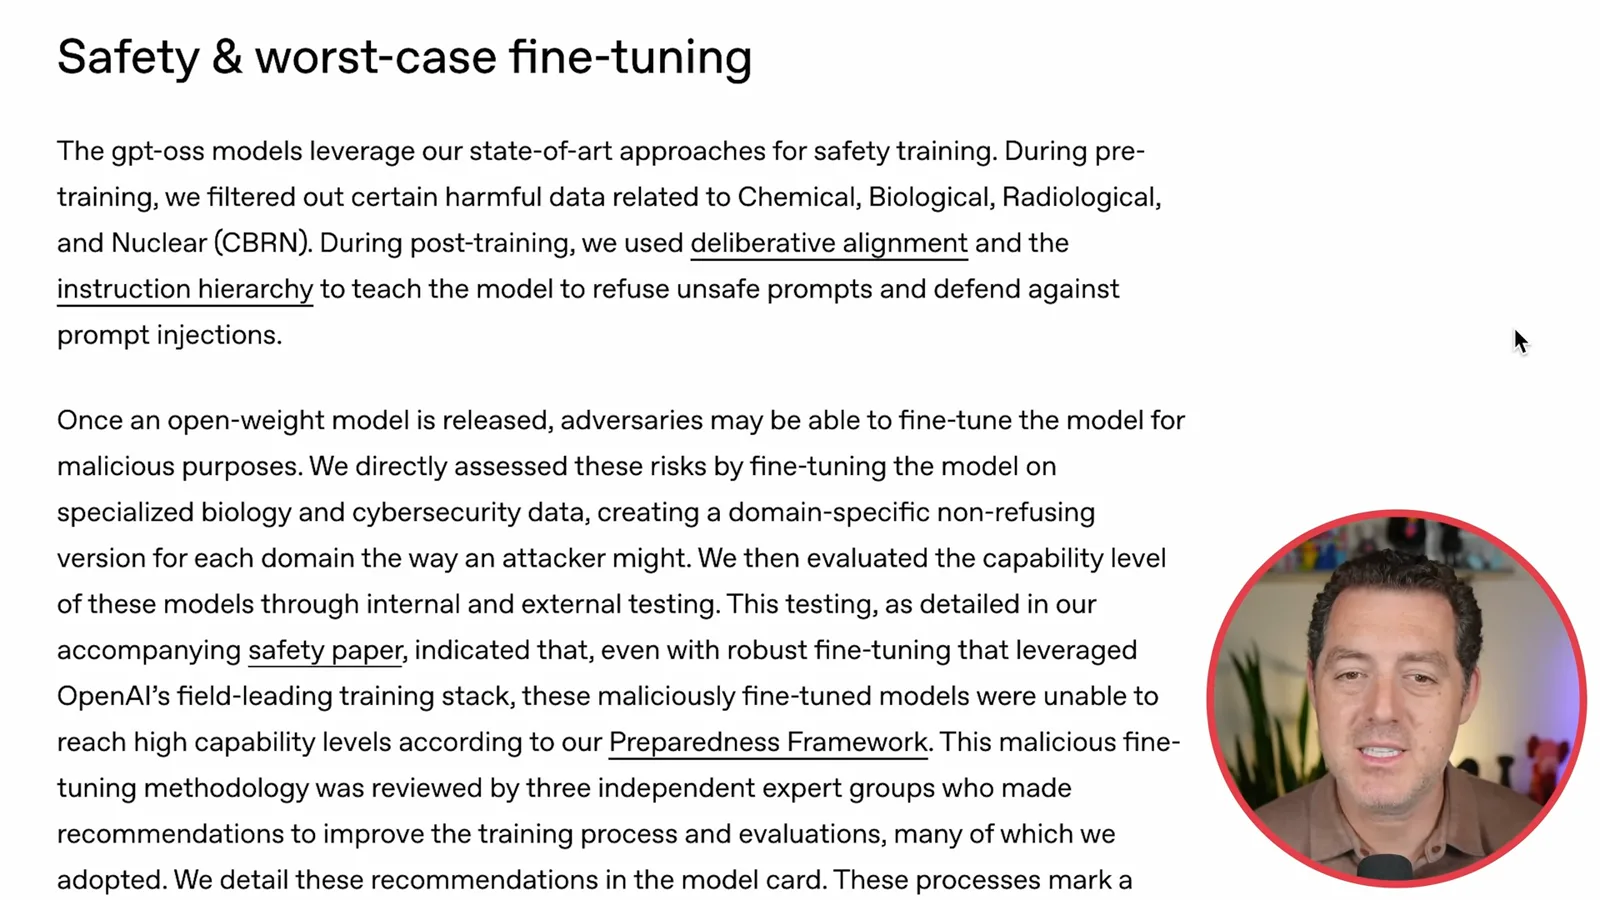
The company described filtering some harmful pretraining data and evaluating worst-case fine-tuning in biology and cybersecurity. It reported that the modified models did not reach its framework’s high-capability threshold in those tests. That finding does not mean harmful fine-tuning or unsafe outputs are impossible.
OpenAI also announced a red-teaming challenge with awards to find safety issues. I plan a fuller hands-on test and point viewers to the sponsor’s hosted option. The figures and availability described here are from the 2025 launch.
Mehr aus diesem Kanal
 34:21EN
 Matthew Berman· 27. Okt. 2026Matthew Berman Examines Anthropic’s IPO Filing, AI Growth and GovernanceMatthew Berman, Sam Altman · Forward FutureThe presenter reviews the S-1’s financial metrics, compute strategy and voting structure while questioning the tension between rapid AI development and safety.
 0:36ENMatthew Berman· 25. Okt. 2026Kimi K3.1 and a Rubik’s Cube Solver DemonstrationMatthew Berman · Forward FutureMatthew Berman shows a scrambled virtual cube being solved and gives the Kimi K3.1 test a favorable assessment.
 25:50ENMatthew Berman· 24. Okt. 2026Kimi K3.1 Pro Tested: Strong 3D Demos, Uneven Results and Competitive PricingMatthew Berman · Forward FutureMatthew Berman tests the open-weight model on coding, 3D rendering and visual explanations, then compares benchmark results and prices.
 32:20ENMatthew Berman· 23. Okt. 2026Who Is Local AI For? The Costs, Trade-offs and a Hybrid FutureMatthew Berman · Forward FutureMatthew Berman weighs data control and independence against hardware cost, setup complexity and inference speed.
 1:03:37ENMatthew Berman· 23. Okt. 2026Matthew Berman’s Team Tests Kimi K3.1 on Animation, Games, and ChartsMatthew Berman, Alex, Brian · Forward FutureA live team AMA turns into an informal test of Kimi K3.1, from personal-agent workflows to motion graphics, a browser game, and a benchmark chart.
 0:53ENMatthew Berman· 22. Okt. 2026Sam Altman on AI and the Discovery of New KnowledgeSam Altman · OpenAIAltman expects progress in mathematical discovery to extend to biology, materials and energy.