30초 요약
Berman explains how Meta-Harness proposes, evaluates and records candidate agent harnesses. He reviews classification, math retrieval and Terminal-Bench results, then predicts broader self-improving software; the paper’s results concern specific experimental settings.
- 1The proposerA coding agent inspects files and proposes harness edits.
- 2Classification resultsThe paper reports average gains, though ACE wins on one dataset.
- 3Math retrievalA discovered strategy improves the paper’s held-out model comparisons.
- 4Terminal tasksReported pass rates are compared on Terminal-Bench 2.
핵심 정리
- A harness controls tools, memory and context around a model.
- Meta-Harness uses a coding agent to inspect prior runs and propose candidate changes.
- The paper reports improvements on several evaluated tasks, with exceptions and setup-specific comparisons.
- Lower runtime context alone does not capture the full cost of search.
- Claims about AGI or all software self-evolving are predictions, not conclusions proved by the benchmarks.
챕터별로 다듬은 전문 읽기
Harnesses and self-improvement
Berman introduces the paper and distinguishes the model from its harness.
I review the Meta-Harness research, which searches for improvements to the code surrounding a language model. My prediction that all software will soon evolve itself is a forecast; the paper evaluates specific tasks and does not establish that broad outcome.
A harness supplies the infrastructure around model weights: tools, memory, retrieval, file access and rules for how the system operates. Different harness choices can change the performance of the same underlying model.
I compare the idea with Andrej Karpathy’s autoresearch project, which repeatedly proposes and tests training experiments. Meta-Harness instead uses an outer search loop to improve harness code for a target task.
The researchers argue that model weights alone do not determine system performance. I believe current models could reach AGI with the right harness, but that is my opinion and is not demonstrated by these benchmark results.
The optimization loop
A coding agent examines earlier runs, proposes changes and receives feedback.
The paper asks whether harness engineering can be automated. A difficulty is that a decision to store or retrieve information can affect behavior many steps later, so reducing a long execution trace to a single score can hide the cause of failure.
Rather than packing all history into one prompt, the approach lets the agent access external context selectively. The goal is to inspect the relevant information when needed, including previous experiments and their traces.
The proposer is a coding agent that can use developer tools and edit code. It inspects previous harnesses, scores and execution traces through file operations, decides what to change and submits another candidate for evaluation.
The file system stores source code, evaluation scores and details such as prompts, tool calls and outputs. The agent can inspect more than the latest or best candidate, giving it access to useful failures as well as successes.
The method draws on external memory, retrieval and executable program search. The outer loop remains relatively simple: propose a harness, evaluate it, save the evidence and repeat for a fixed number of iterations.
The proposer chooses what to inspect and whether to make a small edit or a larger rewrite. Berman expects stronger coding agents to improve this process, but the claimed recursive acceleration is an interpretation and prediction, not an experimentally established law.
Classification and transfer
The paper compares harnesses on classification and held-out datasets.
The experiments use Claude Code with Opus 4.6 as proposer and evaluate text classification, retrieval-assisted mathematical reasoning and terminal tasks. The comparisons include human-designed harnesses and other search methods.
On three classification datasets, the paper reports an average accuracy of 48.6 for its selected harness versus 40.9 for ACE, with 11.4 thousand additional context tokens versus 50.8 thousand. ACE performs better on USPTO, so the result is not a win on every dataset.
The paper identifies USPTO-50k as a chemistry task predicting precursor reactants from product molecules, not simply a general patent-office classification task. The other datasets concern symptoms and legal charges.
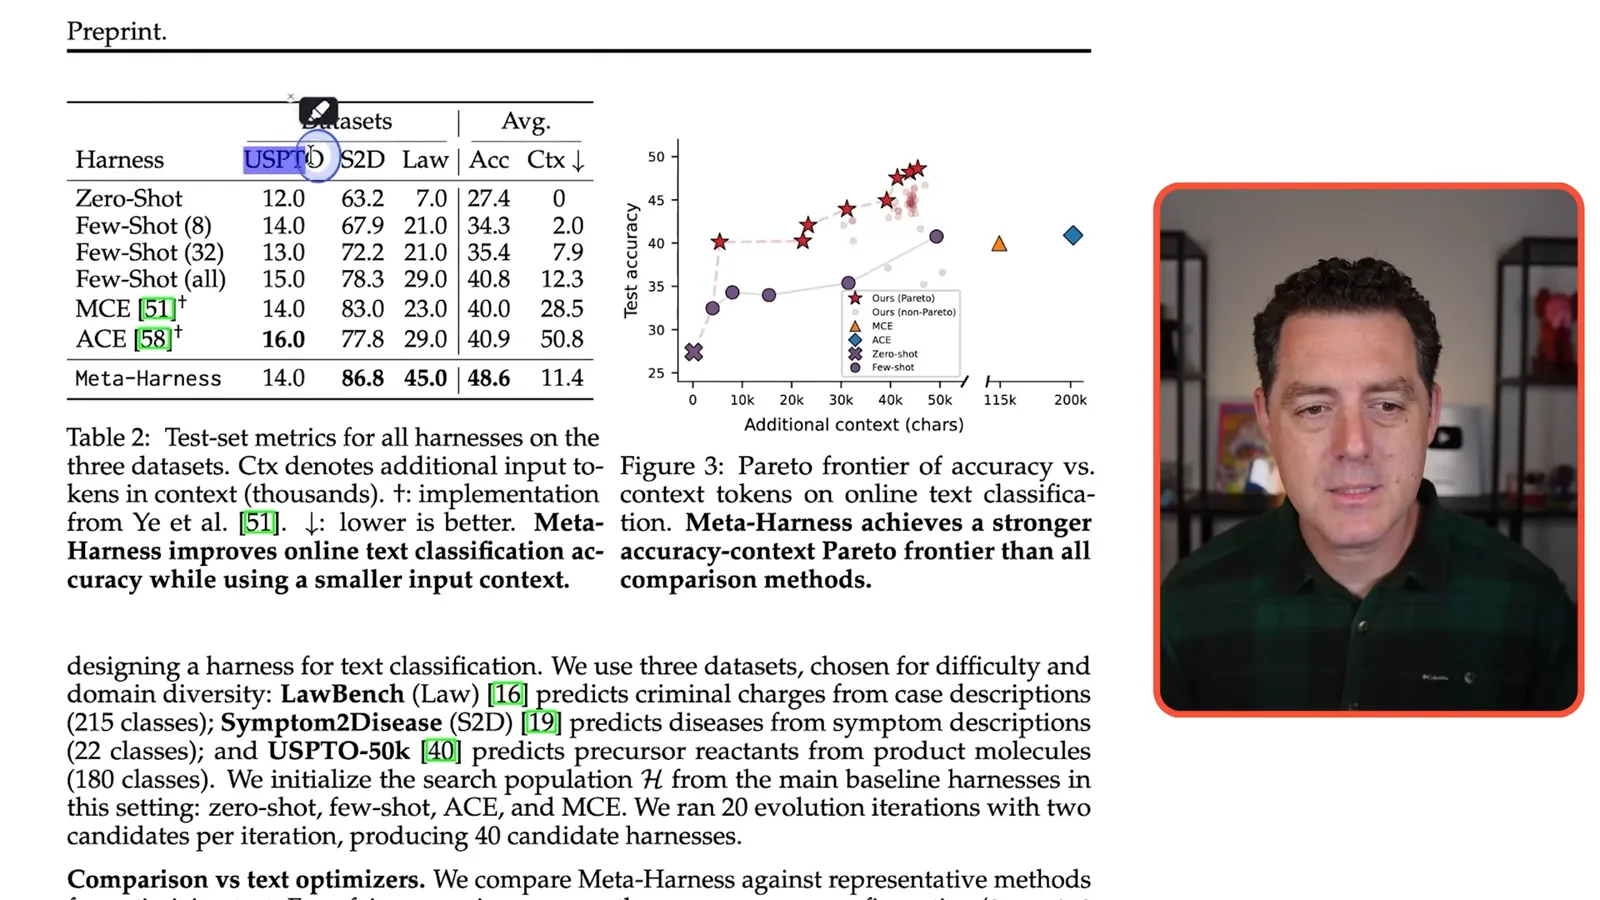
The authors also compare against other optimization methods and report strong search results using fewer full evaluations in their setup. A lower context count is not by itself a complete accounting of the cost of searching and evaluating candidate harnesses.
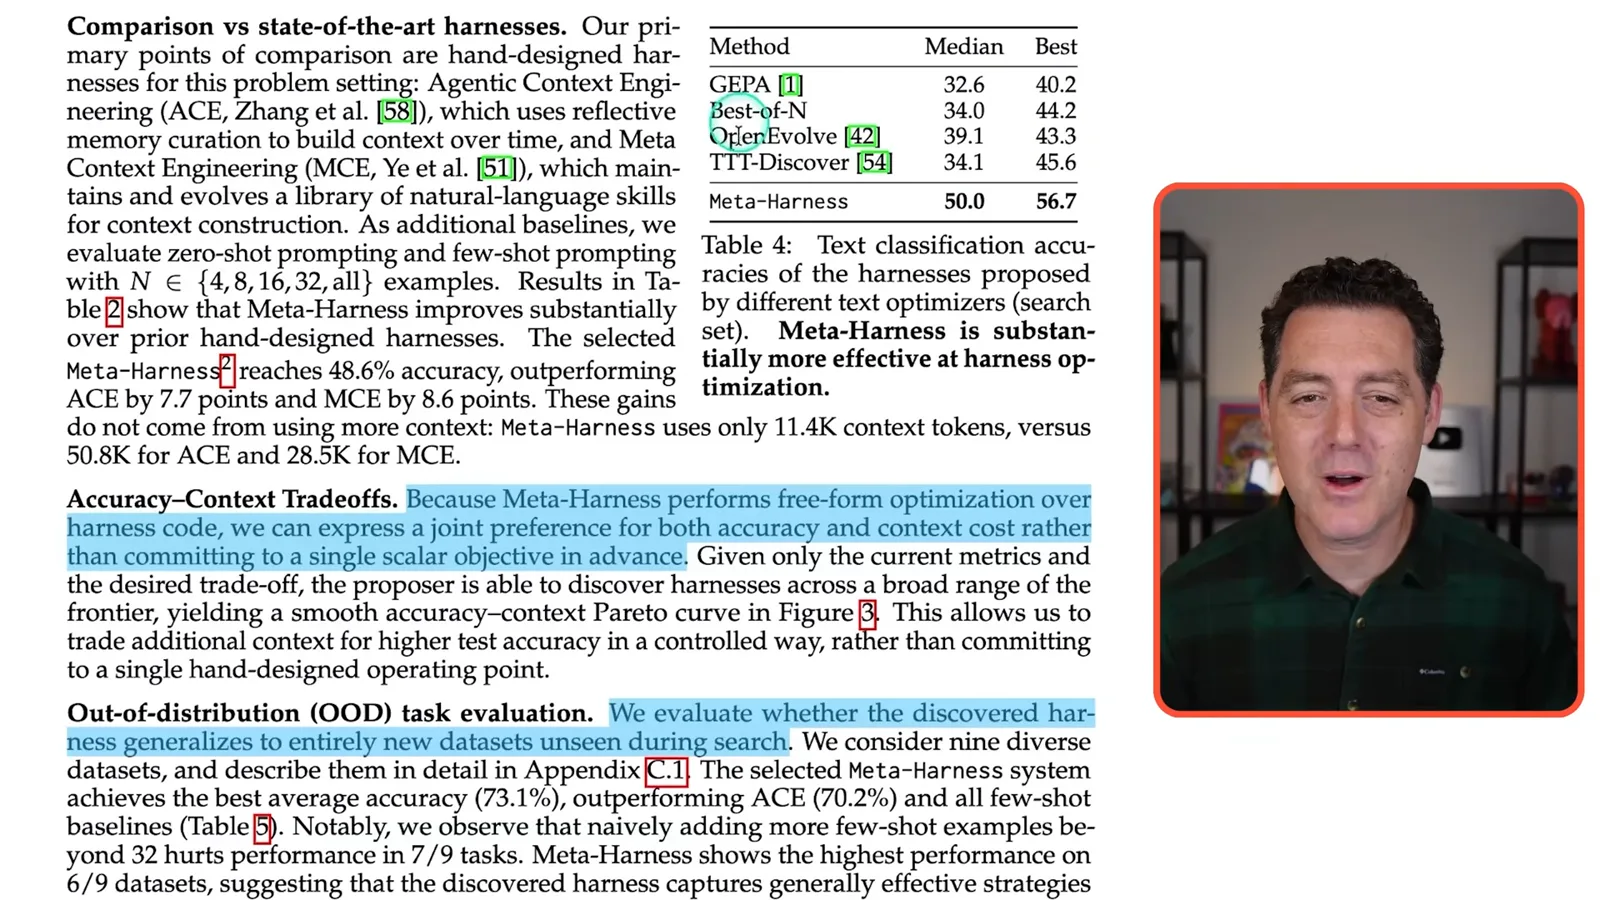
On nine datasets held out from search, the paper reports average accuracy of 73.1 versus 70.2 for ACE. It reports the best result on six of nine datasets, evidence of transfer within this evaluation rather than proof of universal generalization.
Math and terminal benchmarks
Berman reviews retrieval and terminal results and offers his predictions.
For Olympiad-level mathematical reasoning, the discovered retrieval strategy improves results across five held-out models by an average of 4.7 points over no retrieval. The proposed intuition is that earlier solutions can contain reusable proof patterns.
Terminal-Bench 2 tests long-horizon tasks requiring terminal interaction. The paper reports a 76.4% pass rate with Opus 4.6, below the listed ForgeCode result, and 37.6% with Haiku 4.5 versus 35.5% for the next listed Haiku agent.
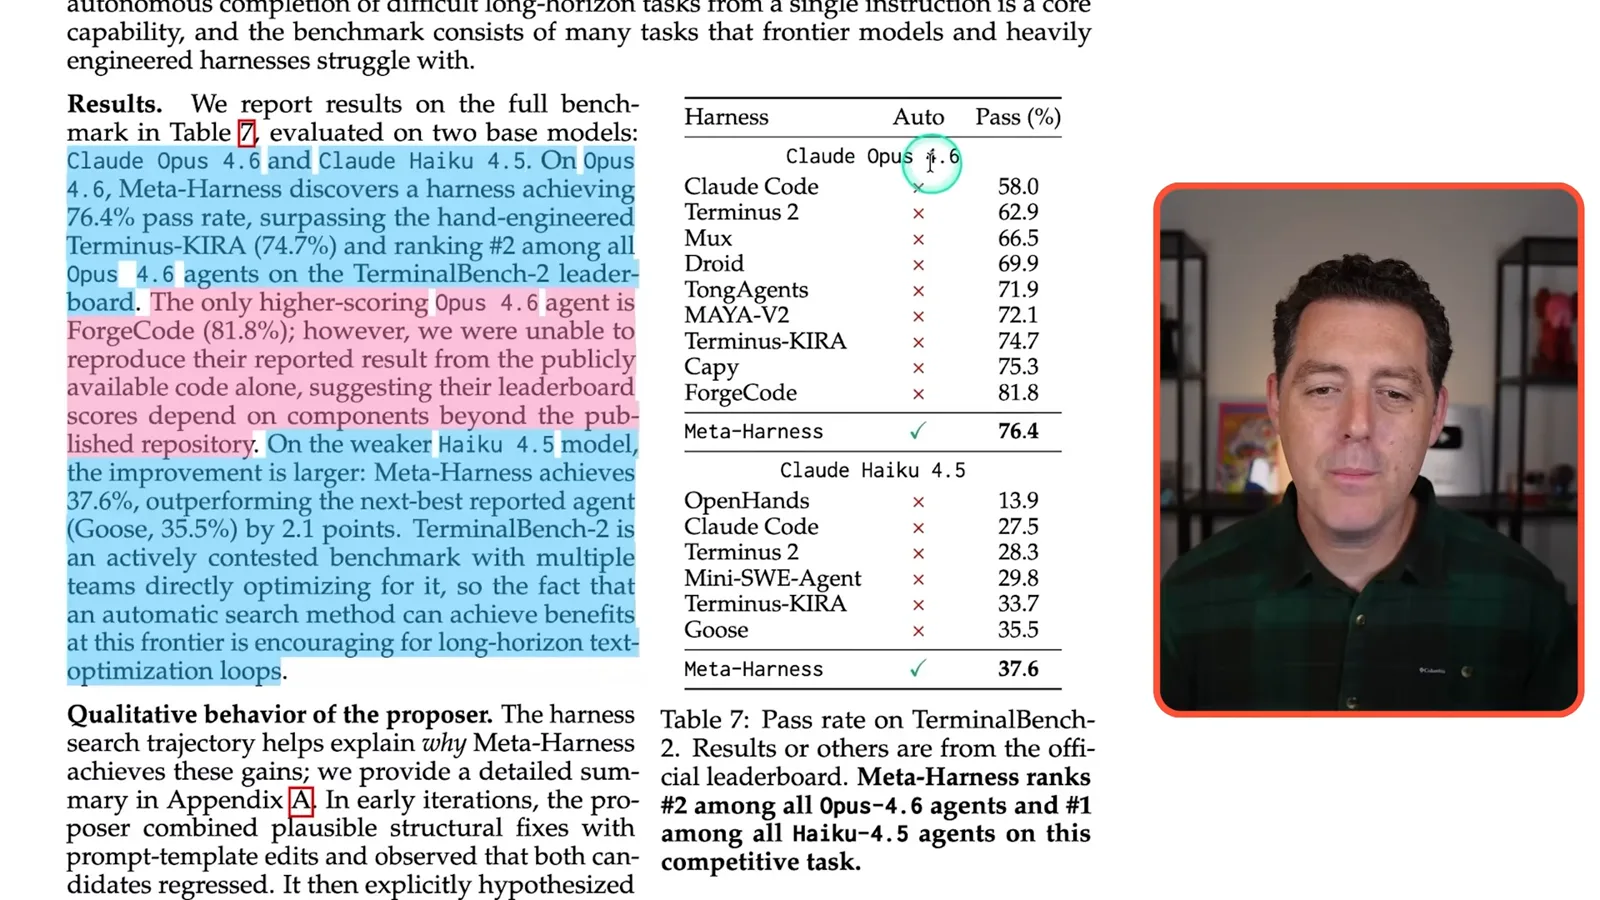
I connect the results to the “bitter lesson” and argue that learned methods will replace hand-written heuristics. That is my broad interpretation; these particular comparisons do not prove that AI-written systems always outperform human-designed ones.
I expect more software and harnesses to be improved through repeated automated experiments. The paper offers evidence for the tested search procedure, while real deployments would still need suitable evaluations, cost accounting and oversight.
같은 채널의 다른 글
 34:21EN
 Matthew Berman· 2026년 10월 27일Matthew Berman Examines Anthropic’s IPO Filing, AI Growth and GovernanceMatthew Berman, Sam Altman · Forward FutureThe presenter reviews the S-1’s financial metrics, compute strategy and voting structure while questioning the tension between rapid AI development and safety.
 0:36ENMatthew Berman· 2026년 10월 25일Kimi K3.1 and a Rubik’s Cube Solver DemonstrationMatthew Berman · Forward FutureMatthew Berman shows a scrambled virtual cube being solved and gives the Kimi K3.1 test a favorable assessment.
 25:50ENMatthew Berman· 2026년 10월 24일Kimi K3.1 Pro Tested: Strong 3D Demos, Uneven Results and Competitive PricingMatthew Berman · Forward FutureMatthew Berman tests the open-weight model on coding, 3D rendering and visual explanations, then compares benchmark results and prices.
 32:20ENMatthew Berman· 2026년 10월 23일Who Is Local AI For? The Costs, Trade-offs and a Hybrid FutureMatthew Berman · Forward FutureMatthew Berman weighs data control and independence against hardware cost, setup complexity and inference speed.
 1:03:37ENMatthew Berman· 2026년 10월 23일Matthew Berman’s Team Tests Kimi K3.1 on Animation, Games, and ChartsMatthew Berman, Alex, Brian · Forward FutureA live team AMA turns into an informal test of Kimi K3.1, from personal-agent workflows to motion graphics, a browser game, and a benchmark chart.
 0:53ENMatthew Berman· 2026년 10월 22일Sam Altman on AI and the Discovery of New KnowledgeSam Altman · OpenAIAltman expects progress in mathematical discovery to extend to biology, materials and energy.