30초 요약
Matthew Berman shows how Soundraw can arrange instrumental tracks, experiments with vocals in Synthesizer V and plays Google Research’s MusicLM samples. The availability and pricing described are historical and the vocal demo includes mistakes and limitations.
- 1Generated arrangementsSoundraw offers mood, genre and section-energy controls.
- 2Editable synthetic singingBerman assigns lyrics and notes to a voice and adjusts its characteristics.
- 3Text-to-music researchMusicLM examples include text, sequential prompts and melody conditioning.
핵심 정리
- Soundraw’s demonstrated controls include mood, arrangement, tempo and instrumentation.
- Synthesizer V allows notes, lyrics and vocal characteristics to be edited.
- The host’s first vocal example has pronunciation and musical-quality issues.
- MusicLM was presented as research with sample outputs at the time of the video.
- The tools provide different forms of control rather than identical workflows.
챕터별로 다듬은 전문 읽기
Soundraw arrangements
Berman explores instrumental generation and historical pricing.
In this February 2023 video I explore three approaches to AI music: arranging generated instrumental tracks, synthesizing vocals and research on generating music from descriptions. The products and prices I mention reflect that time.
Soundraw generates instrumental options from selected moods and genres. I choose several mood tags and preview tracks, then adjust the energy of different sections to create a buildup.
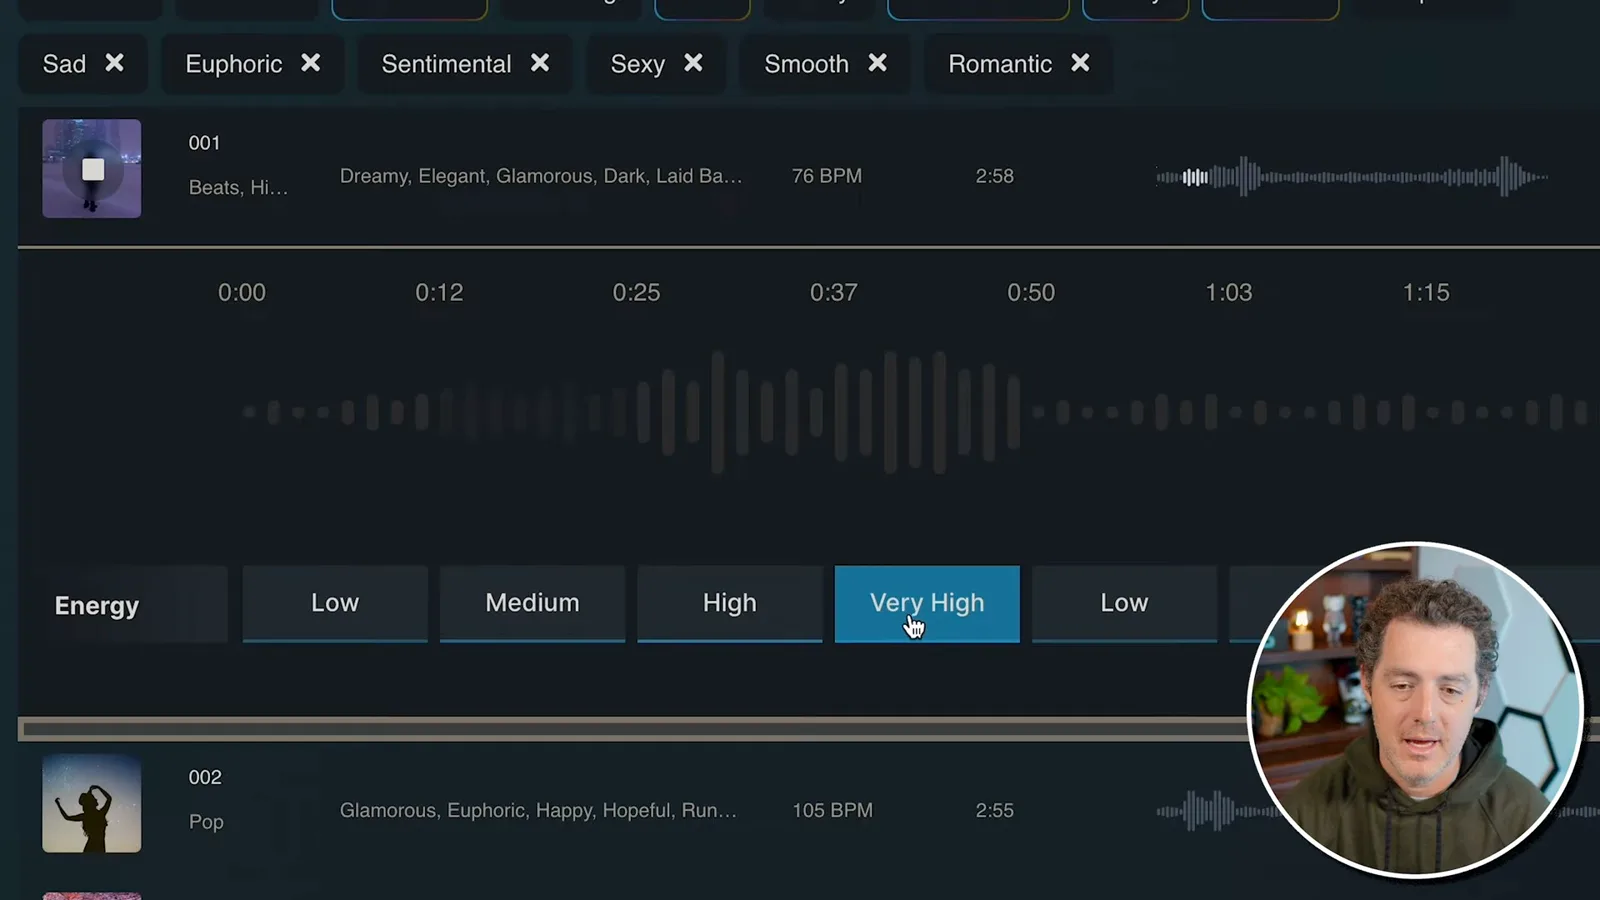
In the demonstrated pro mode, the arrangement can be adjusted by component, including melody, backing, bass, drums and fills. Tempo, duration, key and instruments offer further control over the result.
I try different genres and themes, including tutorial and technology, to show how selections produce different tracks. The interface also offers a way to find similar music and preview a track under a video.
I describe a free generation and bookmarking tier and a paid download plan then listed around $16.99 per month. Those are historical terms from 2023 and should not be assumed to be current.
Synthesizer V vocals
He experiments with notes, lyrics and synthetic voice settings.
Next I demonstrate Dreamtonics’ Synthesizer V, a desktop application for assigning lyrics and notes to a synthetic singing voice. I used ChatGPT to draft lyrics and chose the Natalie voice for my experiment.
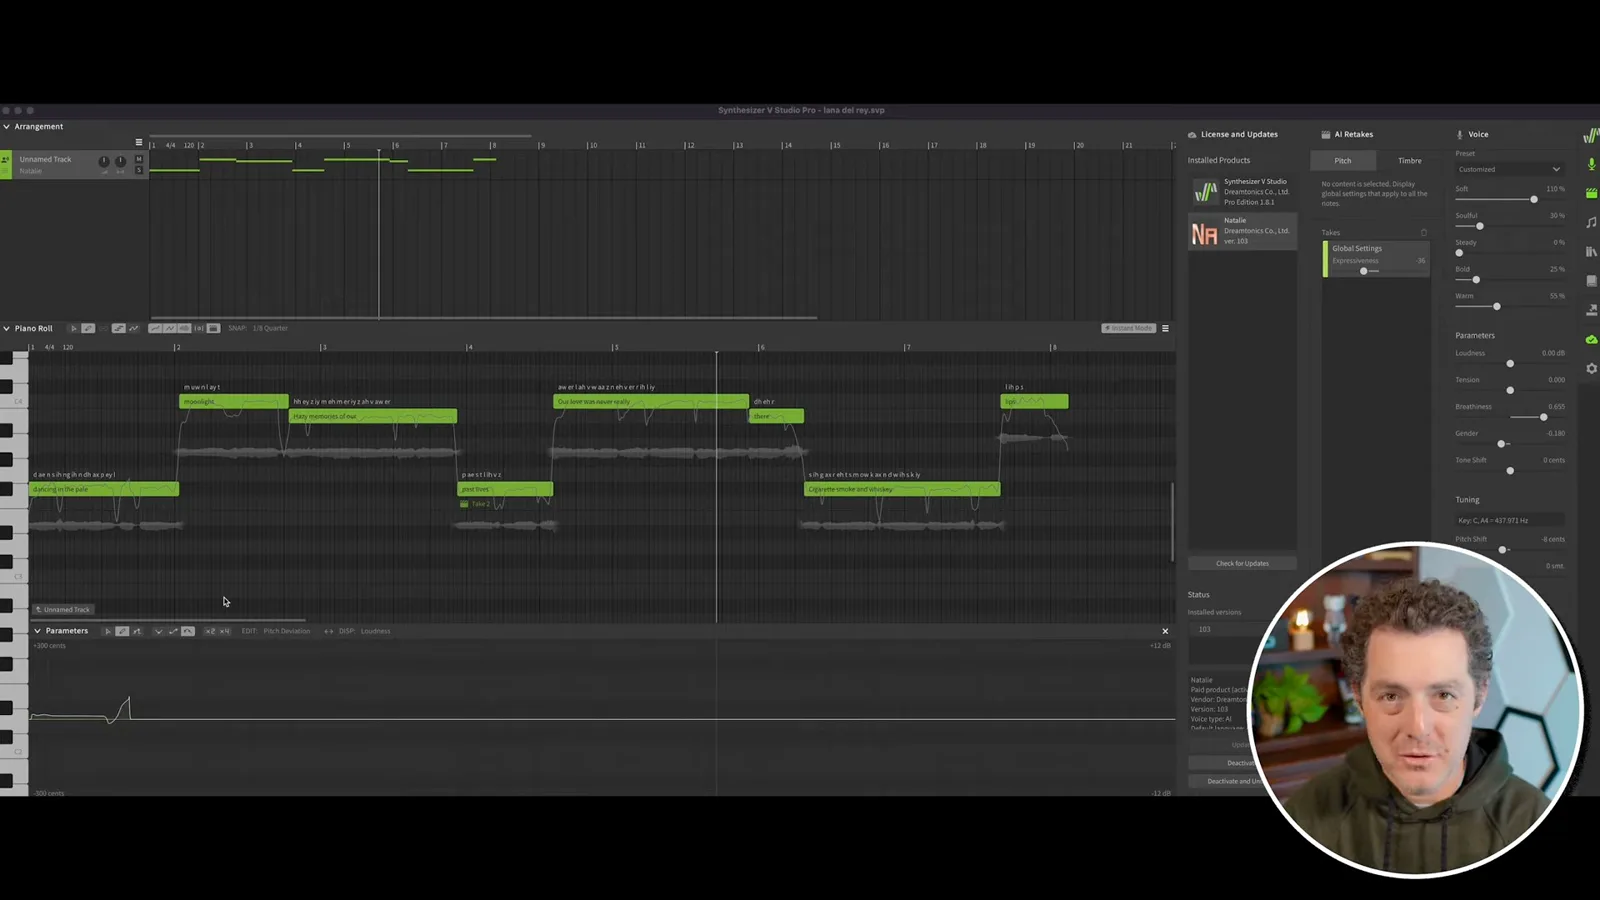
I describe my own musical knowledge as limited and am not satisfied with the first result; I notice a pronunciation problem in the vocal. The example illustrates both the possibility and the need for editing.
The editor lets me place notes, enter lyrics and adjust voice parameters such as softness, breathiness, pitch and key. Moving notes and lining up syllables changes the synthesized performance.
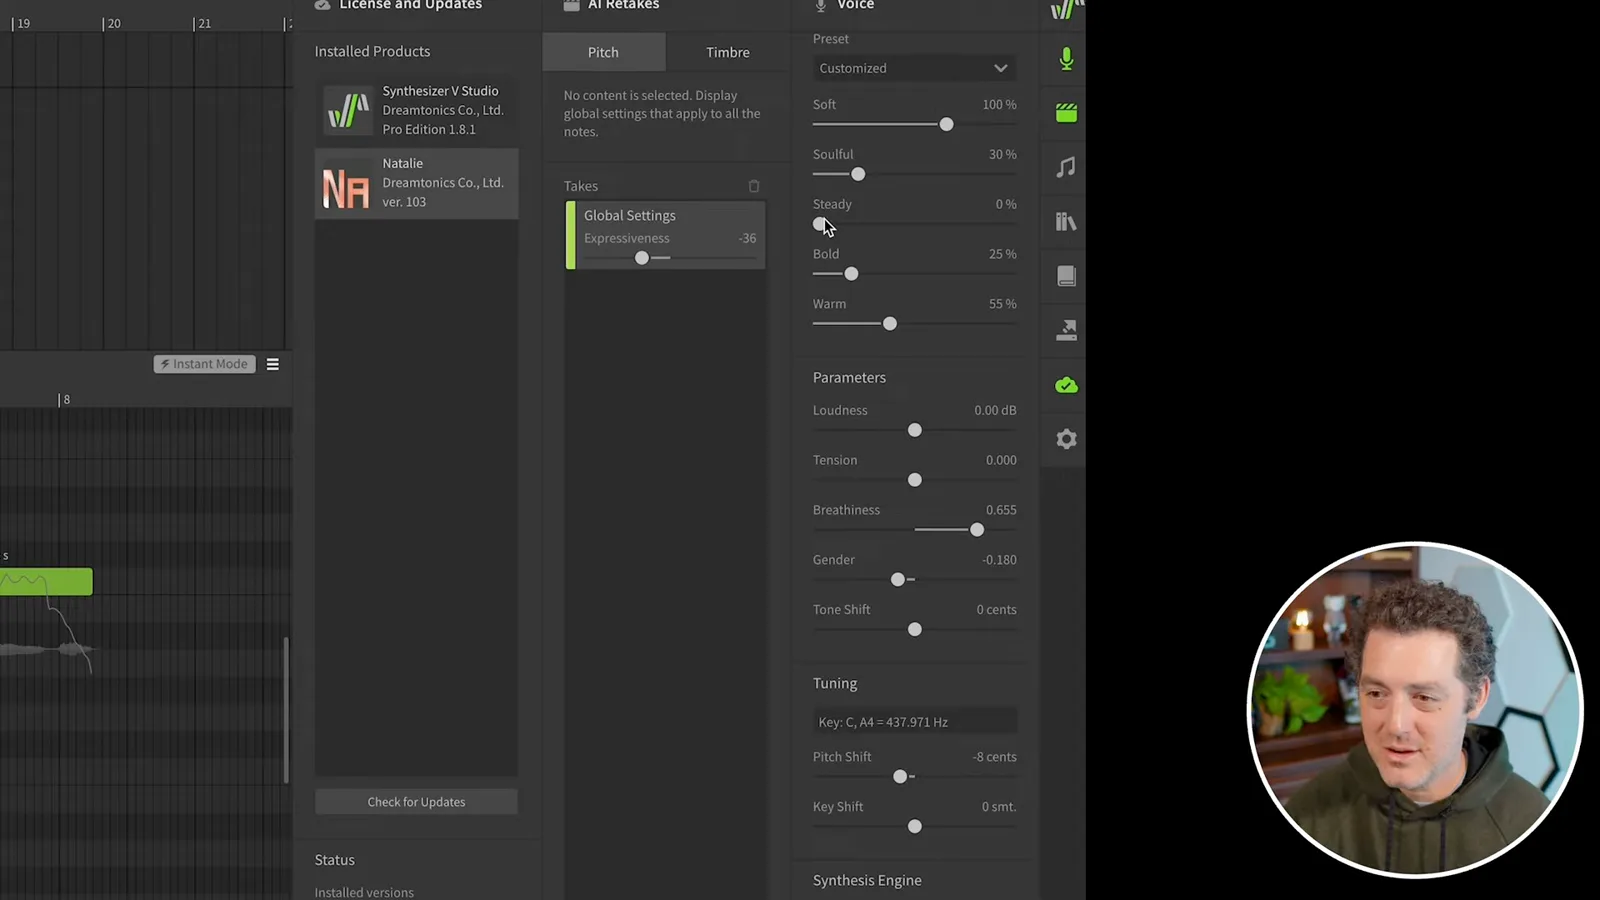
I suggest combining an instrumental track with synthesized vocals and show the available voice options from Dreamtonics. Some voices and the fuller product version were paid offerings in the demonstration.
MusicLM research
He listens to text-to-music examples and shows different conditioning methods.
The final example is Google Research’s MusicLM, which generates music from text descriptions. At the time of this video Berman could only play research examples, not use it as a publicly available interactive product.
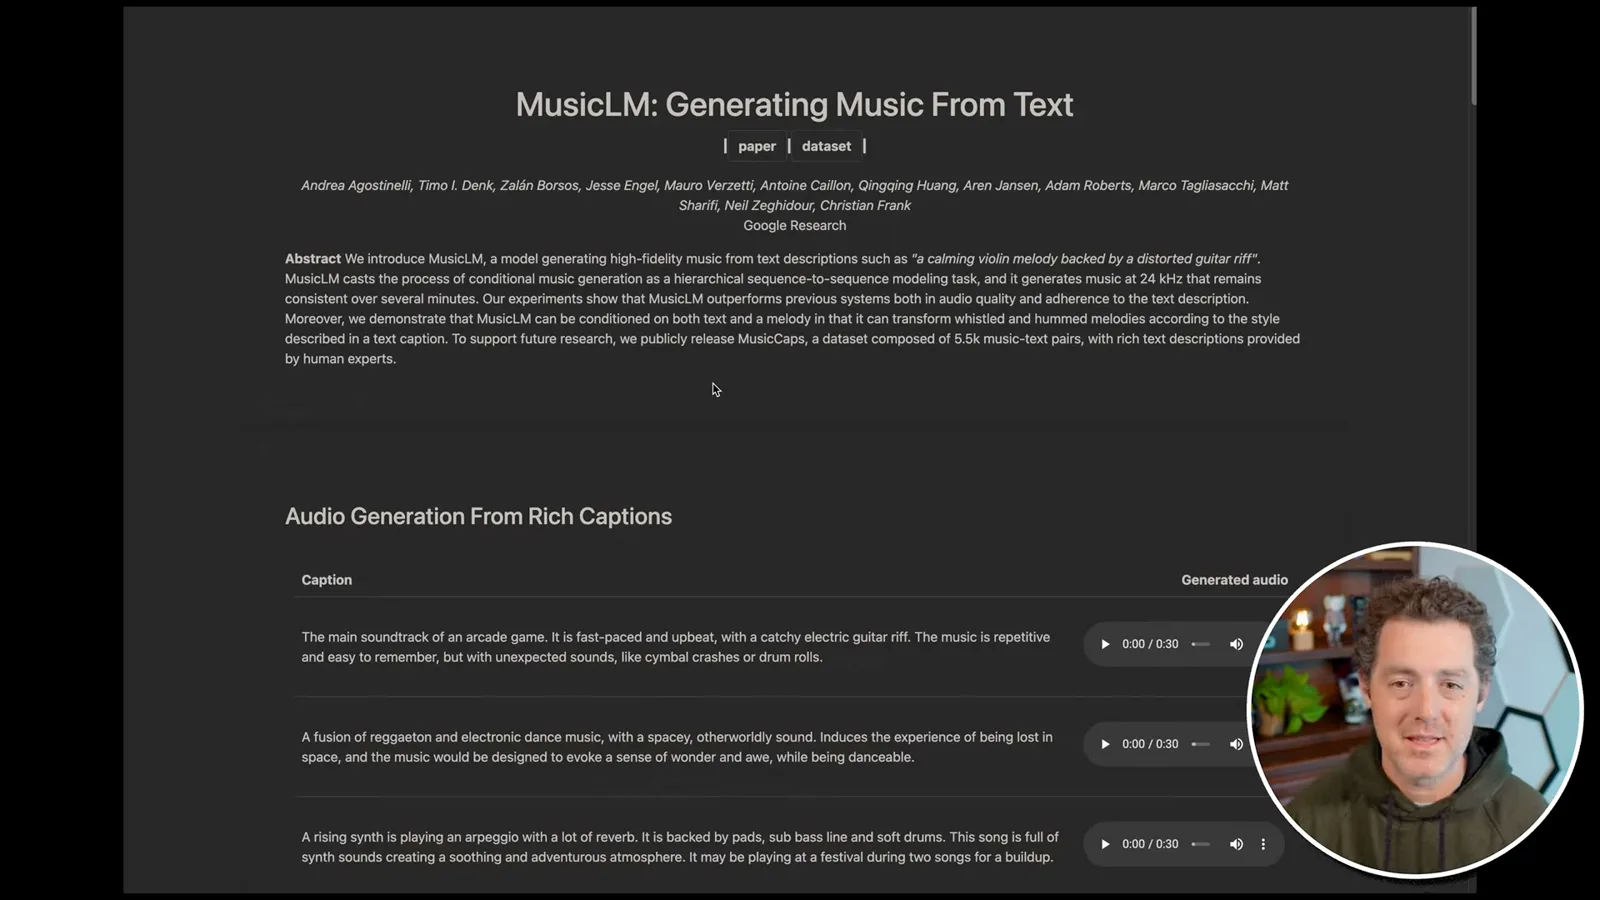
I listen to examples prompted as an arcade soundtrack and a fusion of electronic dance music with reggaeton. The examples demonstrate the research direction, but listening to a few samples is not a broad evaluation of quality or originality.
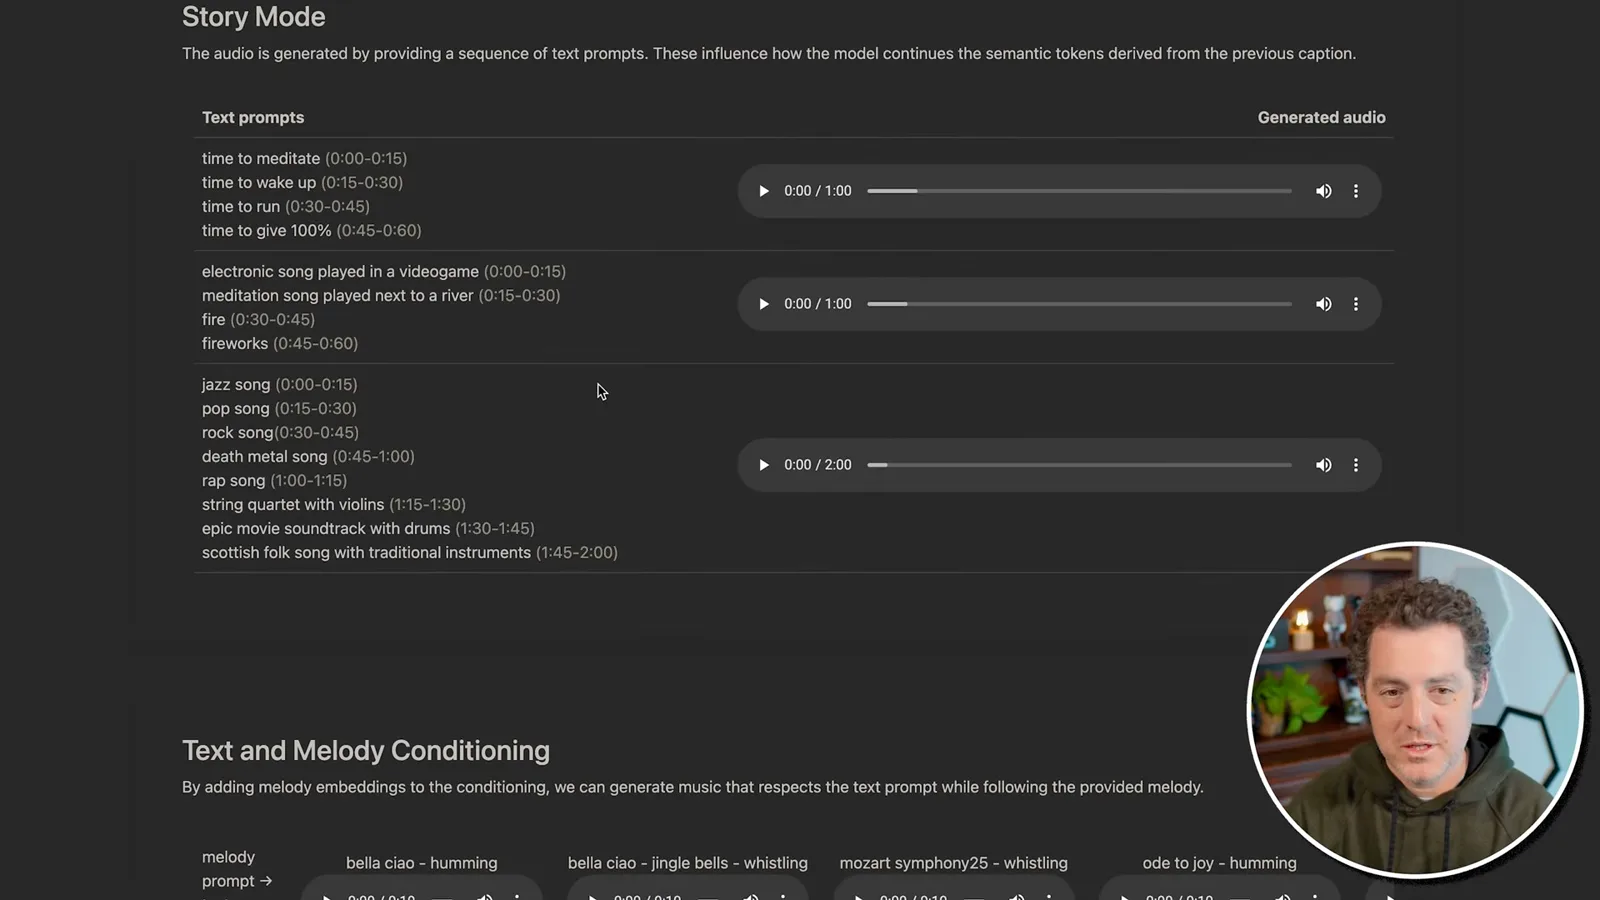
The research page also demonstrates sequences of prompts that change the music over time and conditioning on a supplied melody as well as text. I show examples of humming or whistling as melodic inputs.
I play an example connected to a visual artwork and look at instrument-specific samples. I anticipate that text-to-music tools will become more accessible, a prediction made from the research state visible in 2023.
I conclude by comparing the accessible arrangement and vocal tools with the then research-only text-to-music demonstration. Each offers a different degree of control and requires different creative input.
같은 채널의 다른 글
 34:21EN
 Matthew Berman· 2026년 10월 27일Matthew Berman Examines Anthropic’s IPO Filing, AI Growth and GovernanceMatthew Berman, Sam Altman · Forward FutureThe presenter reviews the S-1’s financial metrics, compute strategy and voting structure while questioning the tension between rapid AI development and safety.
 0:26ENMatthew Berman· 2026년 10월 25일Sam Altman on Human Values and Problem-Solving in an AI WorldSam Altman · OpenAIIn a short interview excerpt, Altman considers the enjoyment of solving hard problems and the human role in interpreting results.
 0:36ENMatthew Berman· 2026년 10월 25일Kimi K3.1 and a Rubik’s Cube Solver DemonstrationMatthew Berman · Forward FutureMatthew Berman shows a scrambled virtual cube being solved and gives the Kimi K3.1 test a favorable assessment.
 0:21ENMatthew Berman· 2026년 10월 24일An AI-Generated Kimi Benchmark Chart Used Invented ScoresMatthew Berman · Forward FutureMatthew Berman asks for a graph of Kimi K3.1 Pro benchmarks, then discovers that the displayed figures are illustrative placeholders.
 25:50ENMatthew Berman· 2026년 10월 24일Kimi K3.1 Pro Tested: Strong 3D Demos, Uneven Results and Competitive PricingMatthew Berman · Forward FutureMatthew Berman tests the open-weight model on coding, 3D rendering and visual explanations, then compares benchmark results and prices.
 32:20ENMatthew Berman· 2026년 10월 23일Who Is Local AI For? The Costs, Trade-offs and a Hybrid FutureMatthew Berman · Forward FutureMatthew Berman weighs data control and independence against hardware cost, setup complexity and inference speed.