








필터 결과
155개정렬
 19:38EN
 Matthew Berman· 2025년 10월 20일Andrej Karpathy’s AGI Timeline, Learning Ideas and Critique of Coding AgentsMatthew Berman · Forward FutureMatthew Berman examines Karpathy’s 2025 arguments for a decade of agents, new learning approaches and closer human oversight of AI coding.
 16:12ENMatthew Berman· 2025년 10월 18일AI News in October 2025: Claude Skills, DGX Spark and a Proposed AGI MeasureMatthew Berman, Jensen Huang, Elon Musk, Jeff Bezos · Forward FutureMatthew Berman reviews product announcements, early research and predictions, from reusable agent skills to orbital data centers.
 15:43ENMatthew Berman· 2025년 10월 13일How AI Data Centers Work: Power, Cooling and Community TradeoffsMatthew Berman · Forward FutureMatthew Berman explains the physical infrastructure behind AI prompts, from accelerator racks and backup power to water use and local planning.
 15:54ENMatthew Berman· 2025년 10월 1일Claude Sonnet 4.5: Coding, Long Tasks and a Simulated DesktopMatthew Berman, Dario Amodei · Forward FutureMatthew Berman reviews Anthropic’s launch claims and tries a generated-interface demo.
 26:17ENMatthew Berman· 2025년 9월 30일21 Practical AI Uses for Design, Work and ResearchMatthew Berman · Forward FutureMatthew Berman demonstrates ways to use image tools, ChatGPT and NotebookLM for visual concepts, research, everyday work and study.
 17:51ENMatthew Berman· 2025년 8월 28일AI News in August 2025: Claude for Chrome, New Models and AI InfrastructureMatthew Berman · Forward FutureMatthew Berman reviews a browser-agent preview, model releases, reported Apple discussions and research on inference and weather.
 18:31ENMatthew Berman· 2025년 8월 27일Testing Nano Banana: Gemini 2.5 Flash Image EditingMatthew Berman · Forward FutureMatthew Berman tests character consistency, image edits, generation, visual sequences and common failure cases.
 23:41ENMatthew Berman· 2025년 8월 19일GPT-5 Prompting: Agent Behavior, Coding and Prompt OptimizationMatthew Berman · Forward FutureMatthew Berman walks through OpenAI’s 2025 prompting guide and demonstrates a tool for revising developer instructions.
 15:08ENMatthew Berman· 2025년 8월 8일GPT-5 at Launch: Routing, Coding, Benchmarks and ReliabilityMatthew Berman · Forward FutureMatthew Berman reviews OpenAI’s 2025 GPT-5 release, its unified ChatGPT experience, benchmark claims and the limitations of model evaluations.
 25:24ENMatthew Berman· 2025년 8월 7일GPT-5 Tested on Coding, Simulations and Multimodal TasksMatthew Berman · Forward FutureMatthew Berman tries browser applications, visual simulations and image prompts, showing both successes and defects in his early hands-on tests.
 15:30ENMatthew Berman· 2025년 7월 31일Qwen3 Tested: Coding Demos, Long Context and Response BehaviorMatthew Berman · Forward FutureMatthew Berman tests generated simulations, political and safety prompts, hand tracking and word puzzles using a hosted Qwen3 model.
 27:40ENMatthew Berman· 2025년 6월 28일Seedance 1.0 vs. Veo 3: An Informal Text-to-Video ComparisonMatthew Berman · Forward FutureMatthew Berman compares visual quality, motion and prompt adherence across gymnastics, action, animation and fantasy scenes.
 20:00ENMatthew Berman· 2025년 6월 19일Sam Altman on Meta’s Hiring, GPT-5 and the Future of AIMatthew Berman, Sam Altman, Jack Altman, Andrew Mayne · Forward FutureMatthew Berman examines 2025 interview clips in which OpenAI’s CEO discusses competition for researchers, scientific discovery, robots and new AI hardware. His claims and forecasts are presented in their historical context.
 22:05ENMatthew Berman· 2025년 6월 9일Apple’s “Illusion of Thinking”: Puzzle Limits and a Code-Assisted TestMatthew Berman, Ilya Sutskever · Forward FutureMatthew Berman reviews Apple’s reasoning-model experiments and tests a different way to solve Tower of Hanoi using generated code.
 15:55ENMatthew Berman· 2025년 5월 28일AI Shutdown Resistance and Blackmail in Controlled Safety TestsMatthew Berman · Forward FutureMatthew Berman examines Palisade’s shutdown experiment, Apollo’s simulated scheming evaluations and Anthropic’s Claude 4 system card.
 26:01ENMatthew Berman· 2025년 5월 27일Testing Veo 3: Convincing Video, Generated Audio and Physics FailuresMatthew Berman · Forward FutureMatthew Berman and a collaborator test Google’s 2025 video model with street interviews, cinematic scenes, visual puzzles and edited short films.
 15:35ENMatthew Berman· 2025년 5월 24일Claude 4 Reactions: Safety Tests, Model Welfare and CodingMatthew Berman · Forward FutureMatthew Berman reviews early reactions to Anthropic’s May 2025 Claude 4 release, from simulated whistleblowing to coding demonstrations and model-welfare research.
 15:13ENMatthew Berman· 2025년 5월 10일Absolute Zero: Training a Reasoner on Self-Generated Coding TasksMatthew Berman · Forward FutureMatthew Berman examines a 2025 paper in which a pretrained language model proposes and solves code tasks using verifiable feedback.
 27:20ENMatthew Berman· 2025년 4월 29일Dario Amodei’s Case for Urgent AI Interpretability ResearchMatthew Berman · Forward FutureMatthew Berman examines Anthropic’s interpretability work, experimental safety findings and the debate over how quickly understanding can advance.
 19:06ENMatthew Berman· 2025년 4월 25일Sleep-Time Compute: Preparing AI Context Before a QuestionMatthew Berman · Forward FutureMatthew Berman reviews a 2025 paper on moving some reasoning ahead of a user query, and explains where its experiments found benefits and limits.
 26:35ENMatthew Berman· 2025년 4월 23일Testing Gemini 2.5 Flash on Coding and Video UnderstandingMatthew Berman · Forward FutureMatthew Berman compares Google’s faster model with Gemini 2.5 Pro through interactive simulations, games and questions about a long video.
 15:15ENMatthew Berman· 2025년 4월 19일Early Reactions to OpenAI o3 and o4-mini: Tool Use, Math and MistakesMatthew Berman · Forward FutureMatthew Berman reviews 2025 demos and benchmark reports, from location guessing and coding to simple failures that challenge the hype.
 15:45ENMatthew Berman· 2025년 4월 18일AI News: Gemini 2.5 Flash, OpenAI Models, Claude Research and Kling 2.0Matthew Berman · Forward FutureMatthew Berman reviews a week of 2025 model releases, research tools and agent announcements, including historical price and benchmark comparisons.
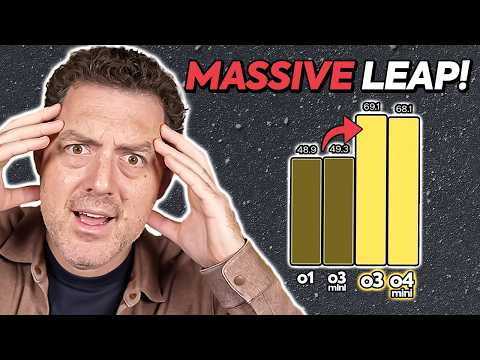 15:46ENMatthew Berman· 2025년 4월 16일OpenAI o3 and o4-mini: Tool Use, Benchmarks and the First Codex CLIMatthew Berman · Forward FutureMatthew Berman reviews OpenAI’s April 2025 reasoning-model release, a scientific image-analysis demonstration and the debut of its terminal coding agent.
더 보기155개 중 24개 표시