30초 요약
Matthew Berman reviews Andrej Karpathy’s post following his Dwarkesh podcast appearance. Karpathy describes a ten-year-plus AGI timeline, distinguishes model learning from animal evolution and questions how much current reinforcement learning signals can teach. Berman adds his own more optimistic interpretation and explores Karpathy’s proposed system prompt learning, compact “cognitive core” and preference for collaborative coding agents. The discussion reflects views expressed in 2025, not established forecasts.
- 1A decade of agentsKarpathy expects extensive work to make agents useful at scale; Berman is more optimistic about the pace.
- 2Animals and models learn differentlyKarpathy contrasts evolutionary inheritance with neural networks trained on next-token prediction.
- 3The reinforcement learning critiqueOutcome rewards can reinforce flawed reasoning or discourage good steps when the final answer is wrong.
- 4Learning through notesSystem prompt learning would preserve explicit general problem-solving strategies for later tasks.
- 5A local cognitive coreKarpathy envisions a small multimodal model that uses tools and selectively consults the cloud.
- 6Collaborative codingHe wants agents to explain and verify manageable changes rather than deliver large amounts of unreviewed code.
핵심 정리
- Karpathy calls 2025–2035 the decade of agents and argues that broad deployment requires substantial integration and research.
- He compares animal capabilities shaped by evolution with neural networks trained to predict tokens.
- He questions noisy outcome-based reinforcement learning signals and sees promise in agentic interaction and explicit learned strategies.
- His proposed cognitive core favors capability over encyclopedic knowledge in a small, locally available model.
- For coding, Karpathy prefers understandable, verifiable chunks and human collaboration over long unattended agent runs.
챕터별로 다듬은 전문 읽기
AGI timelines and the decade of agents
Berman reviews Karpathy’s ten-year-plus estimate and his analogy between digital agents and physical robots. They differ in optimism about the pace and the work required.
Andrej Karpathy says artificial general intelligence is at least ten years away. After his discussion on the Dwarkesh podcast, he posted a longer clarification on X. I find the post just as interesting because it expands on his views of agents, learning and the work still needed for AGI.
Karpathy calls 2025–2035 the decade of agents. I take that to mean it may take a decade for agents to become useful, valuable and widespread across the economy. When I call 2025 the year of agents, I mean they are coming to the forefront of people’s attention and implementations; I am more optimistic about the pace.
He compares OpenAI’s Operator in the digital world with humanoid robots in the physical world. Operator can use a browser to work on a task without a specialized interface for each site. Both approaches point toward humans supervising lower-level automation, but Karpathy expects digital work to advance faster because manipulating bits is much cheaper than moving atoms.
Karpathy thinks the physical world may offer the larger market opportunity. I wonder whether knowledge work is larger for now, even if the physical opportunity could eventually expand beyond Earth. His point is that there is a huge amount of work to make agents actually function across the board.
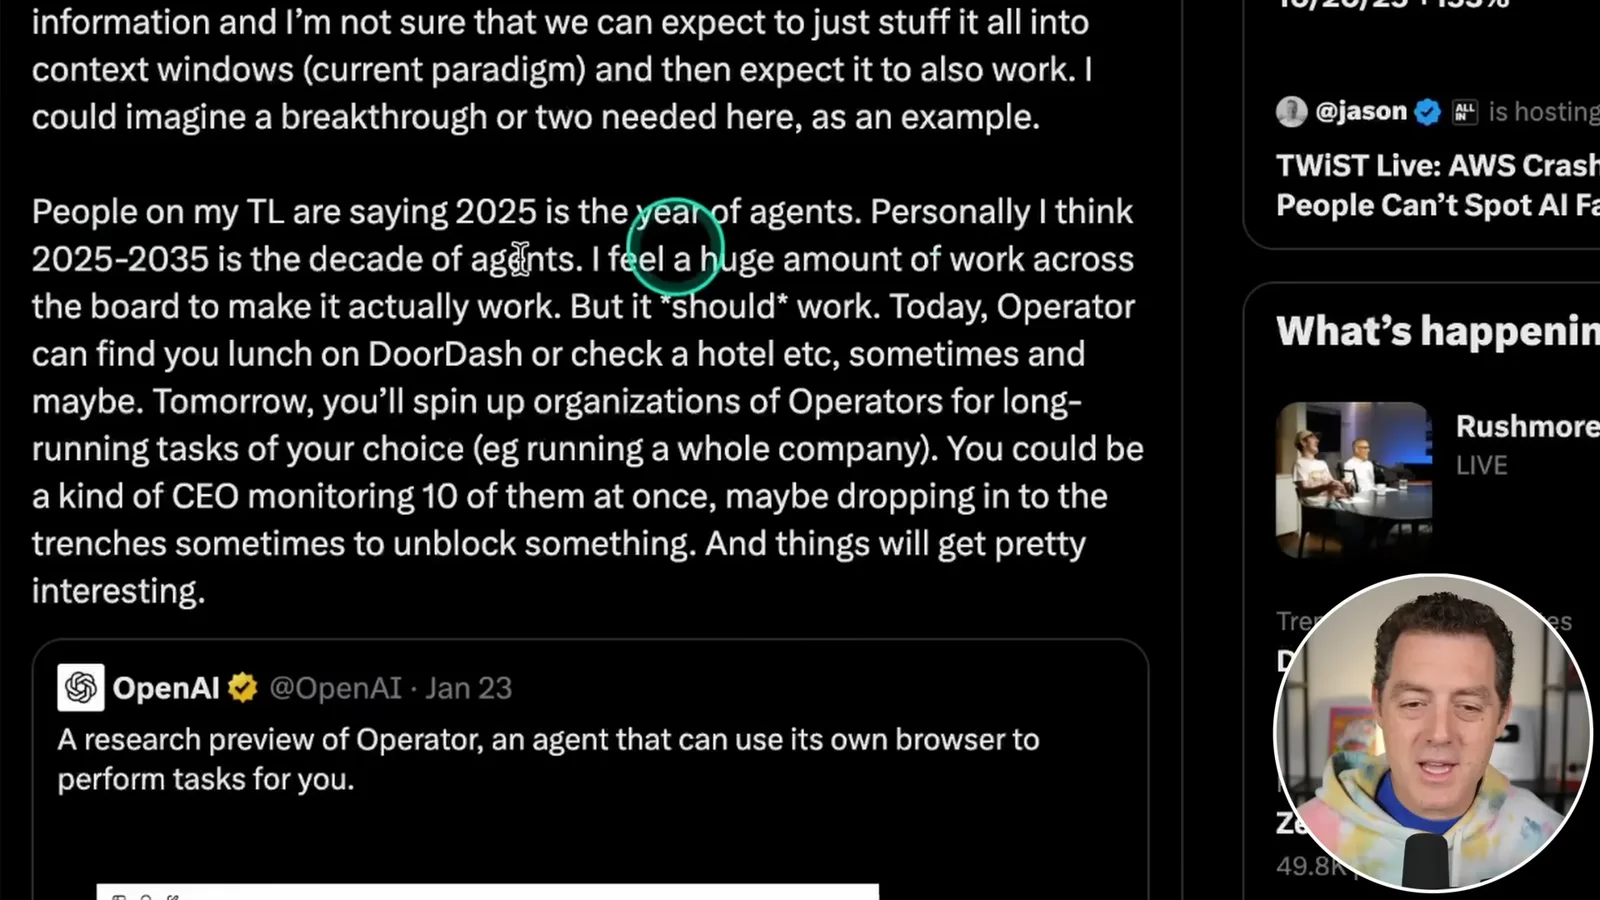
He places his AI timelines between the most enthusiastic people in his online circles and growing skepticism. He acknowledges enormous progress since ChatGPT appeared in 2022, but says integration, safety, security, physical sensors and actuators, social adaptation and further research remain before an AI is preferable to a person for an arbitrary job.
I think some of that work is scaffolding: tools, memory and infrastructure that let us make use of the intelligence already in the core models. Karpathy also thinks core capabilities themselves are not yet sufficient. He argues that a ten-year AGI timeline is still bullish, even if it sounds cautious against present hype; I expect it sooner.
Animals, language models and reinforcement learning
Karpathy contrasts evolved animal capabilities with token prediction. He also questions noisy reinforcement learning signals and considers other ways agents might learn.
Karpathy is skeptical that one simple algorithm can be unleashed on the world to learn everything from scratch. In his view, animals are not examples of that: evolution packages substantial intelligence into them before birth. A newborn zebra, for example, can stand and start walking shortly after birth.
He sees language models as a different route to building intelligence into a neural network: predicting the next token over internet data rather than evolving as animals do. He describes them as more like ghosts or spirits and thinks researchers can gradually make them more animal-like. I see generalization—learning to handle new problems rather than relying only on memorization—as central to AGI.
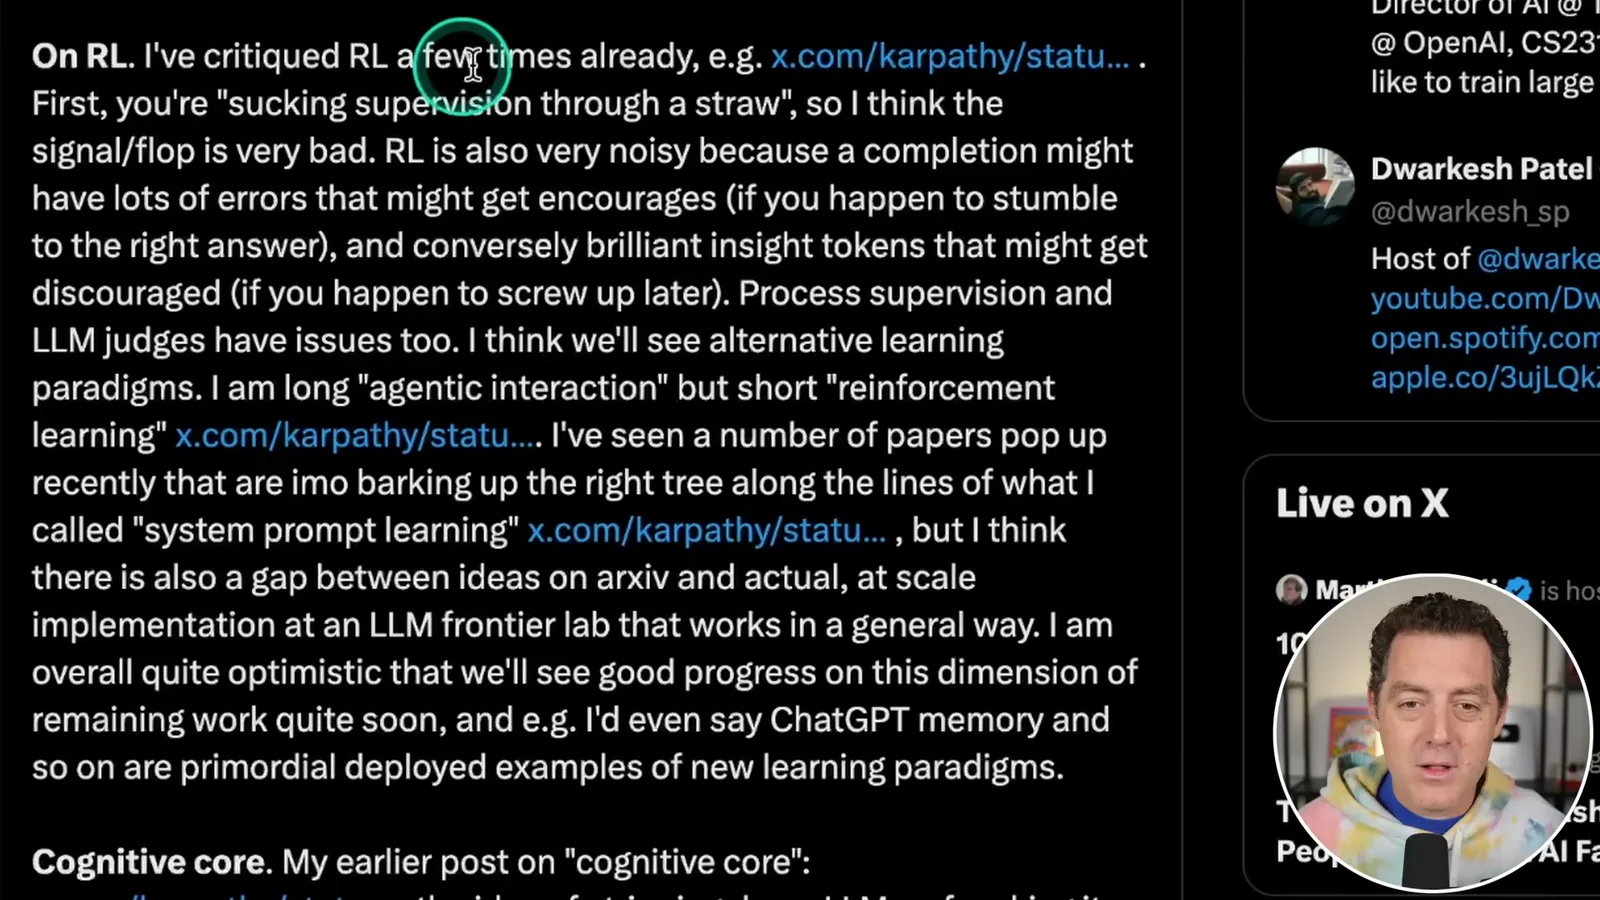
Karpathy also criticizes reinforcement learning. He argues that the supervision signal per unit of computation is poor and that the signal is noisy. I expect the efficiency to improve, but the question is whether it improves enough to produce the generalization we need.
His concern with outcome-based rewards is that a correct final answer can reward a chain of reasoning that contains errors, while a wrong answer can discourage useful intermediate insights. As a simple illustration, a model might make irrelevant or incorrect calculations along the way and still arrive at 1 + 1 = 2. A final-answer reward alone does not distinguish the good reasoning from the bad.
Conversely, useful intermediate steps might be penalized if the final answer is wrong. Karpathy says process supervision and LLM judges have their own problems too. He is optimistic about agentic interaction but skeptical of reinforcement learning as the main path, a striking position when frontier labs are investing heavily in it.
My interpretation of agentic interaction is to give agents environments in which they can experiment and learn. I think of game-playing work at DeepMind and companies building world models as examples of environments where digital or embodied agents can try things and learn from the results. Karpathy also points to research related to what he calls system prompt learning.
System prompt learning and the cognitive core
Karpathy proposes retaining explicit problem-solving strategies and describes a small local model centered on capability. Berman discusses context limits, memory and the proposed model’s features.
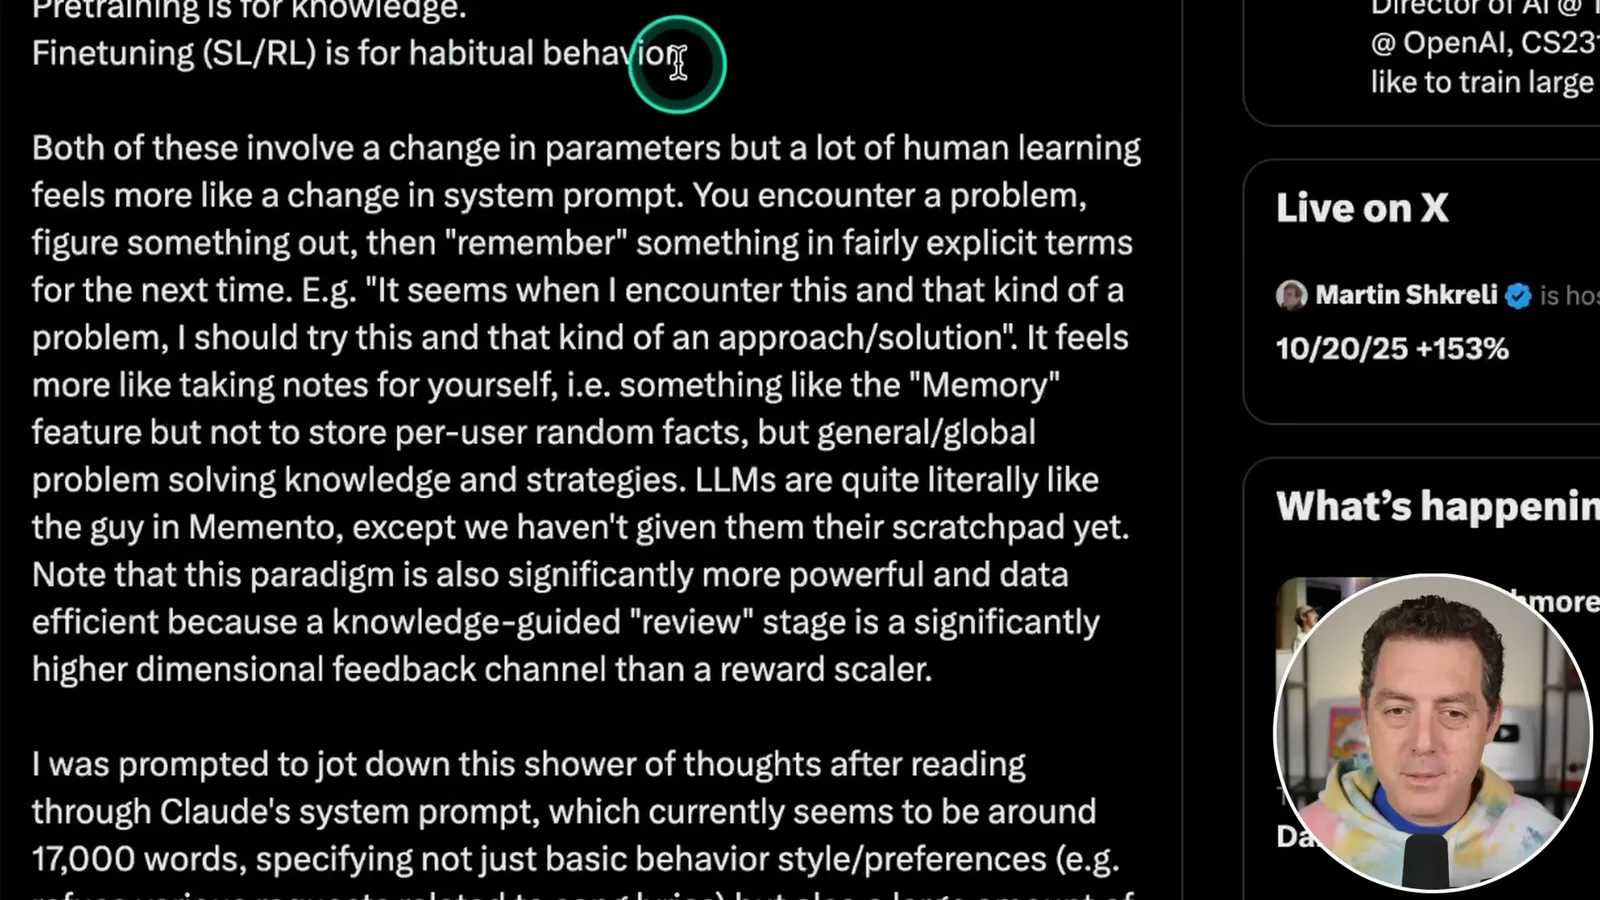
His distinction is that pretraining builds knowledge and fine-tuning shapes habitual behavior, both by changing model parameters. Much human learning, he suggests, resembles changing a system prompt: encounter a problem, figure something out and write down an explicit strategy for next time. A system prompt influences model behavior, although its space is limited by the context window.
He contrasts a memory of general problem-solving strategies with a feature that merely stores facts about an individual user. He notes that Claude’s system message was about 17,000 words in the version he examined and included instructions such as explicitly counting characters before answering. That kind of instruction can help with the familiar question of how many r’s are in “strawberry.”
Karpathy sees promising papers but a gap between research ideas and general implementations at production scale. He describes ChatGPT memory as a primitive deployed example of a potentially new learning paradigm. The vision is for models to retain useful lessons from experience in a form they can apply to later problems.
Another proposal is the “cognitive core”: a model that sacrifices encyclopedic knowledge to preserve useful capability. Karpathy suggests that humans’ inability to memorize everything might act like regularization, pushing us to generalize rather than always leaning on memory. The proposed core would have a few billion parameters and run persistently on a personal computer.
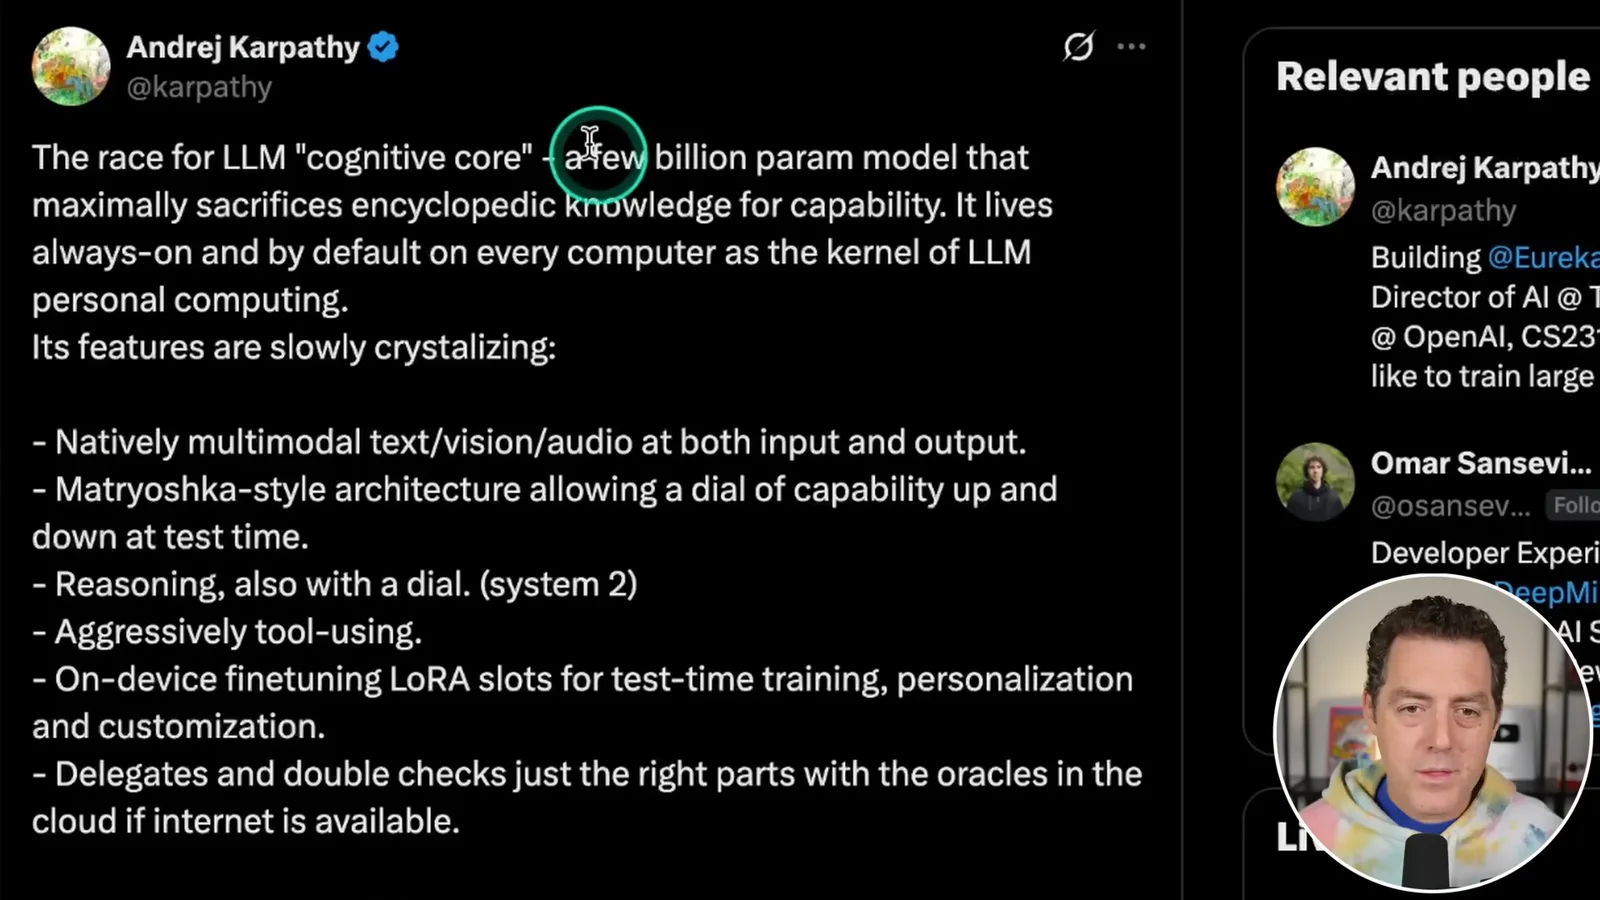
His suggested features include native text, vision and audio input and output; a Matryoshka-style architecture with adjustable capability; adjustable reasoning; and extensive tool use. It could use on-device LoRA slots for personalization and test-time training, while delegating or checking selected work with cloud models when connected. He wrote this in response to Google’s Gemma 3n.
Coding agents and collaboration
Karpathy argues that agent tooling can outpace model capabilities and prefers understandable, verifiable collaboration. Berman closes with Musk’s proposed coding contest and Karpathy’s reply.
Karpathy’s critique of the agent industry is that tooling can overshoot present model capability. He prefers collaboration that matches human and model strengths rather than asking an agent to work unattended for 20 or 30 minutes. He says his NanoChat project was built almost entirely by hand rather than through vibe coding.
He does not want an agent to return after 20 minutes with 1,000 lines of code, and does not feel ready to supervise ten such agents. Instead, he wants manageable chunks, explanations, evidence that the code is correct, and checks against API documentation. He wants the model to make fewer assumptions and ask to collaborate when uncertain.
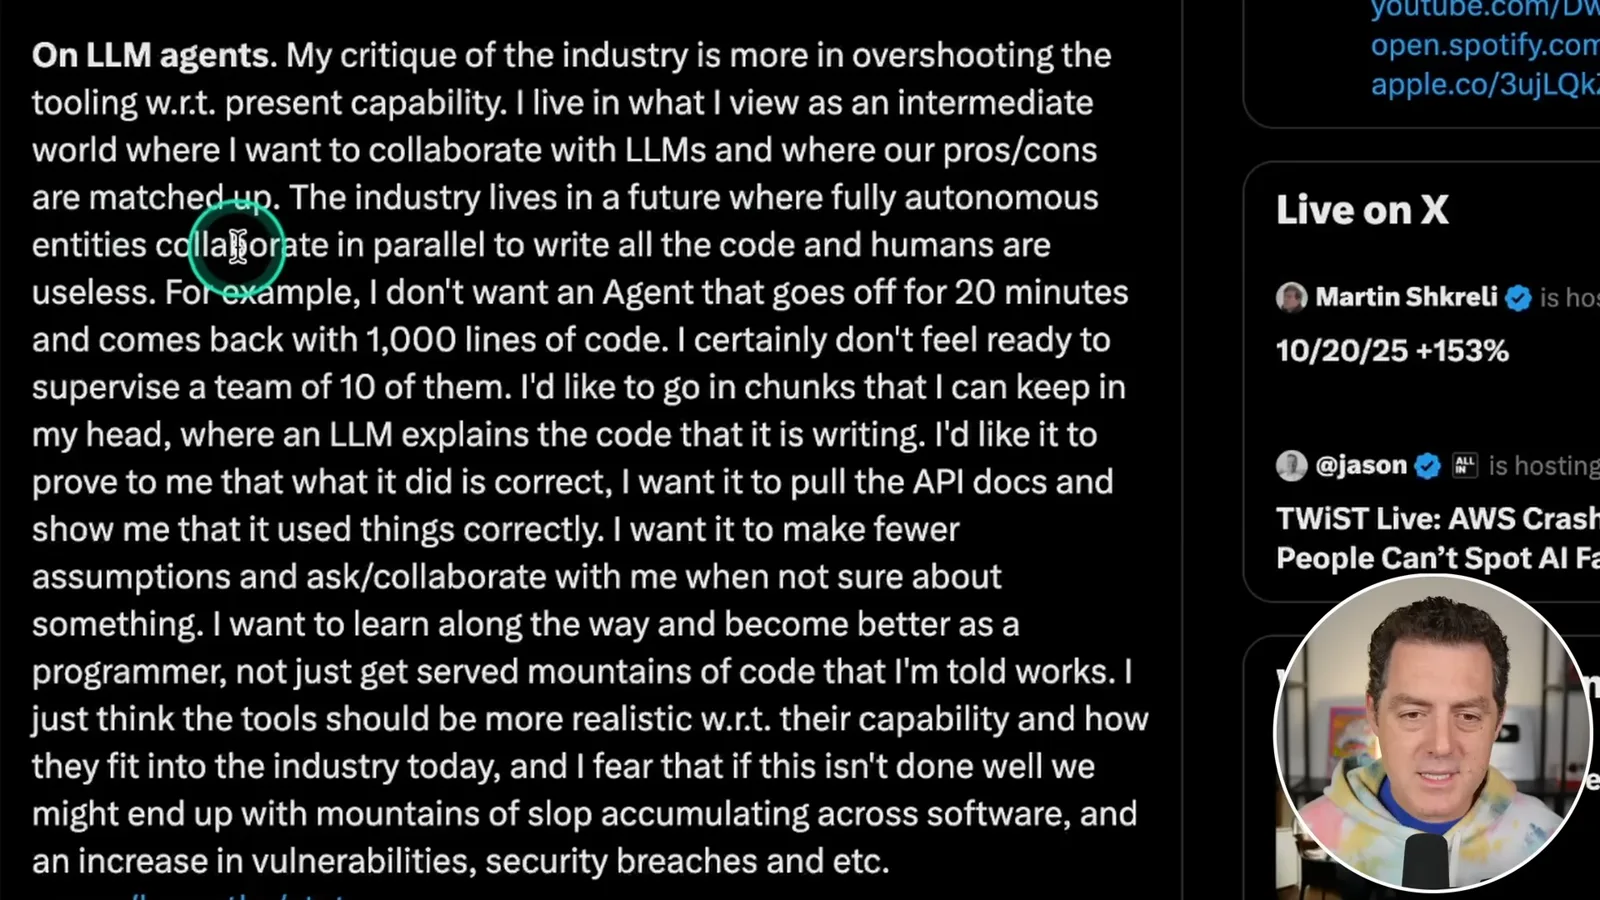
Karpathy warns that large amounts of generated code can accumulate as “mountains of slop” if the human does not review it carefully and understand the context. His concern is not just how much code can be generated but whether the person responsible can understand and verify it.
To finish, Elon Musk replied by proposing a coding contest between Karpathy and Grok 5, invoking Garry Kasparov’s chess match against IBM’s Deep Blue. Karpathy replied that he would rather use and collaborate with Grok 5 than compete against it, while suggesting that his own marginal contribution could eventually approach zero. I interpret that as acknowledging the possibility that AI coding could surpass him over time.
같은 채널의 다른 글
 34:21EN
 Matthew Berman· 2026년 10월 27일Matthew Berman Examines Anthropic’s IPO Filing, AI Growth and GovernanceMatthew Berman, Sam Altman · Forward FutureThe presenter reviews the S-1’s financial metrics, compute strategy and voting structure while questioning the tension between rapid AI development and safety.
 0:36ENMatthew Berman· 2026년 10월 25일Kimi K3.1 and a Rubik’s Cube Solver DemonstrationMatthew Berman · Forward FutureMatthew Berman shows a scrambled virtual cube being solved and gives the Kimi K3.1 test a favorable assessment.
 25:50ENMatthew Berman· 2026년 10월 24일Kimi K3.1 Pro Tested: Strong 3D Demos, Uneven Results and Competitive PricingMatthew Berman · Forward FutureMatthew Berman tests the open-weight model on coding, 3D rendering and visual explanations, then compares benchmark results and prices.
 32:20ENMatthew Berman· 2026년 10월 23일Who Is Local AI For? The Costs, Trade-offs and a Hybrid FutureMatthew Berman · Forward FutureMatthew Berman weighs data control and independence against hardware cost, setup complexity and inference speed.
 1:03:37ENMatthew Berman· 2026년 10월 23일Matthew Berman’s Team Tests Kimi K3.1 on Animation, Games, and ChartsMatthew Berman, Alex, Brian · Forward FutureA live team AMA turns into an informal test of Kimi K3.1, from personal-agent workflows to motion graphics, a browser game, and a benchmark chart.
 0:53ENMatthew Berman· 2026년 10월 22일Sam Altman on AI and the Discovery of New KnowledgeSam Altman · OpenAIAltman expects progress in mathematical discovery to extend to biology, materials and energy.