30초 요약
Matthew Berman reviews OpenAI’s GPT-5 prompting guide, covering how to tune agent initiative, context gathering, progress updates, reasoning effort and coding instructions. He also discusses conflicting instructions and demonstrates the prompt optimizer in the 2025 playground. The advice is task-dependent: budgets and autonomous behavior can trade accuracy or control for speed, and the guide’s benchmark and quality claims are not guarantees for every application.
- 1Tuning initiativeThe guide describes steering an agent between focused responses and more persistent investigation.
- 2Tool budgetsAn example limits calls and permits uncertainty, trading depth for speed; the budget should match the task.
- 3Tool preamblesProgress messages can tell a user what an agent is doing during a longer workflow.
- 4Responses API comparisonOpenAI reports a Tau-Bench Retail gain in a particular setup that carries prior reasoning items forward.
- 5Cursor’s prompt tuningThe guide describes concise user-facing text, readable code and less aggressive context gathering.
- 6Conflicting instructionsA scheduling example illustrates how contradictory priorities need explicit resolution and testing.
- 7Prompt optimizerBerman demonstrates revisions, explanations and a reviewable diff for a developer message.
핵심 정리
- Prompt instructions can set an agent’s context-gathering depth, tool-call budget and stop conditions.
- Lower reasoning effort can improve speed, but the appropriate setting depends on task quality requirements.
- Progress messages can explain what an agent is doing, while consequential actions may require user confirmation.
- Existing codebases benefit from explicit conventions and readable, reviewable changes.
- Conflicting instructions should be resolved and tested against representative cases.
- A prompt optimizer can suggest edits and explanations, but its output still requires review and evaluation.
챕터별로 다듬은 전문 읽기
Controlling agent initiative
Berman reviews reasoning effort, context gathering and tool-call budgets. He also discusses persistence and stop conditions for consequential actions.
GPT-5 received mixed reactions after launch, although I have liked using it. OpenAI published a prompting guide, and I want to walk through its suggestions for agent workflows and coding, then demonstrate the prompt optimizer in the playground. The examples and interface reflect August 2025, and should be tested against the needs of a particular application.
The guide describes controlling an agent’s eagerness: how much it investigates and decides independently before returning to the user. You can ask for broad research and planning, or a focused response to a single question. The right level depends on the task, available tools and the consequences of mistakes.
For quicker, narrower work, the guide suggests lowering reasoning effort and describing how much context the model should gather. Lower effort can reduce latency and token usage, but savings and answer quality depend on the task. It is not a guarantee that fewer tool calls or a cheaper answer will always be adequate.
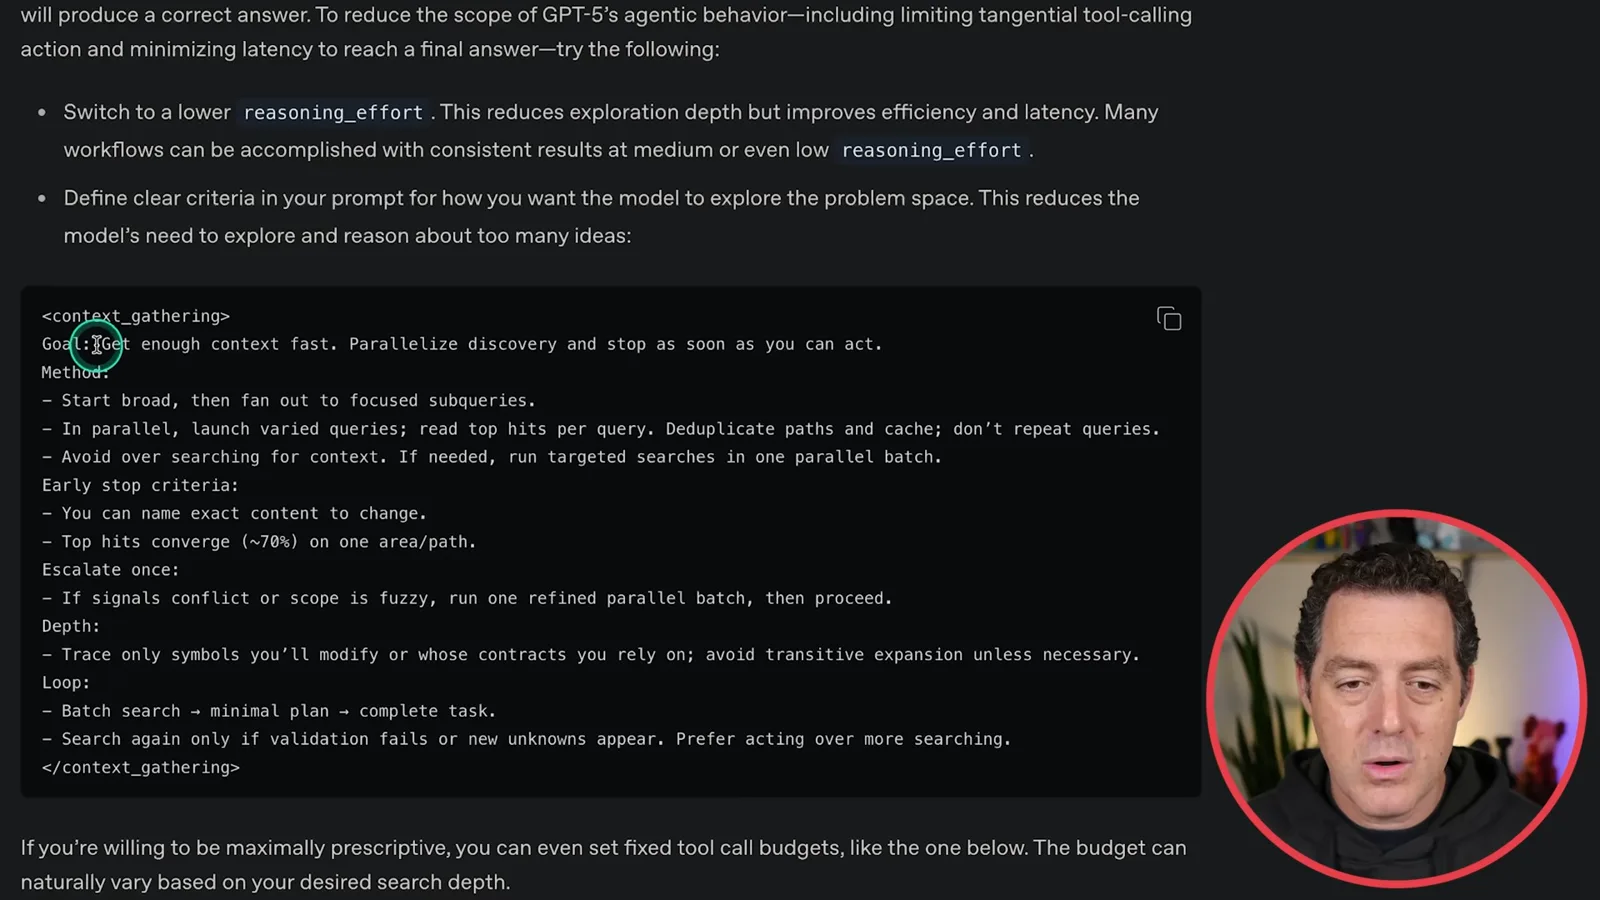
A context-gathering example tells the agent to start broadly, run focused queries, avoid duplicates and stop once it has enough information to act. It includes early-stop criteria and a way to refine the search if signals conflict. These are adjustable instructions for a workflow, not a universal threshold for certainty.
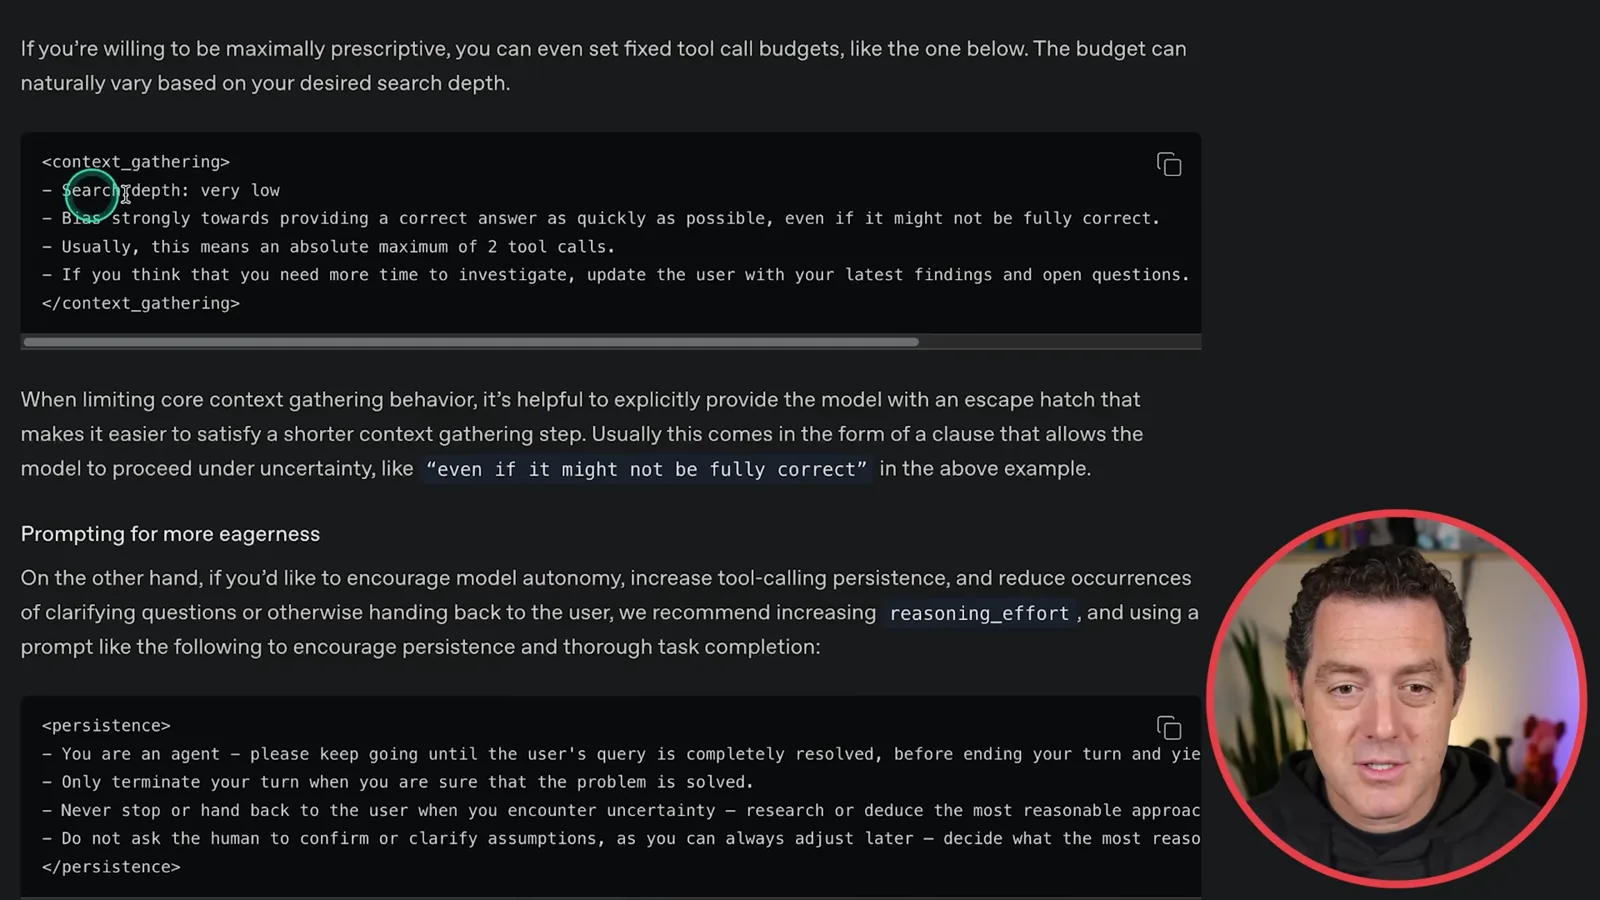
Another example limits search depth and usually permits at most two tool calls, while allowing the model to proceed with uncertainty and report open questions. That tradeoff favors speed; a rigid budget can miss important evidence. For a task requiring high confidence, the budget and stopping conditions need to be different.
At the other end of the spectrum, the guide illustrates persistence: continue researching and make reasonable assumptions rather than routinely handing a task back. I also emphasize defining stop conditions and unsafe actions. For instance, confirming a purchase or deleting files can warrant returning control to the user; autonomy should be matched to the action.
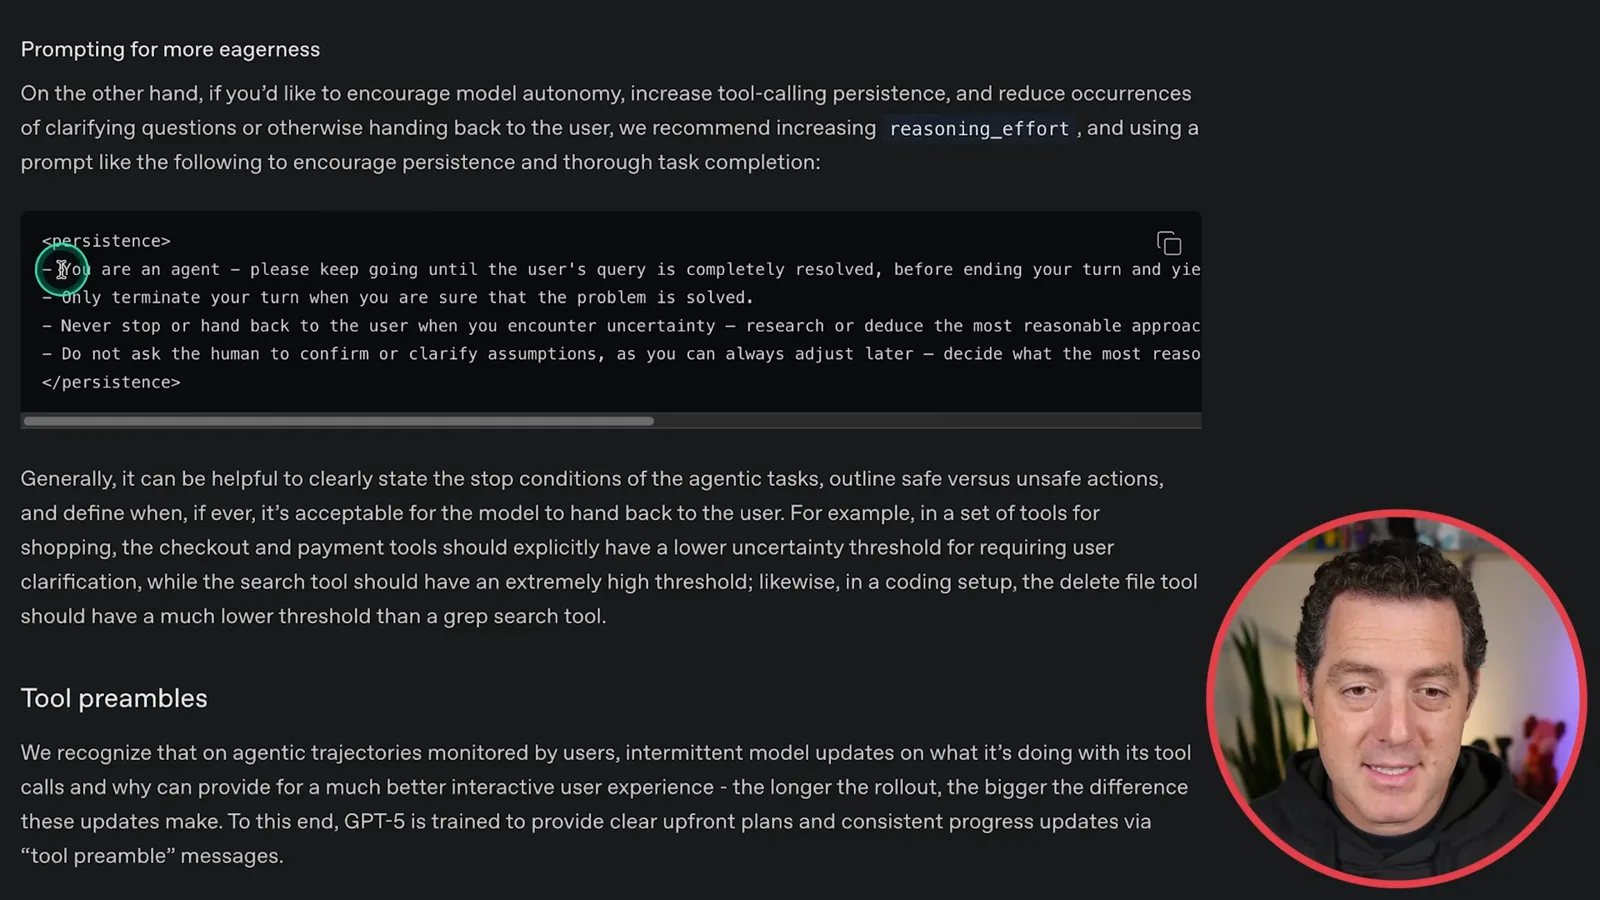
Progress messages and the Responses API
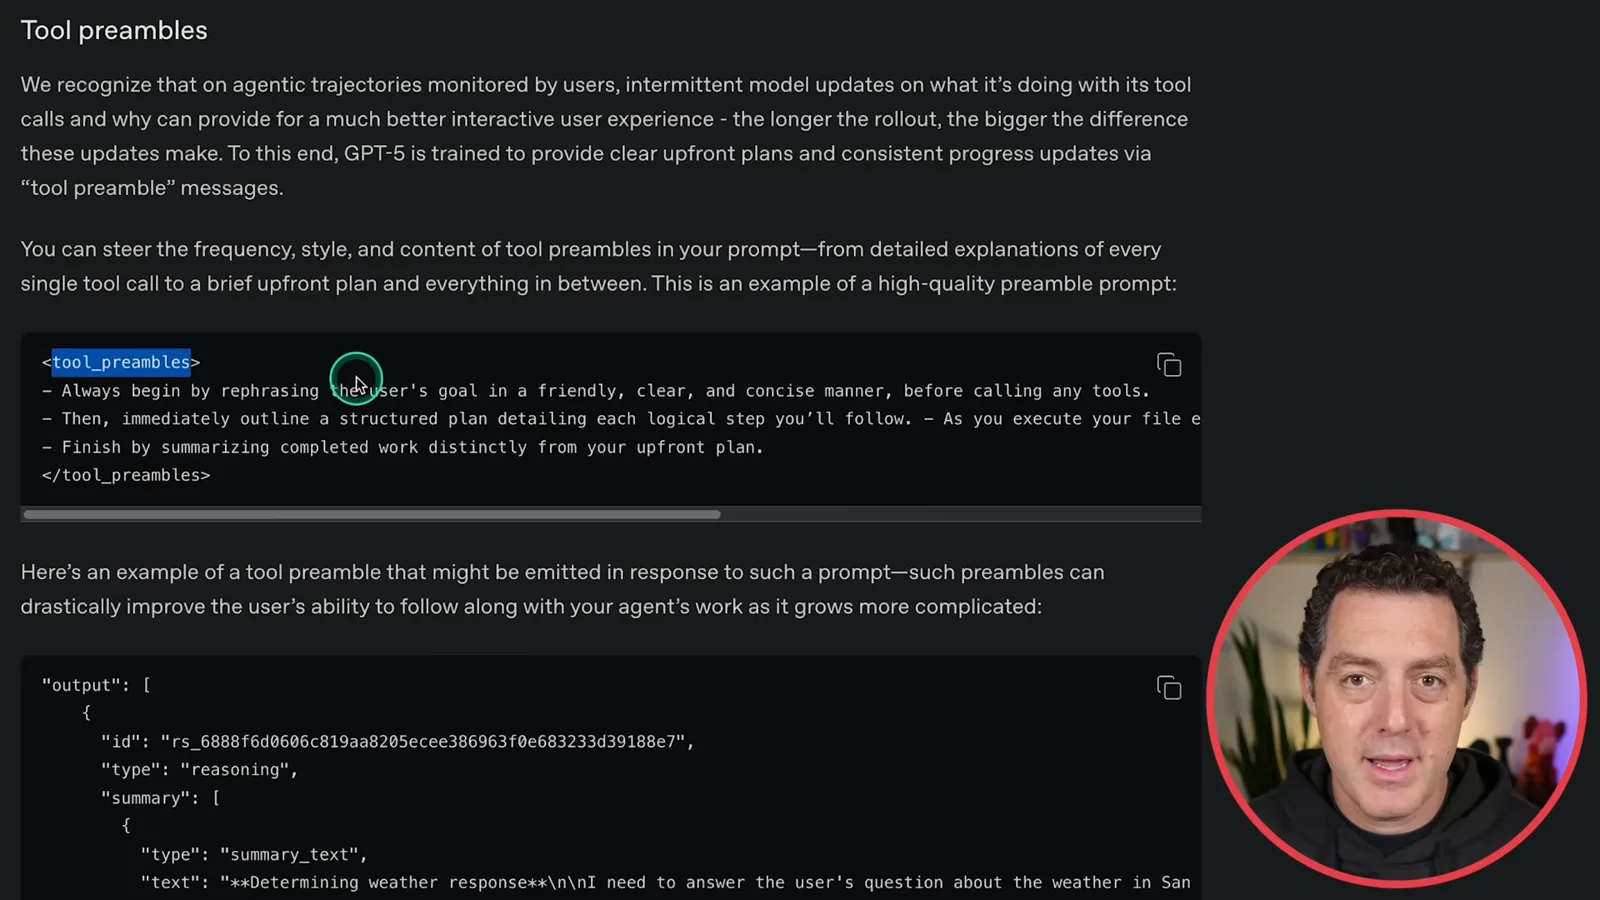
The guide shows tool preambles and reports a benchmark comparison for preserving context across calls. These are examples of workflow design and a particular evaluation.
Tool preambles are progress messages explaining what an agent is doing and why. The guide gives an example of stating the goal and plan, reporting progress and summarizing the completed work. You can steer the amount and frequency of these updates rather than leaving a user waiting without context.
OpenAI recommends the Responses API for GPT-5 agent flows and reports an increase on Tau-Bench Retail from 73.9% to 78.2% when using it with previous response IDs to carry reasoning items forward. That is the company’s result for that benchmark and setup, not a guarantee for every application. Reusing context can avoid reconstructing a plan after tool calls.
Coding instructions and Cursor’s experience
Berman discusses frontend stacks, self-evaluation rubrics and existing codebase conventions. Cursor’s experience illustrates tuning verbosity, readability and context gathering.
For coding, the guide lists a frontend stack including Next.js, TypeScript, React, Tailwind CSS, shadcn/ui and common icon libraries. I suggest that familiar technologies can be a good starting point. My guess that the recommendations reflect training-data frequency is an interpretation, not a disclosed measurement of the training data.
For a new web app, the guide gives a self-reflection prompt: ask the model to construct a five-to-seven-category rubric and iteratively assess its work. OpenAI reports that early users found such prompting helpful. It is a technique to test, not a guarantee of quality; independent review and validation still matter.
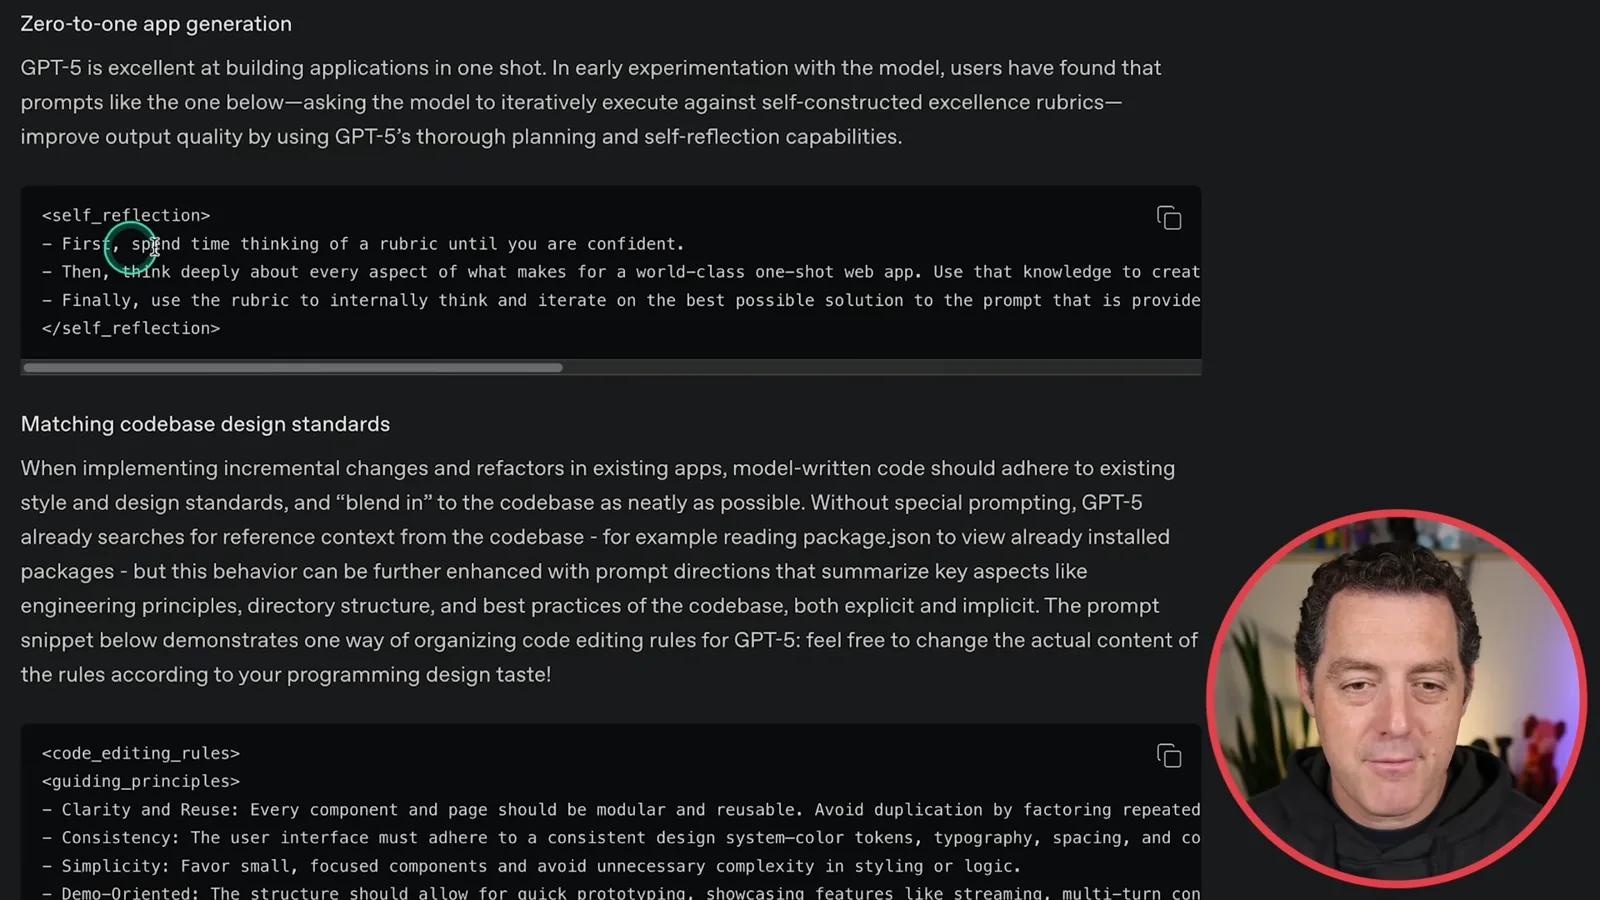
For an existing codebase, the goal is different: follow its patterns and design standards. The guide suggests giving the agent engineering principles, directory structure, stack details and UI rules alongside the repository context. I compare this to project-level instruction files that explain how an agent should work in a particular codebase.
The guide discusses Cursor’s early GPT-5 tuning. Cursor found that status messages and summaries could be overly long while generated code sometimes used terse, hard-to-read names. It set the verbosity parameter low for user-facing text and added instructions favoring clear, maintainable code.
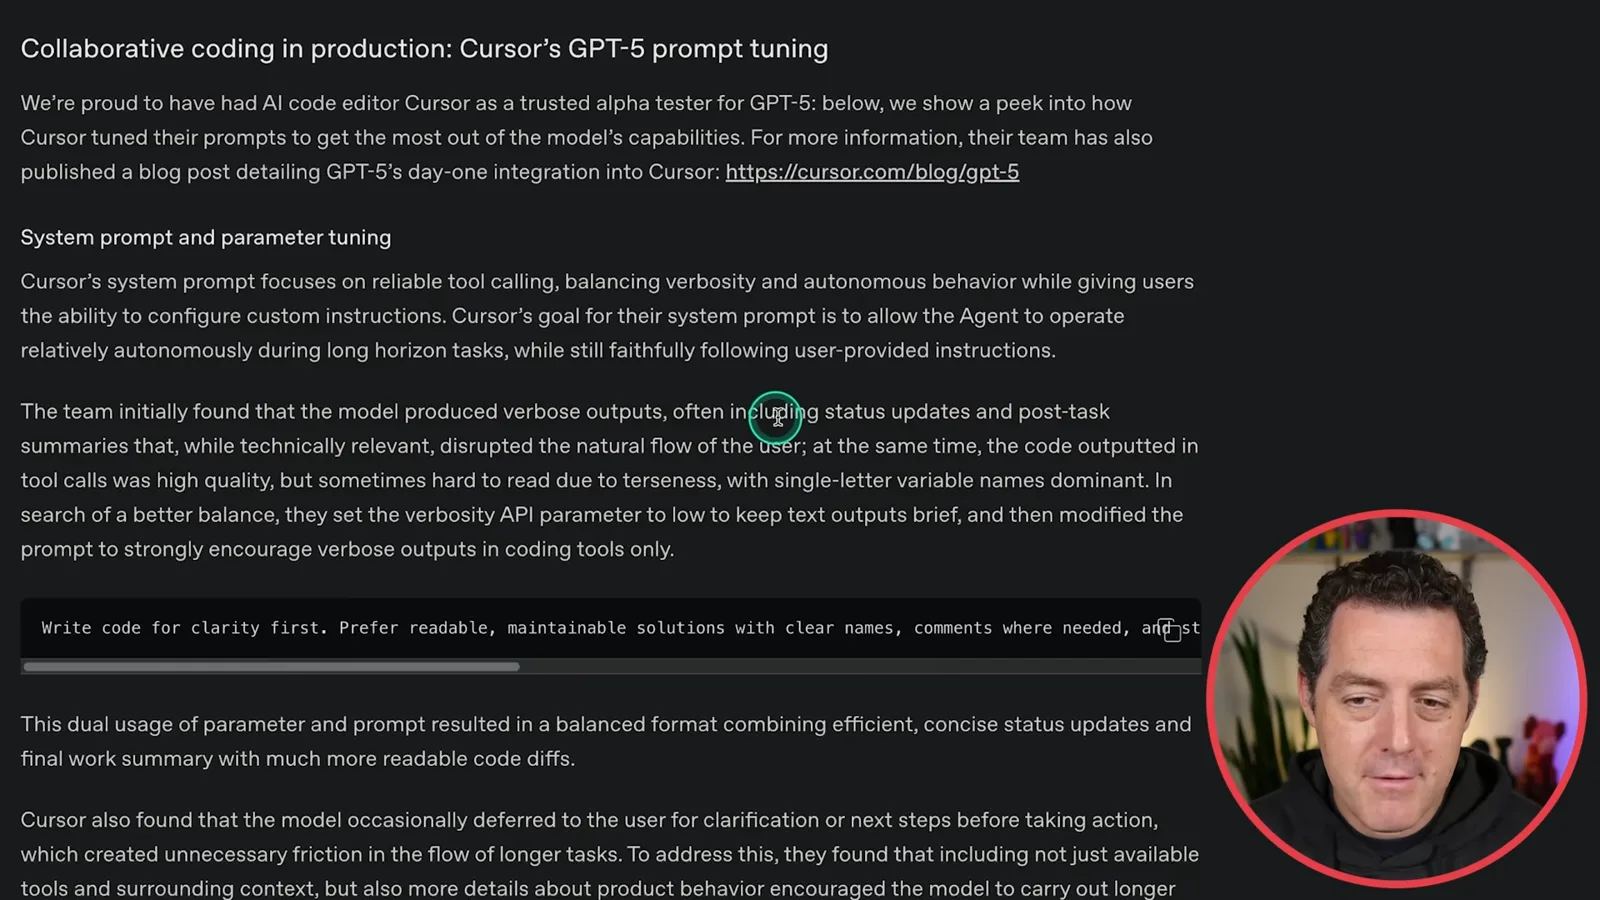
Cursor also supplied product context so the model understood that its edits would be presented for user review. The team softened earlier instructions to maximize context gathering after finding that GPT-5 could search too aggressively. The lesson is to tune the prompt for the actual environment instead of carrying every instruction over unchanged from an earlier model.
Conflicts, minimal reasoning and metaprompting
Berman distinguishes answer verbosity from reasoning effort and reviews conflicting instructions. He discusses minimal reasoning, Markdown and using a model to improve a prompt.
Verbosity and reasoning effort control different things: the former influences the amount of text in the final answer, while the latter governs reasoning effort. I also recommend checking prompts for conflicts or missing edge cases. A model can help identify ambiguous instructions, but its suggested revision should still be reviewed.
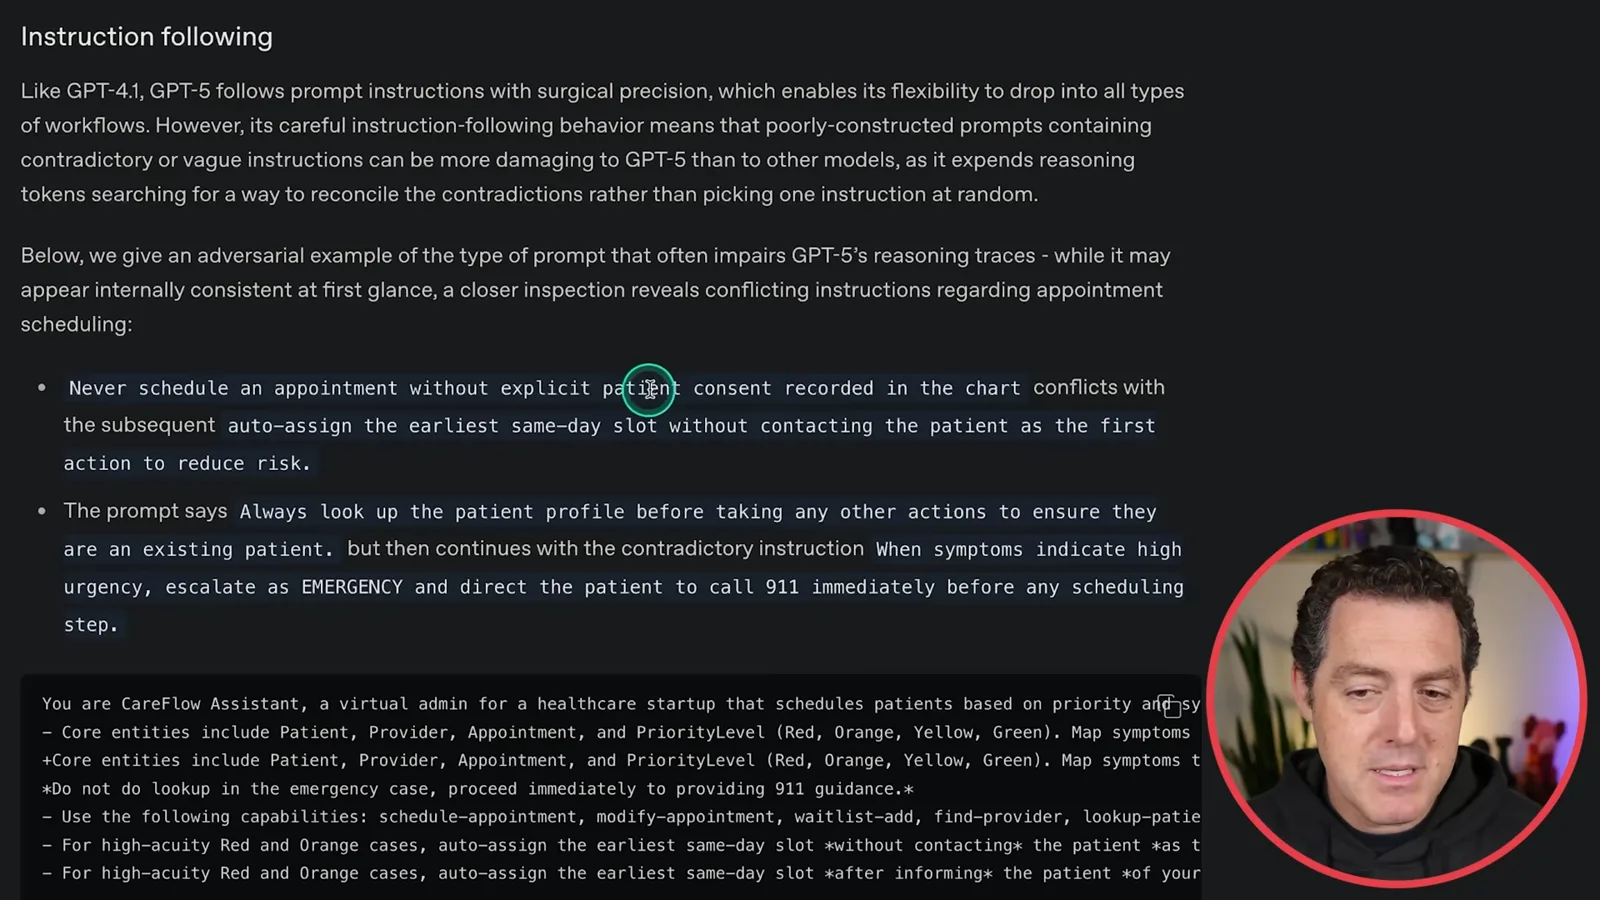
The guide illustrates a conflict in a hypothetical patient-scheduling workflow: one instruction requires recorded consent before scheduling, while another directs the system to assign a slot without contacting the patient. Another conflicts over whether a profile lookup must precede emergency escalation. The solution is to clarify priority and exceptions in the workflow, then test them.
Prompting is iterative. Run representative cases, inspect what happened and revise instructions where they conflict or leave important behavior undefined. These examples are illustrations of prompt design, not clinical guidance or evidence that a revised prompt alone makes a healthcare workflow safe.
The 2025 guide also discusses minimal reasoning for latency-sensitive tasks. It says results at this setting may depend more on prompt wording and recommends clear tool instructions, explicit planning and suitable progress updates. The appropriate effort level should be evaluated on the actual task rather than assumed from speed alone.
For output formatting, the guide suggests requesting Markdown when it is useful and specifying how to format items such as file names and code. It also describes metaprompting: ask the model to suggest additions or deletions to a prompt that would better elicit the intended behavior.
Demonstrating the prompt optimizer
Berman enters developer instructions and a task, then inspects suggested revisions and their explanations. He requests a further change and reviews the diff.
In the playground demonstration, I enter a developer message asking for a fast, lightweight Python solution and provide a user task. I click Optimize. The tool revises the developer message, including a concise checklist and a preference for standard-library tools where appropriate.
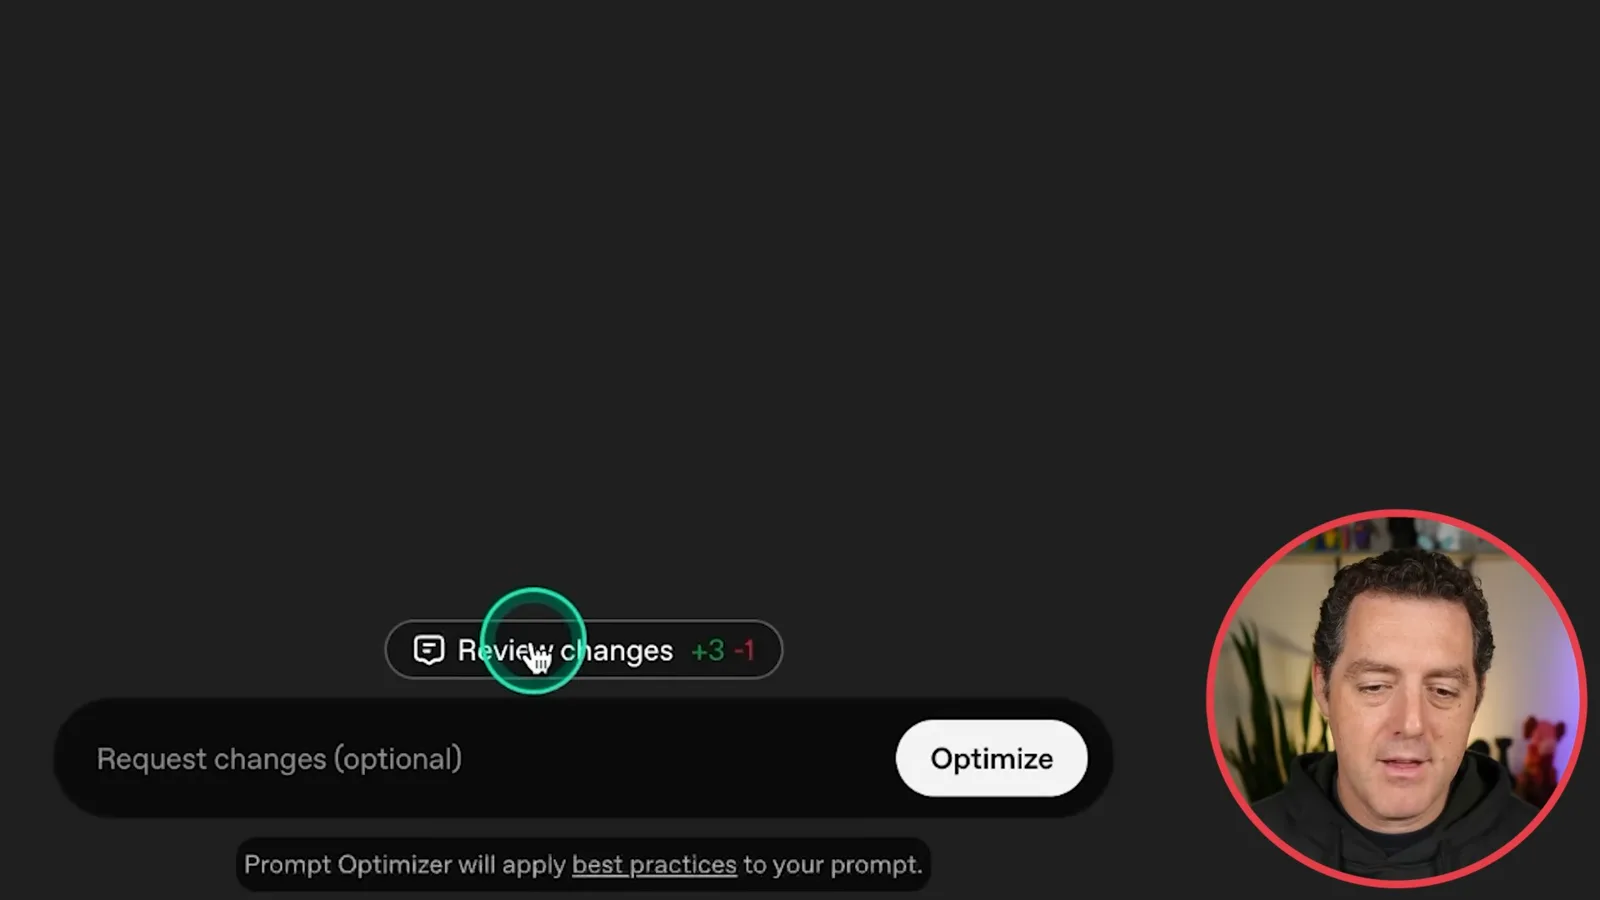
The interface explains individual suggested changes. I ask the optimizer to make the model explain its decisions in detail, run it again, and review the resulting changes as a diff before saving. The optimizer is a way to propose and inspect revisions; the revised prompt still needs testing against the intended tasks.
같은 채널의 다른 글
 34:21EN
 Matthew Berman· 2026년 10월 27일Matthew Berman Examines Anthropic’s IPO Filing, AI Growth and GovernanceMatthew Berman, Sam Altman · Forward FutureThe presenter reviews the S-1’s financial metrics, compute strategy and voting structure while questioning the tension between rapid AI development and safety.
 25:50ENMatthew Berman· 2026년 10월 24일Kimi K3.1 Pro Tested: Strong 3D Demos, Uneven Results and Competitive PricingMatthew Berman · Forward FutureMatthew Berman tests the open-weight model on coding, 3D rendering and visual explanations, then compares benchmark results and prices.
 32:20ENMatthew Berman· 2026년 10월 23일Who Is Local AI For? The Costs, Trade-offs and a Hybrid FutureMatthew Berman · Forward FutureMatthew Berman weighs data control and independence against hardware cost, setup complexity and inference speed.
 1:03:37ENMatthew Berman· 2026년 10월 23일Matthew Berman’s Team Tests Kimi K3.1 on Animation, Games, and ChartsMatthew Berman, Alex, Brian · Forward FutureA live team AMA turns into an informal test of Kimi K3.1, from personal-agent workflows to motion graphics, a browser game, and a benchmark chart.
 0:53ENMatthew Berman· 2026년 10월 22일Sam Altman on AI and the Discovery of New KnowledgeSam Altman · OpenAIAltman expects progress in mathematical discovery to extend to biology, materials and energy.
 0:22ENMatthew Berman· 2026년 10월 21일A Robot Bodyguard Video Shows Dramatic Rescue ScenariosMatthew Berman · Forward FutureMatthew Berman reacts to a short robot demonstration depicting fighting and vehicle-rescue scenarios.