








Résultats
39 articlesTrier
 1:53EN
 Matthew Berman· 8 juil. 2026What Anthropic’s J-Space Research Suggests About AI ReasoningMatthew Berman · Forward FutureMatthew Berman discusses internal model representations, interventions and the question of consciousness, while the research itself describes important limits.
 11:15ENMatthew Berman· 27 mars 2026ARC-AGI-3: Testing How AI Agents Learn the Rules of Unfamiliar GamesMatthew Berman · Forward FutureMatthew Berman explains ARC’s earlier grid puzzles and plays an interactive ARC-AGI-3 level, then examines early model results. The benchmark tests a specific form of adaptation rather than settling whether a system has general intelligence.
 7:49ENMatthew Berman· 2 déc. 2025DeepSeek V3.2: Reasoning, Sparse Attention and Agent TrainingMatthew Berman · Forward FutureMatthew Berman examines DeepSeek’s December 2025 model release, its benchmark results and the techniques used to improve long-context efficiency and tool use.
 13:53ENMatthew Berman· 10 oct. 2025Tiny Recursive Models and the Limits of Puzzle Benchmark ComparisonsMatthew Berman · Forward FutureMatthew Berman examines a small recursive network that reports strong ARC and Sudoku results, and what its experimental setup means.
 11:38ENMatthew Berman· 12 juin 2025AI News in June 2025: Magistral, Voice Models and Image GenerationMatthew Berman · Forward FutureMatthew Berman reviews Mistral’s reasoning models, voice and browser updates, reports on Meta and Scale AI, and FLUX.1 Kontext.
 22:05ENMatthew Berman· 9 juin 2025Apple’s “Illusion of Thinking”: Puzzle Limits and a Code-Assisted TestMatthew Berman, Ilya Sutskever · Forward FutureMatthew Berman reviews Apple’s reasoning-model experiments and tests a different way to solve Tower of Hanoi using generated code.
 10:09ENMatthew Berman· 30 mai 2025DeepSeek R1 0528: Benchmark Gains and Two Coding TestsMatthew Berman · Forward FutureMatthew Berman examines the May 2025 DeepSeek reasoning-model update, comparing reported benchmark gains with his own Rubik’s Cube and Snake programming tests.
 15:13ENMatthew Berman· 10 mai 2025Absolute Zero: Training a Reasoner on Self-Generated Coding TasksMatthew Berman · Forward FutureMatthew Berman examines a 2025 paper in which a pretrained language model proposes and solves code tasks using verifiable feedback.
 14:04ENMatthew Berman· 29 avr. 2025Qwen3: Open Weights, Adjustable Reasoning and Tool UseMatthew Berman · Forward FutureMatthew Berman reviews the April 2025 Qwen3 family, its benchmark claims, training pipeline and local demonstration.
 19:06ENMatthew Berman· 25 avr. 2025Sleep-Time Compute: Preparing AI Context Before a QuestionMatthew Berman · Forward FutureMatthew Berman reviews a 2025 paper on moving some reasoning ahead of a user query, and explains where its experiments found benefits and limits.
 15:15ENMatthew Berman· 19 avr. 2025Early Reactions to OpenAI o3 and o4-mini: Tool Use, Math and MistakesMatthew Berman · Forward FutureMatthew Berman reviews 2025 demos and benchmark reports, from location guessing and coding to simple failures that challenge the hype.
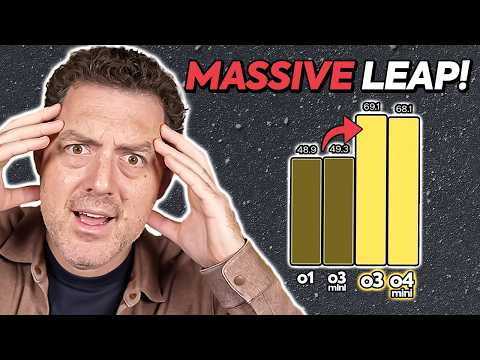 15:46ENMatthew Berman· 16 avr. 2025OpenAI o3 and o4-mini: Tool Use, Benchmarks and the First Codex CLIMatthew Berman · Forward FutureMatthew Berman reviews OpenAI’s April 2025 reasoning-model release, a scientific image-analysis demonstration and the debut of its terminal coding agent.
 12:30ENMatthew Berman· 7 mars 2025QwQ-32B: A Smaller Reasoning Model and Its TradeoffsMatthew Berman · Forward FutureMatthew Berman examines Qwen’s reinforcement-learning recipe, tests a coding task, and compares benchmark scores and hardware requirements with DeepSeek-R1.
 9:35ENMatthew Berman· 25 févr. 2025Claude 3.7 Sonnet and Claude Code: An Early Coding TestMatthew Berman · Forward FutureMatthew Berman reviews Anthropic’s 2025 launch benchmarks and builds an AI-controlled Snake game, then tests math and recent information.
 9:43ENMatthew Berman· 20 févr. 2025Testing Grok 3 on Games, Reasoning, and Web SearchMatthew Berman · Forward FutureMatthew Berman tries a new set of audience-suggested prompts, from a Snake–Flappy Bird mashup to a family-logic puzzle and a tesseract visualization.
 13:24ENMatthew Berman· 18 févr. 2025Grok 3’s 2025 Launch: Benchmarks, Reasoning and DeepSearchMatthew Berman, Elon Musk · Forward FutureMatthew Berman reviews xAI’s launch charts, a historical user-preference leaderboard and an early product demonstration.
 18:05ENMatthew Berman· 16 févr. 2025OpenAI’s Coding-Competition Study: o1-ioi, o3 and the Limits of the ResultsMatthew Berman, Sam Altman · Forward FutureMatthew Berman interprets OpenAI’s 2025 paper on reinforcement learning and programming contests. The results are strong on the studied benchmarks, but do not establish AGI or remove humans from model development.
 15:33ENMatthew Berman· 13 févr. 2025Latent Reasoning and Recurrent Depth: Scaling Compute Before the Next TokenMatthew Berman, Yann Lecun · Forward FutureMatthew Berman examines a 3.5-billion-parameter research model that repeats internal computations, and asks how it relates to language, planning and chain of thought.
 6:50ENMatthew Berman· 12 févr. 2025DeepScaleR: A Small Reasoning Model Tested on Competition MathMatthew Berman · Forward FutureMatthew Berman reviews a 1.5B model’s reported benchmark results and runs a quantized version locally on one AIME problem.
 9:58ENMatthew Berman· 31 janv. 2025OpenAI o3-mini Launch: Reasoning Effort, Benchmarks and a Snake TestMatthew Berman · Forward FutureIn January 2025, Matthew Berman reviews OpenAI’s reported results and tries two coding examples with different reasoning settings.
 16:45ENMatthew Berman· 27 janv. 2025DeepSeek-R1 and the Debate Over AI Costs and ComputeMatthew Berman · Forward FutureMatthew Berman examines the January 2025 reaction to an open-weight reasoning model, disputed cost claims and competing views of future demand for AI chips.
 8:52ENMatthew Berman· 21 janv. 2025Industry Reactions to DeepSeek R1’s 2025 ReleaseMatthew Berman · Forward FutureMatthew Berman reviews early reactions to DeepSeek R1, from open-weight reasoning models and local hardware to benchmark results and API pricing.
 21:02ENMatthew Berman· 24 déc. 2024Reactions to OpenAI’s 2024 o3 Preview: Benchmarks, Cost and LimitsMatthew Berman · Forward FutureMatthew Berman surveys the responses to the o3 preview, from mathematical benchmarks to debates about AGI, compute and reliability.
 26:23ENMatthew Berman· 20 déc. 2024OpenAI’s o3 Announcement: Benchmark Gains and the Question of AGIMatthew Berman, Sam Altman, Mark Chen, Greg Kamradt, Hongyu Ren · Forward FutureMatthew Berman reviews the December 2024 o3 and o3-mini announcement, including coding, math and ARC-AGI results. He calls the results evidence of AGI, a conclusion the benchmarks alone cannot establish.
Charger plus24 sur 39 affichés