En 30 secondes
Matthew Berman examines Apple’s June 2025 paper on reasoning models and puzzle complexity. The researchers report an advantage for thinking models on medium-complexity tasks and failures for both tested model types at high complexity; Berman also discusses benchmark contamination as a possible explanation, not an established finding about specific models. He challenges broad interpretations of the result and demonstrates a code-generated Tower of Hanoi solver. The ten-disc example finishes; the video shows a 20-disc run in progress, not completion. Tool-assisted execution and direct text-based puzzle solving are different evaluations.
- 1The paper’s questionThe authors investigate reasoning, inference compute and potential benchmark contamination.
- 2Controlled puzzlesFour environments permit the researchers to vary complexity and check proposed moves.
- 3Understanding pass@kThe metric measures whether at least one sampled candidate succeeds; selection is a separate problem.
- 4Complexity regimesThe tested thinking models perform better at intermediate complexity, while both model types fail at sufficiently high complexity.
- 5Provided algorithmIn the reported Tower of Hanoi experiment, adding the algorithm did not eliminate the observed failure.
- 6A different workflowBerman generates a solver program; the ten-disc example finishes, but the clip does not show the 20-disc run completing.
À retenir
- Apple’s study uses four controllable puzzle environments to examine performance and reasoning traces as complexity changes.
- The reported low, medium and high complexity regimes apply to the tested models and tasks, not all possible reasoning.
- Benchmark contamination is a possible explanation discussed by the authors, not proof of deliberate cheating.
- Pass@k evaluates whether any candidate is correct; it does not by itself provide a way to select that candidate.
- Supplying a Tower of Hanoi algorithm did not prevent the observed collapse in the paper’s tested setup.
- Berman’s generated program solves a ten-disc example, while the 20-disc run is only shown in progress.
Lire le texte remanié, chapitre par chapitre
The paper’s question
Berman introduces Apple’s study of reasoning models and concerns about benchmark contamination. He explains what the experiments seek to measure.
Apple’s paper “The Illusion of Thinking” has sparked a debate about what reasoning models actually do. I review its experiments, its concerns about benchmark contamination and generalization, and its findings about how model performance changes with puzzle complexity.
The paper studies models that generate extended reasoning traces before answering, including Claude and DeepSeek variants. The researchers question how much benchmark progress reflects reasoning, extra inference compute or possible exposure to benchmark material. My description of contamination as models “cheating” is a concern about possible exposure, not proof that a particular model was intentionally trained on a particular test.
Established mathematics and coding benchmarks often report final-answer accuracy, which makes it difficult to vary complexity systematically or inspect intermediate attempts. The paper proposes controllable puzzles with consistent rules and simulator-based checks, so researchers can examine both solutions and reasoning traces.
Controlled puzzles and benchmark comparisons
The researchers use four puzzle environments and compare models at varying complexity. Berman discusses pass@k and competing interpretations of benchmark gaps.
The four environments are Tower of Hanoi, checker jumping, river crossing and Blocks World. In Tower of Hanoi, discs must move between pegs one at a time without placing a larger disc on a smaller one. Adding discs, pieces, entities or blocks changes problem complexity while keeping the basic rules.
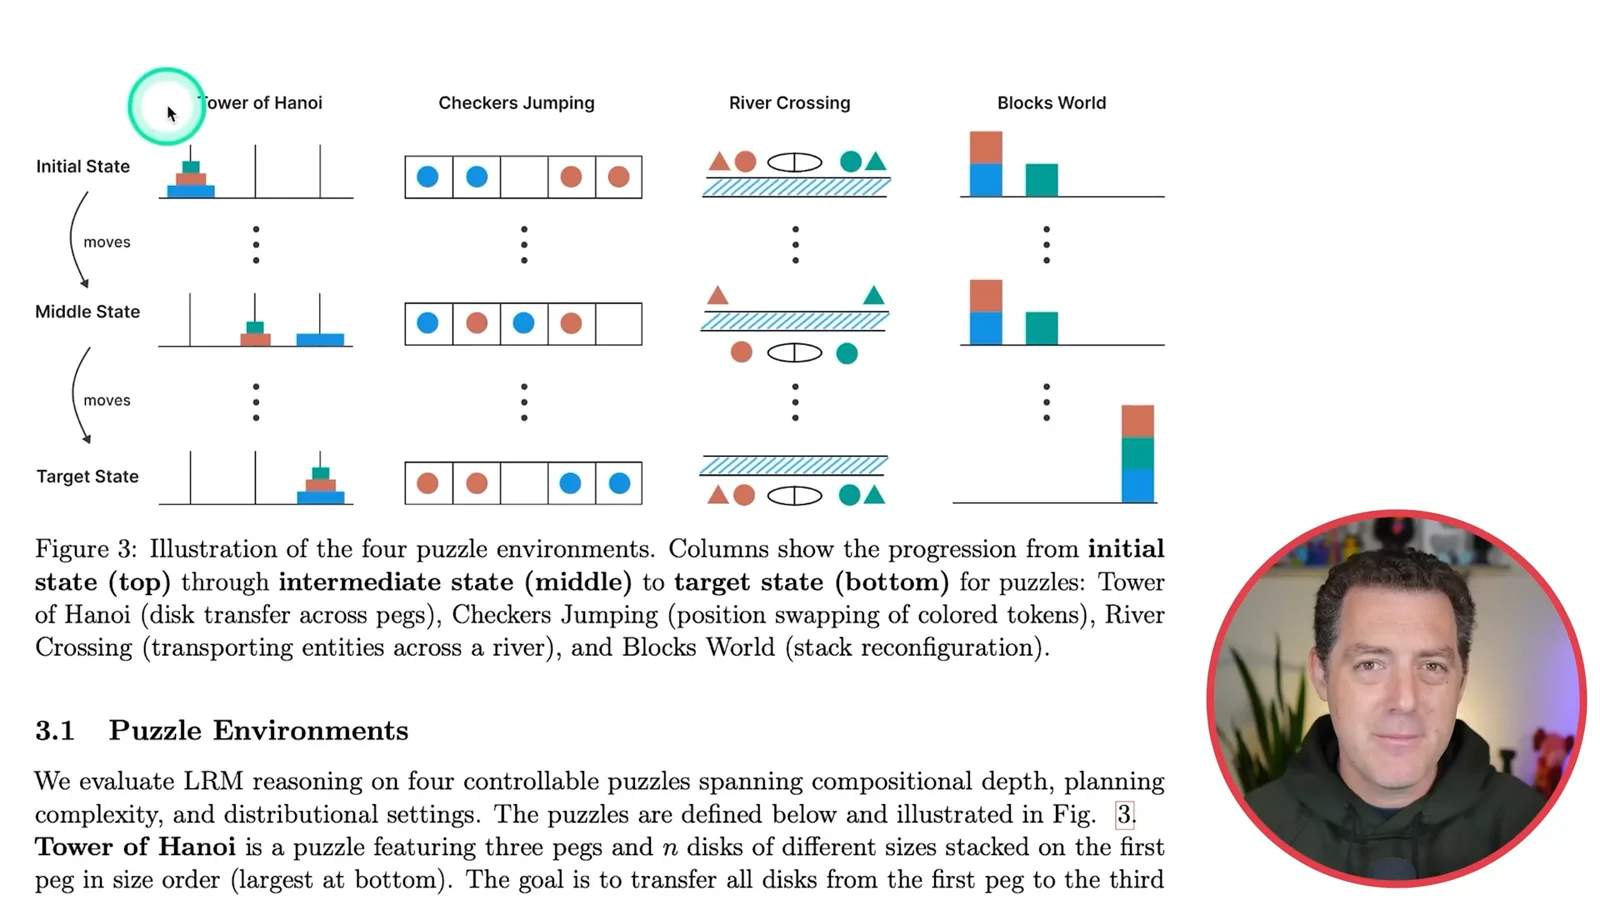
The authors argue these constructed environments help address contamination concerns and allow exact verification. Their questions include whether models generalize, how performance scales with complexity and how reasoning models compare with standard models given equivalent inference budgets.
The paper discusses prior comparisons on MATH-500 and AIME 2024, then reports its own comparisons on MATH-500, AIME 2024 and AIME 2025. The authors say the performance gap is larger on the newer AIME tests and consider both genuine reasoning advantages and differences in contamination as possible explanations; they do not establish which caused the gap.
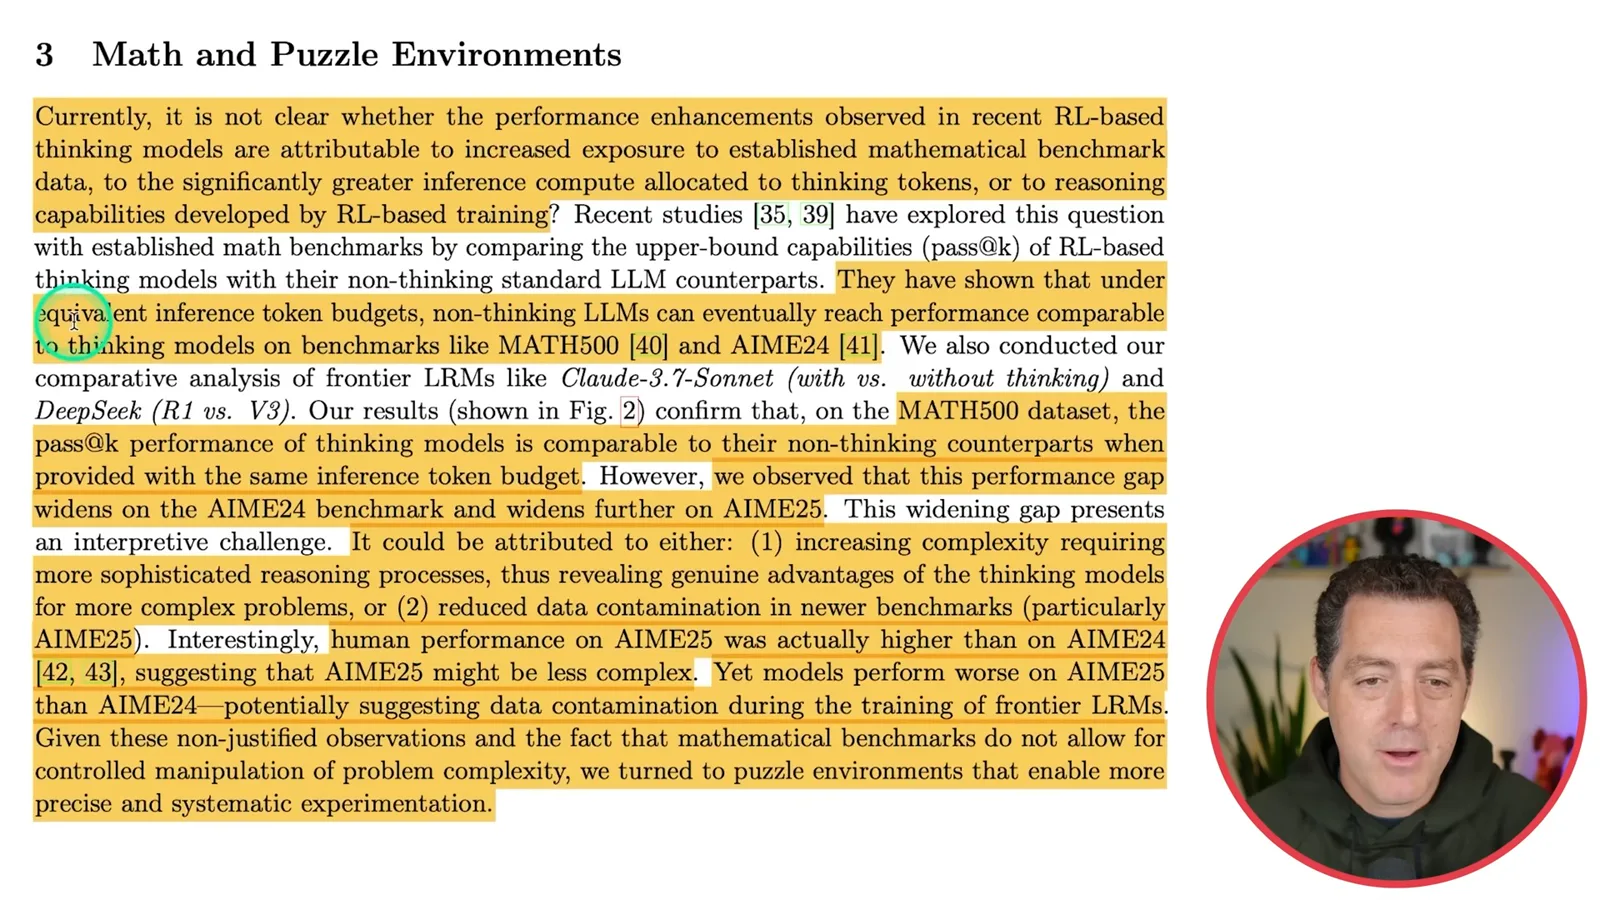
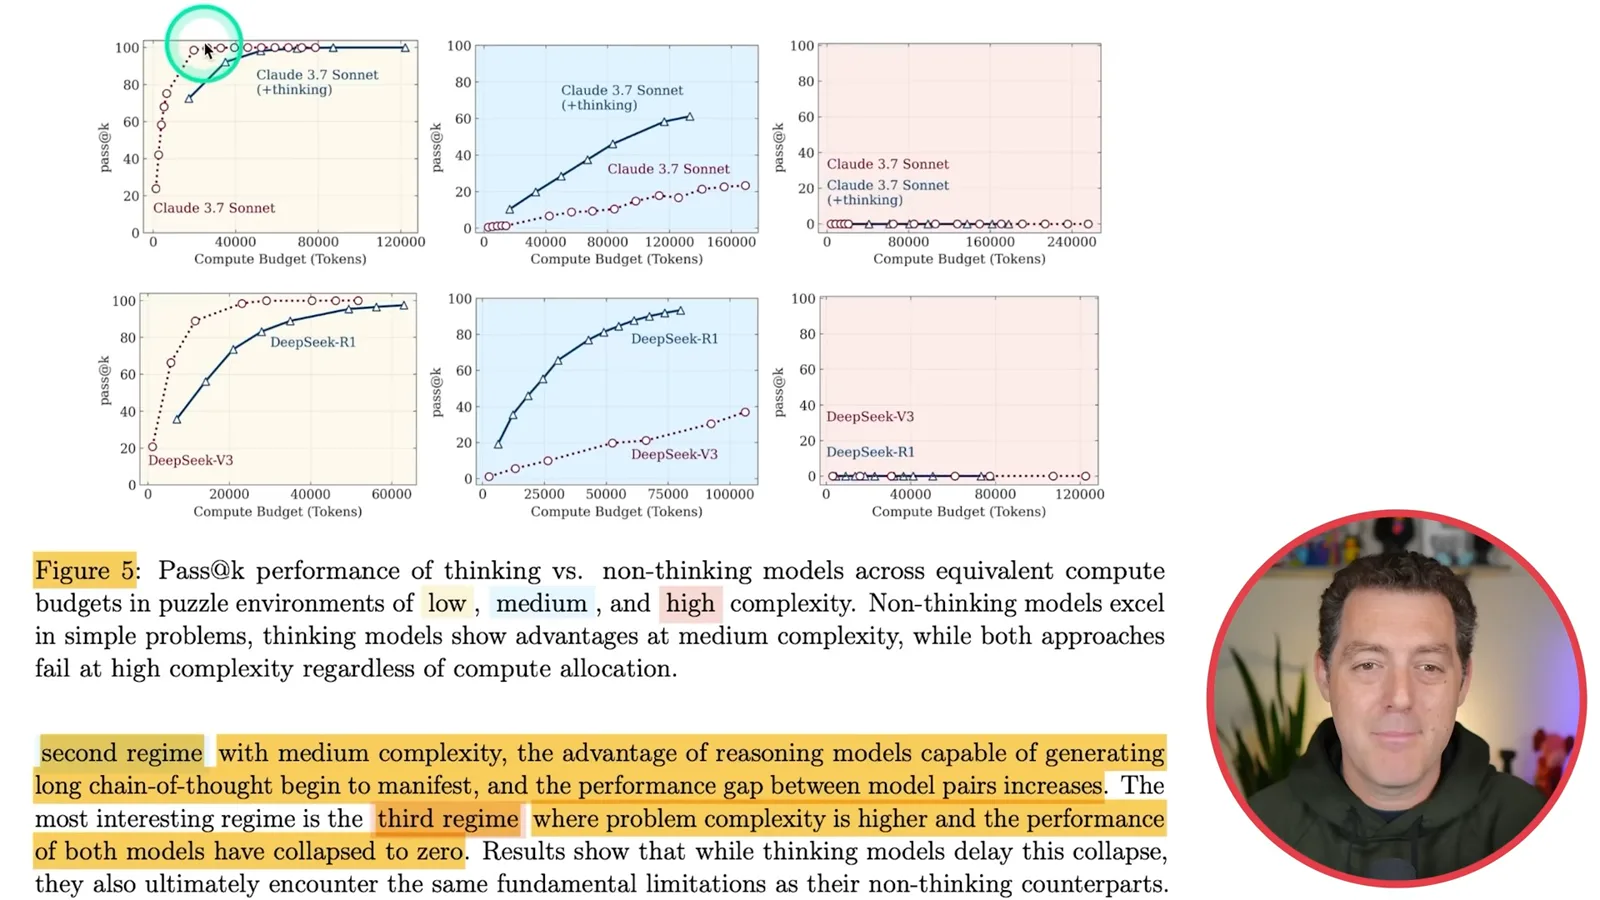
One comparison uses pass@k, examining whether at least one of multiple generated candidates is correct under a compute budget. I describe this as choosing the best solution, but the metric is an upper-bound evaluation: identifying the correct candidate in practice would require a suitable verifier or selection method.
Three performance regimes
The shown model pairs perform differently on easy and intermediate puzzles and fail on sufficiently difficult tested instances. The paper examines token use and intermediate traces.
The puzzle plots compare Claude 3.7 Sonnet with and without thinking and DeepSeek-R1 with DeepSeek-V3. In the experiments, easy instances are often solved by both; thinking models have an advantage at intermediate complexity; at sufficiently high complexity both can fall to zero accuracy. The threshold differs across puzzles and models.
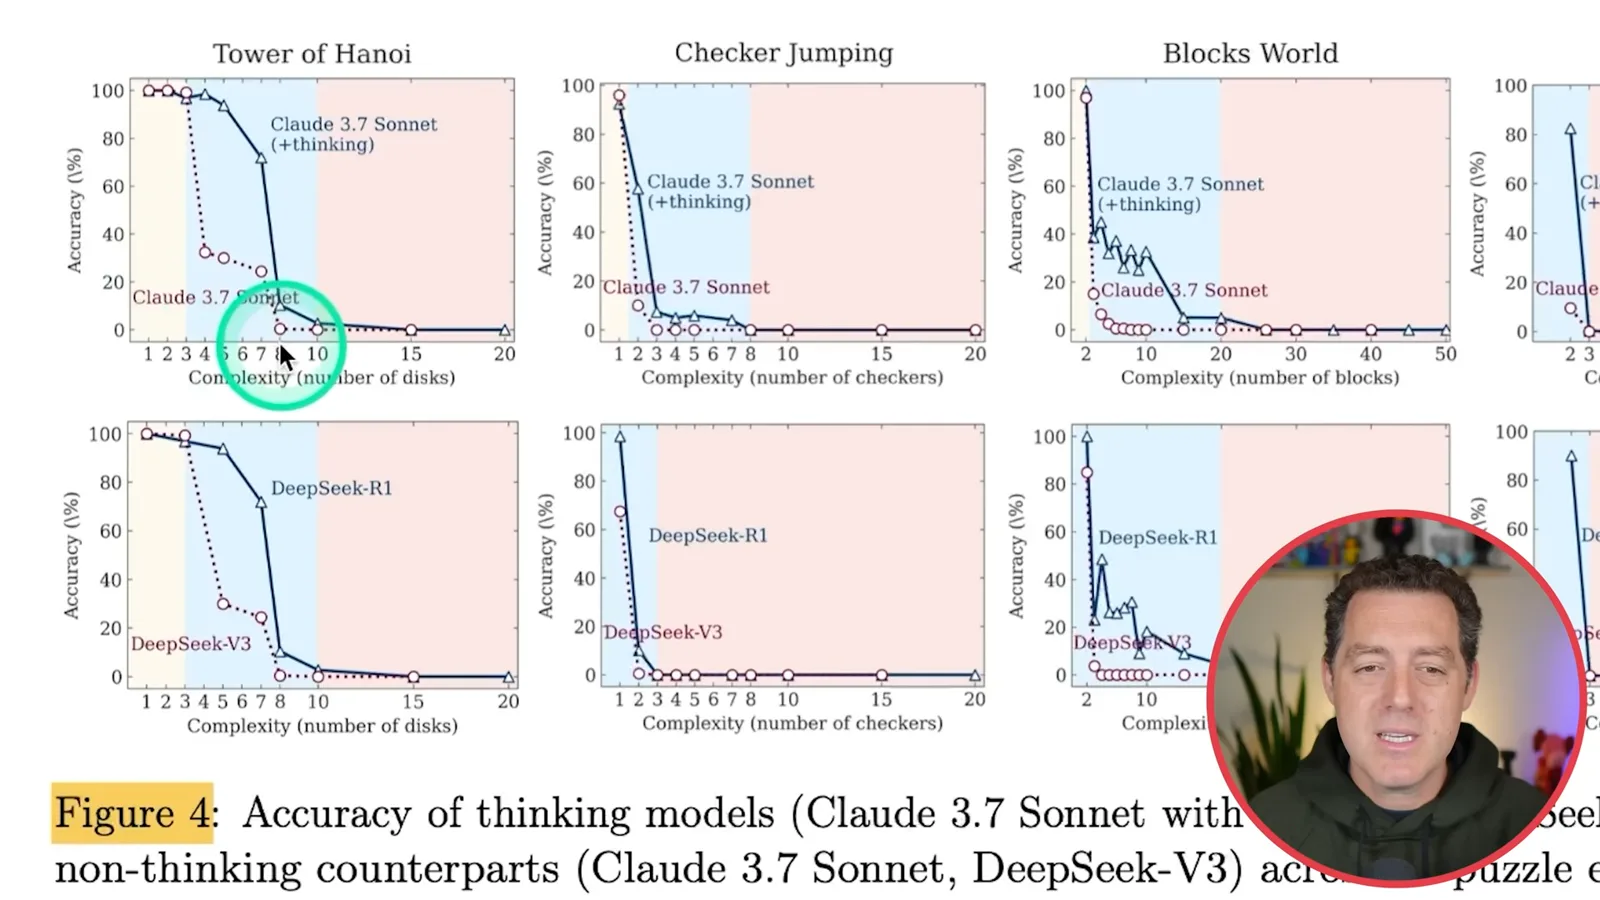
The researchers generate 25 samples per puzzle instance and report average performance. They also compare performance at similar inference-token budgets. The three regimes are a result of these selected model pairs, tasks and evaluation conditions, rather than a claim that every model fails every hard problem.
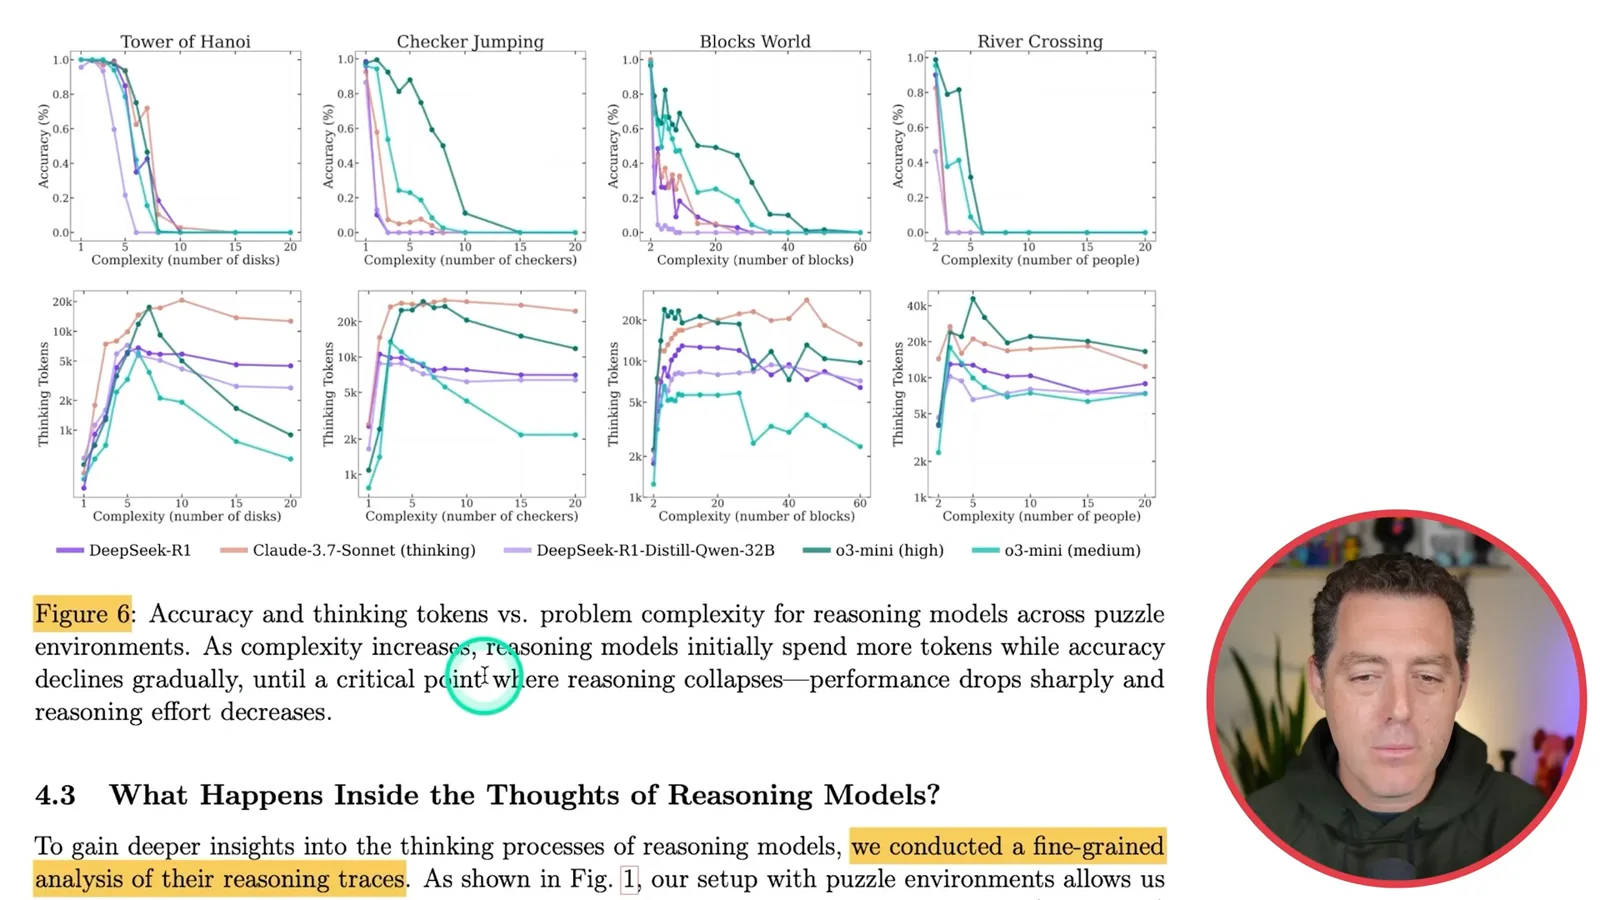
The paper reports that reasoning-token use initially rises with puzzle complexity but falls after a point as performance collapses, despite an available token budget. I wonder whether that resembles “giving up,” but the token pattern alone does not establish the model’s motivation.
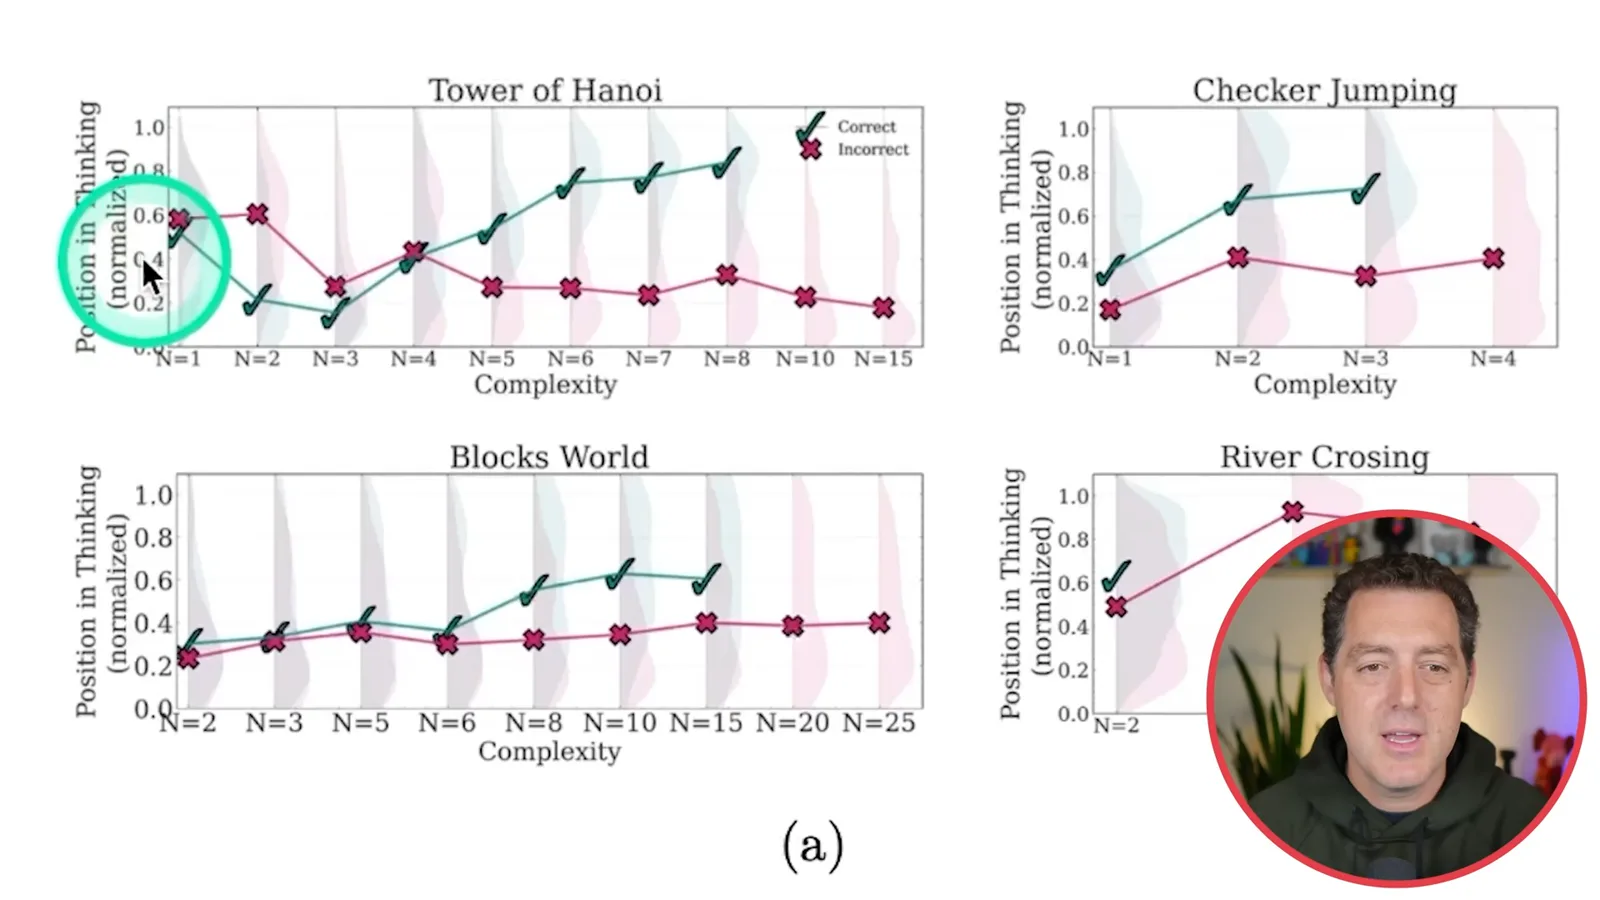
The authors examine where correct and incorrect candidate solutions appear in reasoning traces. On some easier instances they find correct solutions early followed by further exploration, which they call overthinking; on moderately difficult problems correct solutions more often appear later. The patterns vary among the puzzle environments.
Algorithms and the broader debate
Providing an algorithm does not eliminate failure in the paper’s Tower of Hanoi setup. Berman contrasts the study’s scope with Sutskever’s broader prediction.
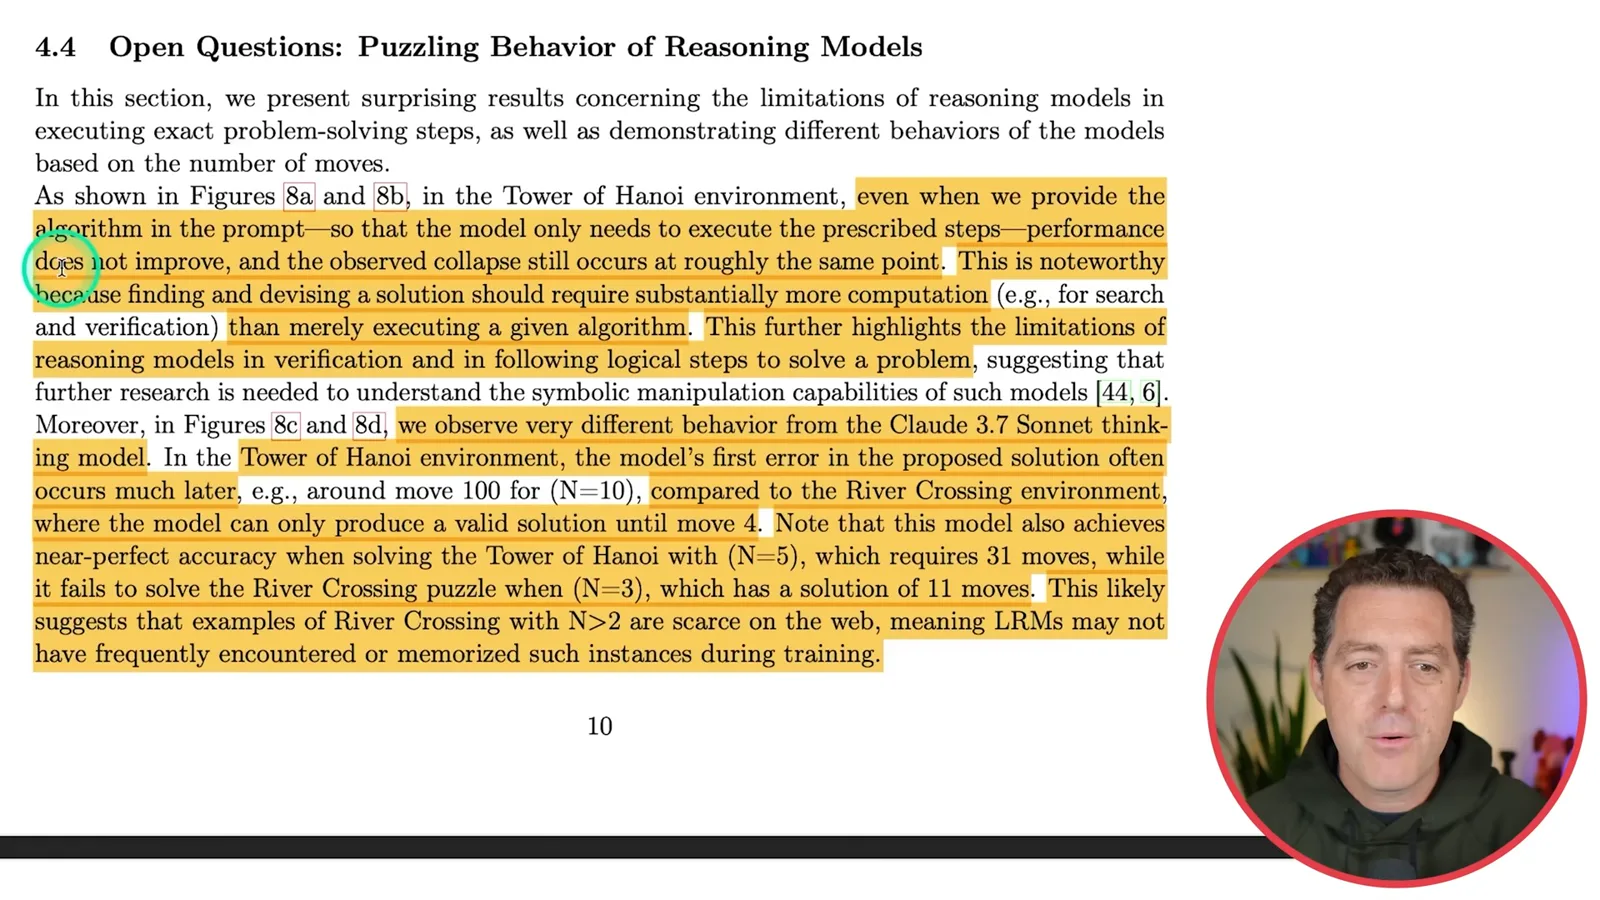
In the Tower of Hanoi tests, the researchers also provide an explicit algorithm in the prompt. They report that this did not prevent the observed failure around the same complexity point, suggesting difficulty executing and verifying long sequences in that setup. The first error appeared at different points across puzzle types.
I contrast the debate with a clip of Ilya Sutskever’s commencement remarks. He predicts AI will eventually perform anything people can learn, arguing that the human brain is a biological computer and asking why a digital computer could not do the same. This is his broader prediction, not a result of Apple’s puzzle experiments.
The authors acknowledge that their experiments cover a narrow slice of reasoning and may not reflect diverse real-world or knowledge-intensive tasks. I agree that poor results on these puzzles alone do not prove models cannot think: models also show abilities in coding and other domains.
A code-assisted Tower of Hanoi test
Berman asks Claude to generate a game with an automated solver. A ten-disc run finishes, while a 20-disc run is shown in progress.
My biggest question is whether a model should get credit for writing code to solve the puzzles. I ask Claude 3.7 to build a Tower of Hanoi simulation in HTML and JavaScript, with up to ten discs and a solve button, without providing the algorithm in the prompt.
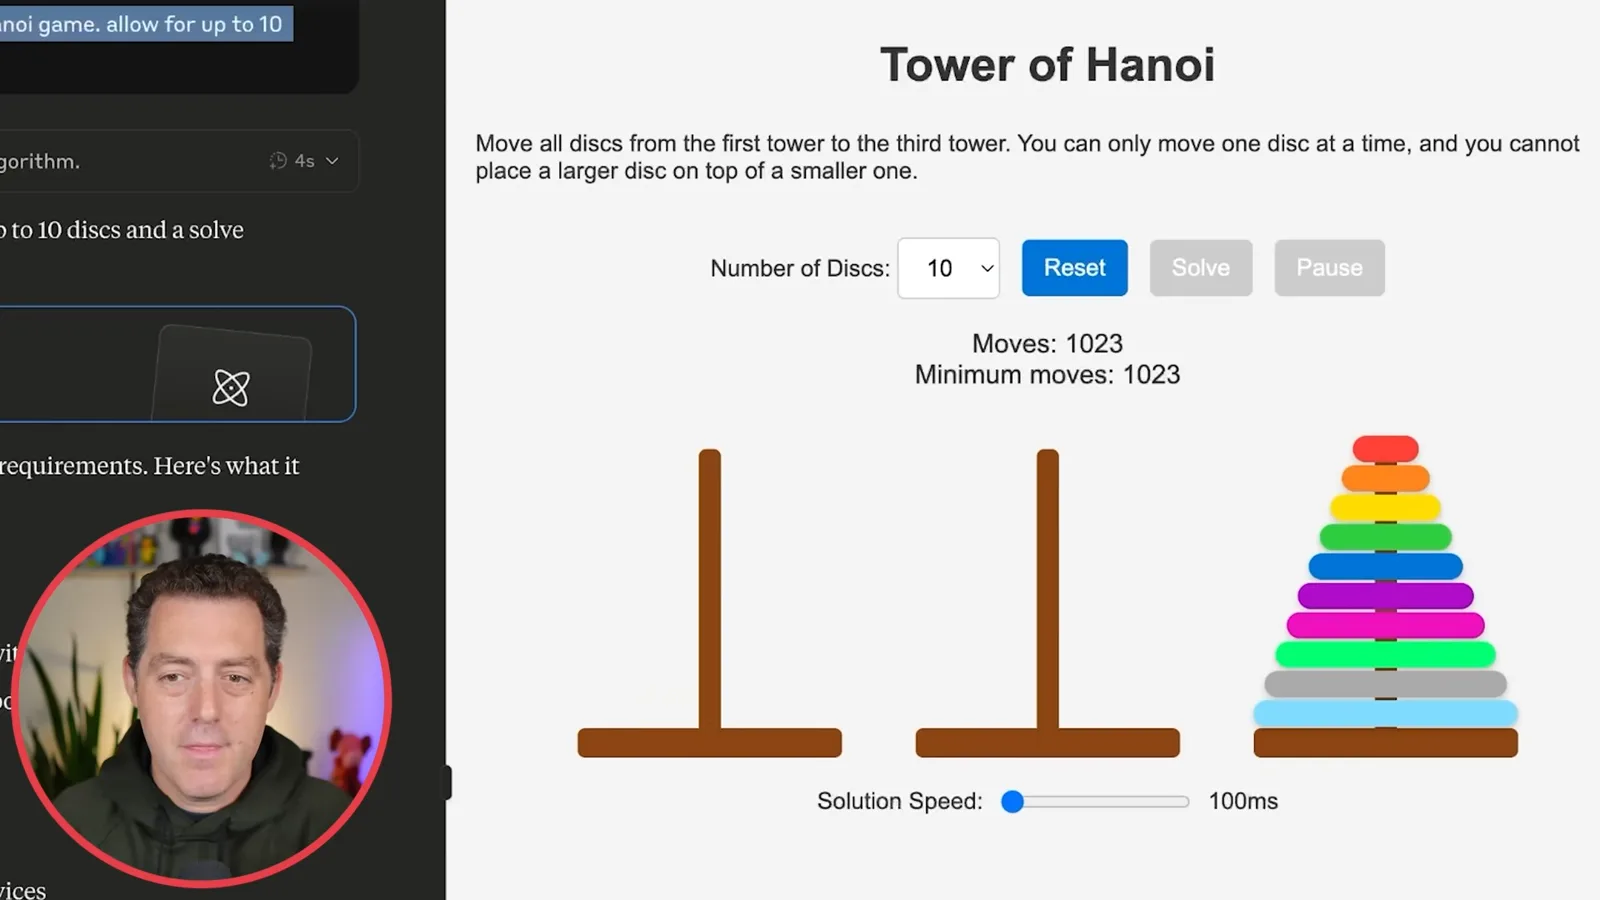
The generated program reaches the solved state for ten discs in 1,023 moves. I then request a 20-disc version; the video shows it running, with a visual formatting issue, and displays a minimum of 1,048,575 moves. The clip does not show the 20-disc run finishing.
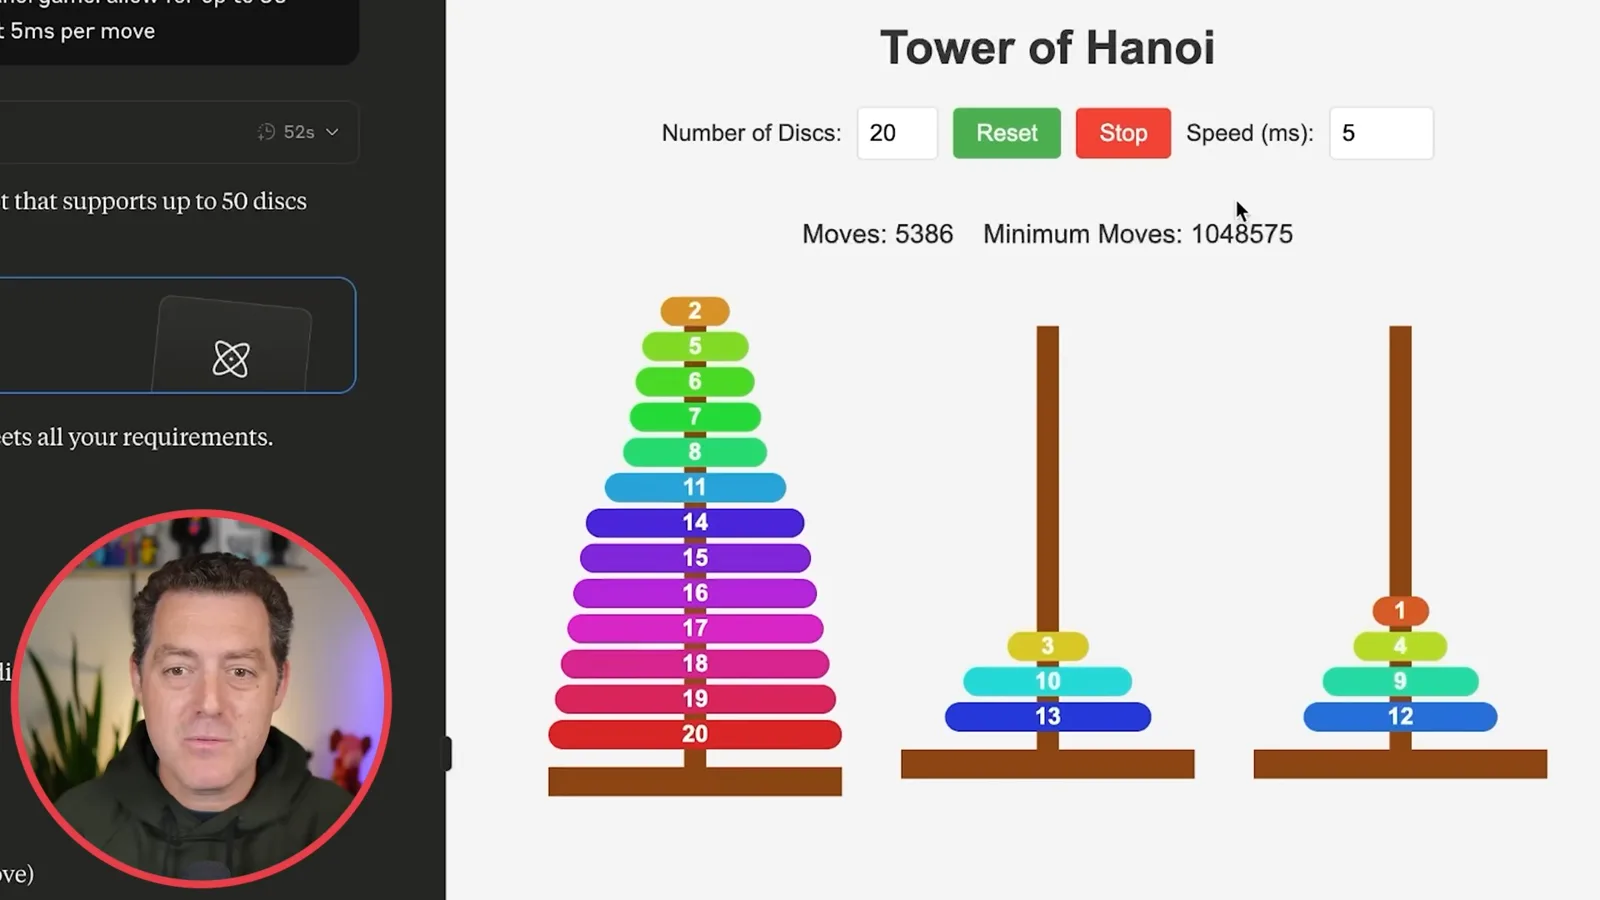
A program can execute the algorithm after the model writes it, which is a different setting from having a model directly enumerate moves in natural language. I ask whether that tool-assisted route should count as solving the problem. The demonstration illustrates an alternative workflow rather than directly replicating the paper’s evaluation.
Sur la même chaîne
 34:21EN
 Matthew Berman· 27 oct. 2026Matthew Berman Examines Anthropic’s IPO Filing, AI Growth and GovernanceMatthew Berman, Sam Altman · Forward FutureThe presenter reviews the S-1’s financial metrics, compute strategy and voting structure while questioning the tension between rapid AI development and safety.
 0:36ENMatthew Berman· 25 oct. 2026Kimi K3.1 and a Rubik’s Cube Solver DemonstrationMatthew Berman · Forward FutureMatthew Berman shows a scrambled virtual cube being solved and gives the Kimi K3.1 test a favorable assessment.
 25:50ENMatthew Berman· 24 oct. 2026Kimi K3.1 Pro Tested: Strong 3D Demos, Uneven Results and Competitive PricingMatthew Berman · Forward FutureMatthew Berman tests the open-weight model on coding, 3D rendering and visual explanations, then compares benchmark results and prices.
 32:20ENMatthew Berman· 23 oct. 2026Who Is Local AI For? The Costs, Trade-offs and a Hybrid FutureMatthew Berman · Forward FutureMatthew Berman weighs data control and independence against hardware cost, setup complexity and inference speed.
 1:03:37ENMatthew Berman· 23 oct. 2026Matthew Berman’s Team Tests Kimi K3.1 on Animation, Games, and ChartsMatthew Berman, Alex, Brian · Forward FutureA live team AMA turns into an informal test of Kimi K3.1, from personal-agent workflows to motion graphics, a browser game, and a benchmark chart.
 0:53ENMatthew Berman· 22 oct. 2026Sam Altman on AI and the Discovery of New KnowledgeSam Altman · OpenAIAltman expects progress in mathematical discovery to extend to biology, materials and energy.