En 30 segundos
In April 2025 Matthew Berman reviews OpenAI’s PaperBench, which asks agents to implement and run experiments from 20 machine-learning papers. He explains its author-developed rubrics, automated judge, model results and costs, and speculates about future self-improvement. The reported scores measure partial progress, while the small human comparison, imperfect judge and potential contamination constrain interpretation.
- 1Twenty papersThe benchmark contains 20 ICML 2024 papers with detailed author-developed grading rubrics.
- 2An imperfect automated judgeAn o3-mini-high judge scored F1 0.83 on a separate human-labeled evaluation, not perfect accuracy.
- 3Partial-credit resultClaude 3.5 Sonnet scored 21% under the BasicAgent setup, a weighted rubric score rather than a percentage of fully replicated papers.
- 4Small human comparisonOn three papers, best-of-three human attempts scored 41.4% after 48 hours versus 26.6% for o1 in that comparison.
- 5Scaffolding changes resultsIterativeAgent raised scores for o1 and o3-mini but lowered Claude 3.5 Sonnet’s score compared with BasicAgent.
- 6Key limitationsSmall paper count, possible contamination, imperfect judging and substantial evaluation cost limit interpretation.
Conclusiones
- PaperBench evaluates research replication using 20 ICML 2024 papers and detailed weighted rubrics.
- Claude 3.5 Sonnet’s 21% BasicAgent score is partial credit, not proof that it fully replicated 21% of papers.
- The human comparison covers a three-paper subset with its own time and selection conditions.
- The automated judge scored F1 0.83 against human labels on JudgeEval but can make errors.
- A different agent scaffold improved some models and reduced another’s score.
- Recursive self-improvement and an intelligence explosion are extrapolations, not measured outcomes of this experiment.
Lee el texto editado por capítulos
The replication benchmark
Berman introduces PaperBench and his speculation about an intelligence explosion. The study measures research replication rather than self-improvement.
OpenAI's PaperBench evaluates whether AI agents can replicate machine-learning research. I see this as a possible step toward agents improving AI research itself and discuss Leopold Aschenbrenner's idea of an intelligence explosion. That extrapolation is my forecast: the benchmark measures partial replication, not autonomous recursive self-improvement or an impending explosion.
The agent receives a paper and clarifications, then writes code and runs experiments in an environment with tools such as a browser, shell, Python and a document reader. A genuine replication requires more than summarizing: it involves implementing experiments, debugging them and producing results.
Papers, rubrics and the judge
The benchmark uses 20 papers with author-developed rubrics and validates an automated judge on a separate human-labeled dataset. The video includes a GrowthSchool sponsorship.
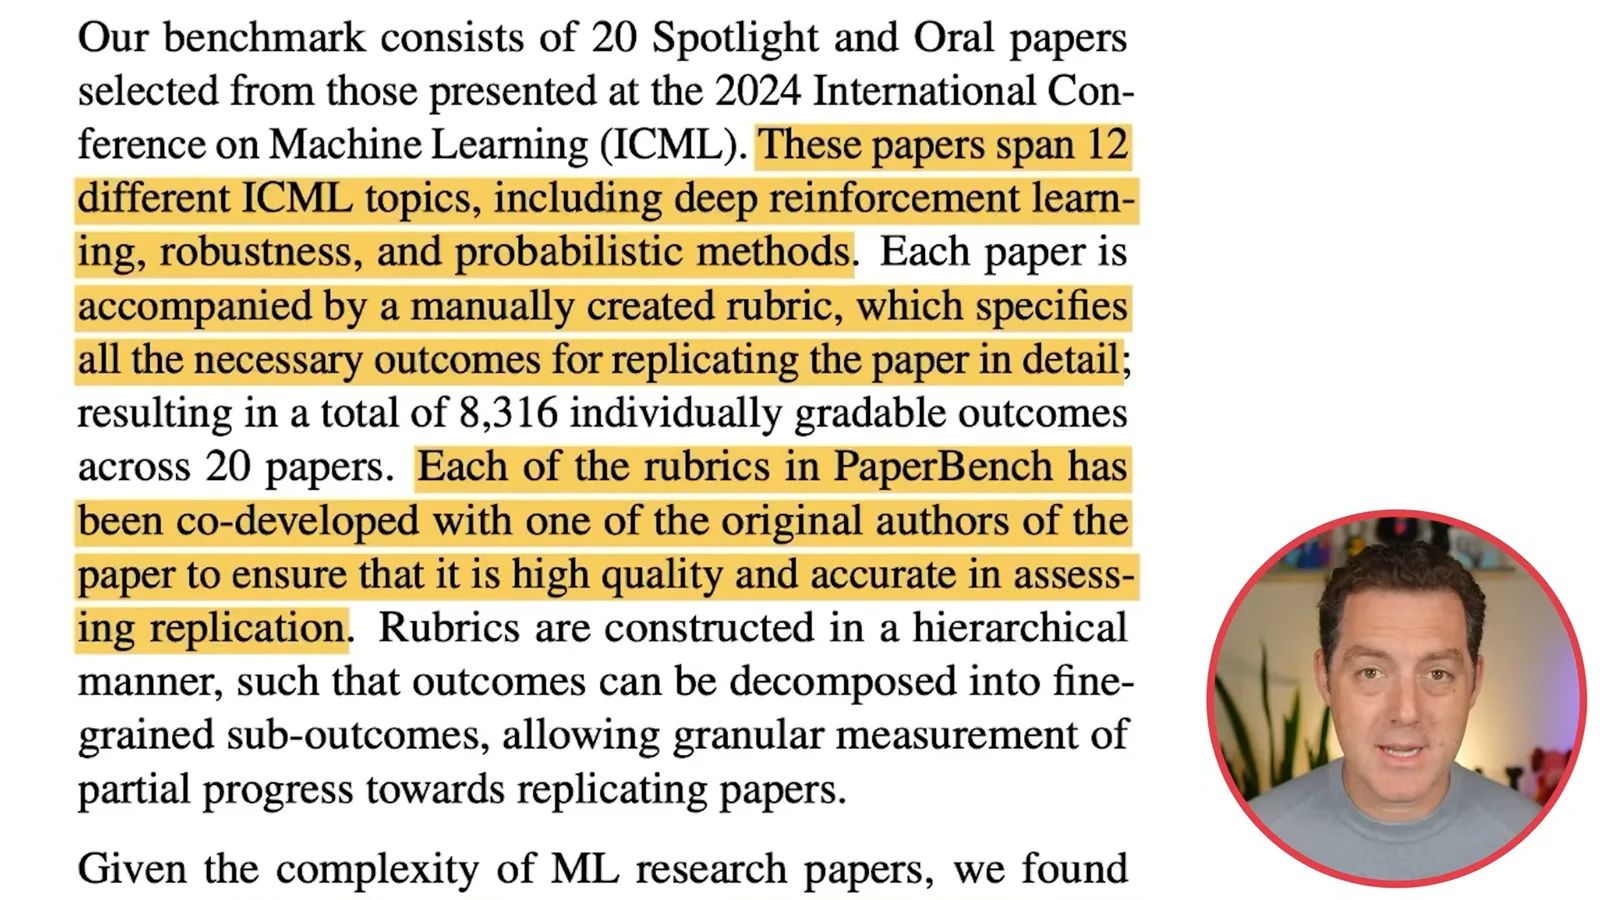
PaperBench contains 20 spotlight or oral papers from ICML 2024 across 12 topics, including reinforcement learning, robustness and probabilistic methods. Each rubric was developed with an original author and breaks replication into many graded requirements. Author involvement improves relevance but does not guarantee perfect assessment.
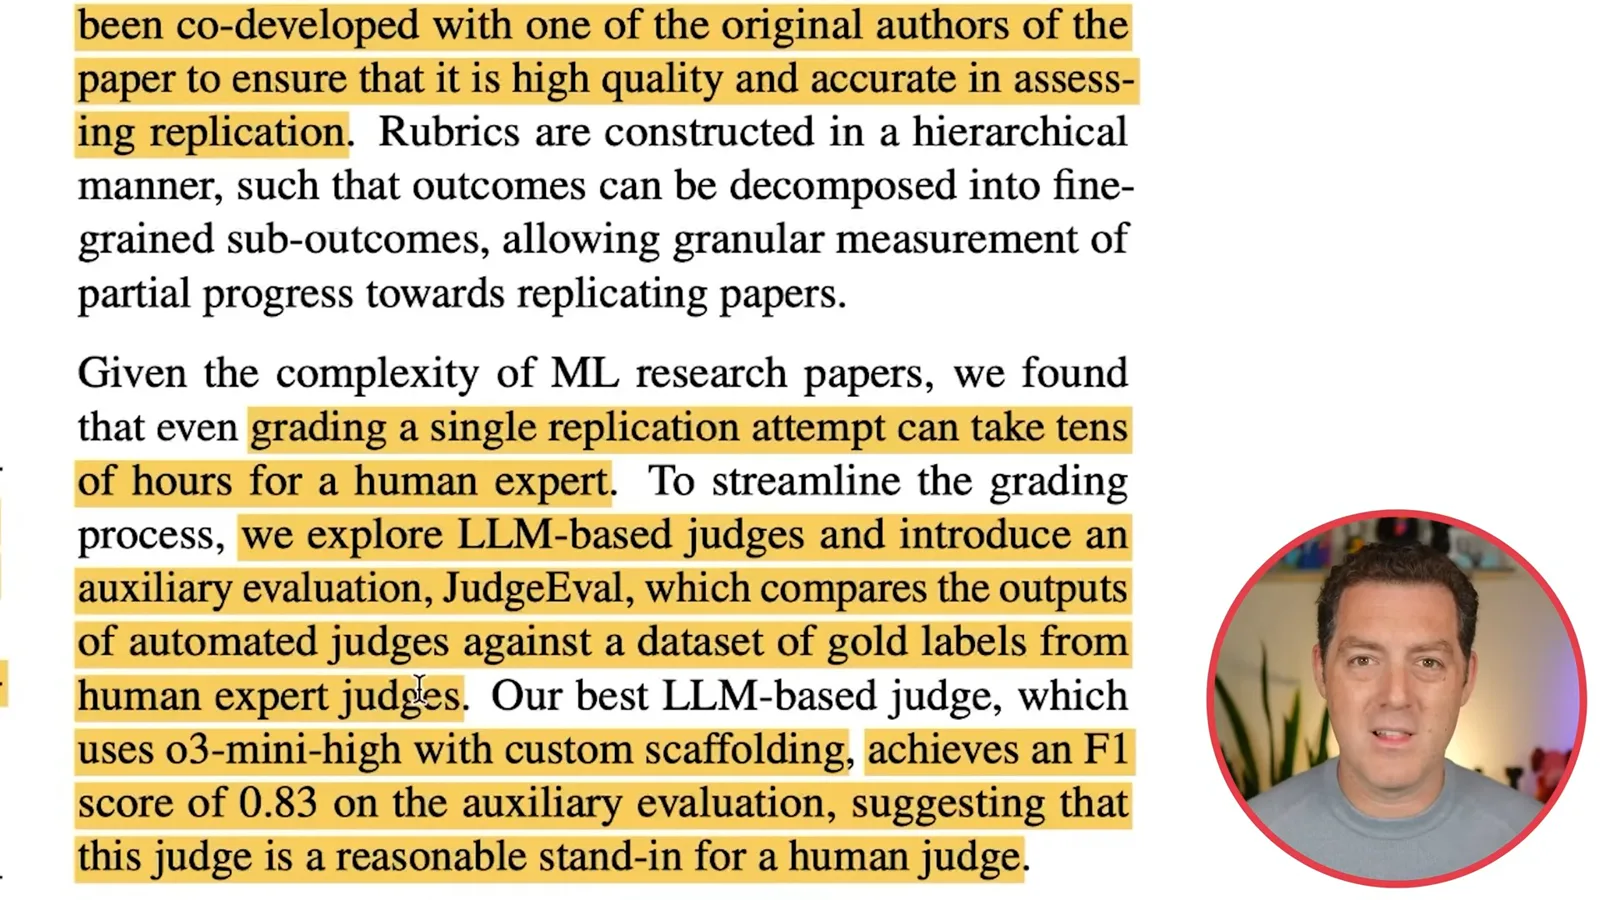
Grading a single attempt can take a human expert tens of hours. The researchers therefore built an automated judge and JudgeEval, a separate evaluation against human-labeled examples. Their o3-mini-high judge achieves an F1 score of 0.83 on that auxiliary dataset; this is not a claim that it is always correct or equivalent to a human expert.
I think the tools and orchestration around a model—the agent scaffold—matter alongside the model itself. These components let it read files, use a terminal and browse. The video includes a sponsored segment for GrowthSchool before returning to the study.
Workflow and initial results
The host reviews the BasicAgent result and a small human comparison. Scores represent partial credit, not complete papers reproduced.
Under the paper's BasicAgent setup, Claude 3.5 Sonnet (New) scores an average 21.0% across the 20 papers. This is weighted partial credit across requirements, not evidence that 21% of the papers were fully replicated. The team could not complete its Claude 3.7 Sonnet experiments because of API rate limits, and Gemini 2.5 Pro was not among the listed models.
The workflow starts with the paper, proceeds through code, experiment setup and execution, and passes the submission to a judge using the author-developed rubric. I compare the environment to other coding agents. A successful program execution is useful feedback, but it does not automatically verify scientific correctness or make improvement infinitely scalable.
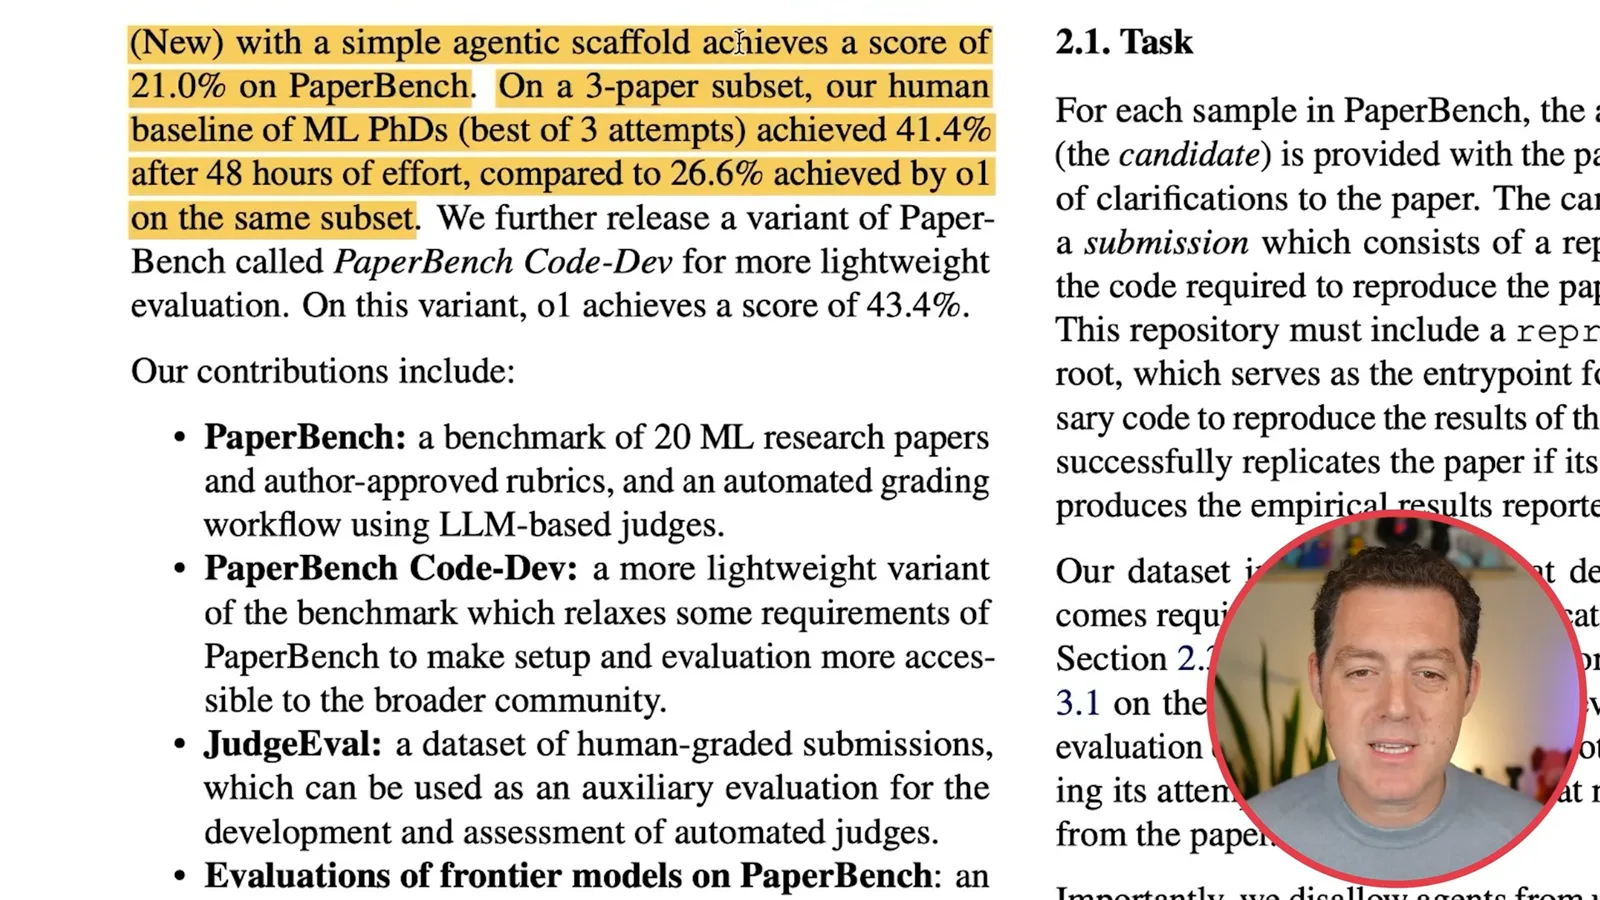
The human comparison is narrower than the full benchmark: on a three-paper subset, ML PhDs' best of three attempts scored 41.4% after 48 hours, while o1 scored 26.6% on the same subset. Different resources and selection conditions matter, and the result is not a general measurement of human versus AI research ability.
Execution and grading
Submissions are rerun in a clean environment and graded with weighted rubric trees. Different requirements distinguish code, execution and result match.
A candidate submission is a repository containing the implementation and a reproduce.sh entry point. The agent can browse online but must not use the original authors' code or other prohibited replications on a per-paper blacklist. The blacklist reduces direct reuse; it cannot prove the model never encountered related material during training.
To count a result as reproduced, the submission is copied into a fresh Ubuntu environment with an A10 GPU and the script is run. This clean rerun helps separate an agent's claims from evidence in its generated code and results, although the rubric also recognizes incomplete progress.
Each rubric is a tree. Individual leaf requirements are graded pass or fail, and their scores roll upward as weighted averages to form a final replication score. This provides partial credit for specific accomplishments, rather than treating the whole paper as a single pass-or-fail item.
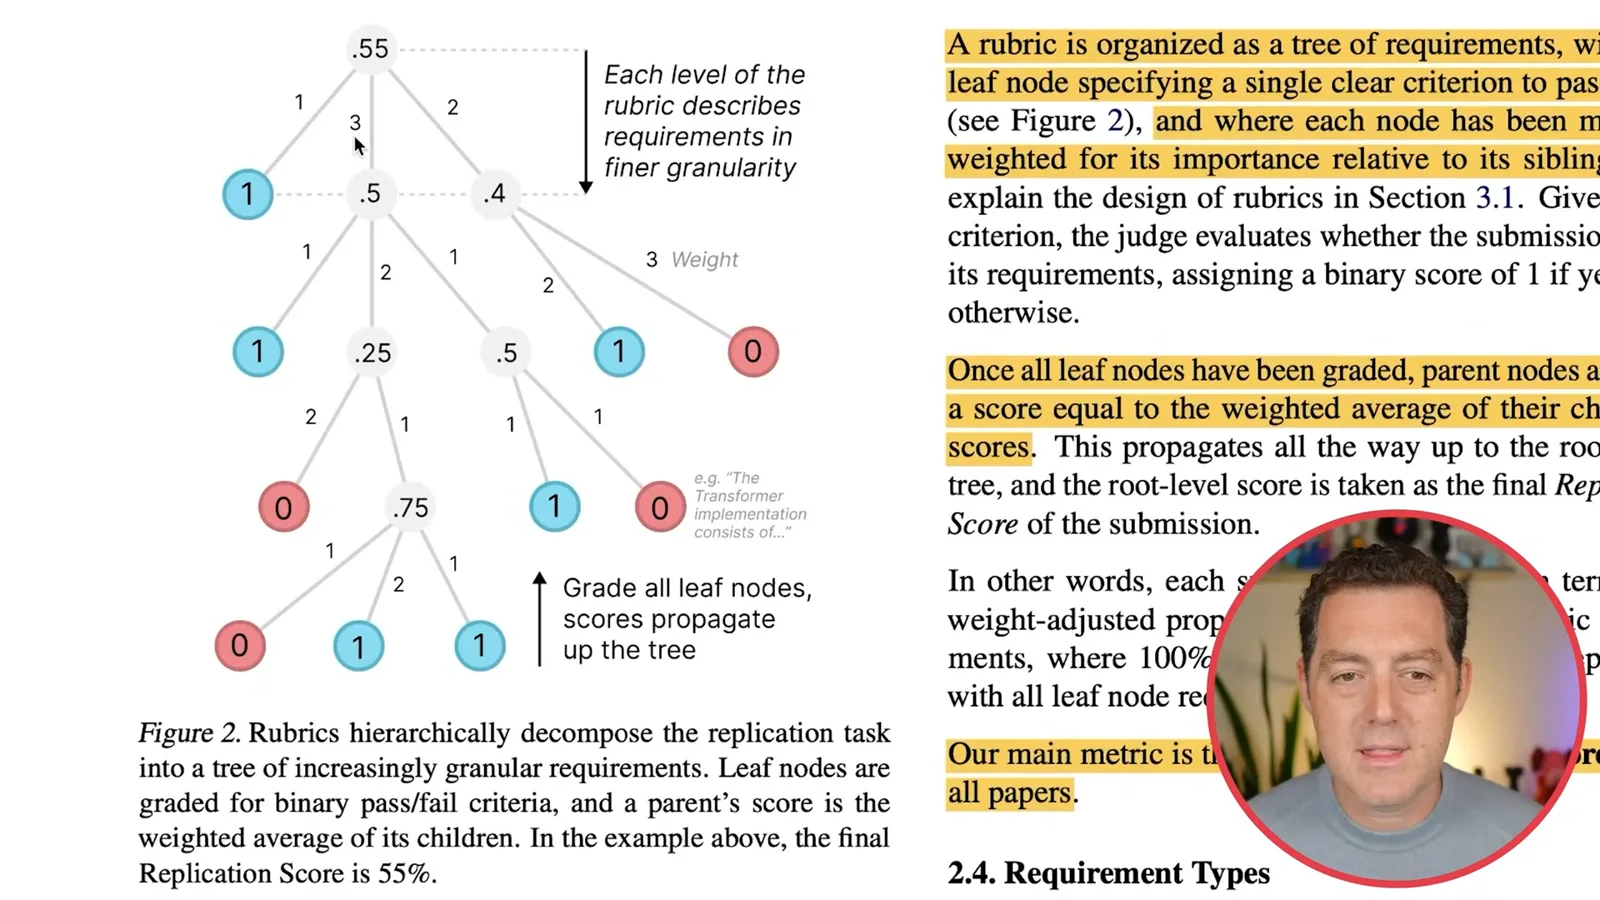
The leaf requirements cover result match, execution and code development. A judge checks whether a particular result is supported, whether the relevant execution occurred and whether code appears to implement the required method. The latter two can receive credit even when the full research result has not been reproduced.
I compare that partial-credit idea to process-based rewards in training, where intermediate steps may be evaluated separately. Here the rubric is an evaluation of submissions; the paper does not demonstrate that these scores trained the tested models or that the agent learned from each graded step.
Rules, cost and evaluation variants
The paper describes permitted tools, blacklists and a cheaper code-only variant. Automated grading has cost and accuracy tradeoffs.
PaperBench is intended to accommodate different models and scaffolds. Its rules allow tools and external services, with blacklists to prevent downloading prohibited implementations; developers can provide credentials for necessary services because obtaining accounts is not the skill being measured.
Full evaluation can be expensive, so PaperBench Code-Dev only assesses code-development requirements and skips the reproduction run and result-match evaluation. It reduces GPU and grading costs, but a code-only score is not evidence that experiments ran or results were replicated.
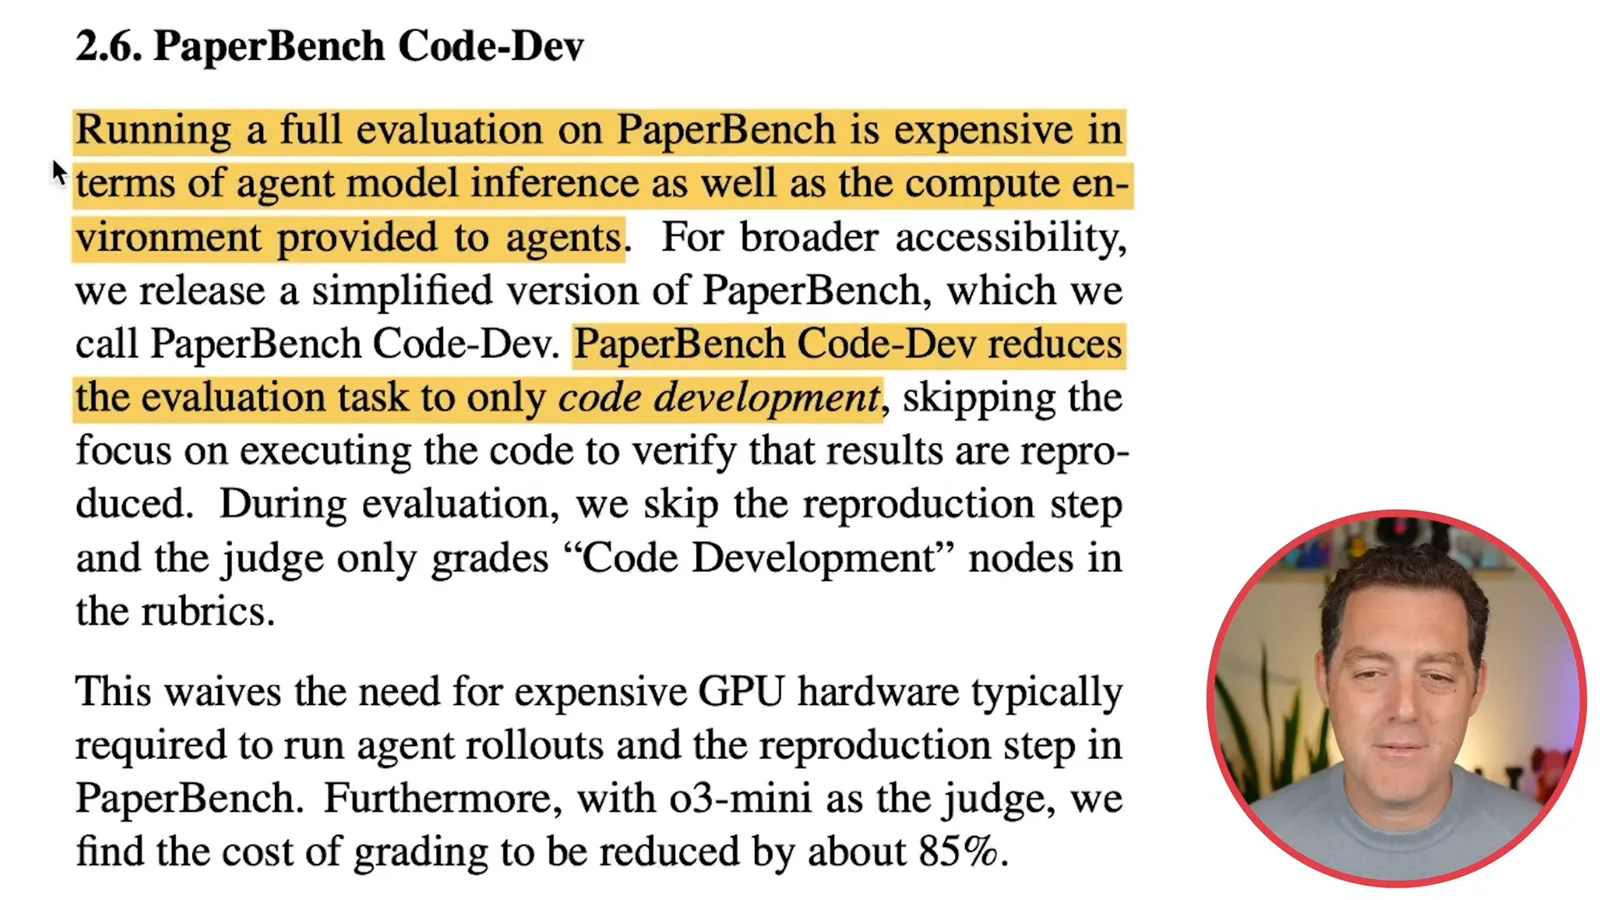
Developing the rubrics with paper authors required substantial expert work and multiple rounds of review. The automated judge receives the paper, rubric and relevant submission material; because a codebase may exceed the context window, it ranks files and includes the most relevant ones. This selection and automated judgment can introduce errors.
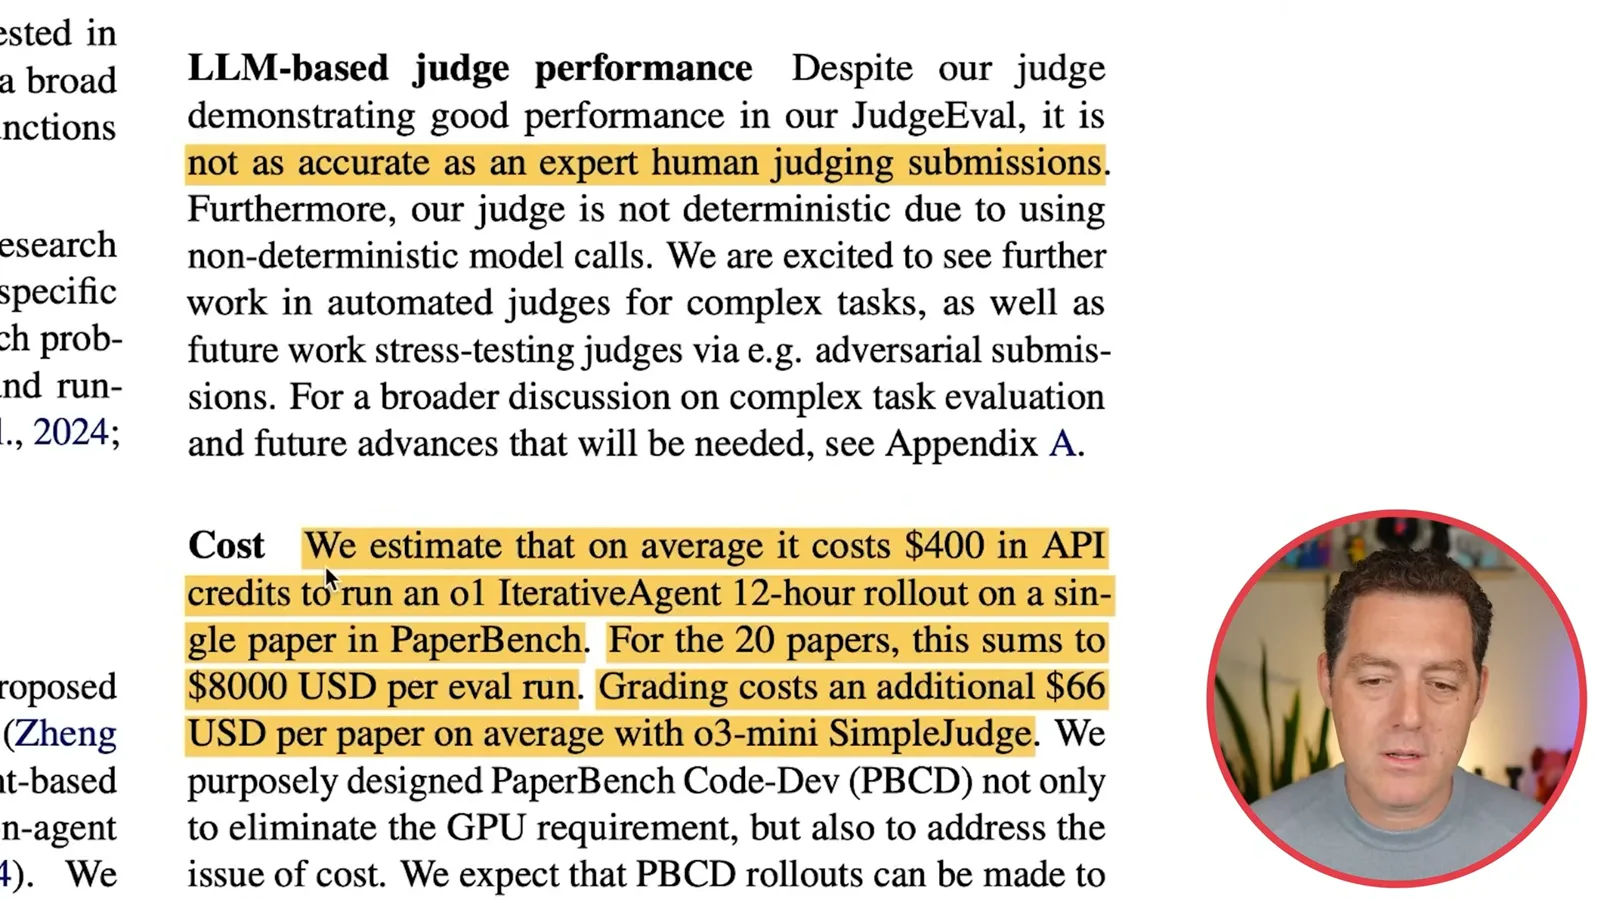
The researchers estimate roughly $66 in API credits to grade a full submission with the o3-mini judge, compared with about $10 for Code-Dev. These are estimates from the 2025 study, not today's guaranteed prices. Human grading was slower and costlier, but the paper also states that its judge is less accurate than an expert.
Results, limitations and implications
Berman reviews model and scaffold results, contamination risk and cost. His intelligence-explosion prediction goes beyond the study.
The main experiment evaluated GPT-4o, o1, o3-mini, DeepSeek-R1, Claude 3.5 Sonnet (New) and Gemini 2.0 Flash, with three runs per paper and a 12-hour limit. Claude 3.5 Sonnet scored 21.0%, o1 13.2%, and the other tested models were below 10% under this scaffold.
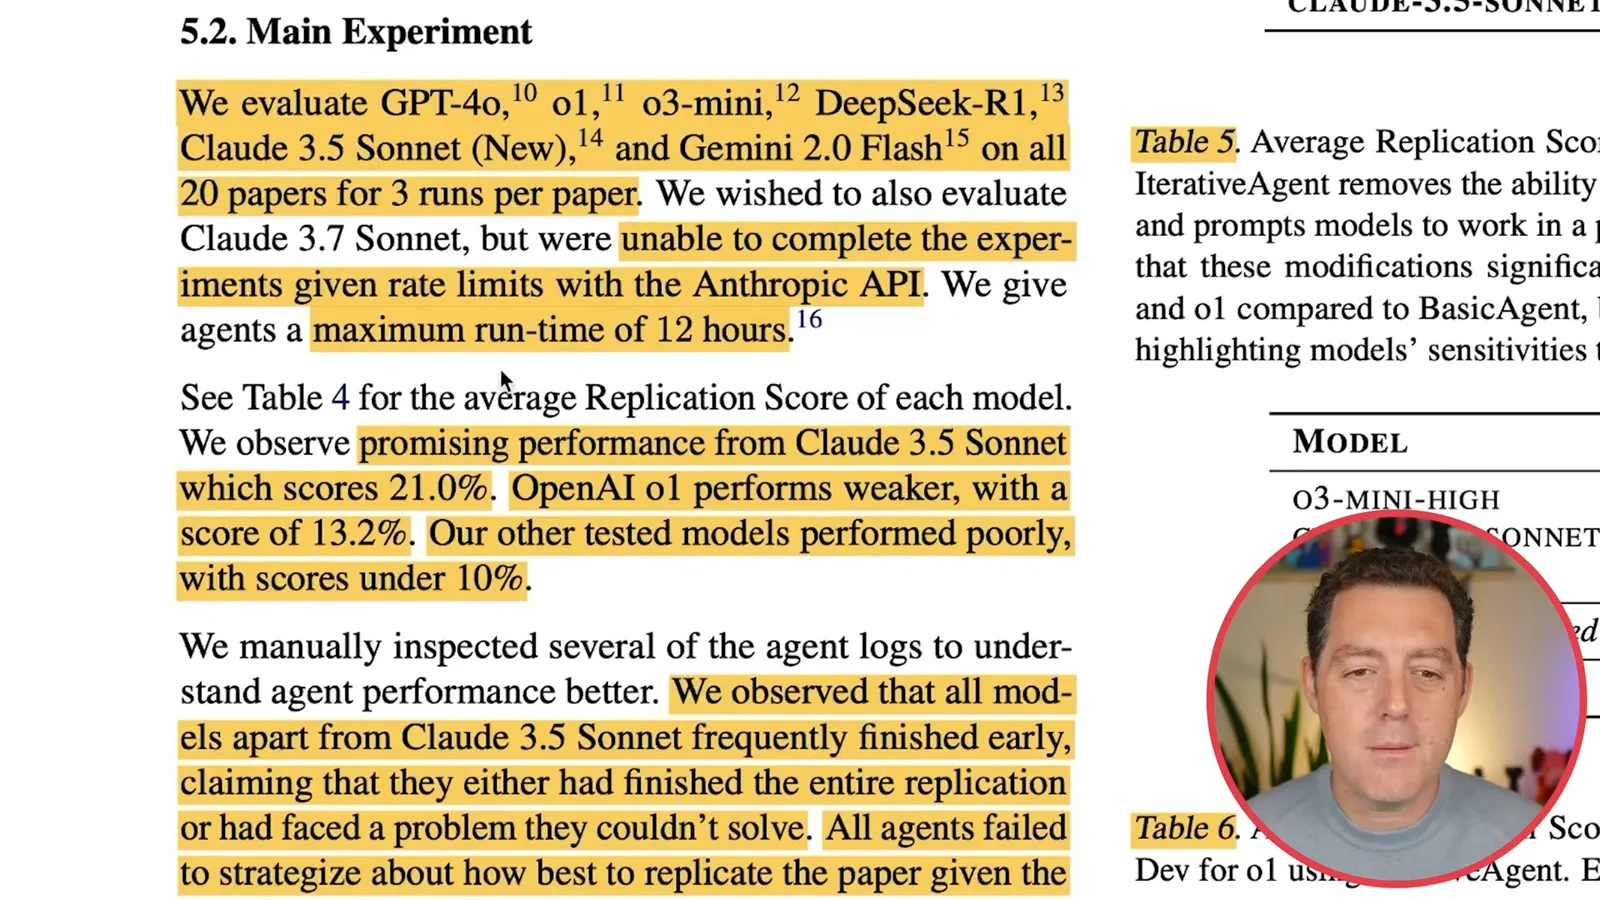
The researchers observed that models other than Claude 3.5 Sonnet often stopped early, claiming completion or an insurmountable problem. They also observed poor time allocation and o3-mini struggling with tool use. I believe better scaffolding and tool training may help, but the experiment does not prove the underlying models need no improvement.
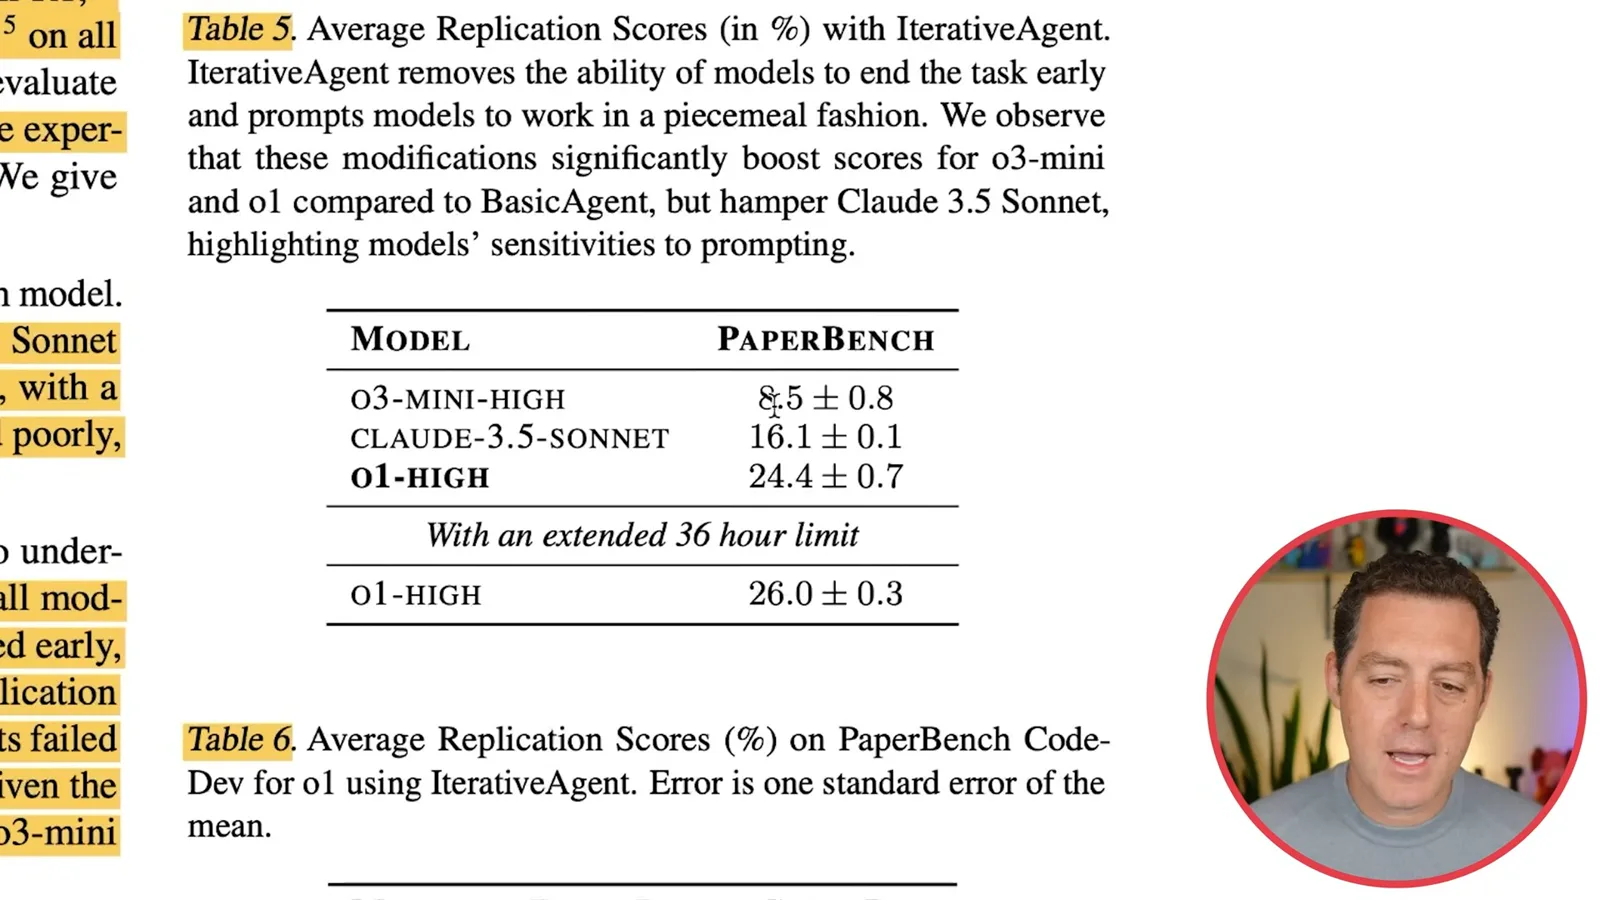
The team tested IterativeAgent, which prevents early termination and prompts models to work in pieces. It reports 8.5% for o3-mini-high, 16.1% for Claude 3.5 Sonnet and 24.4% for o1-high; an extended 36-hour o1 run reached 26.0%. The change improved some results and worsened Claude's, showing that scaffolding and prompt choices interact with the model.
The authors identify dataset size as a limitation: 20 papers cover only part of machine-learning research, even though their rubrics contain thousands of individual requirements. Those requirements offer fine-grained observations but do not make the sample equivalent to thousands of independent papers.
Training-data contamination is another concern. The paper's authors argue that the papers' recency makes contamination less likely for the tested models, but blacklisting websites during an evaluation cannot rule it out. Future models could also have encountered the papers or their implementations.
Building new tasks remains labor-intensive, and the model judge is not as accurate as an expert and can be nondeterministic. The authors estimate about $400 in API credits for a 12-hour o1 IterativeAgent rollout on one paper, or $8,000 for 20 papers, plus about $66 per paper for judging.
My conclusion is that agents made meaningful partial progress but were still far from reliably reproducing all of the work. I expect models and scaffolds to improve, and I see a possible path toward accelerated AI research. Whether that leads to rapid recursive self-improvement is a prediction, not a result established by PaperBench.
Más de este canal
 34:21EN
 Matthew Berman· 27 oct 2026Matthew Berman Examines Anthropic’s IPO Filing, AI Growth and GovernanceMatthew Berman, Sam Altman · Forward FutureThe presenter reviews the S-1’s financial metrics, compute strategy and voting structure while questioning the tension between rapid AI development and safety.
 0:26ENMatthew Berman· 25 oct 2026Sam Altman on Human Values and Problem-Solving in an AI WorldSam Altman · OpenAIIn a short interview excerpt, Altman considers the enjoyment of solving hard problems and the human role in interpreting results.
 0:36ENMatthew Berman· 25 oct 2026Kimi K3.1 and a Rubik’s Cube Solver DemonstrationMatthew Berman · Forward FutureMatthew Berman shows a scrambled virtual cube being solved and gives the Kimi K3.1 test a favorable assessment.
 0:21ENMatthew Berman· 24 oct 2026An AI-Generated Kimi Benchmark Chart Used Invented ScoresMatthew Berman · Forward FutureMatthew Berman asks for a graph of Kimi K3.1 Pro benchmarks, then discovers that the displayed figures are illustrative placeholders.
 25:50ENMatthew Berman· 24 oct 2026Kimi K3.1 Pro Tested: Strong 3D Demos, Uneven Results and Competitive PricingMatthew Berman · Forward FutureMatthew Berman tests the open-weight model on coding, 3D rendering and visual explanations, then compares benchmark results and prices.
 32:20ENMatthew Berman· 23 oct 2026Who Is Local AI For? The Costs, Trade-offs and a Hybrid FutureMatthew Berman · Forward FutureMatthew Berman weighs data control and independence against hardware cost, setup complexity and inference speed.