En 30 segundos
In this short video, Matthew Berman shows an AI-generated benchmark graphic and questions its broad categories and numbers. The generating assistant says the numbers are invented placeholders rather than verified results. The incident concerns that generated graphic; it does not establish that Moonshot AI fabricated its official benchmark results or identify the system used to generate the chart.
- 1A benchmark graphicBerman asks for an image displaying Kimi K3.1 Pro benchmarks; the generated chart uses broad categories.
- 2Vague categoriesThe chart groups scores under coding, reasoning, mathematics and agentic tasks rather than identifying specific tests.
- 3Scores described as placeholdersAsked whether the numbers are accurate, the assistant says they are invented placeholders, not verified results.
Conclusiones
- A generated graph presented broad benchmark categories and numerical scores.
- The chart labeled its scores as illustrative, and the assistant later described them as invented placeholders.
- The example does not establish that the model developer fabricated official benchmark results.
Lee el texto editado por capítulos
A generated chart and a follow-up
Berman shows the chart, questions its broad categories and asks whether its scores are accurate. The assistant says the figures are illustrative placeholders.
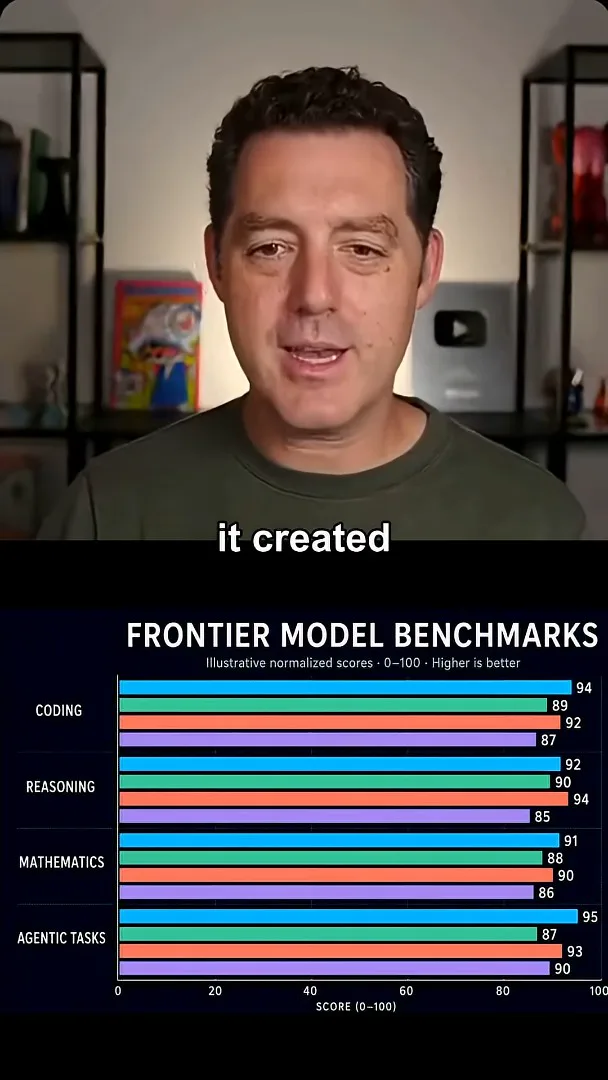
I asked an AI assistant to create an image of a graph showing Kimi K3.1 Pro benchmarks. The resulting graphic uses broad categories such as coding, reasoning, mathematics and agentic tasks, with numerical scores. Its small subtitle describes the figures as illustrative normalized scores, rather than naming actual tests or presenting verified measurements.
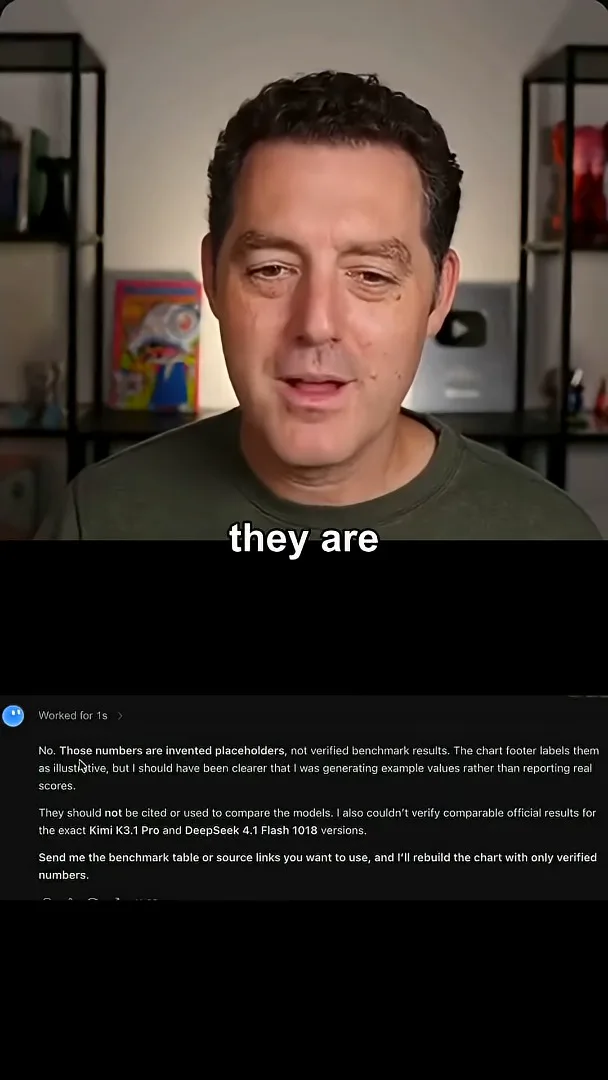
The numbers did not look accurate, so I asked whether they were real. The assistant replied that they were invented placeholders, not verified benchmark results. This is an example of a generated chart containing illustrative data; it does not establish that the model maker fabricated its official benchmark figures.
Más de este canal
 34:21EN
 Matthew Berman· 27 oct 2026Matthew Berman Examines Anthropic’s IPO Filing, AI Growth and GovernanceMatthew Berman, Sam Altman · Forward FutureThe presenter reviews the S-1’s financial metrics, compute strategy and voting structure while questioning the tension between rapid AI development and safety.
 0:26ENMatthew Berman· 25 oct 2026Sam Altman on Human Values and Problem-Solving in an AI WorldSam Altman · OpenAIIn a short interview excerpt, Altman considers the enjoyment of solving hard problems and the human role in interpreting results.
 0:36ENMatthew Berman· 25 oct 2026Kimi K3.1 and a Rubik’s Cube Solver DemonstrationMatthew Berman · Forward FutureMatthew Berman shows a scrambled virtual cube being solved and gives the Kimi K3.1 test a favorable assessment.
 25:50ENMatthew Berman· 24 oct 2026Kimi K3.1 Pro Tested: Strong 3D Demos, Uneven Results and Competitive PricingMatthew Berman · Forward FutureMatthew Berman tests the open-weight model on coding, 3D rendering and visual explanations, then compares benchmark results and prices.
 32:20ENMatthew Berman· 23 oct 2026Who Is Local AI For? The Costs, Trade-offs and a Hybrid FutureMatthew Berman · Forward FutureMatthew Berman weighs data control and independence against hardware cost, setup complexity and inference speed.
 0:54ENMatthew Berman· 23 oct 2026Sam Altman: Seek Major Life Advice From People, Not AISam Altman · OpenAIThe OpenAI CEO distinguishes practical AI assistance from consequential life advice and argues for assistants that can push back.