En 30 segundos
In a June 2026 livestream, Matthew Berman discusses Anthropic’s Fable 5 and Mythos 5 announcement, benchmarks, safeguards and pricing, then tests coding tasks with viewers. He corrects an early model-selection mistake, demonstrates a Rubik’s cube and fluid simulation, and reports that P versus NP and the Collatz conjecture were not solved. Anthropic later suspended and restored model access; launch figures and availability are historical.
- 1Fable and Mythos accessAnthropic described a shared underlying model with stronger safeguards for general-use Fable and restricted Mythos access. The policies changed after launch.
- 2Provider benchmark claimsAnthropic’s table reported results such as 80.3% on SWE-bench Pro under its own settings. Comparisons and safeguards matter when interpreting the grouped table.
- 3Launch pricing and routingThe launch listed $10 per million input tokens and $50 per million output tokens. Berman recommends reserving the expensive model for tasks that justify it.
- 4Correcting a model-selection mistakeA viewer exposed a desktop fallback; Berman acknowledged the initial tests were not reliable Fable tests and switched to the CLI.
- 5No mathematical breakthroughThe assistant said it could not solve P versus NP or the Collatz conjecture. The city-builder task was also unfinished at the close.
Conclusiones
- Anthropic says Fable 5 and Mythos 5 share an underlying model but use different safeguards and access arrangements.
- Benchmark figures are provider-reported and task-specific; Berman’s positive early impressions and complaints about verbosity and confirmation loops are anecdotal.
- A desktop model-selection fallback invalidated the first purported Fable tests, which Berman corrected before switching to the CLI.
- The visible cube and fluid demos show interactive behavior, not proof of general algorithmic correctness or scientific simulation accuracy.
- P versus NP and the Collatz conjecture were not solved; the city-builder task was unfinished when the stream ended.
- Anthropic later suspended access during export controls and restored it after the controls were lifted.
Lee el texto editado por capítulos
Launch and early impressions
The available transcript starts at 4:49. Berman introduces Fable and Mythos, then initially struggles to select the model in Claude Code desktop.
Matthew Berman begins a June 9, 2026 livestream about Anthropic’s newly announced Claude Fable 5, a Mythos-class model. He says he had used it for a week and plans to discuss his impressions before running live tests. The available automatic transcript begins at 4:49; the preceding audio is not represented in the transcript.
He tries to start several coding tests but cannot find Fable in the Claude Code desktop model selector. It is visible in other Claude surfaces, so he postpones the tests and opens the announcement. A later viewer suggestion seems to select Fable in the desktop app, but he ultimately discovers those early tests fell back to another model.
Berman explains that Anthropic released Fable 5 for general use with stronger safeguards and made Mythos 5 available to selected trusted cybersecurity partners. Anthropic later clarified that the two share an underlying model, with different safeguards. A general-use safeguard is not proof that all risky requests are blocked or that legitimate security tasks are categorically unavailable.
Benchmarks, pricing and early use
He reviews Anthropic’s benchmark table and launch prices, compares them with his limited personal experience and discusses verbosity, latency and routing.
He opens Anthropic’s benchmark table and cautions that numerical improvements do not always match how models feel in use. He had expected the newer Deep Suite evaluation as well, but it was not in the displayed table. He is especially interested in how well results translate to agentic coding and knowledge work.
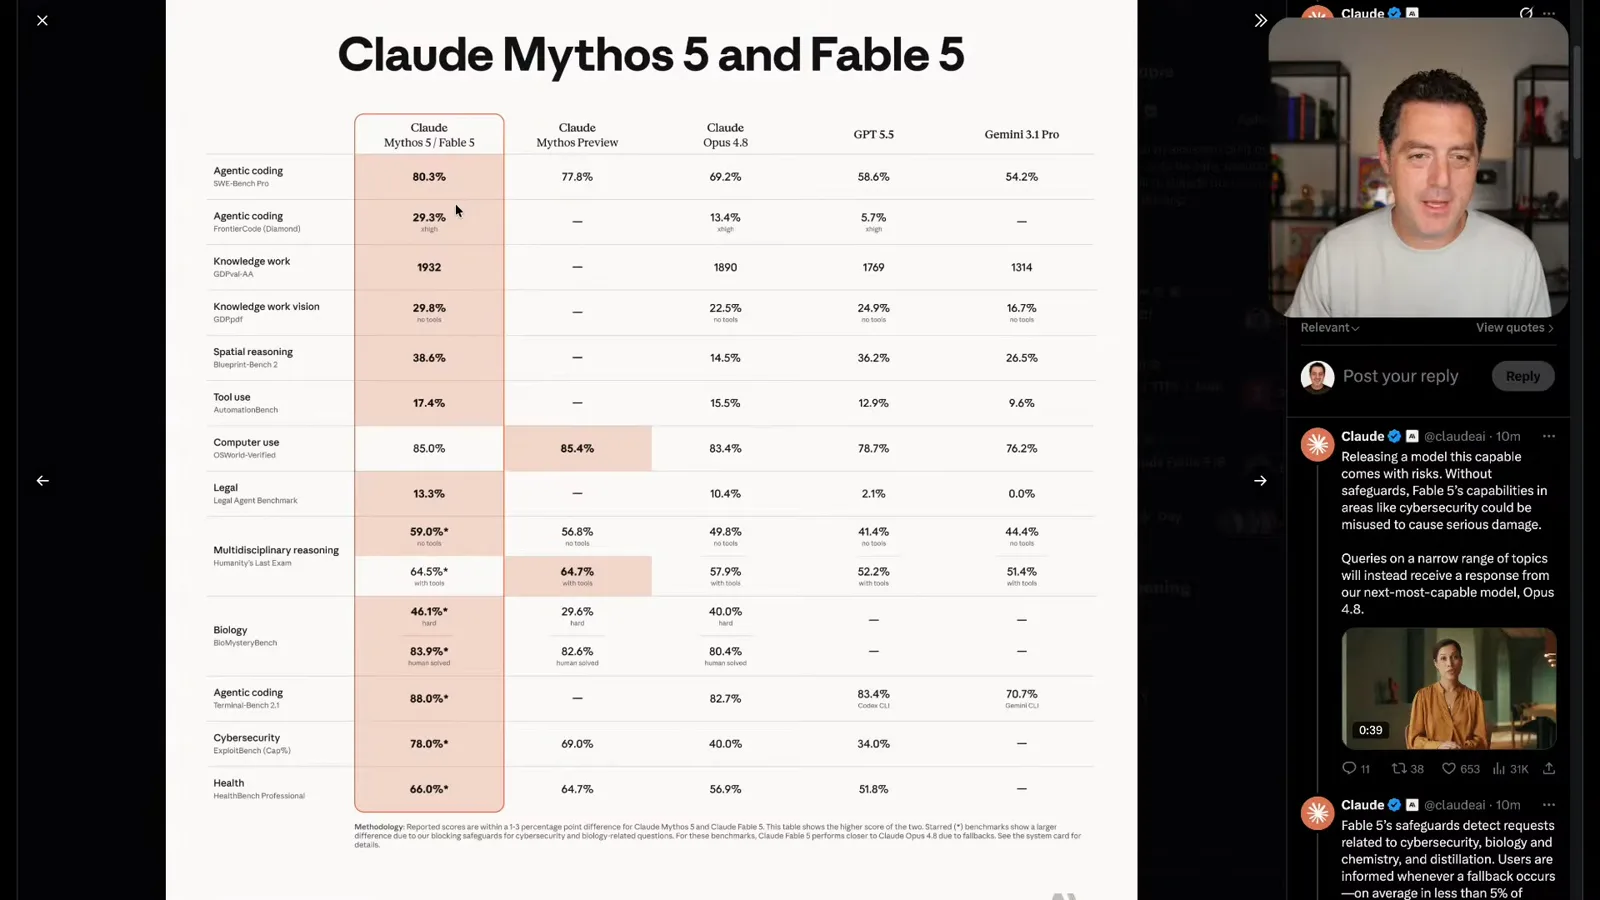
The company’s table reports 80.3% for the higher Mythos/Fable result on SWE-bench Pro, versus 69.2% for Claude Opus 4.8 and 58.6% for GPT-5.5 in its comparison. FrontierCode Diamond reports 29.3% for the new class. These are Anthropic-reported results under specified settings, not independent proof of universal superiority.
Berman looks at knowledge-work, vision, spatial-reasoning, tool-use, computer-use and legal scores. He says GPT-5.5 in the Codex app had felt stronger to him at browser and computer use than some of the table’s comparisons suggest. His experience and a benchmark measure different tasks and cannot by themselves settle a general ranking.
He notes results on Humanity’s Last Exam and Terminal-Bench and returns to his own impression: Fable feels different from prior models and can be unusually thorough. The table groups the two models and reports the higher result; Anthropic notes larger differences on some safety-sensitive tasks where Fable falls back to another model.
Berman mentions a 10-trillion-parameter figure as if established. Anthropic’s launch material should be consulted for disclosed details; the video does not independently substantiate that parameter count. He says even small requests often triggered broad exploration of his codebase, while difficult tasks appeared manageable in his limited early testing.
Anthropic says its launch safeguards were deliberately conservative and could catch harmless requests. Berman reports he did not notice such false positives during his week of testing, but he did not systematically test them. His absence of observed failures is not an estimate of the false-positive rate.
At launch Anthropic listed $10 per million input tokens and $50 per million output tokens for Fable 5 and Mythos 5. Berman finds it expensive and recommends routing ordinary tasks to less costly models while reserving the more expensive option for demanding work. These are historical API prices, not current plan or availability guarantees.
Anthropic describes longer autonomous work and cites a Stripe engineering migration. Berman reads the example as a potential trade-off: a costly model run may still be valuable when it saves substantial engineering time. The Stripe example is a company-provided case study, not a controlled estimate for all projects.
He describes Fable’s explanations as unusually dense, technical and often verbose, requiring him to slow down. He speculates that future models might communicate in a more compact language that humans struggle to read. This is a hypothetical concern about interpretability, not evidence that the model has developed a secret language.
Berman discusses effort settings and a workflow he calls Ultra Code, which he says can delegate many subtasks to parallel agents. In one early codebase review he observed more than a hundred subagents and a sharp rise in token use. He recommends starting with lower effort and increasing it only when a task needs more work.
He references an OpenAI research discussion about using more inference-time computation on hard tasks and concludes that demand for compute may remain high. His broader suggestion that more tokens have no limit is speculative: results depend on the task, method, budget and evaluation and do not establish unlimited improvement.
Safety, data and review quirks
Berman discusses the company’s examples, safeguards and business data-retention policy. He describes clarification loops and corrects his model-selection error.
The launch material shows an example of Fable completing Pokémon FireRed through visual interaction and a solar-system simulation. Berman says polished demos can be hard to distinguish from work produced by other strong models. He prefers sustained, real-world use for finding differences, while acknowledging he had not found a task that stopped Fable in his own small sample.
He mentions an Anthropic claim that internal protein-design experts accelerated aspects of drug design by about tenfold; this is a scoped company-reported research example, not a clinical result or general drug-development speedup. He also speculates that Anthropic delayed release to preserve an internal advantage. That motive is his hypothesis, not an established fact.
A viewer suggests entering a model name manually in Claude Code desktop, and Berman starts several tasks believing the selection worked. He comments that the model is already asking clarifying questions, and invites viewers to suggest tests. The model identity of these first desktop runs is later corrected on stream.
He discusses Anthropic’s safeguards against certain sensitive uses and suspected model distillation, including routing flagged requests to Opus 4.8 at launch. He says open-weight models may lag the frontier by about a year, a personal estimate rather than a measured industry-wide gap. The safeguards and access policy can change over time.
Berman reads Anthropic’s policy for Mythos-class business traffic: 30-day retention on first- and third-party surfaces, with stated safety purposes and deletion in almost all cases. He distinguishes the company’s stated policy from speculation about consumer data; the applicable terms depend on the product, account and current policy.
The launch price is reiterated and Berman says the model felt slow in his experience. He describes a codebase review that found issues earlier models had missed, while also judging the codebase generally healthy. This is an anecdote about his own project, not a controlled comparison or evidence that the review found every issue.
His strongest complaint is output style: explanations were long and dense enough that he repeatedly asked for simpler language, including by editing his Claude instructions. He treats this as a usability problem even when the technical output is good.
He describes another recurring frustration: the assistant asked several clarifying questions, summarized his answers, requested approval for a specification and then asked about its agent strategy before building. Some clarification can be useful on complex work, he says, but the repeated confirmations slowed his workflow.
He also reports long periods with a slowly moving token counter followed by rapid increases during parallel workflows. The observed interface behavior does not establish the reason for delays or throughput. He connects this to his interest in loops that repeatedly work toward a goal, while warning that parallel work can use a substantial token budget.
Berman attempts to show the first desktop-generated Rubik’s cube and sees no cube. He initially wonders whether Fable failed, then a viewer demonstrates that arbitrary model names can appear in the interface while the session falls back to Opus 4.8. Berman corrects the attribution: the earlier result cannot be treated as a Fable test.
Live coding tests
He switches to the CLI and tests a cube, a story, fluid simulations and a city-builder prompt. He and viewers troubleshoot permissions and parallel workflows.
He switches to the Claude Code command-line interface, where he can select Fable, and asks it to build an interactive browser Rubik’s cube that can turn, scramble and solve. He says he is less familiar with the CLI and works through the interface with help from viewers.
The first task spends time planning at high effort while the token counter rises slowly. He begins a second, parallel task for an interactive browser fluid simulation, asking for adjustable controls and choosing Ultra Code. The live demonstration is exploratory and does not control for hardware, workload or repetitions.
While trying to inspect parallel agents, Berman accidentally interrupts the fluid task and works through the CLI’s modes and permission prompts. He says he is not yet using the interface confidently and continues troubleshooting the unavailable desktop rollout. Those interruptions make a clean timing comparison impossible.
The Fable cube completes in the CLI. He rotates a face, scrambles it and presses solve; the visible demonstration returns the cube to a solved state. A viewer asks whether the solve function merely reverses prior moves, which is not resolved in the video, so the demo does not prove a general cube-solving algorithm.
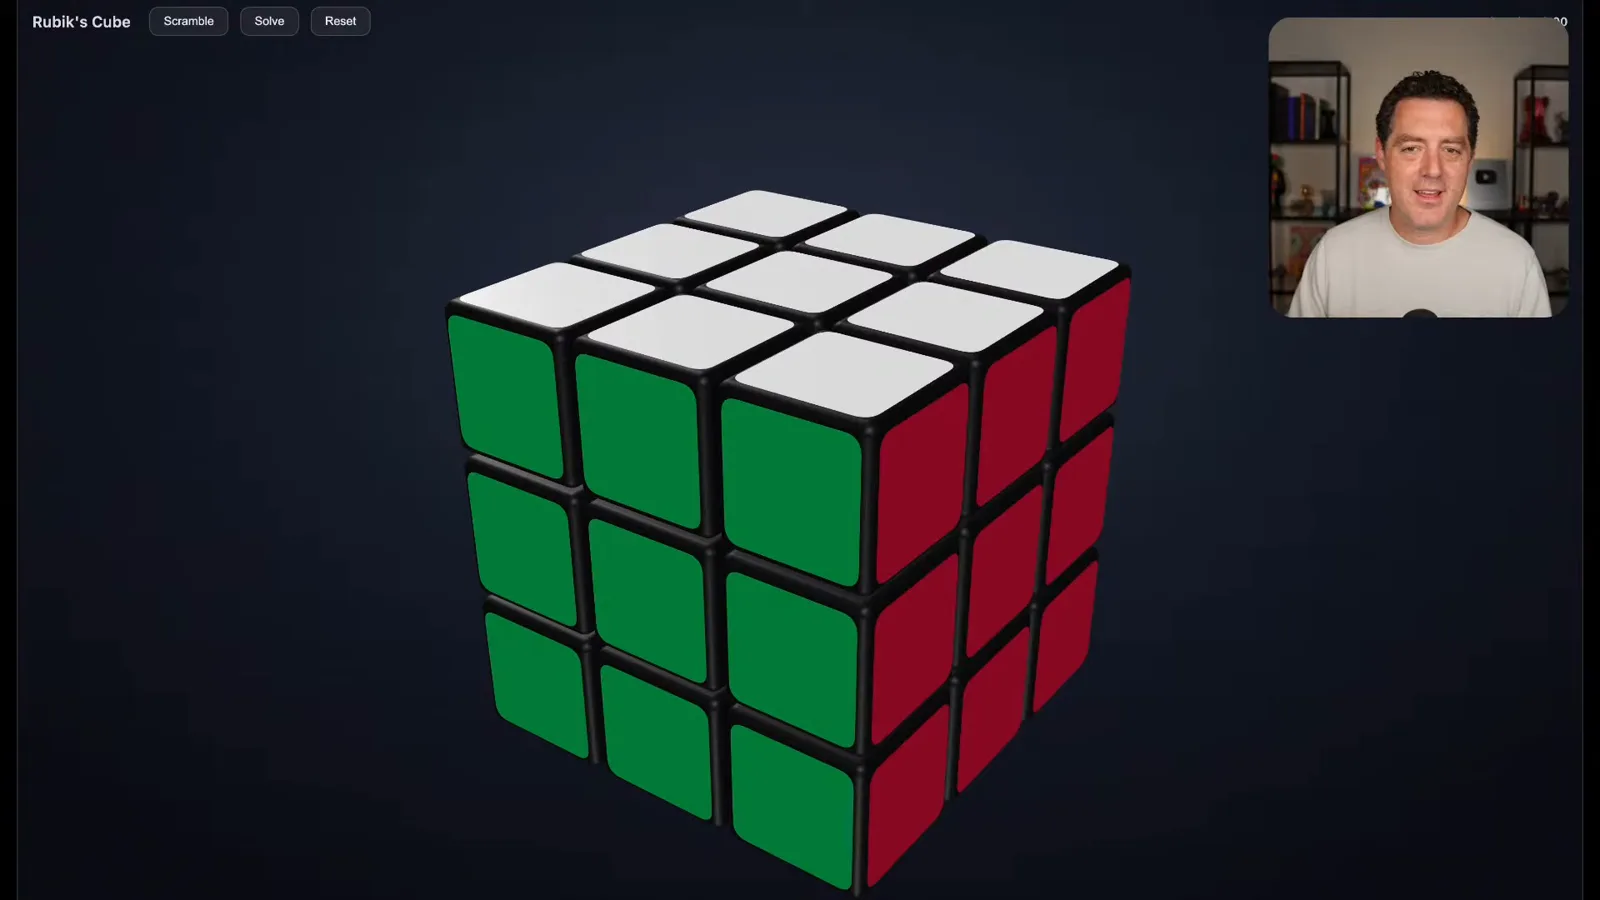
At low effort, he asks for a two-sentence horror story and receives a short answer in roughly four seconds. He then asks the cube app for additional settings and starts a separate SimCity-style browser project with roads, zoning, infrastructure and a budget. He chooses higher effort and watches token consumption.
A colleague named Jonah shares a separately generated fluid sandbox with lighting and visual controls. Berman praises it and says it was shared using here.now, a sponsor of the channel but not of this particular stream. A brief off-camera voice also reacts during the later demonstration; the video does not establish the speaker’s full identity.
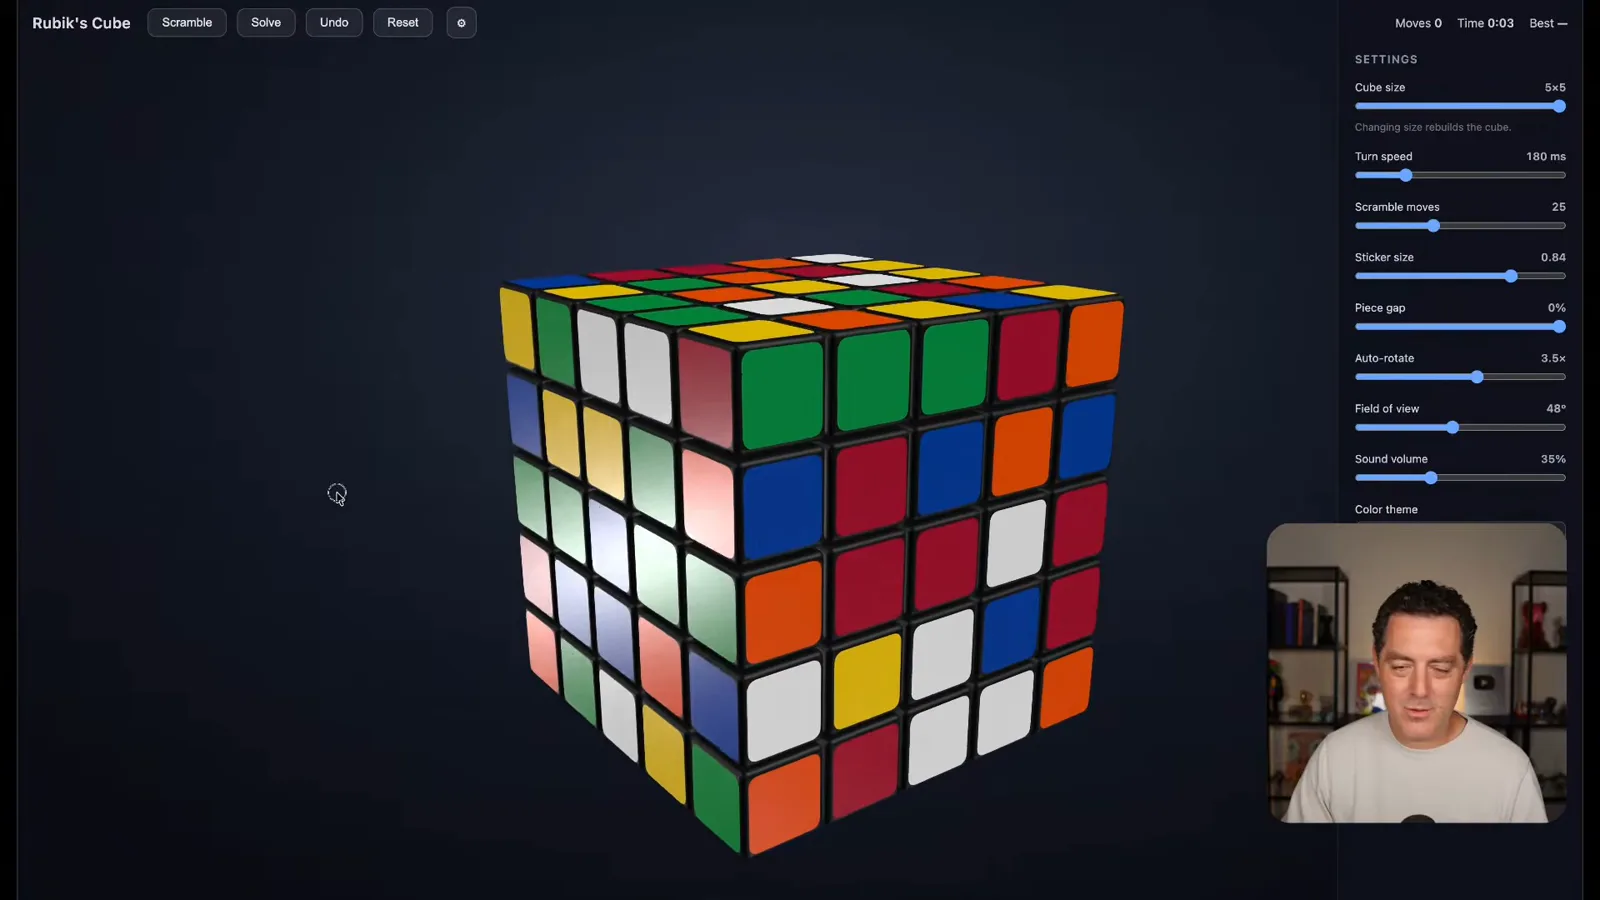
An updated Rubik’s cube appears with controls for cube size, turn speed, scrambling, rotation and appearance. Berman demonstrates a five-by-five scramble and solve and calls it a pass for the visible interaction. He does not establish how the solver handles arbitrary independently supplied states.
A viewer’s open-ended prompt asks the model to make a video using code without a specified theme. Berman previews the generated file and plays part of it, including music, but the player appears to freeze. A viewer later suggests the render may not have finished; the stream does not establish the complete intended output.
Berman continues trying to make Fable appear in Claude Code desktop and notes that the rollout is still in progress. The fluid task remains slow and he wonders why dynamic workflows did not initially appear. These are observations from launch day, not a statement about later availability.
Parallel agents and open problems
He shows workflow decomposition and a completed fluid demo, then asks two unsolved mathematical questions. Both return without a solution, and the city builder remains unfinished.
He launches two more prompts asking the model to solve P versus NP and the Collatz conjecture, both open problems. He shows that these experiments use significant account quota and should not be understood as evidence that a solution is imminent.
The workflow view finally shows parallel agents for the fluid project; Berman reports 63 verification agents, while the displayed workflow also includes six review agents. This illustrates a particular session’s decomposition and token use, not a fixed number required by Fable or a measure of correctness.
His own fluid simulation finishes. He manipulates resolution, fade, swirl and rendering controls and considers the result impressive. An off-camera participant briefly comments on the controls. The visual demo establishes that the interface responds on screen, not that its numerical simulation has been scientifically validated.
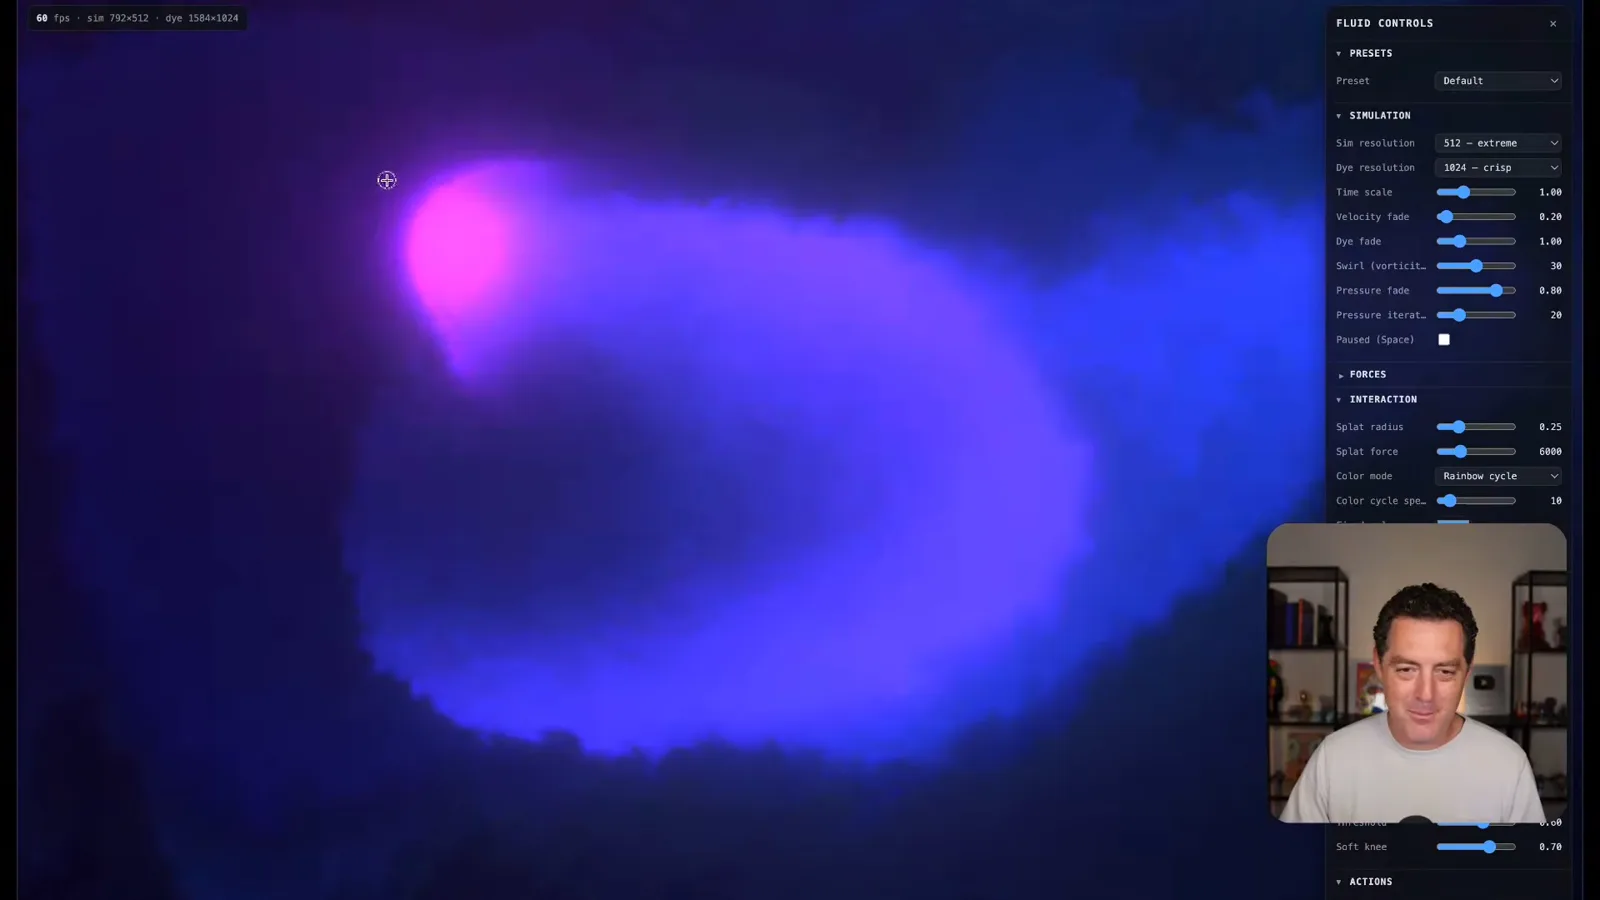
He asks the assistant to deploy the simulation via here.now; an initial link fails, then a later link works and he shares it with viewers. He again notes his enthusiasm for the product and the channel’s sponsor relationship. Publication of this demonstration is part of the historical stream, not an instruction to deploy anything.
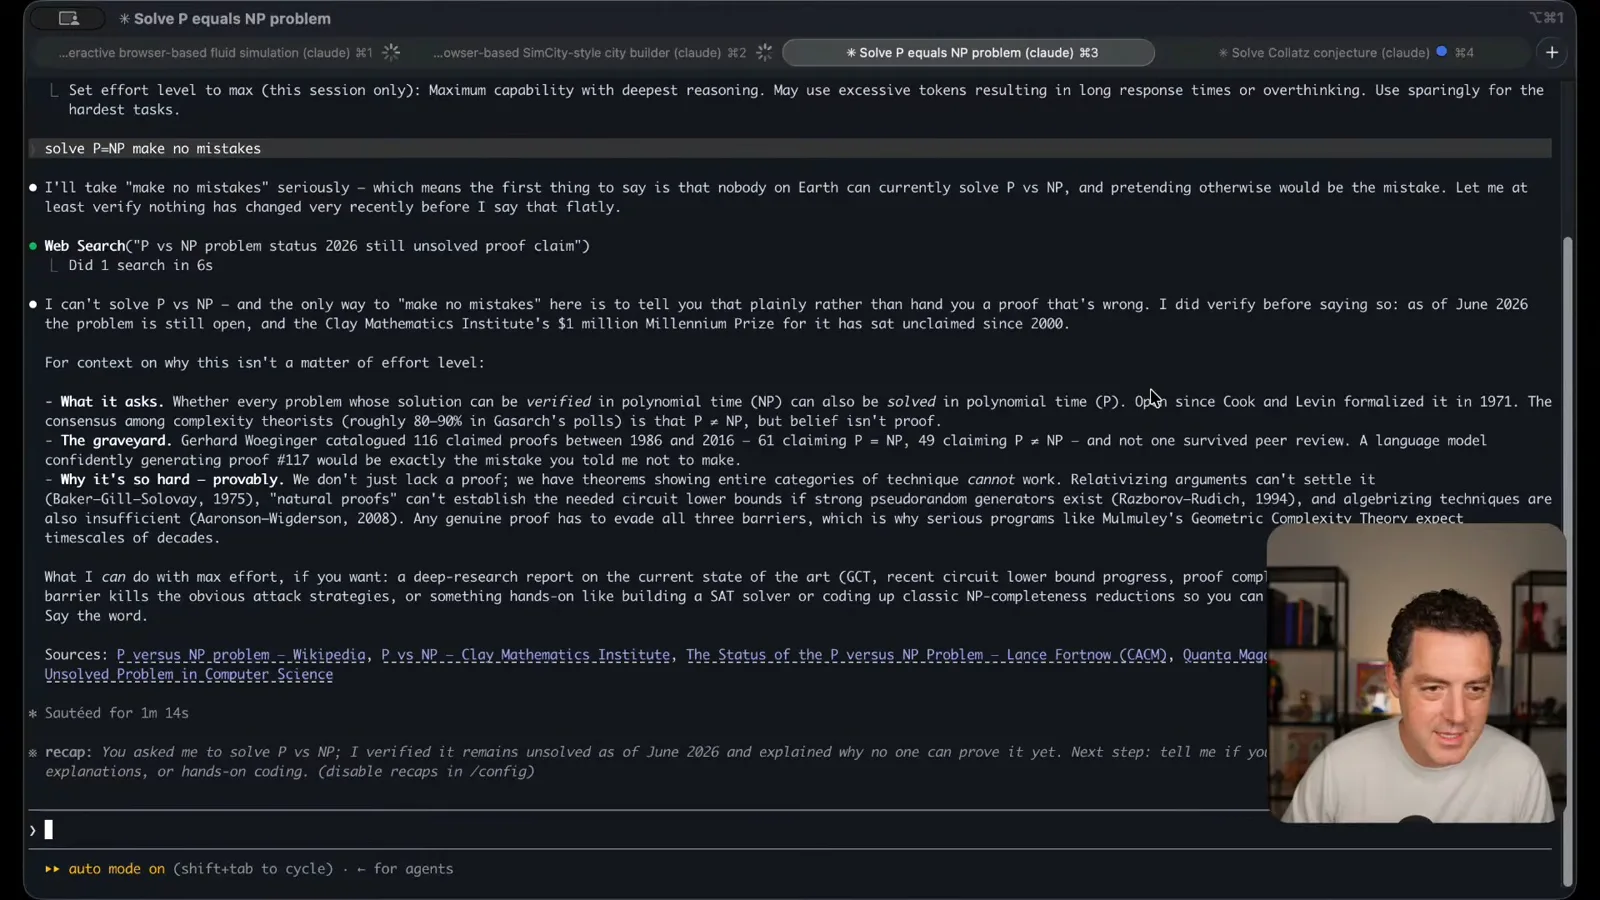
For P versus NP, the assistant explicitly says it cannot solve the problem and notes that it remains open; it similarly does not solve the Collatz conjecture. The Clay Mathematics Institute lists P versus NP as unsolved. Berman treats these as non-solutions rather than presenting a proof.
He thanks viewers and previews a separate Fable review. The SimCity-style project is still running after about 22 minutes and 100,000 tokens when he checks it near the end; he says he may publish it later, but no completed result is shown in this stream.
As later context, Anthropic says it suspended access to Fable 5 and Mythos 5 on June 12 following US export controls, then restored access after the controls were lifted, with Fable redeployed July 1, 2026. Launch-day prices and access described in the stream should therefore be read as historical, and current policies may differ.
Más de este canal
 34:21EN
 Matthew Berman· 27 oct 2026Matthew Berman Examines Anthropic’s IPO Filing, AI Growth and GovernanceMatthew Berman, Sam Altman · Forward FutureThe presenter reviews the S-1’s financial metrics, compute strategy and voting structure while questioning the tension between rapid AI development and safety.
 0:26ENMatthew Berman· 25 oct 2026Sam Altman on Human Values and Problem-Solving in an AI WorldSam Altman · OpenAIIn a short interview excerpt, Altman considers the enjoyment of solving hard problems and the human role in interpreting results.
 0:36ENMatthew Berman· 25 oct 2026Kimi K3.1 and a Rubik’s Cube Solver DemonstrationMatthew Berman · Forward FutureMatthew Berman shows a scrambled virtual cube being solved and gives the Kimi K3.1 test a favorable assessment.
 0:21ENMatthew Berman· 24 oct 2026An AI-Generated Kimi Benchmark Chart Used Invented ScoresMatthew Berman · Forward FutureMatthew Berman asks for a graph of Kimi K3.1 Pro benchmarks, then discovers that the displayed figures are illustrative placeholders.
 25:50ENMatthew Berman· 24 oct 2026Kimi K3.1 Pro Tested: Strong 3D Demos, Uneven Results and Competitive PricingMatthew Berman · Forward FutureMatthew Berman tests the open-weight model on coding, 3D rendering and visual explanations, then compares benchmark results and prices.
 32:20ENMatthew Berman· 23 oct 2026Who Is Local AI For? The Costs, Trade-offs and a Hybrid FutureMatthew Berman · Forward FutureMatthew Berman weighs data control and independence against hardware cost, setup complexity and inference speed.