En 30 segundos
Matthew Berman reviews AI announcements from November 2024, including Mistral’s Le Chat and Pixtral Large, Gemini’s Chatbot Arena standing, agent tools and Perplexity shopping. He discusses reports on nuclear safeguards, GPU infrastructure and a study of medical diagnostic reasoning. The article distinguishes historical announcements and limited evaluations from broader claims.
- 1Le Chat expandsMistral demonstrated web search, image generation, custom agents and canvas editing.
- 2Gemini in Chatbot ArenaA November 2024 leaderboard snapshot reflected user preference votes rather than a universal ranking.
- 3AG2 correctionAG2 is a fork of AutoGen, not a Microsoft rename of its project.
- 4Medical study limitsA randomized trial of 50 physicians used case vignettes; chatbot access did not significantly improve the primary outcome.
Conclusiones
- Mistral added search, image generation, agent configuration and canvas features to Le Chat in 2024.
- Pixtral Large was released with open weights under a research license, with commercial licensing separate.
- Chatbot Arena rankings reflect user preferences on a particular sample of prompts and time.
- The 50-physician trial did not find a significant improvement from providing GPT-4 access, and its model-only comparison was exploratory.
- Nuclear safety testing and a statement about human control do not prove technical safeguards are infallible.
Lee el texto editado por capítulos
Mistral’s assistant and vision model
Berman demonstrates Le Chat features and discusses Pixtral Large. Its release and license are placed in their 2024 context.
Mistral has added several features to Le Chat, its conversational assistant. I show web search with citations using a question about UFC 309, followed by image generation powered by Black Forest Labs' Flux Pro. At the time of this November 2024 video, I describe the features as free; availability and pricing can change.
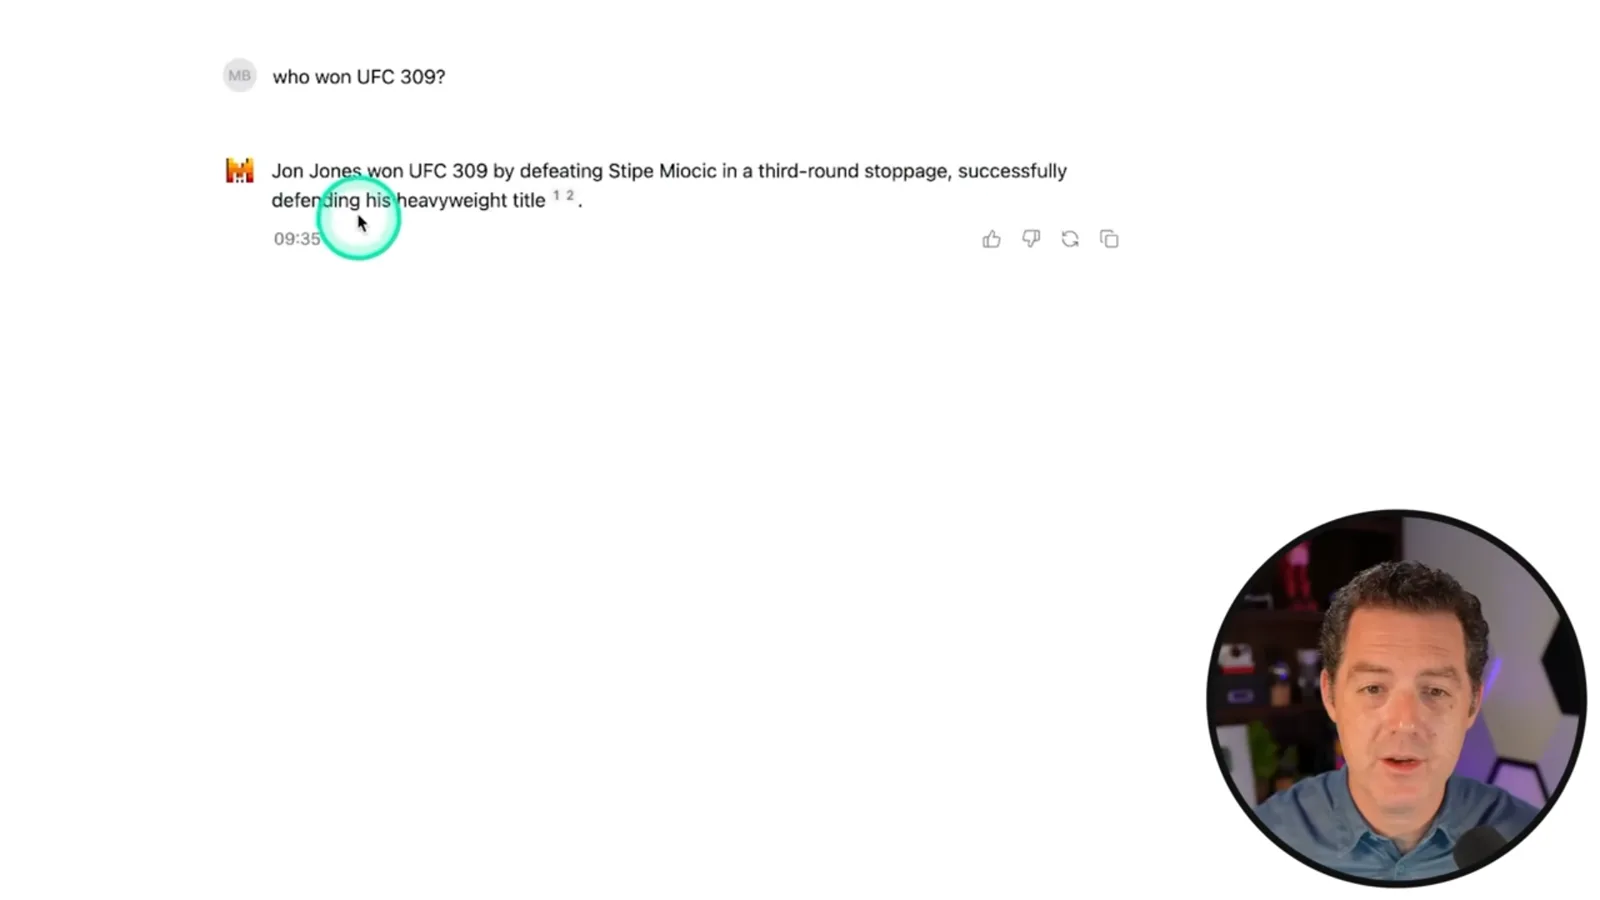
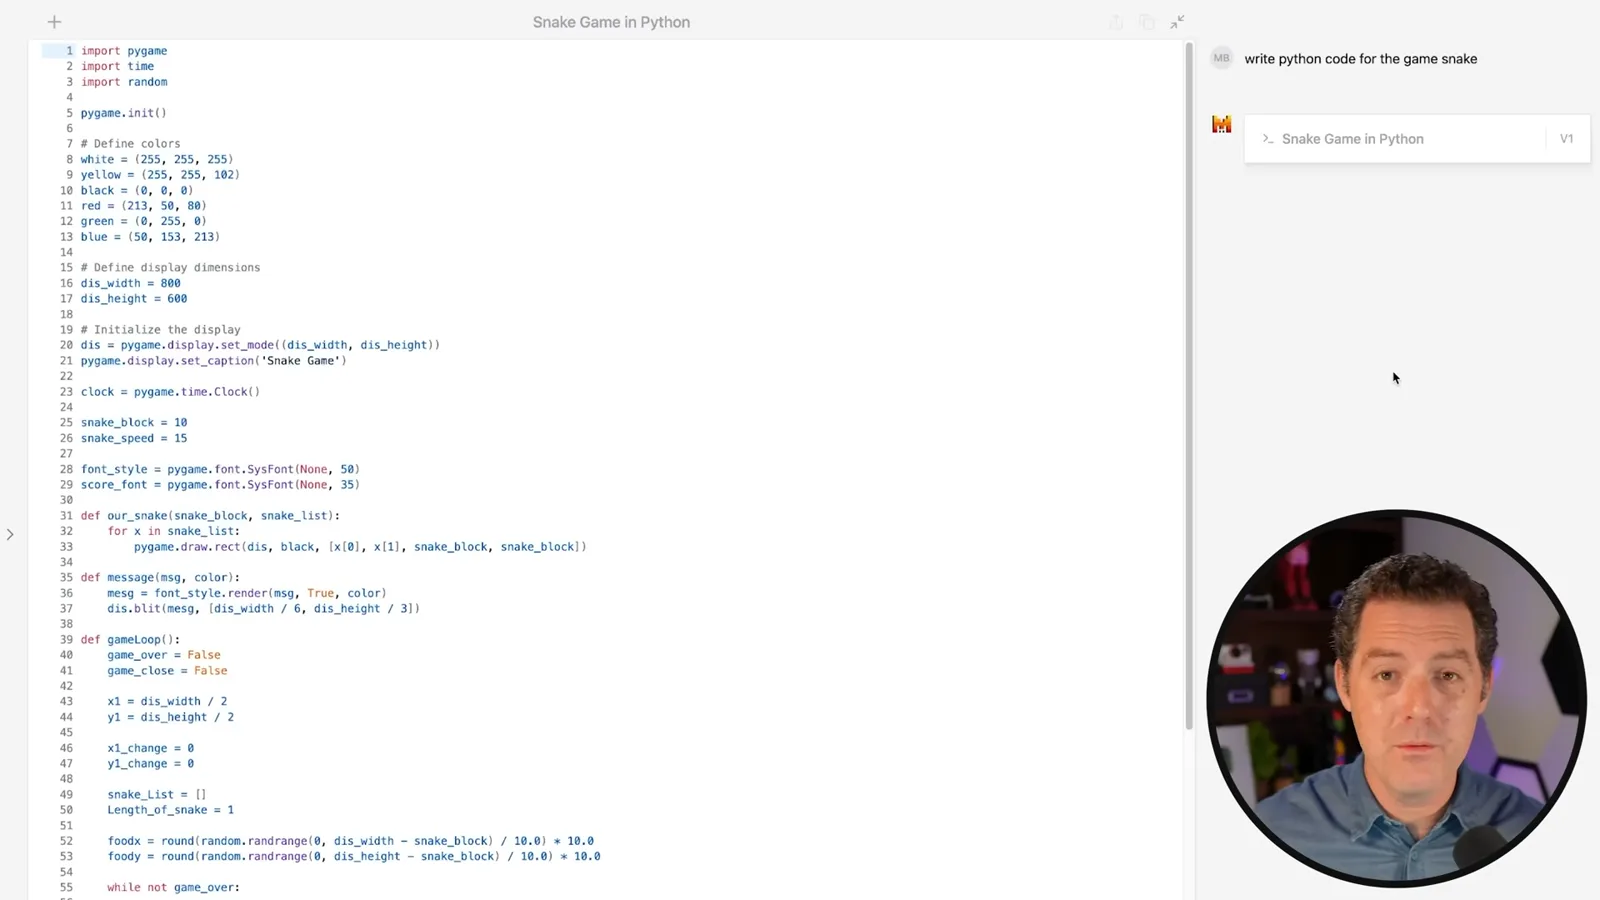
Le Chat also lets users create and mention custom agents. In the interface I show, you can select a model, add instructions and examples, adjust temperature, and test the agent before invoking it in a conversation. Canvas opens code or writing alongside chat; I ask for a Python Snake game, change its colors inline, and inspect differences between versions.
Mistral also released Pixtral Large, a vision model that can work with images and PDFs. I show it describing an image of a llama and mention my positive experience with a smaller Pixtral model. Mistral described Pixtral Large as a 124-billion-parameter open-weights model; its November 2024 release used a research license for self-deployment, with commercial use requiring a separate license. Open weights do not by themselves mean unrestricted use.
Rankings, scaling and desktop tools
He discusses Gemini’s preference ranking and debates claims that AI progress is slowing. He also reviews ChatGPT desktop integration and AG2.
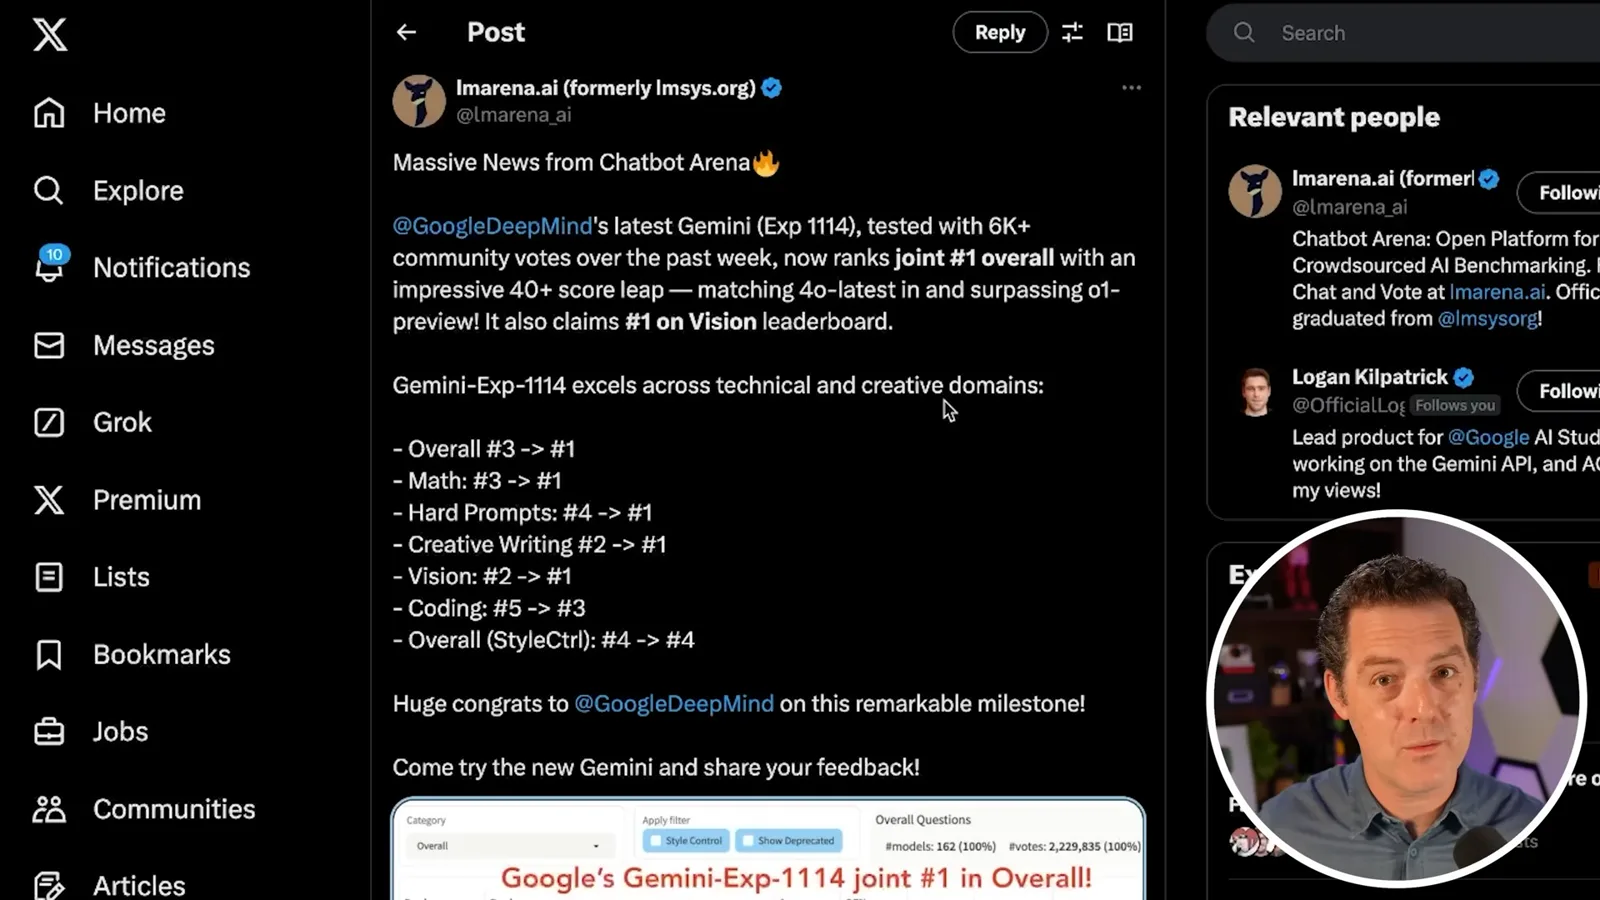
The Chatbot Arena leaderboard then placed Gemini Experimental 1114 around the top alongside GPT-4o, based on community preference votes. The snapshot also shows movement in math, hard prompts, creative writing and vision. I contrast this with conventional benchmark scores, but the arena is itself an evaluation: votes reflect the participating users, prompts and methodology, and a small ranking difference should not be treated as proof of universal superiority.
Reports have suggested that leading AI companies may be hitting a wall in model improvement. Sam Altman disagreed, and I share his skepticism about a hard limit: advances in algorithms, test-time training and additional computation during inference provide other ways to improve systems. That is my assessment of the trend, not proof that scaling will continue indefinitely.
OpenAI's ChatGPT desktop app was adding beta integration with VS Code, Xcode, Terminal and iTerm2, allowing it to read relevant application content without constant copy and paste. I see that as a possible step toward broader desktop control, and speculate that an AI-native browser with agents might come first. These are predictions, not features established by this announcement.
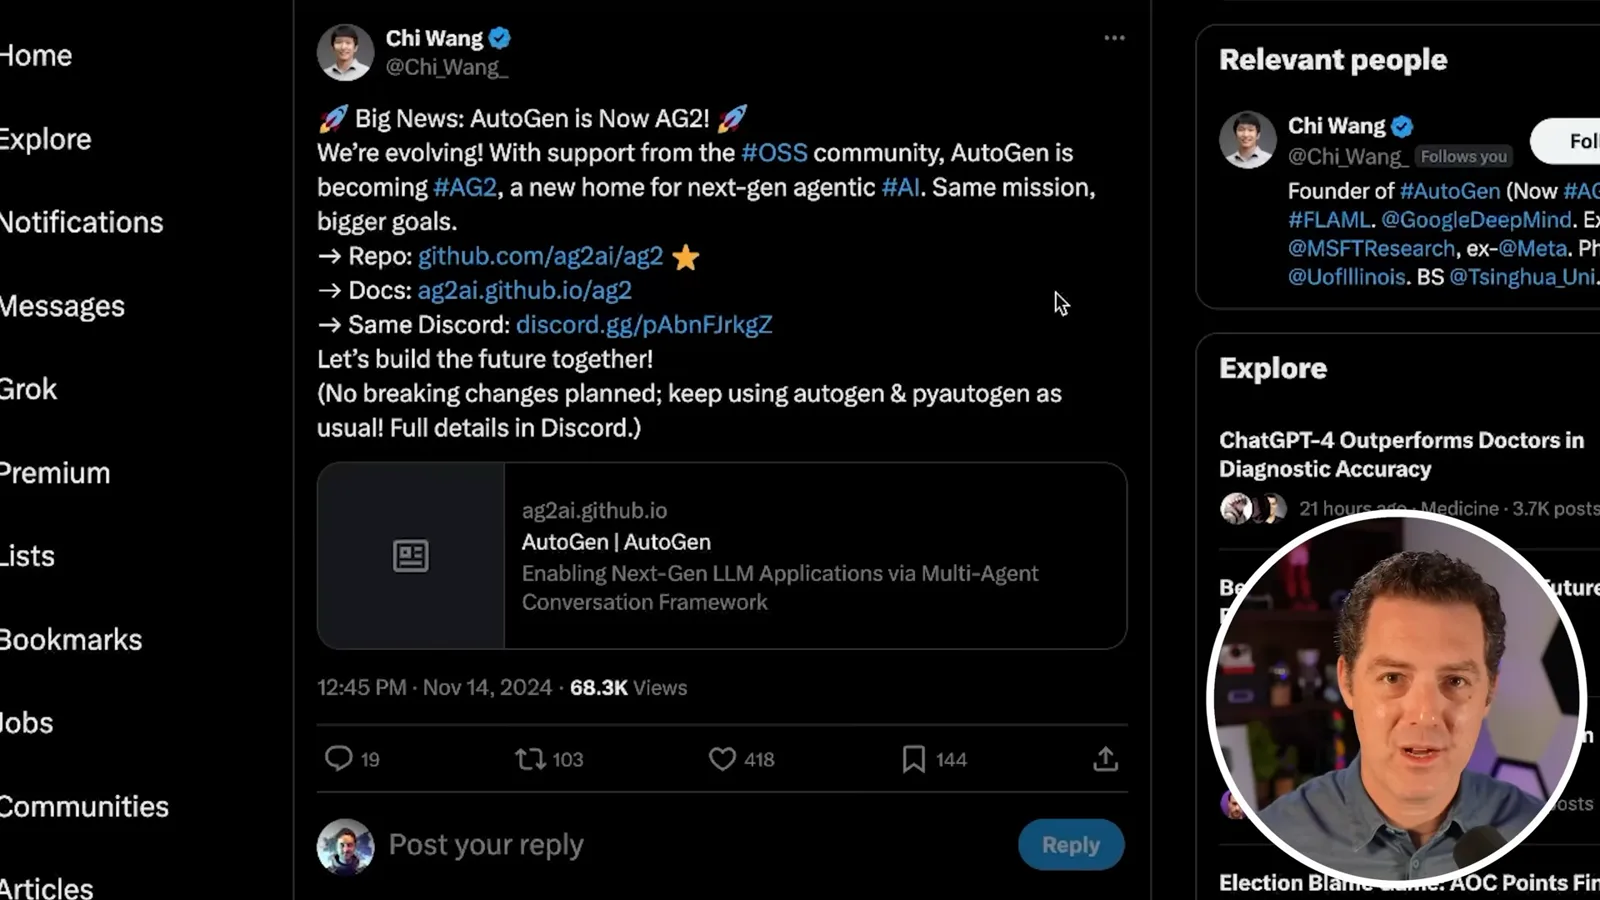
Chi Wang announced AG2 as a new home for agentic AI based on AutoGen. A correction in this video's description clarifies that AG2 is a fork of AutoGen and is not Microsoft's AutoGen project. It remains open source; the announcement should not be read as Microsoft simply renaming its project.
Nuclear safety and compute
Reports cover Anthropic’s nuclear red-teaming and xAI fundraising. Berman considers human control over nuclear decisions.
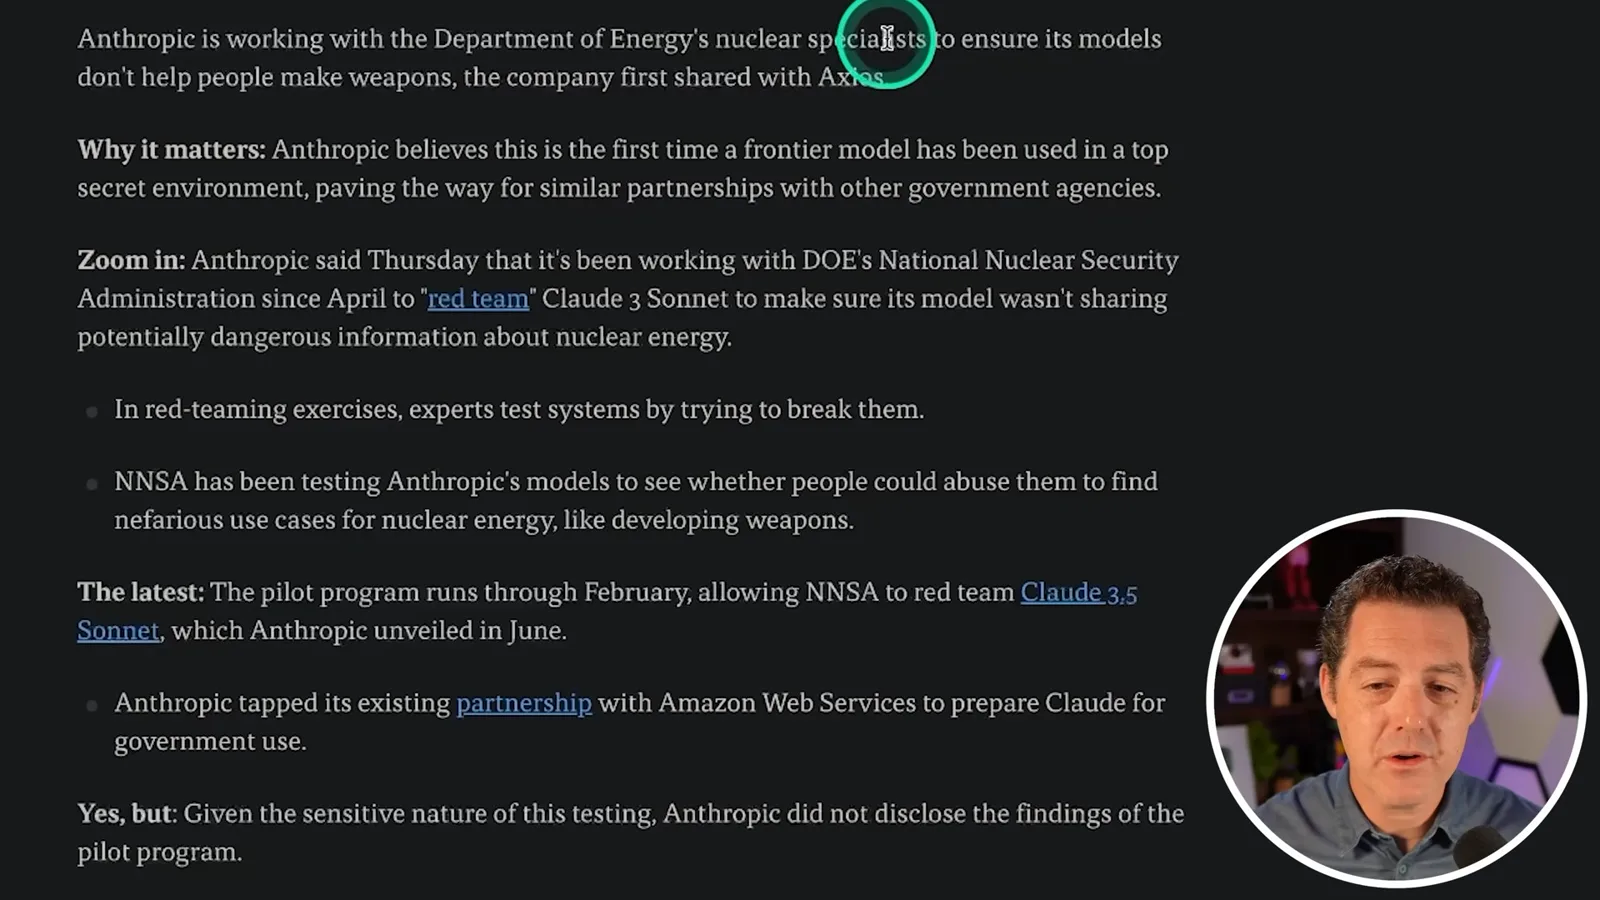
Anthropic said it was working with Department of Energy nuclear specialists and the National Nuclear Security Administration to red-team its models for potentially dangerous nuclear information. The reported pilot tested whether models could be misused to assist weapons development; the cited report did not disclose the findings. Such tests assess risk and do not establish that a model leaked classified secrets or is completely safe.
A report said xAI was seeking up to $6 billion in funding, with plans connected to purchasing additional Nvidia GPUs, at a reported valuation of $50 billion. These figures were fundraising reports at the time rather than proof that every planned purchase had occurred. I was eager to see whether additional compute would translate into a stronger Grok model.
A report on President Biden and President Xi's 2024 meeting said the leaders affirmed the need to maintain human control over decisions to use nuclear weapons. I welcome that principle and worry about relying on systems that can hallucinate or be manipulated. The statement is a political expression of intent, not evidence of a verified technical enforcement mechanism or a comprehensive arms-control treaty.
Medical AI, hardware and shopping
Berman discusses a diagnostic reasoning trial and reported Blackwell server issues. He closes with Perplexity’s shopping launch.
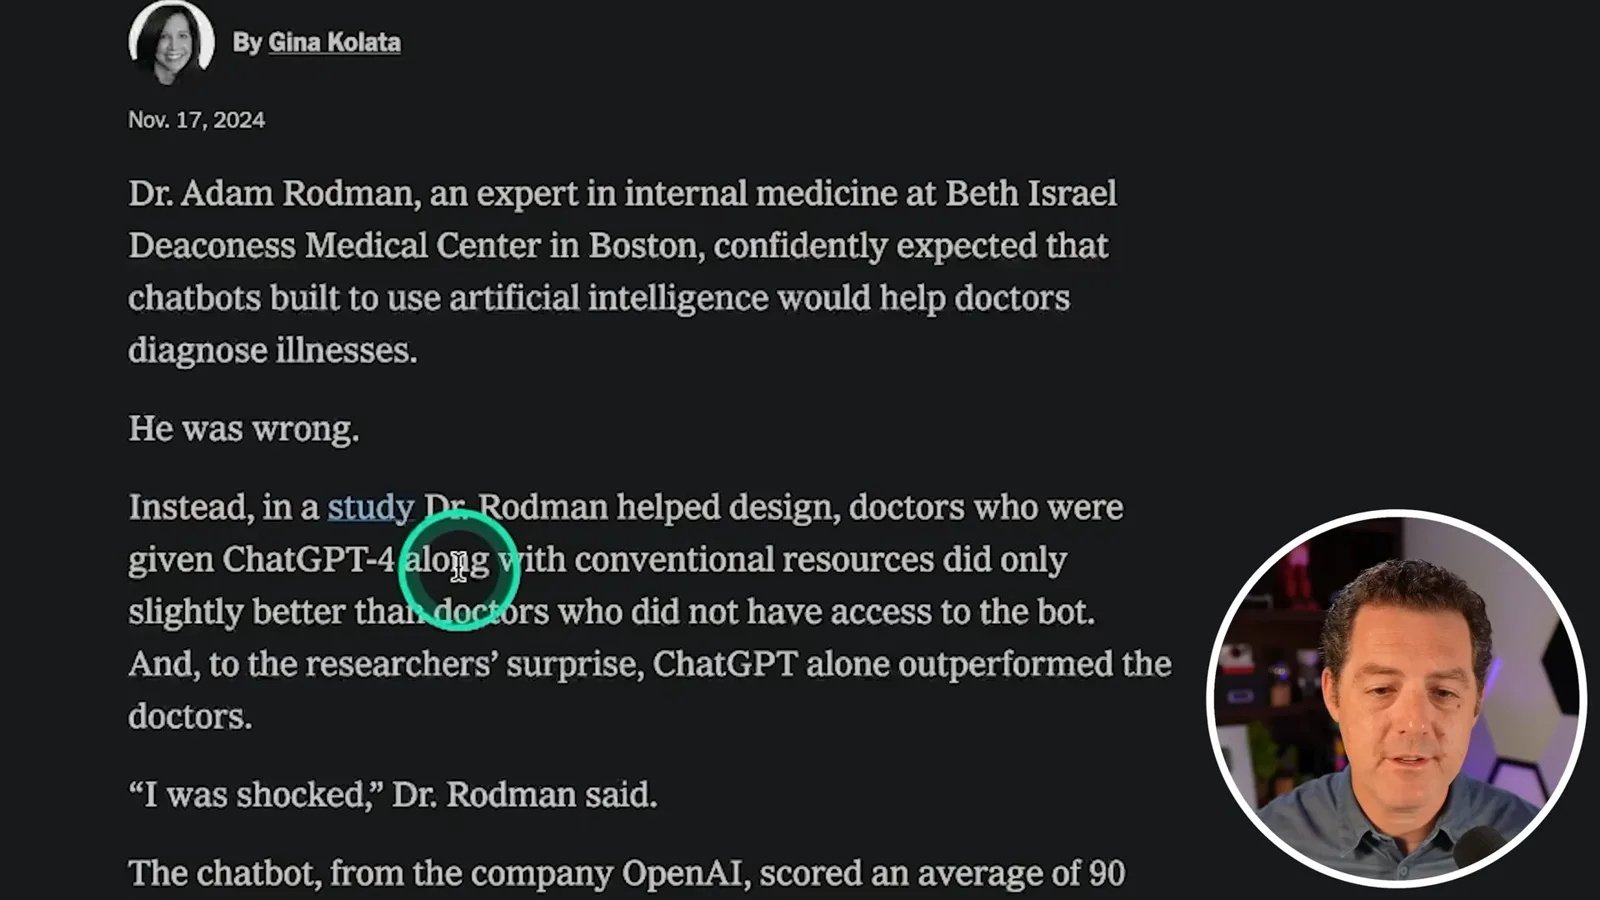
I discuss a small study comparing physicians with and without GPT-4 and GPT-4 alone on diagnostic reasoning from clinical case vignettes. The original randomized trial involved 50 physicians; median reasoning scores were 76% with model access and 74% with conventional resources, a difference that was not statistically significant. The model-alone comparison was exploratory and scored higher on that rubric. The video reports approximately 90% for the chatbot, but this is not evidence it consistently outperforms doctors in live patient care.
I am optimistic about AI helping clinicians work through cases, potentially with a doctor reviewing the final decision. But case vignettes and a small study do not capture the full clinical workflow, and a model's errors still matter. My expectation of further improvement is a forecast, not a guarantee that each future model will be better in every medical situation.
Reuters reported, citing The Information, that Nvidia's Blackwell systems faced overheating concerns when GPUs were connected in high-density racks, prompting design changes and customer concern over deployment schedules. This was a reported engineering issue in November 2024, not a finding that all Blackwell installations failed or a statement about current hardware.
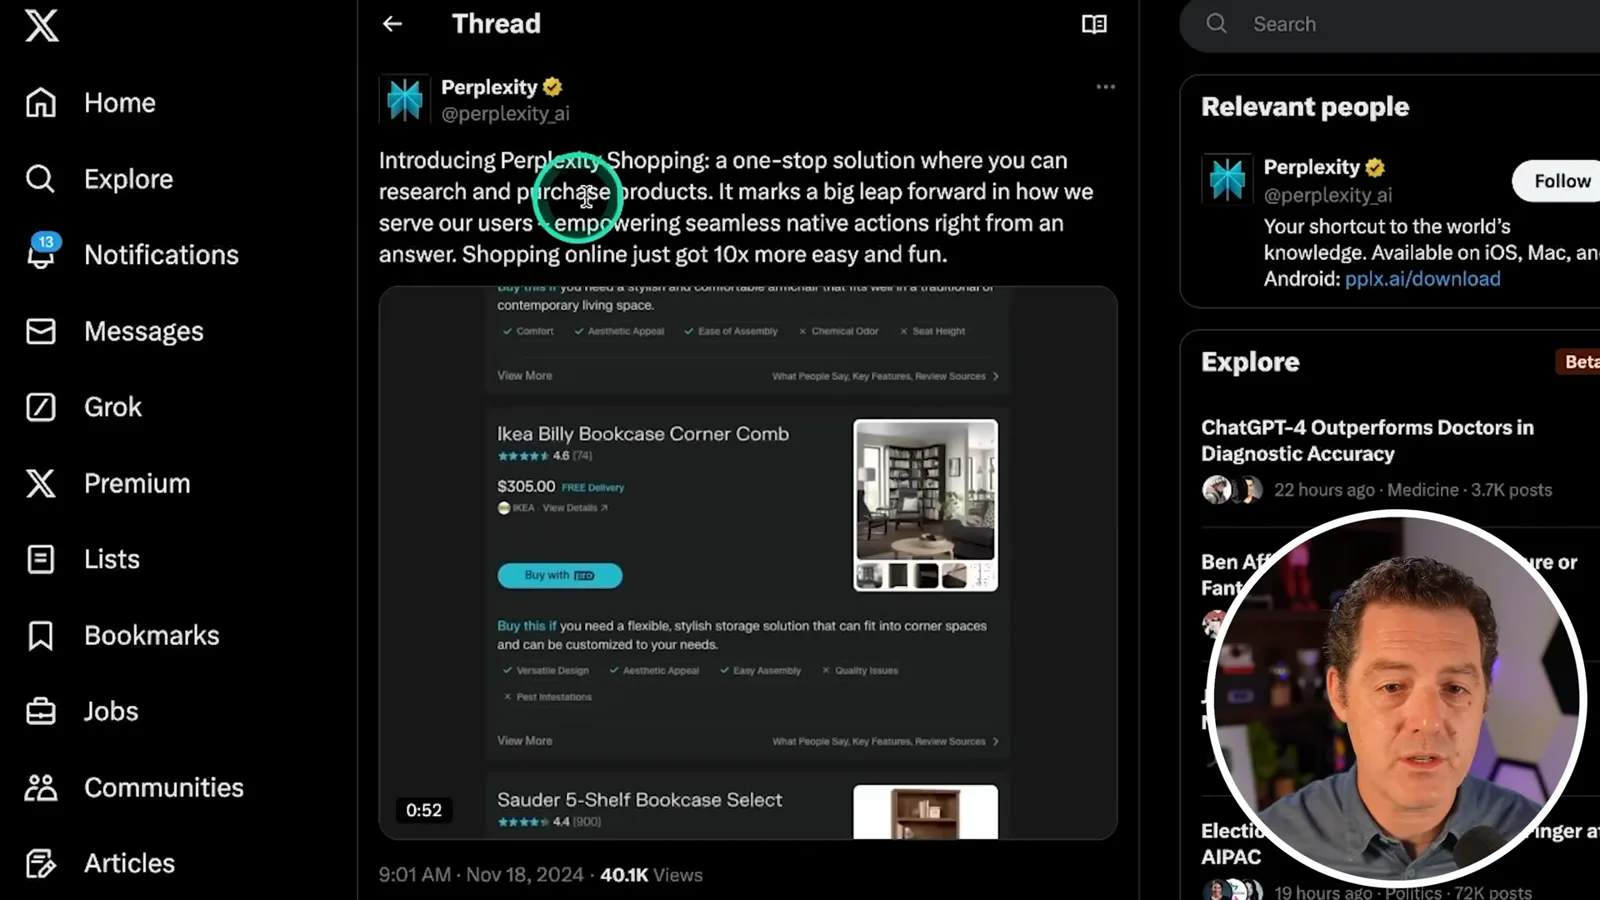
Perplexity announced shopping features for researching and buying products, including a one-click checkout and a merchant program. I see native transactions as a potential way to reduce friction and monetize beyond subscriptions, and I plan to try them. I also describe relying heavily on Perplexity and ChatGPT rather than Google for my own searches; that is my usage, not a market-wide measurement.
Más de este canal
 34:21EN
 Matthew Berman· 27 oct 2026Matthew Berman Examines Anthropic’s IPO Filing, AI Growth and GovernanceMatthew Berman, Sam Altman · Forward FutureThe presenter reviews the S-1’s financial metrics, compute strategy and voting structure while questioning the tension between rapid AI development and safety.
 0:36ENMatthew Berman· 25 oct 2026Kimi K3.1 and a Rubik’s Cube Solver DemonstrationMatthew Berman · Forward FutureMatthew Berman shows a scrambled virtual cube being solved and gives the Kimi K3.1 test a favorable assessment.
 25:50ENMatthew Berman· 24 oct 2026Kimi K3.1 Pro Tested: Strong 3D Demos, Uneven Results and Competitive PricingMatthew Berman · Forward FutureMatthew Berman tests the open-weight model on coding, 3D rendering and visual explanations, then compares benchmark results and prices.
 32:20ENMatthew Berman· 23 oct 2026Who Is Local AI For? The Costs, Trade-offs and a Hybrid FutureMatthew Berman · Forward FutureMatthew Berman weighs data control and independence against hardware cost, setup complexity and inference speed.
 1:03:37ENMatthew Berman· 23 oct 2026Matthew Berman’s Team Tests Kimi K3.1 on Animation, Games, and ChartsMatthew Berman, Alex, Brian · Forward FutureA live team AMA turns into an informal test of Kimi K3.1, from personal-agent workflows to motion graphics, a browser game, and a benchmark chart.
 0:53ENMatthew Berman· 22 oct 2026Sam Altman on AI and the Discovery of New KnowledgeSam Altman · OpenAIAltman expects progress in mathematical discovery to extend to biology, materials and energy.