En 30 segundos
Nathan Lambert reviews the language-model and machine-learning concepts used throughout his post-training course. He connects PyTorch tensor operations and decoding to probability, reward modeling and reinforcement learning.
- 1The language-model headA head converts hidden states to vocabulary scores and then token probabilities.
- 2Sequence probabilitiesShift labels, gather token log probabilities and sum the completion positions.
- 3Three masksCausal, padding and completion masks control different parts of computation.
- 4Mid-trainingAn intermediate stage prepares the pretrained model for subsequent post-training.
- 5KL and entropyKL is a directional divergence related to entropy and cross-entropy.
Conclusiones
- A sequence probability factors into next-token probabilities, whose logs add.
- Causal, padding and completion masks serve different purposes.
- Pretraining, mid-training and supervised fine-tuning are related stages of model development.
- KL divergence is directional and is not a mathematical distance.
- Post-training combines sampling, objectives and rewards to shape model behavior.
Lee el texto editado por capítulos
Language-model prerequisites
Lambert reviews token distributions, model heads, softmax and log probabilities. He explains why machine-learning and PyTorch basics help.
What should you know before reading the RLHF book? The course is aimed broadly at master’s and PhD students, but motivated readers can work through it. This lecture reviews the machine-learning and probability concepts that recur in language-model post-training.
Some familiarity with machine learning and PyTorch—losses, backpropagation and gradients—is a useful prerequisite. We will look at language modeling, optimization, KL divergence and reinforcement learning as a starting point.
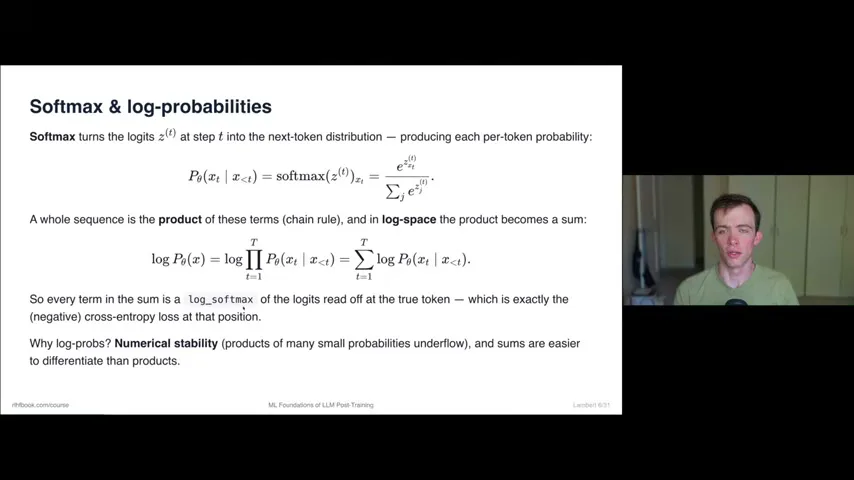
A language model represents a probability distribution over token sequences. At each step it predicts a distribution for the next token. The probability of a sequence is the product of its conditional token probabilities, and training encourages the model to assign more probability to the observed next token.
Modern language models are commonly decoder-only transformers built with self-attention. I recommend learning the history and significance of the transformer, even though that architectural history is outside this course.
The language-model head maps a hidden-state vector to logits: one score for each vocabulary token. Softmax converts those scores into a probability distribution from which a token can be selected. Other post-training architectures add different heads, such as a scalar head for a reward or value estimate.
Softmax exponentiates scores and normalizes them so the probabilities sum to one. A sequence probability is a product, but its log probability is a sum of token log probabilities. This is convenient for differentiation and avoids numerical underflow from multiplying many small probabilities.
Training examples and decoding
A PyTorch walkthrough aligns next-token labels and applies masks. Decoding methods choose tokens from model distributions.
A typical PyTorch example begins with input token IDs in a batch of size B and sequence length L. A forward pass returns logits with dimensions for batch, sequence position and vocabulary. The code then aligns each position with the true next token.
To build next-token labels, drop the final logit position and shift the input labels by one token. Apply log-softmax, gather the log probability assigned to each actual next token, and sum the relevant terms to get sequence log probabilities.
In many post-training examples a completion mask selects the model’s answer for the loss rather than training on prompt tokens. Understanding these tensor shapes, shifts and masks makes post-training code much less intimidating.
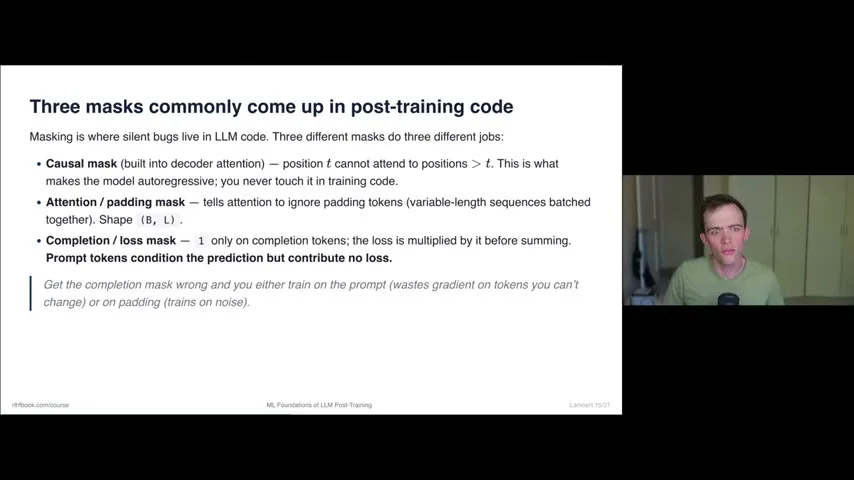
Three masks serve distinct roles. A causal mask prevents attention to future tokens. A padding or attention mask identifies padding in batched sequences. A completion or loss mask selects the answer tokens that contribute to the training objective.
For decoding, greedy selection takes the most likely token at each step. Temperature sampling rescales logits before sampling: higher temperatures generally make choices more varied, while lower temperatures concentrate probability on high-scoring tokens. Beam search and truncated sampling provide other choices.
Optimization and model stages
Cross-entropy and gradient descent train language models. Pretraining, mid-training and supervised fine-tuning contribute different stages.
Cross-entropy compares a predicted distribution with a target. For a single correct next-token label, minimizing negative log likelihood increases the probability assigned to that token. Lambert notes the relationship between this objective and the log-probability calculations shown earlier.
Gradient-based optimization updates model parameters, with a learning rate controlling update size. Lambert says Adam remains widely used in post-training, while other optimizers also exist. The focus of this course is the training recipe rather than optimizer details.
Pretraining learns next-token prediction from large collections of text and code. Mid-training is an intermediate, less clearly documented stage that can emphasize higher-quality data and prepare a model for reasoning or agentic behavior. Supervised fine-tuning then trains on instruction-and-response examples.
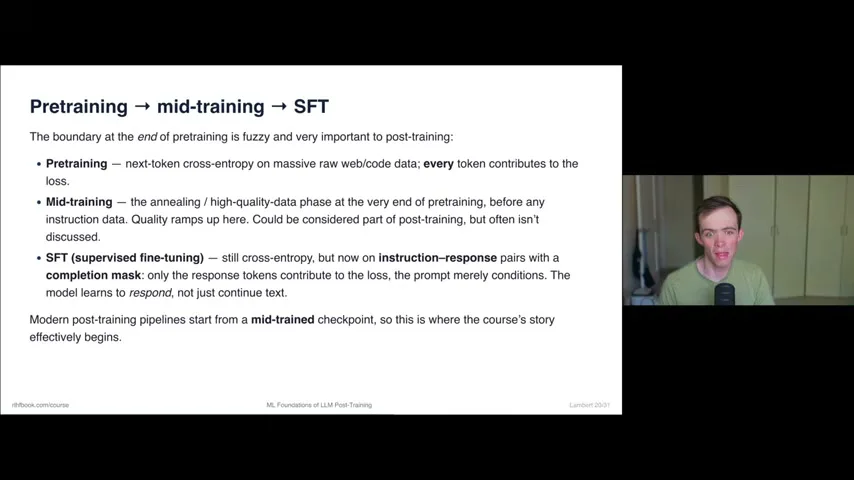
These stages interact: a post-training recipe depends on the model and data produced by earlier steps. Lambert emphasizes that mid-training matters even though the book covers it less, in part because the details are often not publicly documented.
Probability and reinforcement learning
KL, entropy, Monte Carlo estimation and sigmoid appear throughout post-training. Lambert closes with the reinforcement-learning framing and further reading.
KL divergence measures a directional difference between probability distributions and is nonnegative. It appears throughout post-training, including as a way to measure or constrain policy changes. Although Lambert sometimes calls it a distance, he later corrects this terminology: KL is asymmetric and is not a mathematical distance.
Entropy, cross-entropy and KL are closely related. Entropy describes average surprise under a distribution; cross-entropy measures the cost of representing samples from a target using another distribution. Cross-entropy equals the target entropy plus the KL divergence from target to approximation.
A Monte Carlo estimate approximates an expectation using sampled examples. For example, sample tokens from a policy and average the log ratio of its probability to a reference policy’s probability. The sampling distribution and direction of the KL matter.
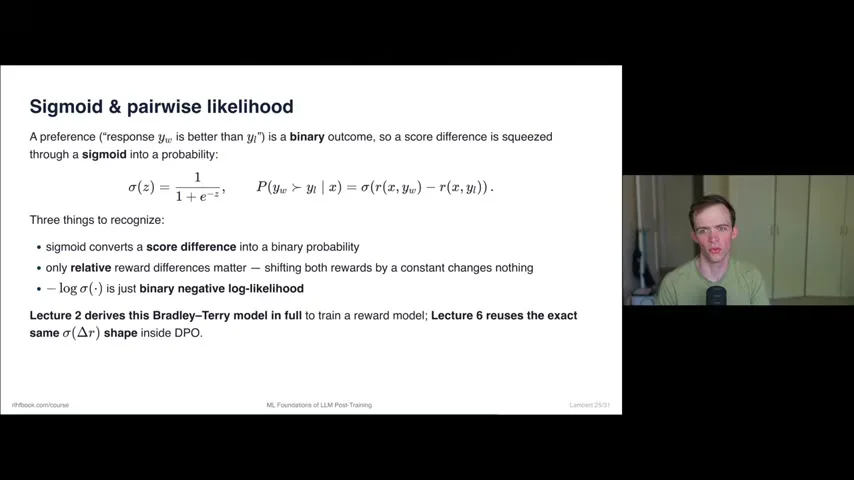
The sigmoid maps a real-valued score to a number between zero and one. Reward modeling uses it to turn a score difference between chosen and rejected responses into a pairwise preference probability. It is a recurring building block in preference losses.
A Markov decision process describes an agent interacting with an environment using states, actions, transition probabilities, a policy, rewards and a discount factor. Trial and error can improve the agent’s behavior over time.
The language-model setting can make this framing look unusual, but complex tool-using agents on long tasks may resemble traditional RL environments more closely. Rewards can be sparse or delayed, and environment dynamics may not be known in advance.
Post-training combines these tools—sampling, losses, constraints, regularization and rewards—to change a pretrained language model’s distribution toward more specific goals. Lambert recommends Sutton and Barto’s reinforcement-learning book and Sebastian Raschka’s Build a Language Model from Scratch, along with resources on the course site.
Más de este canal
 16:48EN
 Nathan Lambert· 2 nov 2026Nathan Lambert on How Open Models Can Compete With Frontier LabsNathan Lambert · Allen Institute for AIOpen models are gaining use and closing capability gaps, but their builders need a sustainable economy and advantages beyond price.
 48:04ENNathan Lambert· 26 oct 2026Nathan Lambert on Open Language Models: History, Competition and RiskNathan Lambert · Allen Institute for AIA tour of open weights, research infrastructure, distillation, adoption and the choices facing model developers.
 46:42ENNathan Lambert· 25 oct 2026Nathan Lambert and Florian Brand on Kimi K3.1, Cyber Risk and AI AgentsNathan Lambert, Florian Brand · Allen Institute for AIThe Interconnects hosts discuss mixed model evaluations, a wave of security disclosures, and what a personal agent can do in everyday life.
 5:42ENNathan Lambert· 12 ago 2026Why the Shoggoth Became a Mascot for AI Post-TrainingNathan Lambert · Allen Institute for AINathan Lambert traces a creature from Lovecraft to a visual metaphor for language models, fine-tuning, and RLHF.
 32:56ENNathan Lambert· 6 ago 2026Nathan Lambert: An Introduction to AI Character TrainingNathan Lambert · Allen Institute for AIHow post-training shapes a model’s behavior, from constitutions and model specs to experiments with personality and activation steering.
 32:11ENNathan Lambert· 5 ago 2026Nathan Lambert on How Language Model Evaluation Has EvolvedNathan Lambert · Allen Institute for AIFrom few-shot prompts and pass@k to agent sandboxes, noisy scores and benchmark contamination.