En 30 segundos
Nathan Lambert examines public signals of open-model adoption, research use, capability and cost. He argues that a fragmented ecosystem must find ways to fund model development while competing with vertically integrated frontier labs. His proposed advantages are lower inference costs and adaptable, private models that organizations can own.
- 1Usage is growing, but visibility is incompleteInference providers' public disclosures suggest substantial growth. Cloud deployments mean these figures represent only a portion of open-model use.
- 2A gap measured in monthsLambert reads capability indices as showing open weights consistently reaching frontier thresholds several months after closed models.
- 3Open does not always mean cheaperClosed providers offer competitive performance across the cost frontier, aided by scale and their training and serving stacks.
- 4A fragmented economyBuilders, inference providers and model adaptation firms capture different parts of the value, complicating the funding of new models.
- 5Compete on ownership and adaptabilityLambert calls for lower inference prices and models enterprises can own, customize and run privately.
Conclusiones
- Public inference data shows substantial growth, but captures only part of open-model usage.
- Open-weight models have generally crossed capability thresholds months after leading closed models, according to the indices Lambert discusses.
- Open models are not automatically cheaper at a given level of performance.
- Revenue is fragmented among model developers, inference providers and adaptation companies, making reinvestment in frontier training difficult.
- Lambert argues that open models can differentiate through low-cost inference and private, adaptable weights owned by customers.
Lee el texto editado por capítulos
Measuring open-model use
Lambert compares public inference data with disclosures from closed providers. He also looks at research mentions and cautions that usage data is incomplete.
As inference markets have taken off, I have been asking what economic conditions and capabilities would let open models distinguish themselves from OpenAI and Anthropic. The question is how they can win on strengths that closed models may not be able to offer.
Start with usage. Together AI, Baseten, Fireworks and OpenRouter are examples of companies serving inference for open models. For OpenRouter, I look at the share of tokens attributed to open models; the platform also serves closed models. The other companies disclose figures only occasionally, often around fundraising, while OpenRouter publishes its data.
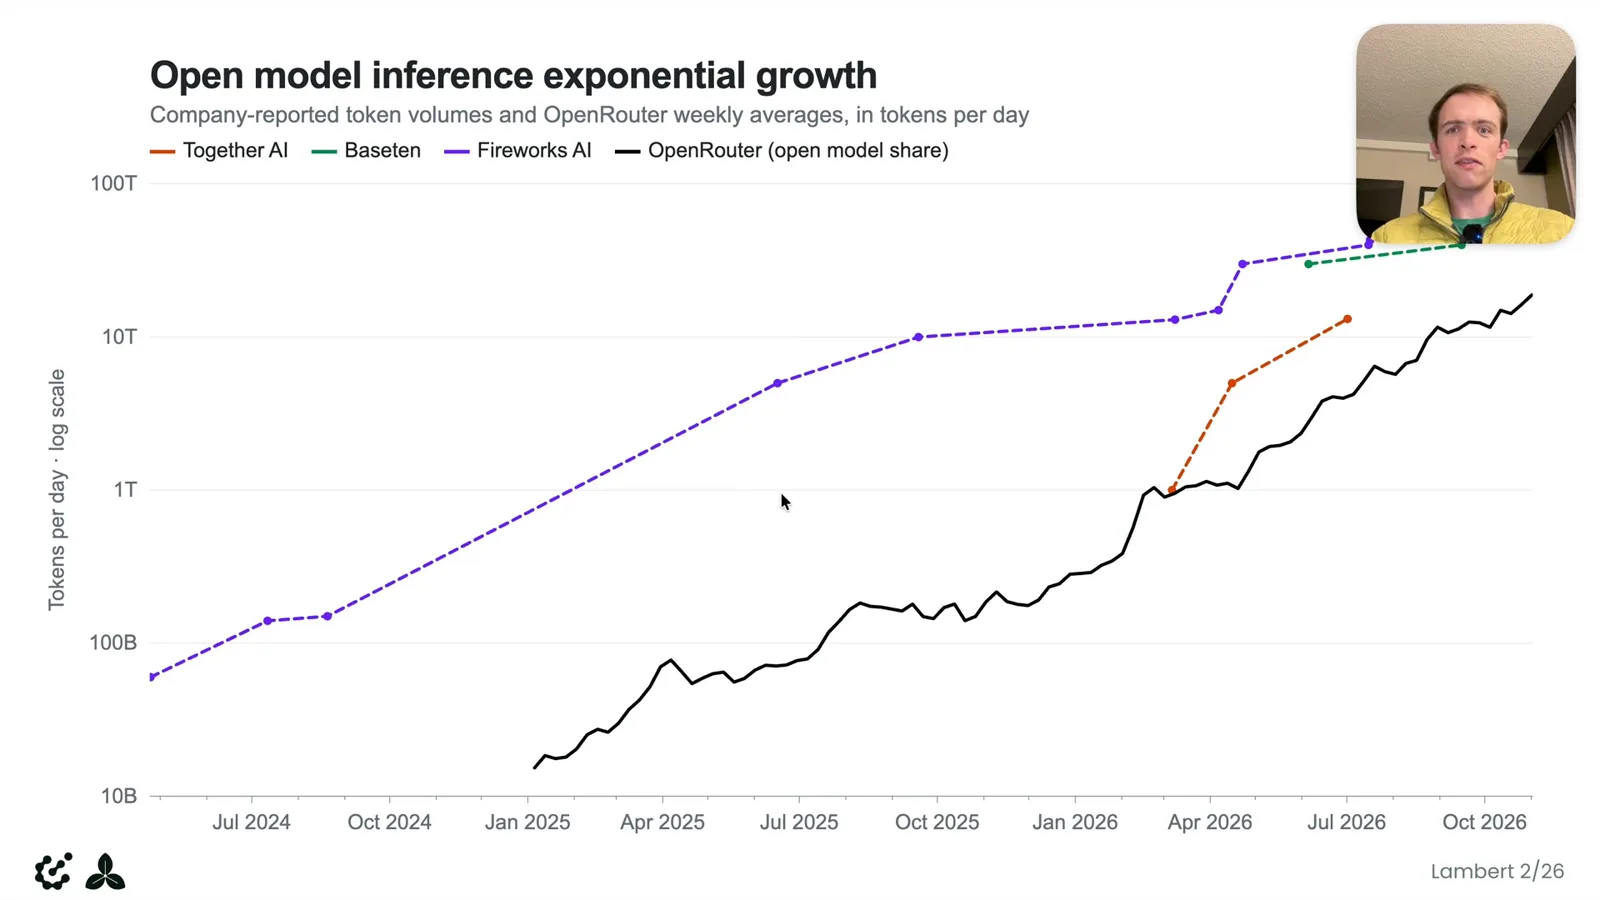
Those figures show rapid growth over the last few years, but their context is hard to judge because we know so little about total usage. I suspect they capture a minority of open-model inference: many models are also served through Amazon Bedrock, Microsoft Azure and other clouds. Still, the inference companies are a useful signal because their business is concentrated in this market.
Google discloses inference across its products as well as figures for the Gemini API. In the data I compare, Fireworks and Baseten appear to be serving at a scale comparable to the Gemini API. That suggests meaningful businesses are growing, although we need much more information before assigning precise shares. At minimum, the data helps us ask whether open models are growing alongside the enormous demand for closed models.
Open models also matter as a foundation for research. I searched recent arXiv papers in popular machine-learning categories and found that nearly as many mention Qwen, the most popular open-model family in that analysis, as mention OpenAI models. Adoption took time, but accessible model families now underpin a great deal of research and innovation.
Capability and cost
Open weights trail the frontier by months in the indices he discusses. Cost comparisons are more complicated than the claim that open models are always cheaper.
On capability measures, open-weight models have trailed the frontier by a few months—a pattern that has persisted longer than I expected. The Artificial Analysis progress index, like the Epoch Capabilities Index, suggests that an open model eventually crosses a given threshold, perhaps four, six or eight months later depending on the measure. That is still rapid diffusion, and it makes planning easier than if the question were whether the capability would arrive at all.
There is uncertainty around individual releases. At the time of this recording, I expected Kimi K3.1 within a few days, while recognizing that release timing can change. More broadly, the stable lag matters more to the argument than any one model's announced date.
Cost is less straightforward than the common claim that open models are cheaper. Closed labs benefit from advanced training stacks, efficient reasoning and compute scale, and they offer models across the cost-performance frontier. At today's lower open-model performance levels, closed models can be competitive too. That changes the reasons an organization might choose open weights at scale.
The economics of a fragmented ecosystem
Model builders, inference providers and adaptation firms occupy different layers. Their incentives and revenue flows differ from those of vertically integrated labs.
At the center of the open-model economy are the organizations building the models: Moonshot AI, Zhipu AI, DeepSeek, Alibaba, Reflection, Arcee and the Llama team, among others. The question is what funds their next iterations. Continuing to scale requires revenue, yet much of the money currently flows to the serving, inference and post-training layer, including Fireworks, Baseten and Together.
This split between the people building models and those benefiting from inference has no obvious fix. OpenAI and Anthropic, by contrast, can integrate products, models, compute and other parts of the stack to reduce serving costs and improve margins. The open ecosystem cannot easily assume it will achieve the lowest cost at a fixed level of intelligence under its current structure.
A third layer is emerging around enterprises that want to post-train models and control their own compute. Prime Intellect offers training infrastructure, while Applied Compute and data companies such as Mercor work on adaptation, evaluation or training. Builders, serving companies and specialists cooperate, but the resulting system does not necessarily compound revenue back into the next generation of models.
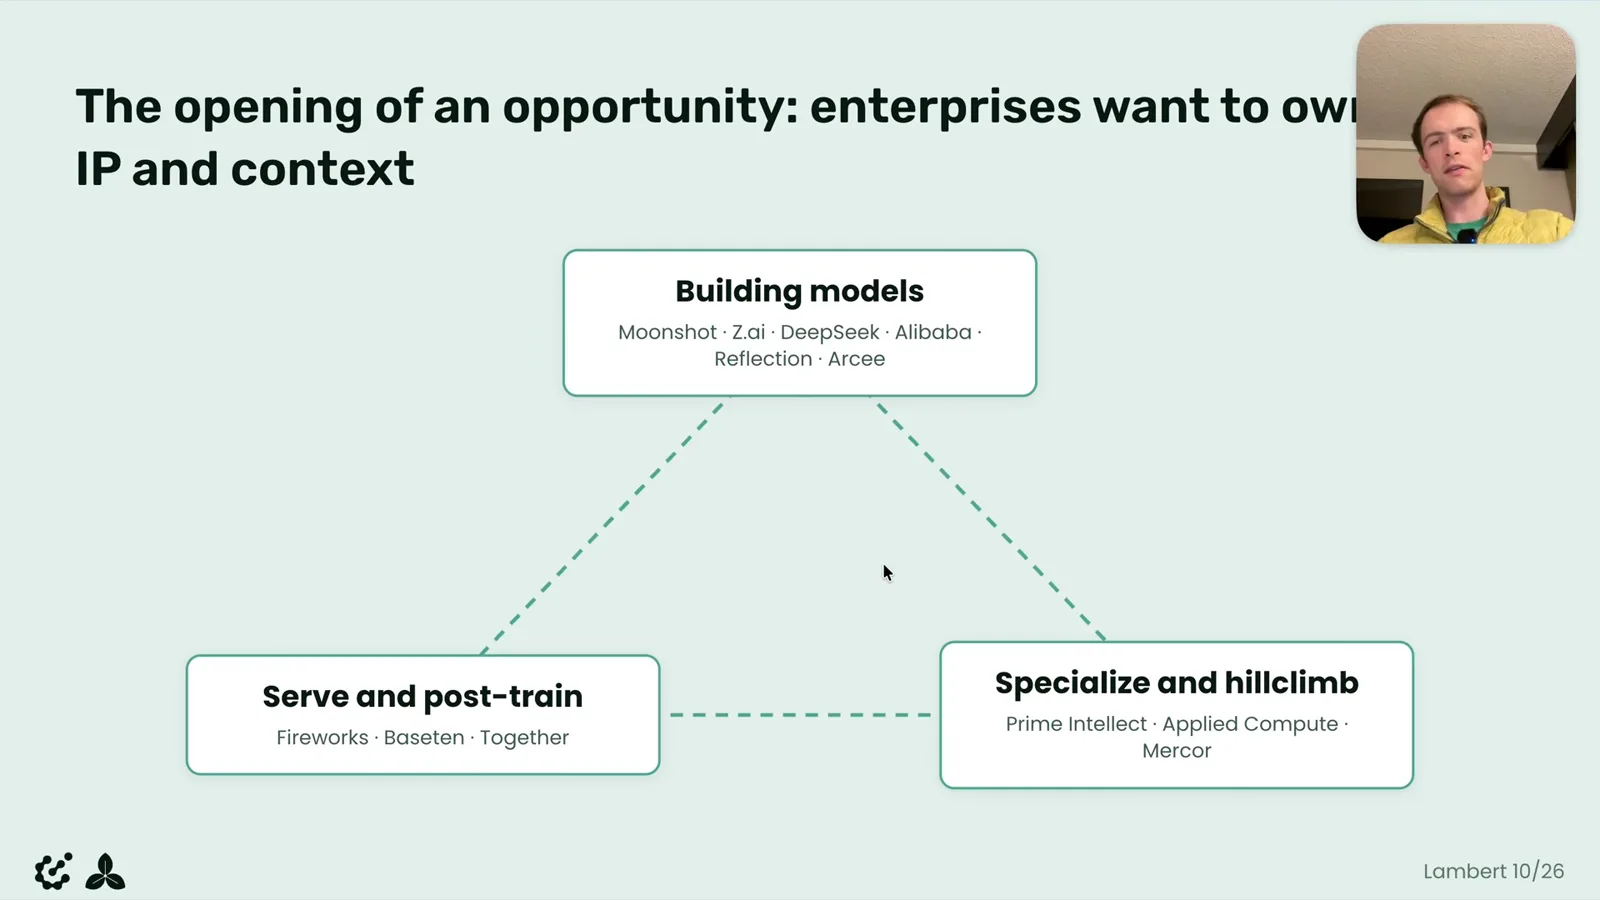
Their business models are also converging. Inference requires compute, but providers can earn money as they serve it. Training a model is expensive before there is a comparable return, and model builders depend on revenue flowing back from downstream providers, including through arrangements such as revenue sharing. That creates pressure for builders to move downstream and compete with others in their own ecosystem.
There is money in inference and in adapting models to valuable domains or private deployments. Yet competition among members of the open-model coalition makes the route to funding larger labs harder to see. The central economic question is what connects these fragmented players and lets the whole system sustain innovation.
The urgency comes from frontier training costs. Jensen Huang has described a GPT-6 Astra model trained using hundreds of thousands of Blackwell chips; I estimate that a frontier model's path from idea to execution can cost billions of dollars and may rise to tens of billions. If open labs cannot finance anything close to those costs, the capability gap could widen.
A path to competing
Lambert proposes cheaper inference and private, adaptable models as complementary advantages. Enterprise specialization may create value that can support the ecosystem.
I do not think the goal is simply the cheapest model at a given intelligence level. It is the cheapest adaptable, private intelligence: give people the weights so they can own and change the model. That ownership offers a path that a closed provider, retaining control of its own weights, cannot offer in the same way.
Since GLM 5.2, the economic questions have become more concrete. Enterprises are discussing their own fine-tuned models, and agents have become useful in practice. Model abilities remain uneven: an open model may be better suited to a particular need, whether speed or work on an internal codebase. The ecosystem needs to capitalize on those differences soon.
One condition for success is driving inference prices toward marginal cost. Many providers compete, but high demand and limited compute supply have kept that competitive pressure from fully playing out. Until prices fall, the relative cost and performance of open models may still make closed alternatives attractive. Open providers may need to find returns in volume, specialization or enterprise agreements.
The other condition is adaptable, private and controlled intelligence. An enterprise is a vehicle for internal expertise, intellectual property and domain knowledge. Some organizations may be reluctant to send that information to a closed provider, especially as AI becomes more capable. I believe giving them model weights enables them to express and retain expertise in a model they control, although the way every participant profits remains unresolved.
Early work by Harvey, Mercor, Applied Compute and others suggests the opportunity is real. I point to Harvey's work on adapting Kimi K3 for a narrow legal task, where it reported higher accuracy at substantially lower cost than frontier models. Many expert domains have not been fully captured in public or digitized data, leaving room for specialized models.
If specialization can feed revenue back into model development, lower model costs could help more organizations own and use intelligence. That diffusion may let open models spread across domains where customers hesitate to give up control of their information. I want to pursue research that enables this future because I believe it could be safer and more accessible, while recognizing the substantial economic problems still to solve.
Más de este canal
 48:04EN
 Nathan Lambert· 26 oct 2026Nathan Lambert on Open Language Models: History, Competition and RiskNathan Lambert · Allen Institute for AIA tour of open weights, research infrastructure, distillation, adoption and the choices facing model developers.
 46:42ENNathan Lambert· 25 oct 2026Nathan Lambert and Florian Brand on Kimi K3.1, Cyber Risk and AI AgentsNathan Lambert, Florian Brand · Allen Institute for AIThe Interconnects hosts discuss mixed model evaluations, a wave of security disclosures, and what a personal agent can do in everyday life.
 5:42ENNathan Lambert· 12 ago 2026Why the Shoggoth Became a Mascot for AI Post-TrainingNathan Lambert · Allen Institute for AINathan Lambert traces a creature from Lovecraft to a visual metaphor for language models, fine-tuning, and RLHF.
 32:56ENNathan Lambert· 6 ago 2026Nathan Lambert: An Introduction to AI Character TrainingNathan Lambert · Allen Institute for AIHow post-training shapes a model’s behavior, from constitutions and model specs to experiments with personality and activation steering.
 32:11ENNathan Lambert· 5 ago 2026Nathan Lambert on How Language Model Evaluation Has EvolvedNathan Lambert · Allen Institute for AIFrom few-shot prompts and pass@k to agent sandboxes, noisy scores and benchmark contamination.
 13:53ENNathan Lambert· 4 ago 2026Nathan Lambert Answers Six Questions About Post-Training RecipesNathan Lambert · Allen Institute for AIA practical discussion of specialist models, KL penalties, supervised data, reinforcement learning and business tradeoffs.