OpenAI’s o1 Preview: A First Look at Longer Reasoning

Matthew Berman introduces the o1-preview and o1-mini models and tries a Python game prompt.

MBMatthew BermanPonente · Forward Future
Canal
Matthew Berman
Publicado
16 sept 2024
Vídeo
0:54
Lectura
1 min
Diapositivas
1
Original
inglés
Abrir en YouTube
Al desplazarte, el vídeo se reduce a la esquina inferior derecha y sigue reproduciéndose. Los subtítulos siguen tu idioma de lectura.
Idioma de lecturaDisponible en 2 idiomas
Este artículo aún no está en español, así que se muestra el original en inglés.
RESUMEN

En 30 segundos

In this September 2024 short, Matthew Berman describes OpenAI’s newly released o1 models and tests a coding prompt. He highlights their longer reasoning time and OpenAI’s research benchmark claims.

  1. 1Two o1 modelsBerman introduces o1-preview and o1-mini, associated with the previously anticipated Strawberry model.
  2. 2More time to thinkHe says the models are designed to spend more time reasoning and cites OpenAI’s comparison with PhD students on research tests.
  3. 3A game promptHe tries a Python Tetris prompt and notes that ChatGPT shows a summary of the thought process, rather than the raw reasoning.

Conclusiones

  1. OpenAI introduced o1-preview and o1-mini as models designed to spend more time reasoning.
  2. Berman cites an OpenAI claim comparing performance on selected research tests with PhD students.
  3. His Python game prompt shows a reasoning summary and a reported 94 seconds of thinking.
TEXTO COMPLETO

Lee el texto editado por capítulos

Solo la transcripción
01

Introducing and testing o1

Berman describes the new models and their reasoning approach. He then tries a Python game prompt and reacts to the result.

OpenAI’s long-awaited Strawberry model is here. There are two models, o1-preview and o1-mini. They are designed to spend more time thinking through a problem, and OpenAI says the model performs similarly to PhD students on some research tests.
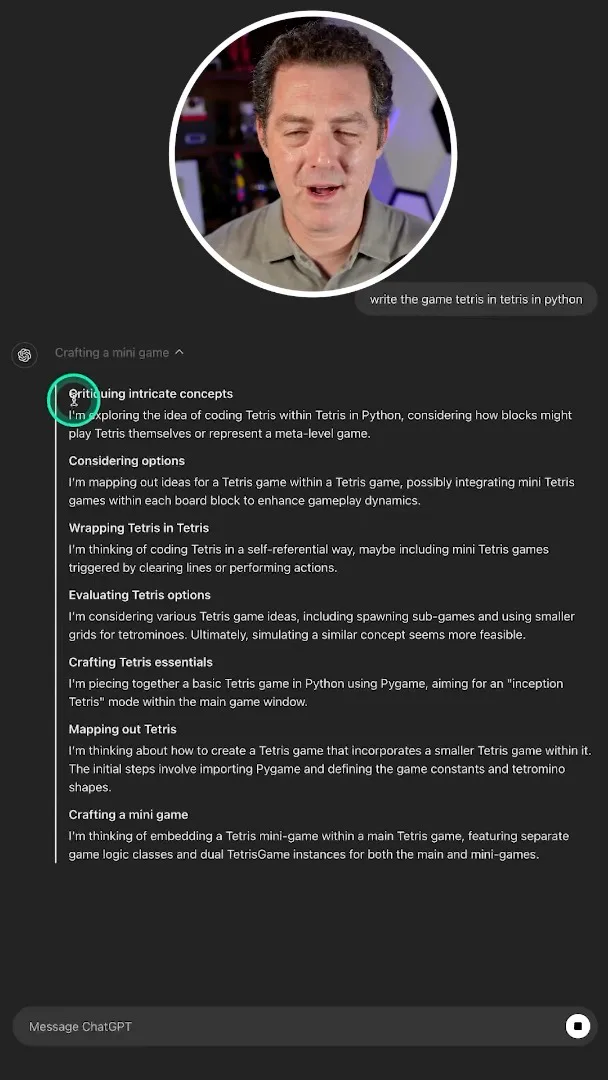
ChatGPT’s reasoning summary
DIAPOSITIVA 1 / 1ChatGPT’s reasoning summaryThe interface shows the Python game prompt and a summary of the model’s reasoning.

I ask it to write a Tetris game in Python. ChatGPT shows a summary of its thought process, though not the raw reasoning, and reports thinking for 94 seconds. I try the result and react enthusiastically.

Más de este canal

6 diapositivas25:50EN
MBMatthew Berman· 24 oct 2026Kimi K3.1 Pro Tested: Strong 3D Demos, Uneven Results and Competitive PricingMatthew Berman · Forward FutureMatthew Berman tests the open-weight model on coding, 3D rendering and visual explanations, then compares benchmark results and prices.Open-weight modelsBenchmarksAI cost & performance+1
2 diapositivas32:20EN
MBMatthew Berman· 23 oct 2026Who Is Local AI For? The Costs, Trade-offs and a Hybrid FutureMatthew Berman · Forward FutureMatthew Berman weighs data control and independence against hardware cost, setup complexity and inference speed.Local inferenceOpen-weight modelsAI cost & performance+1
45:08EN
MBMatthew Berman· 21 oct 2026Sam Altman on AI Discovery, Consciousness, Compute and a Human-Centered FutureMatthew Berman, Sam Altman · Forward FutureIn a conversation with Matthew Berman, Altman discusses scientific progress, personal assistants, recursive self-improvement and the importance of human agency.AI for sciencePersonal agentsConsciousness+2
0:32EN
MBMatthew Berman· 21 oct 2026Sam Altman on the Continuing Demand for Software WorkSam Altman, Matthew Berman · OpenAIIn a short interview excerpt, Altman says demand for software may be larger than expected even as AI changes how it is made.Future of WorkSoftware engineeringAgentes de programación
5 diapositivas12:14EN
MBMatthew Berman· 14 oct 2026Gemini 4 Argon Tested: 3D Demos, a Spreadsheet Prototype and Benchmark ResultsMatthew Berman · Forward FutureMatthew Berman tests Google’s model on games and visual projects, then compares reported coding and agent benchmarks.GeminiBenchmarksAgentes de programación+1
5 diapositivas10:36EN
MBMatthew Berman· 13 oct 2026Meta Muse Wonder Tested: Strong Benchmarks, Mixed Demos and Quota FrictionMatthew Berman · Forward FutureMatthew Berman tests Meta’s models on browser demos and reviews their published benchmark scores, availability and cost.Modelos y entrenamientoBenchmarksAI cost & performance+1