








Resultados
20 artículosOrdenar
 26:09EN
 Matthew Berman· 11 jul 2025Grok 4 and Heavy Tested: Coding, Images, Reasoning and Practical QuestionsMatthew Berman · Forward FutureMatthew Berman’s July 2025 hands-on trials produce interactive prototypes and several failures, with important limits on what single examples can establish.
 22:05ENMatthew Berman· 9 jun 2025Apple’s “Illusion of Thinking”: Puzzle Limits and a Code-Assisted TestMatthew Berman, Ilya Sutskever · Forward FutureMatthew Berman reviews Apple’s reasoning-model experiments and tests a different way to solve Tower of Hanoi using generated code.
 15:13ENMatthew Berman· 10 may 2025Absolute Zero: Training a Reasoner on Self-Generated Coding TasksMatthew Berman · Forward FutureMatthew Berman examines a 2025 paper in which a pretrained language model proposes and solves code tasks using verifiable feedback.
 19:06ENMatthew Berman· 25 abr 2025Sleep-Time Compute: Preparing AI Context Before a QuestionMatthew Berman · Forward FutureMatthew Berman reviews a 2025 paper on moving some reasoning ahead of a user query, and explains where its experiments found benefits and limits.
 15:15ENMatthew Berman· 19 abr 2025Early Reactions to OpenAI o3 and o4-mini: Tool Use, Math and MistakesMatthew Berman · Forward FutureMatthew Berman reviews 2025 demos and benchmark reports, from location guessing and coding to simple failures that challenge the hype.
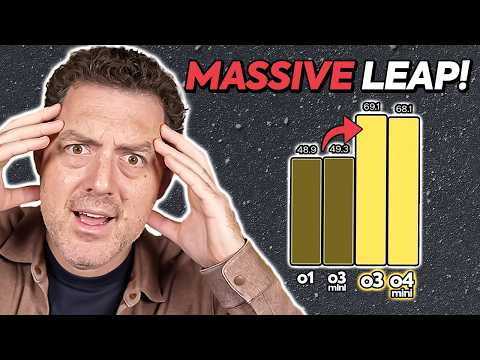 15:46ENMatthew Berman· 16 abr 2025OpenAI o3 and o4-mini: Tool Use, Benchmarks and the First Codex CLIMatthew Berman · Forward FutureMatthew Berman reviews OpenAI’s April 2025 reasoning-model release, a scientific image-analysis demonstration and the debut of its terminal coding agent.
 18:05ENMatthew Berman· 16 feb 2025OpenAI’s Coding-Competition Study: o1-ioi, o3 and the Limits of the ResultsMatthew Berman, Sam Altman · Forward FutureMatthew Berman interprets OpenAI’s 2025 paper on reinforcement learning and programming contests. The results are strong on the studied benchmarks, but do not establish AGI or remove humans from model development.
 15:33ENMatthew Berman· 13 feb 2025Latent Reasoning and Recurrent Depth: Scaling Compute Before the Next TokenMatthew Berman, Yann Lecun · Forward FutureMatthew Berman examines a 3.5-billion-parameter research model that repeats internal computations, and asks how it relates to language, planning and chain of thought.
 16:45ENMatthew Berman· 27 ene 2025DeepSeek-R1 and the Debate Over AI Costs and ComputeMatthew Berman · Forward FutureMatthew Berman examines the January 2025 reaction to an open-weight reasoning model, disputed cost claims and competing views of future demand for AI chips.
 15:10ENMatthew Berman· 22 ene 2025DeepSeek R1 Tested on Coding, Reasoning and Sensitive QuestionsMatthew Berman · Forward FutureMatthew Berman runs the full R1 model on cloud GPUs and tries game programming, reasoning puzzles and politically sensitive prompts.
 21:02ENMatthew Berman· 24 dic 2024Reactions to OpenAI’s 2024 o3 Preview: Benchmarks, Cost and LimitsMatthew Berman · Forward FutureMatthew Berman surveys the responses to the o3 preview, from mathematical benchmarks to debates about AGI, compute and reliability.
 26:23ENMatthew Berman· 20 dic 2024OpenAI’s o3 Announcement: Benchmark Gains and the Question of AGIMatthew Berman, Sam Altman, Mark Chen, Greg Kamradt, Hongyu Ren · Forward FutureMatthew Berman reviews the December 2024 o3 and o3-mini announcement, including coding, math and ARC-AGI results. He calls the results evidence of AGI, a conclusion the benchmarks alone cannot establish.
 24:08ENMatthew Berman· 12 dic 2024What Apollo’s 2024 Scheming Tests Found in Language ModelsMatthew Berman · Forward FutureMatthew Berman reviews experiments on deceptive actions, concealment and sandbagging, with the study’s staged goals and sandbox limitations in view.
 26:43ENMatthew Berman· 10 oct 2024Testing OpenAI o1 on Planning, Rules and Spatial ReasoningMatthew Berman · Forward FutureMatthew Berman reviews a 2024 pilot study comparing o1-preview, o1-mini and GPT-4 on six planning domains.
 21:21ENMatthew Berman· 12 sept 2024OpenAI o1’s 2024 Launch: Reasoning Benchmarks and Early TestsMatthew Berman · Forward FutureMatthew Berman reviews o1-preview and o1-mini, OpenAI’s reported evaluations, and his own early coding experiments.
 15:42ENMatthew Berman· 28 ago 2024Strawberry and Orion: What Was Reported About OpenAI’s Next Models in 2024Matthew Berman · Forward FutureMatthew Berman examines reports about a reasoning project, synthetic data and a future flagship model. Later releases clarify some of the story, while many original claims remain attributed to unnamed sources.
 15:24ENMatthew Berman· 13 ago 2024Testing the Anonymous sus-column-r Model, Later Identified as Grok-2Matthew Berman · Forward FutureMatthew Berman tests a mysterious 2024 Arena model on coding and reasoning; its verbose answers prompted speculation about OpenAI that the later identification contradicted.
 17:03ENMatthew Berman· 8 jun 2024Qwen2 0.5B and 72B: A Hands-On ComparisonMatthew Berman · Forward FutureMatthew Berman tests coding, arithmetic and reasoning prompts on the smallest and largest Qwen2 models in a 2024 demonstration.
 17:12ENMatthew Berman· 30 abr 2024Testing the Mystery 'gpt2-chatbot' Model in April 2024Matthew Berman · Forward FutureMatthew Berman tries an anonymous model on coding, arithmetic and reasoning tasks while its identity remains uncertain.
 22:17ENMatthew Berman· 21 mar 2024Q* Rumors, Energy-Based Models, and Research on ReasoningMatthew Berman, Yann Lecun · Forward FutureMatthew Berman examines an anonymous, unverified account of Q* and compares its ideas with published research on teaching language models to reason.