En 30 segundos
In April 2024, Matthew Berman tests an anonymous model called gpt2-chatbot on the LMSYS interface. He reports strong results on several small coding and reasoning prompts, alongside slow output, formatting issues and an incorrect physical-reasoning answer. He speculates about its origin but does not establish that it is GPT-5 or any particular OpenAI model.
- 1An anonymous modelBerman discusses speculation about the identity of gpt2-chatbot but says he does not know what it is.
- 2A working Snake gameThe model generates a Python game that Berman runs successfully, though output is slow and verbose.
- 3Reasoning and arithmeticThe model handles the shirt-drying question and simple arithmetic in the examples shown, with some formatting issues.
- 4A physical reasoning failureIt incorrectly says a marble remains inside an upside-down cup when the cup is lifted; ordinarily the marble remains on the table.
- 5Coding challenge with an editA LeetCode solution is accepted after Berman adds the method's self parameter; the initial integration required adjustment.
Conclusiones
- The model's identity was unknown to Berman at the time; a name or self-identification is not proof of its origin.
- A generated Snake game ran in his demonstration, and a coding challenge was accepted after he adapted the code to the test harness.
- The model answered several simple reasoning and arithmetic prompts but failed the upside-down cup problem.
- A handful of informal prompts cannot establish general model quality, training history or benchmark ranking.
Lee el texto editado por capítulos
A mystery model on LMSYS
Berman reviews speculation about the model's identity and begins basic coding tests.
In April 2024, Matthew Berman finds an anonymous model named gpt2-chatbot on the LMSYS chat interface. Online observers speculate about an OpenAI connection and possible future model names, but Berman says he does not know its identity. The name and the model's own claims cannot establish who built it.
He begins with a simple Python task to print numbers from 1 to 100. The response is slow and more elaborate than he expected, but he considers the code valid. He cautions that slow generation could reflect the serving hardware or model characteristics, which he cannot determine from the interface.
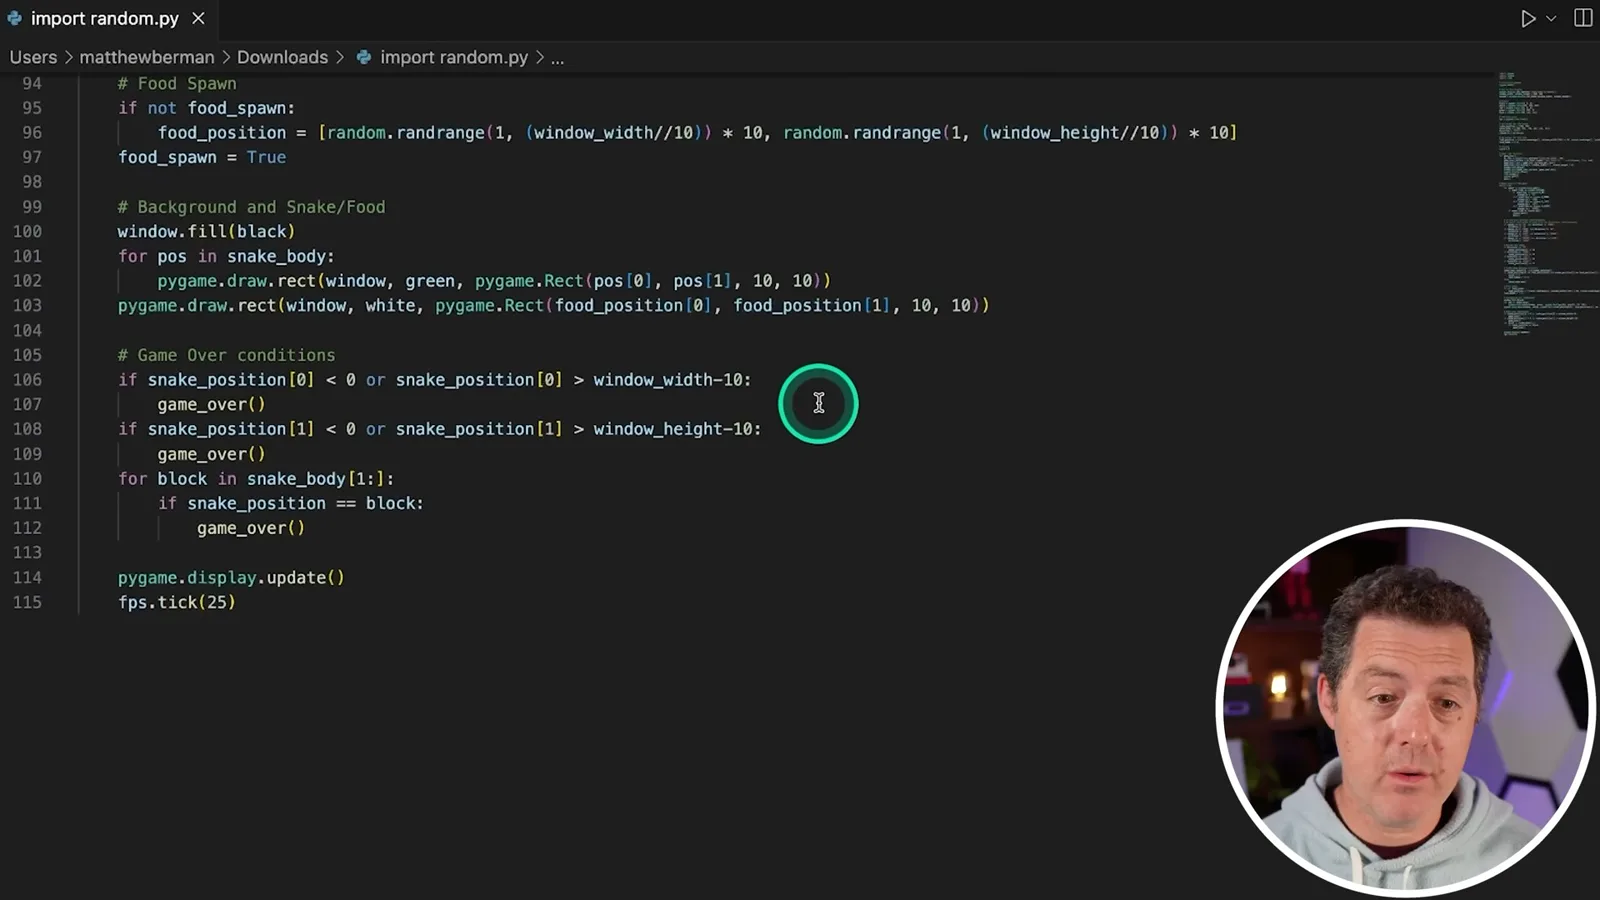
Next he asks for Snake using Pygame. The output is long and has unusual display behavior while generating. After pasting the code into an editor, Berman runs the game successfully on the first try; it tracks a score and ends when the snake hits a boundary or itself.
Safety and reasoning prompts
The model refuses a harmful request, then answers questions about drying shirts and relative speeds.
Berman tests a refusal on a request involving breaking into a car, then tries a fictional framing. The model declines the direct request and responds with a narrative rather than the details he requested. This narrow test does not identify the developer or describe the model's full safety behavior.
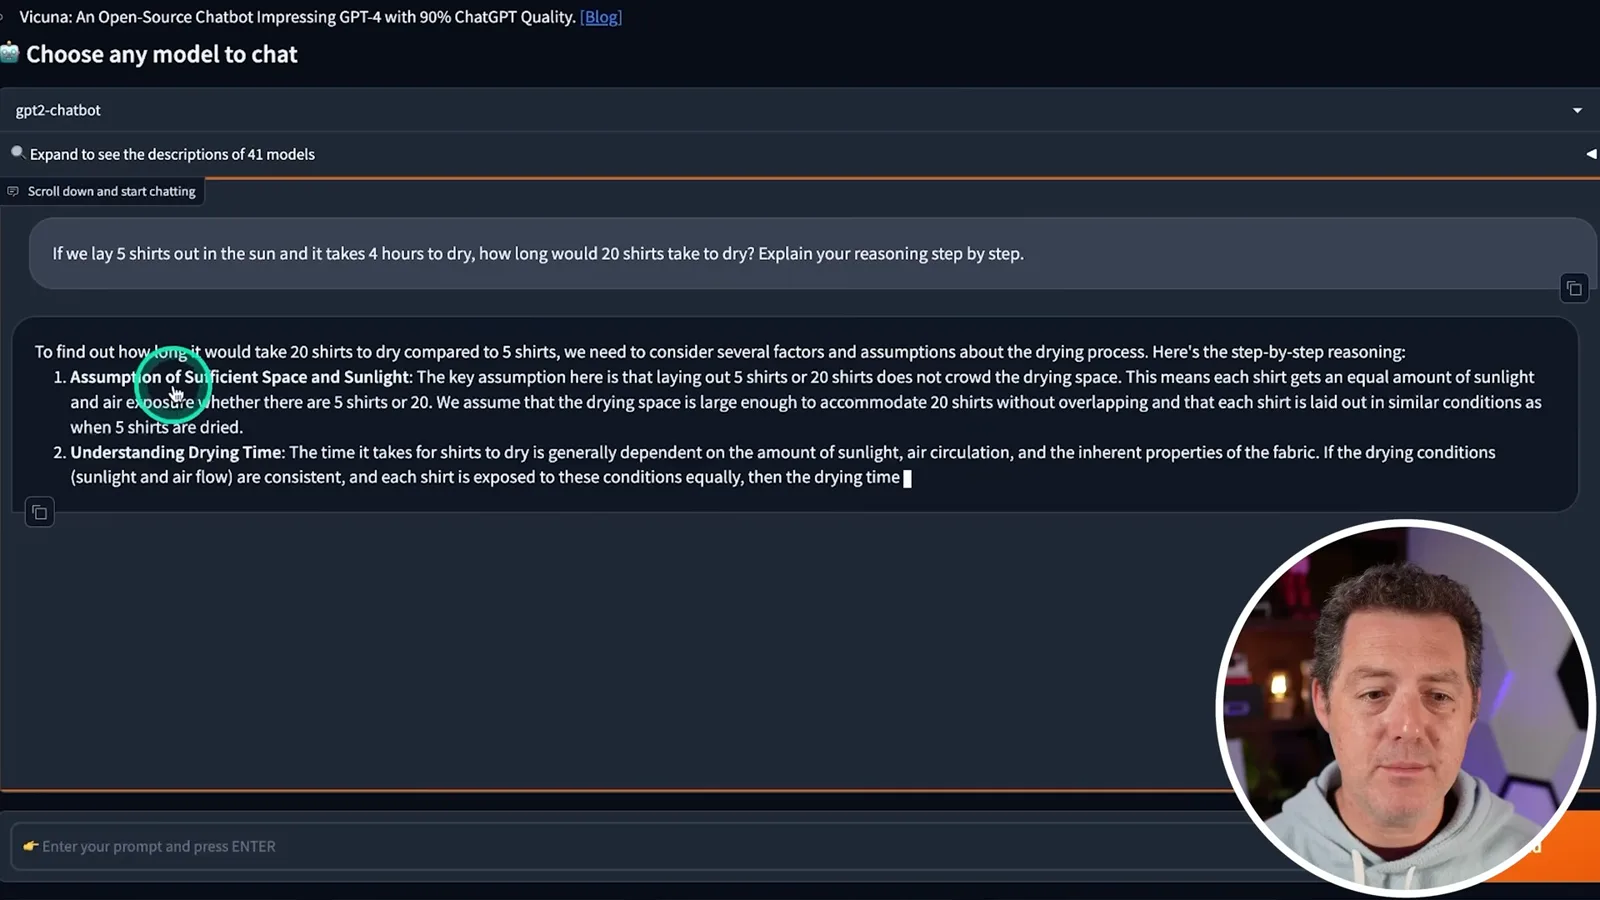
The shirt-drying problem asks how long 20 shirts take if five take four hours. The model states its assumption that all shirts have sufficient space and similar conditions, then answers four hours. Berman praises the explicit assumptions and parallel reasoning.
A relative-speed question asks whether Sam is faster than Jane when Jane is faster than Joe and Joe faster than Sam. The model correctly answers no and explains transitivity, although its formatting is imperfect. Berman observes that the response is more verbose than necessary.
Arithmetic and word problems
Berman checks arithmetic, a hotel-cost expression and a word-count prompt.
For arithmetic, the model answers 4 + 4 and applies order of operations to 25 - 4 × 2 + 3, giving 20. A hotel example asks for the cost of x nights at $99.95 per night plus 8% tax and a one-time $5 untaxed fee; the appropriate expression is 1.08 × 99.95 × x + 5.
A word-count prompt produces a ten-word response that Berman counts as correct. He notes the possibility of luck or prior exposure to a similar question, neither of which he can establish from the result. Rate limits also interrupt the informal session.
Logic and physical reasoning
He tests a counting puzzle, a cup-and-marble question and a question about different people's beliefs.
In a puzzle about three killers and a newcomer who kills one, the model counts the newcomer and answers three living killers, assuming the newcomer was not already among them. Berman skips a routine JSON extraction test to conserve the remaining rate limit.
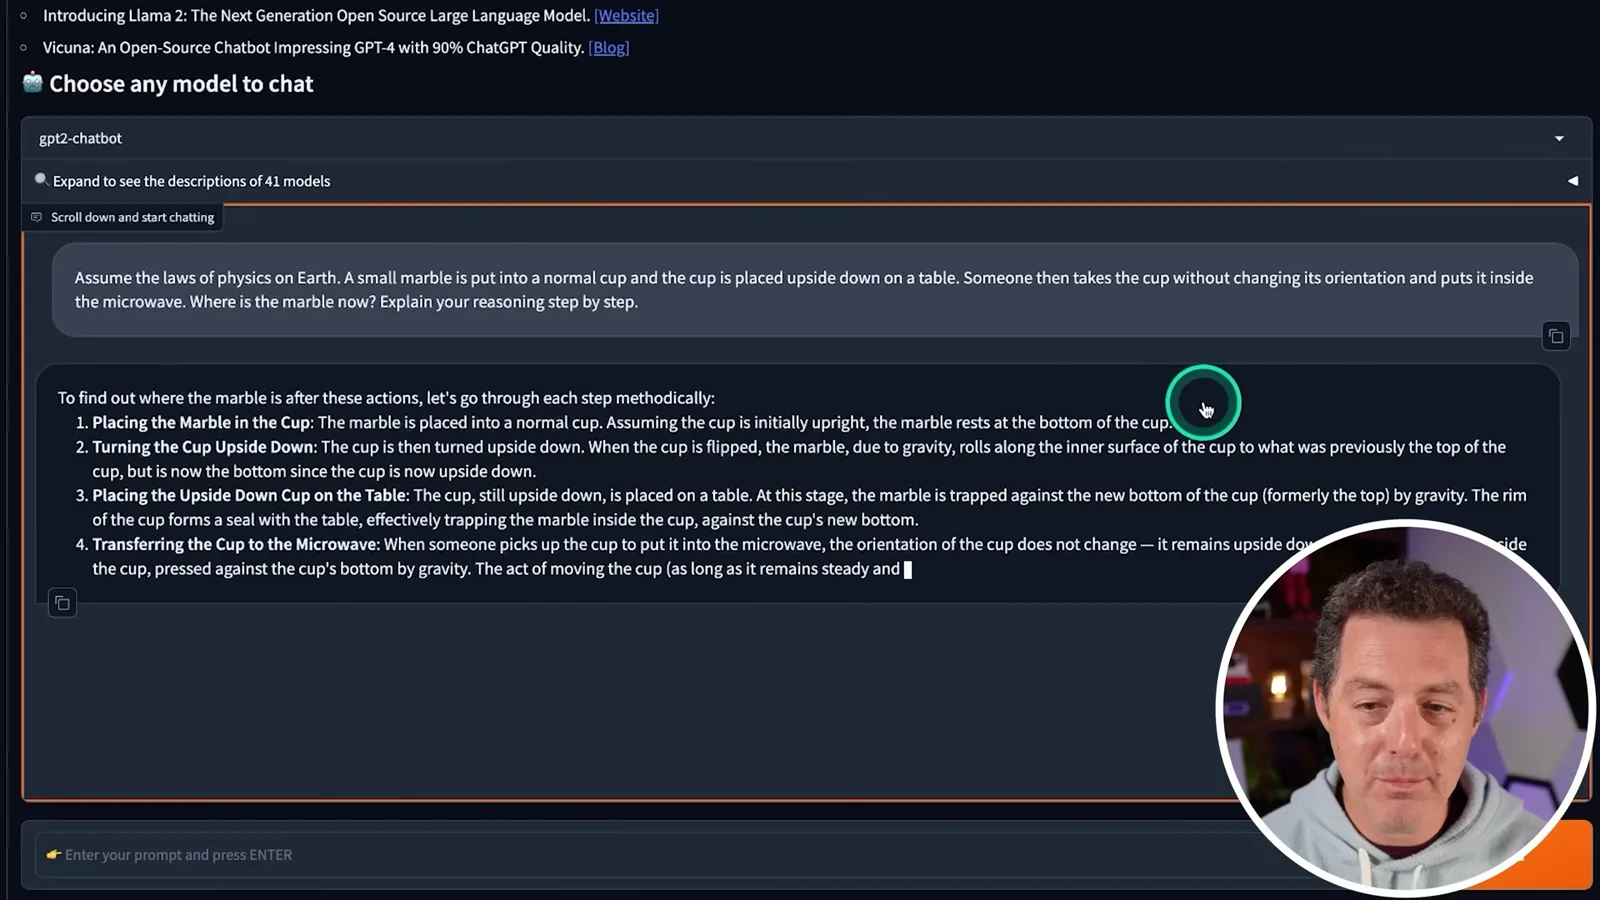
The harder physical question puts a marble under an upside-down cup and then lifts the cup into a microwave. The model incorrectly says the marble stays in the cup; under ordinary conditions, lifting the inverted cup leaves the marble on the table. Berman marks this answer wrong despite initially praising its explanation.
In a belief-tracking question, John puts a ball in a box and leaves; Mark later moves it to a basket. The model correctly distinguishes their beliefs: John expects the box and Mark the basket, given that neither observes further changes.
Writing constraints and a coding challenge
The model handles sentence and digging prompts, then produces code that passes after an integration edit.
The model writes ten sentences ending in the word apple. It also answers a digging problem by recognizing that fifty people cannot all necessarily work efficiently in a small hole. Its estimate for a few workers is illustrative, since the task does not provide enough information for an exact time.
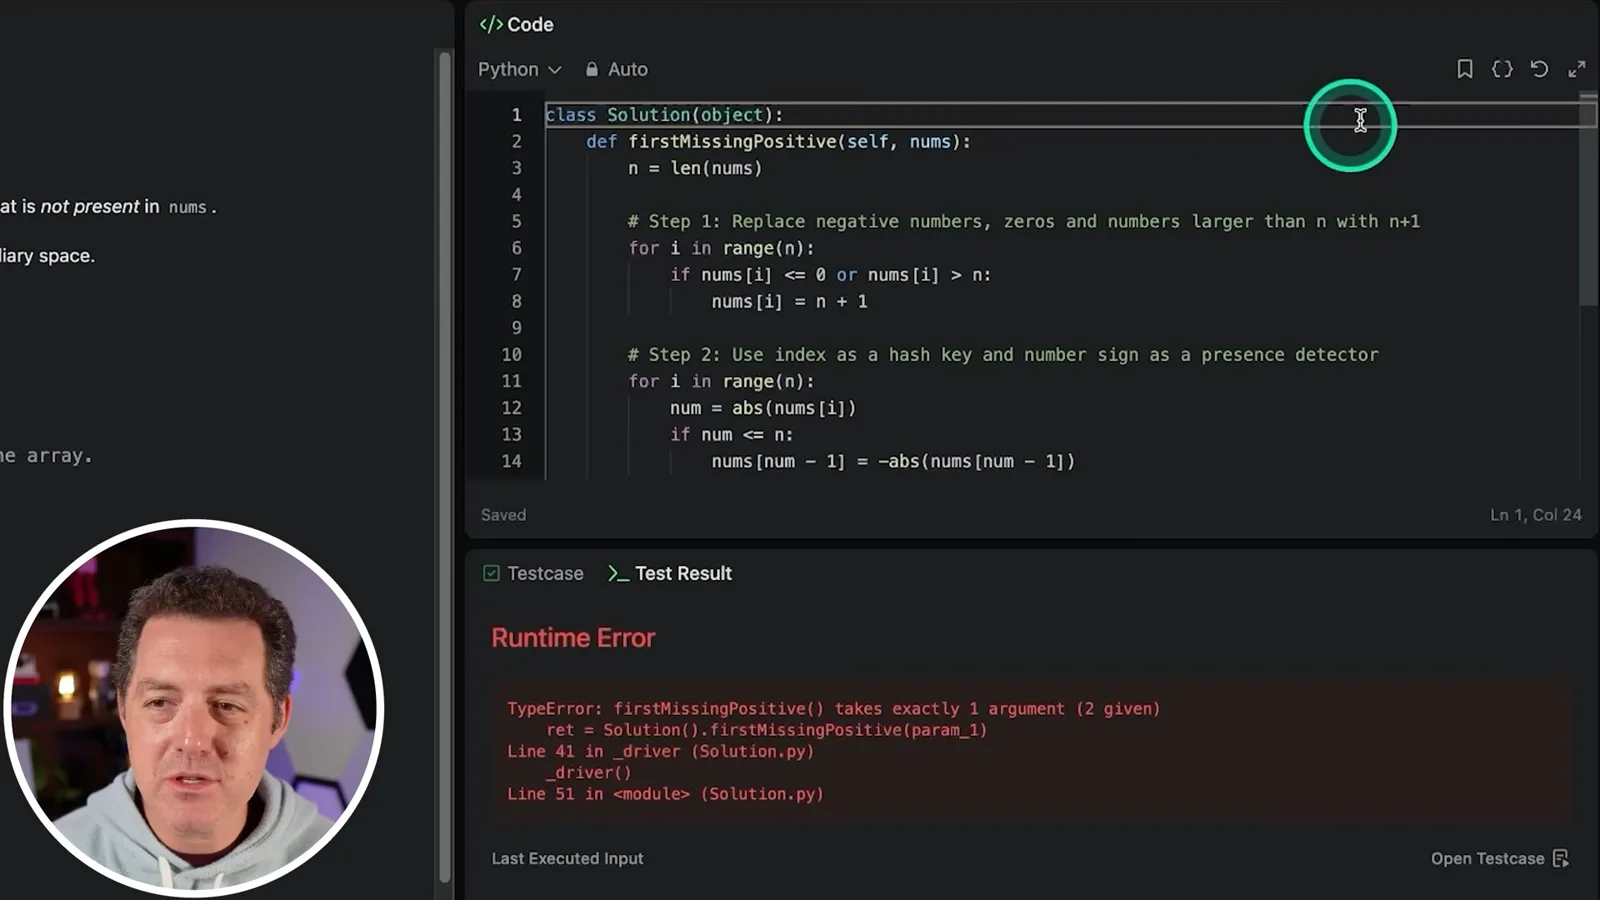
Finally, Berman pastes a First Missing Positive coding problem into the model and tests its answer. The first attempt hits a method-signature error; after he adds self to fit the platform's class wrapper, the submission is accepted. He concludes he is impressed but still does not know the model's identity.
Más de este canal
 25:50EN
 32:20EN
 45:08EN
 0:32EN
 12:14EN
 10:36EN