En 30 segundos
Matthew Berman examines a 2024 University of Texas at Austin paper on the planning capabilities of o1-preview, o1-mini and GPT-4. The researchers distinguish feasible plans, optimal plans and generalization across changed representations, finding gains for o1-preview in some tasks but persistent failures in more spatially complex ones. The study uses a relatively small dataset and is not a test of real-world robot operation. Berman says randomized Tyreworld success fell to 80%; the paper reports a fall from 100% to 20%.
- 1Three measures of planningThe paper evaluates feasibility, optimality and generalizability across six benchmark domains.
- 2Barman constraintsThe models struggle to follow rules governing hands, containers and action order.
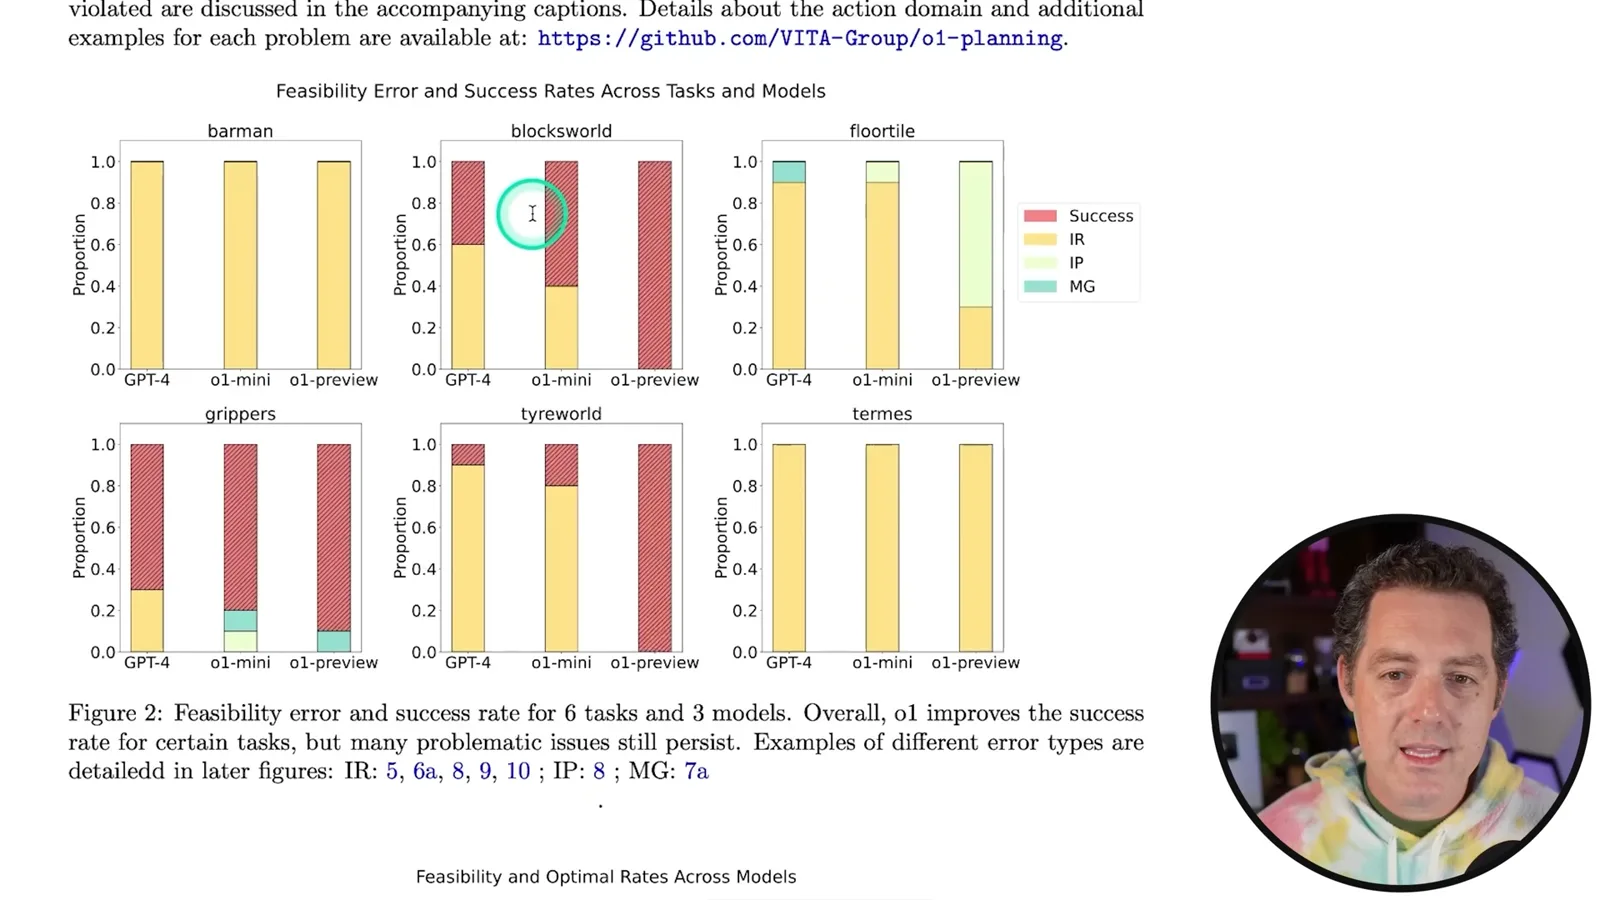
- 3Blocksworld resultsThe paper reports success rates of 40% for GPT-4, 60% for o1-mini and 100% for o1-preview on its test cases; some successful plans are suboptimal.
- 4Spatial failuresAll three models fail the tested Floortile and Termes problems, although their error types differ.
- 5Randomized TyreworldThe paper reports a drop from 100% to 20% success when actions and tools are renamed with arbitrary symbols; Berman says 80% in the video.
- 6Directions for improvementThe authors suggest research into resource-aware planning, memory, self-evaluation, multimodal inputs, multi-agent approaches and human feedback.
Conclusiones
- Feasibility asks whether a plan obeys constraints and reaches the goal; optimality asks how efficiently it does so.
- In the tested Blocksworld problems, o1-preview succeeded on all cases but sometimes took unnecessary steps.
- All three models failed the tested Floortile and Termes cases, illustrating limits in those spatial planning tasks.
- The paper reports o1-preview Tyreworld success dropping from 100% to 20% when action and tool names were randomized.
- The authors identify their small dataset as a limitation and recommend broader testing.
Lee el texto editado por capítulos
A study of planning abilities
Berman introduces o1 and the paper’s framing around planning and spatial reasoning. The study compares models on six benchmark domains.
How good are OpenAI’s o1-preview and o1-mini at planning? Unlike simply scaling a model during training, o1 uses additional computation at inference time. I review a 2024 research paper comparing the models with GPT-4 on tasks designed to expose planning and spatial-reasoning limitations.
I start with the ARC Prize’s distinction between acquiring new skills and merely displaying learned skills. The paper uses six planning domains rather than ARC itself. The tasks are presented as rule-based problems, and their results should not be treated as a direct measure of general intelligence or physical robot performance.
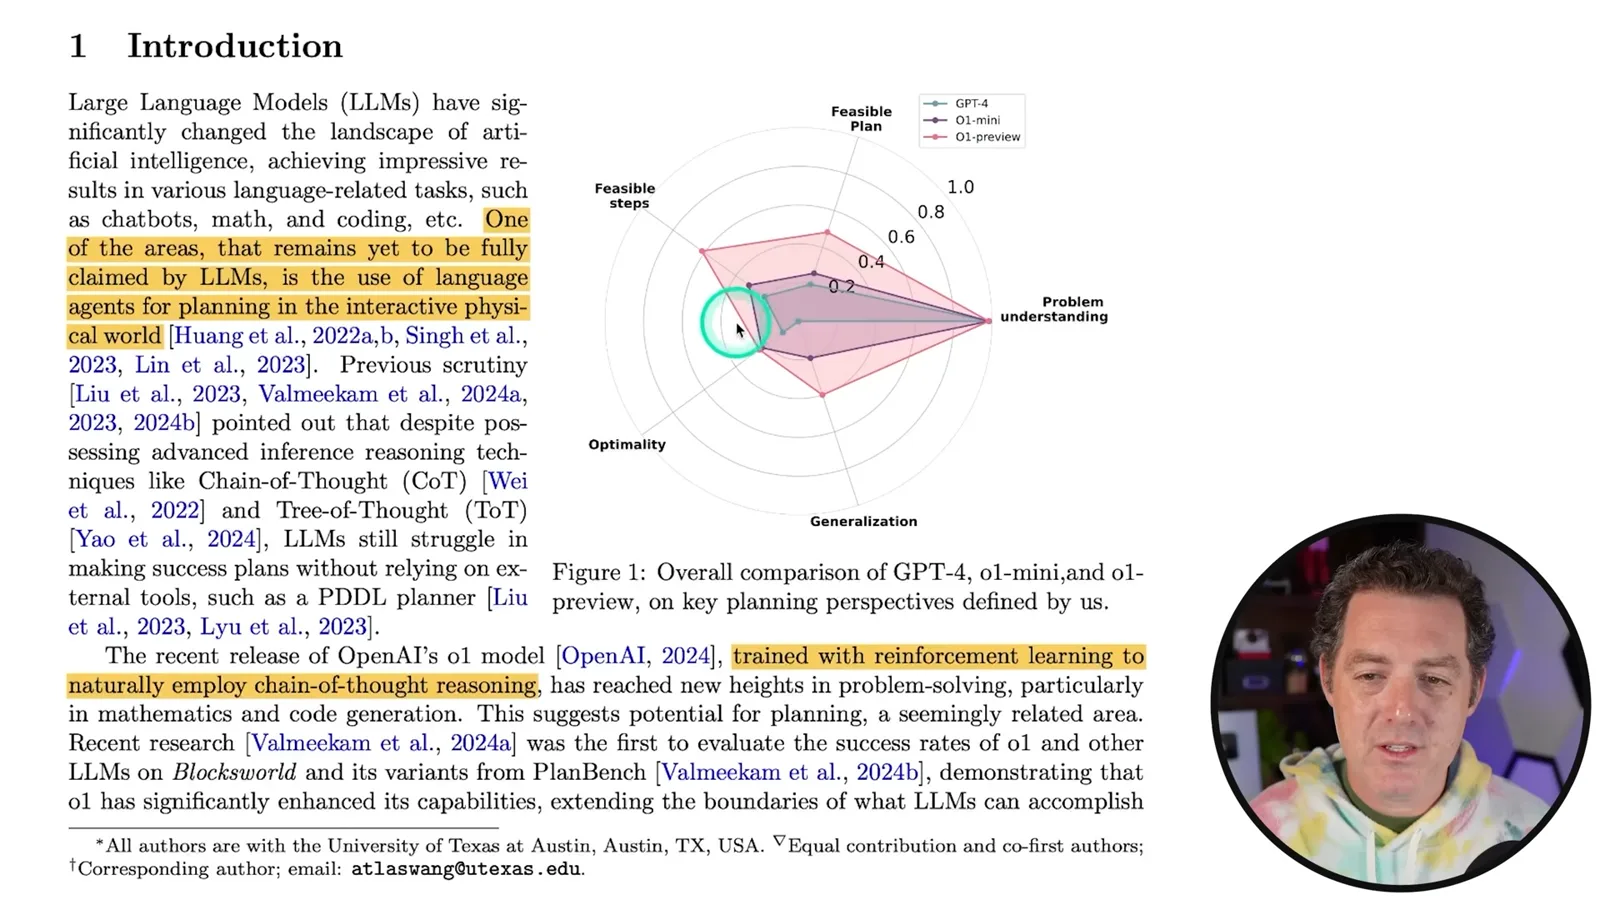
The researchers organize their evaluation around feasibility, optimality and generalizability. They find that o1-preview improves on GPT-4 in some structured cases, but still struggles with decisions and state management, particularly in complex spatial tasks. The authors describe their dataset as relatively small and call for broader testing.
These questions matter for embodied agents: a robot needs to reason about how actions change the physical world. Yann LeCun has argued that language alone may be insufficient for strong spatial reasoning. I mention World Labs and Fei-Fei Li’s work on 3D information as another approach, while noting that the broader question remains open.
The o1 models can use more inference-time compute to reason through an answer. In the paper’s aggregate figure, o1-preview generally compares favorably with GPT-4, although its shortcomings are important too. These results apply to the tested models and tasks in 2024, not necessarily to later systems.
Feasibility, optimality and generalization
He explains valid steps, goal completion, plan efficiency and adaptation to unfamiliar representations.
Feasibility asks whether the plan follows the rules and actually reaches the goal. A proposed action that violates a precondition makes a plan invalid. The paper distinguishes failure to follow rules (IR), failure to form a feasible complete plan (IP), and misinterpretation of the goal state (MG).
Optimality is different: a plan may reach the goal but waste steps, time or resources. Traveling from A through several unnecessary stops before reaching B illustrates the idea. The authors call a feasible but inefficient solution a lack-of-optimality error, or LO.
Generalizability asks whether a model can adapt its planning to changed settings. One experiment replaces meaningful names for actions and objects with arbitrary symbols while retaining the rules. I consider the ability to apply a skill in unfamiliar forms important, but such a test probes one narrow kind of generalization.
Barman, Blocksworld and Grippers
Berman walks through examples of rule violations, unnecessary actions and mistaken goal states.
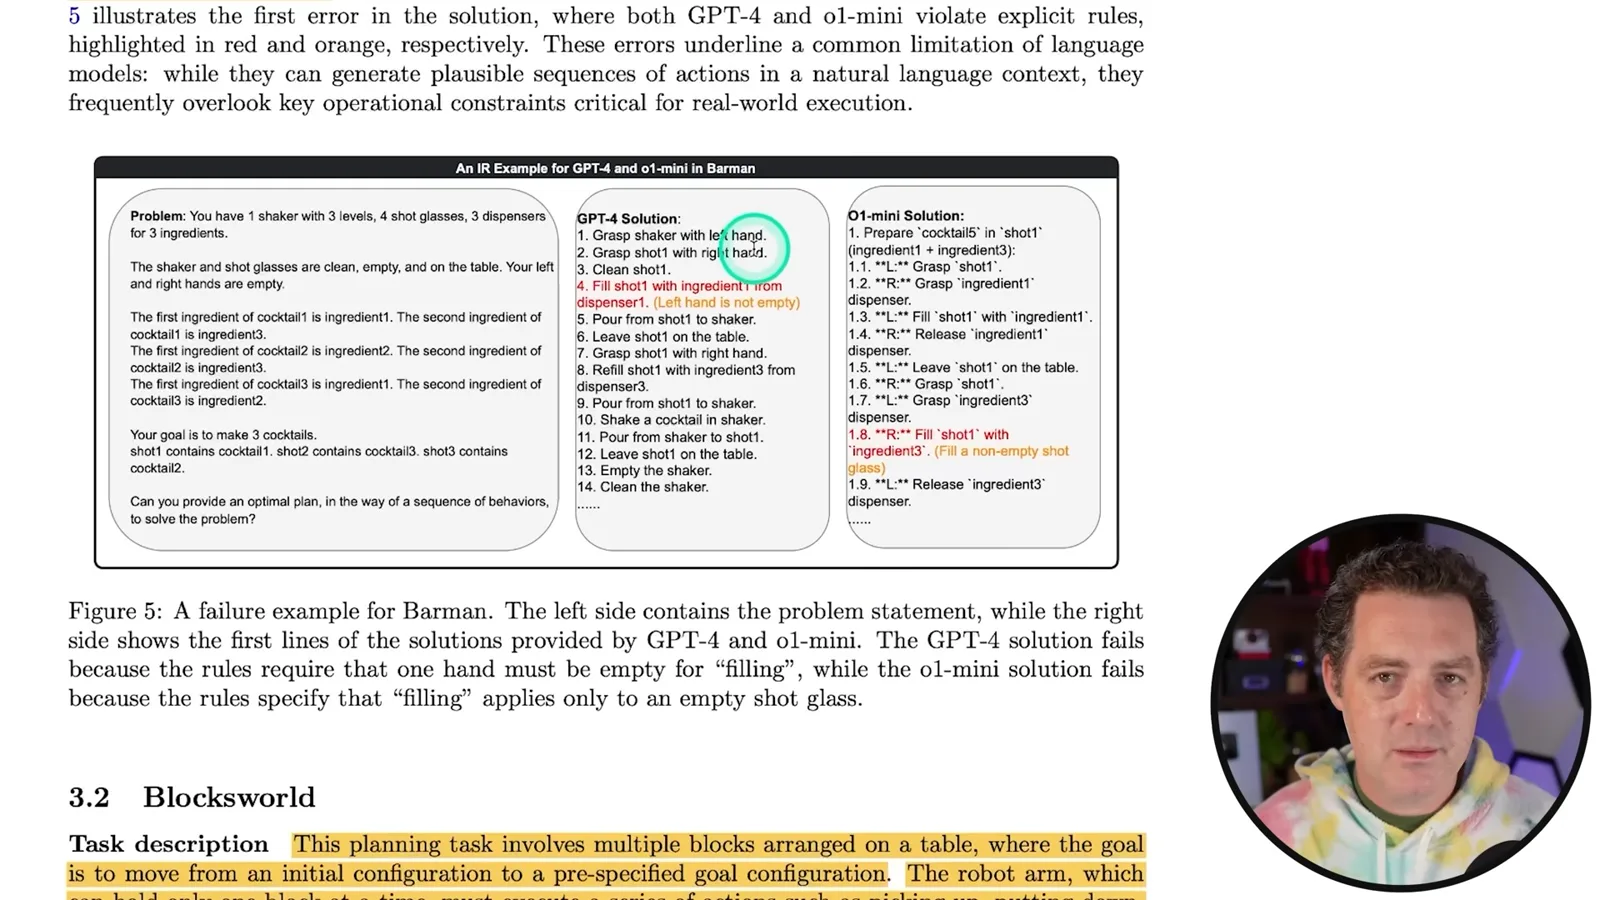
The first domain, Barman, asks a two-handed robot to prepare drinks using dispensers, glasses and a shaker. Each action has preconditions: a hand may need to be free, and the contents and order of operations matter. The models often produce plausible-looking steps that violate these rules.
In the illustrated example, GPT-4 tries to fill a glass while both hands are occupied. o1-mini attempts to fill a shot glass that is already nonempty. The paper says the models struggled to generate feasible Barman plans, with most errors attributed to rule violations.
Blocksworld requires an arm that can hold one block at a time to rearrange a stack into a specified goal. In the paper’s failure example, o1-mini attempts to stack a block while another block still prevents the move. Berman calls it an o1-preview example, but the paper labels it o1-mini.
The paper reports Blocksworld success rates of 40% for GPT-4, 60% for o1-mini and 100% for o1-preview in the evaluated cases. Successful plans were not necessarily optimal: an o1-preview example includes an unnecessary action. These percentages describe the small study, not a guarantee on all block arrangements.
In Grippers, robots move balls between rooms with limited grippers. In one example the initial arrangement already satisfies the goal, but o1-preview misreads it and moves the balls anyway. In another, GPT-4 uses an unnecessary robot movement while o1-mini produces an efficient plan.
Floortile, Termes and Tyreworld
The harder spatial tasks defeat all three tested models. In Tyreworld the paper also tests random substitutions for familiar names.
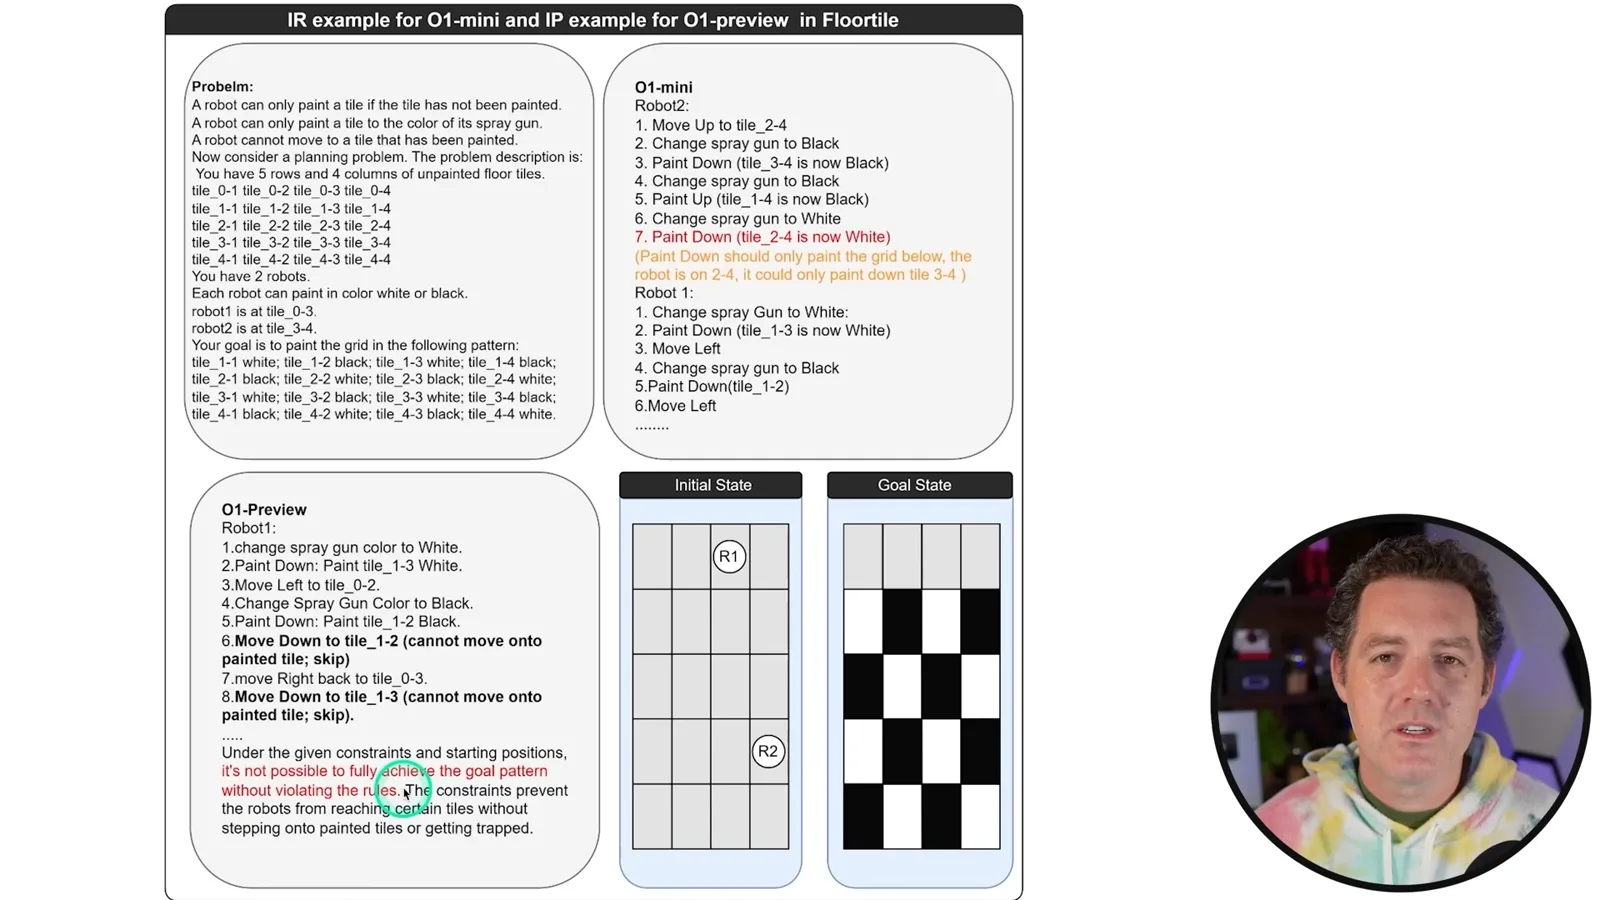
Floortile asks robots to paint a grid while observing movement and painting constraints: they can paint only unpainted tiles and cannot move onto painted ones. All three models failed the tested cases. The paper reports rule-following errors in 90% of GPT-4 and o1-mini failures versus 30% of o1-preview failures; the latter also failed to complete plans.
Termes adds a third dimension: a robot constructs a structure by moving and placing blocks under height and position constraints. All three models failed the tested problems. Errors included ignoring height restrictions and placing blocks at the robot’s own position when the rules required a neighboring position.
Tyreworld describes replacing flat tires with tools in the required order. o1-preview generated valid plans for all of the paper’s ordinary test cases, while GPT-4 and o1-mini struggled beyond the simplest ones. The domain is a symbolic planning benchmark, not a demonstration of changing a real tire.
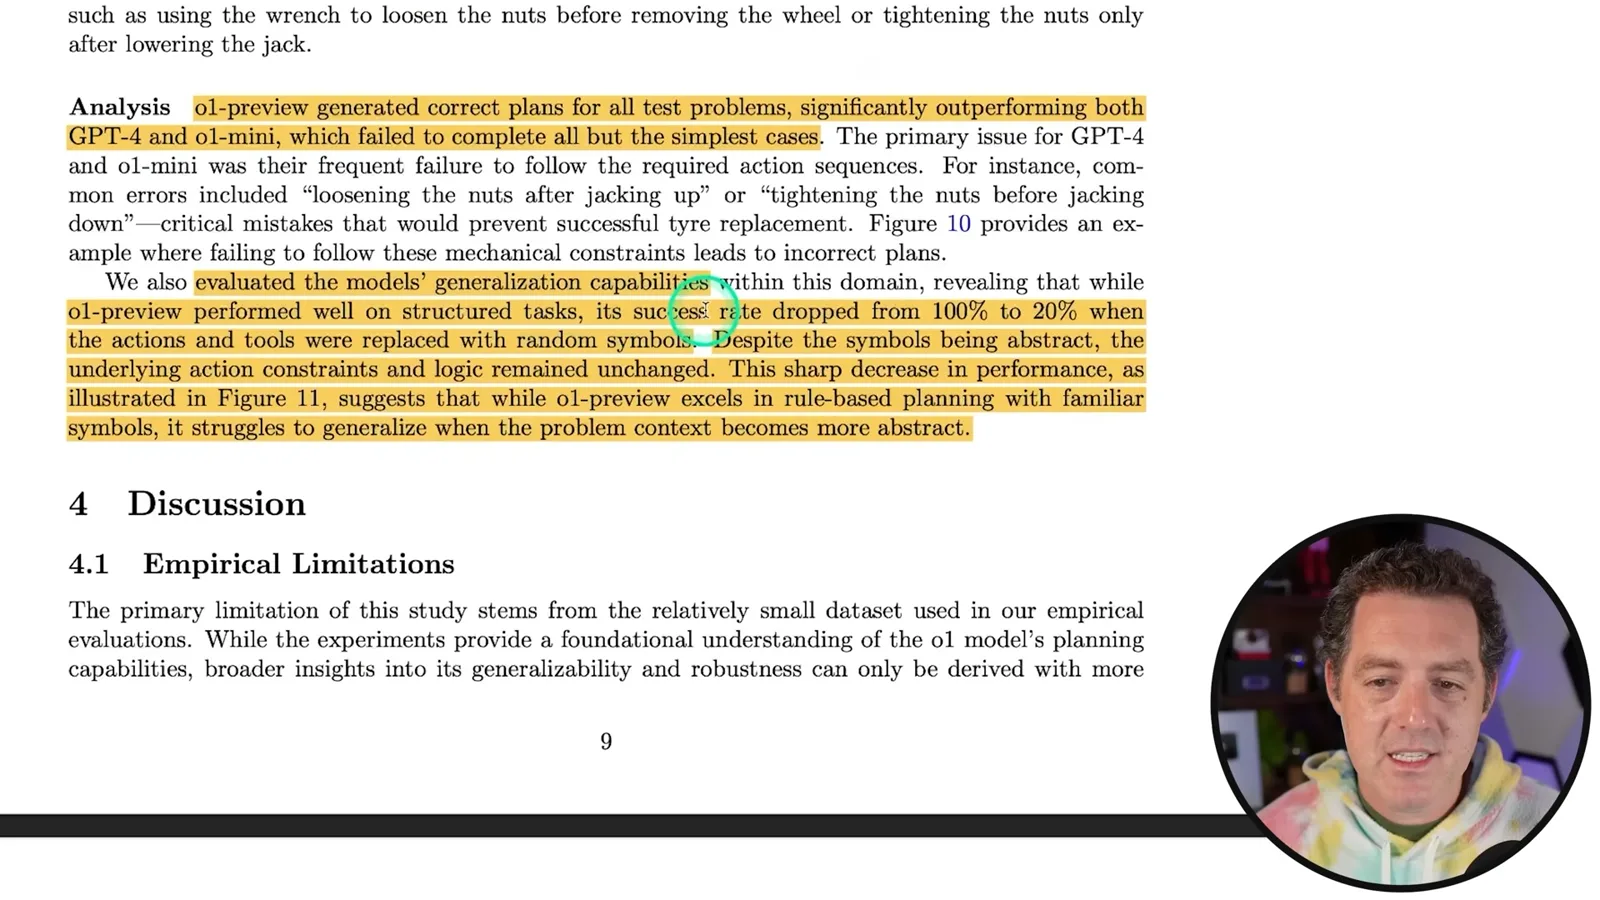
When action and tool names were replaced with random symbols, the underlying rules stayed the same but o1-preview’s performance fell. I say in the video that success dropped from 100% to 80%; the paper and the text on screen instead report a drop from 100% to 20%, an 80-percentage-point decrease.
Interpreting the findings
Berman discusses complexity, constraint-following, efficiency and generalization, then reviews proposed directions for improvement.
The authors associate poorer performance with spatial and rule complexity, particularly in Floortile and Termes. They say action-space size did not appear to be the main factor in their observations. This does not establish that grid size is irrelevant in general; the experiments were limited.
Compared with GPT-4, o1-preview more often follows constraints and tracks state in some structured tasks. The researchers suggest self-evaluation can help, but the exact internal mechanism is not established by these outputs. The advantage weakens when spatial relationships and state transitions become more complicated.
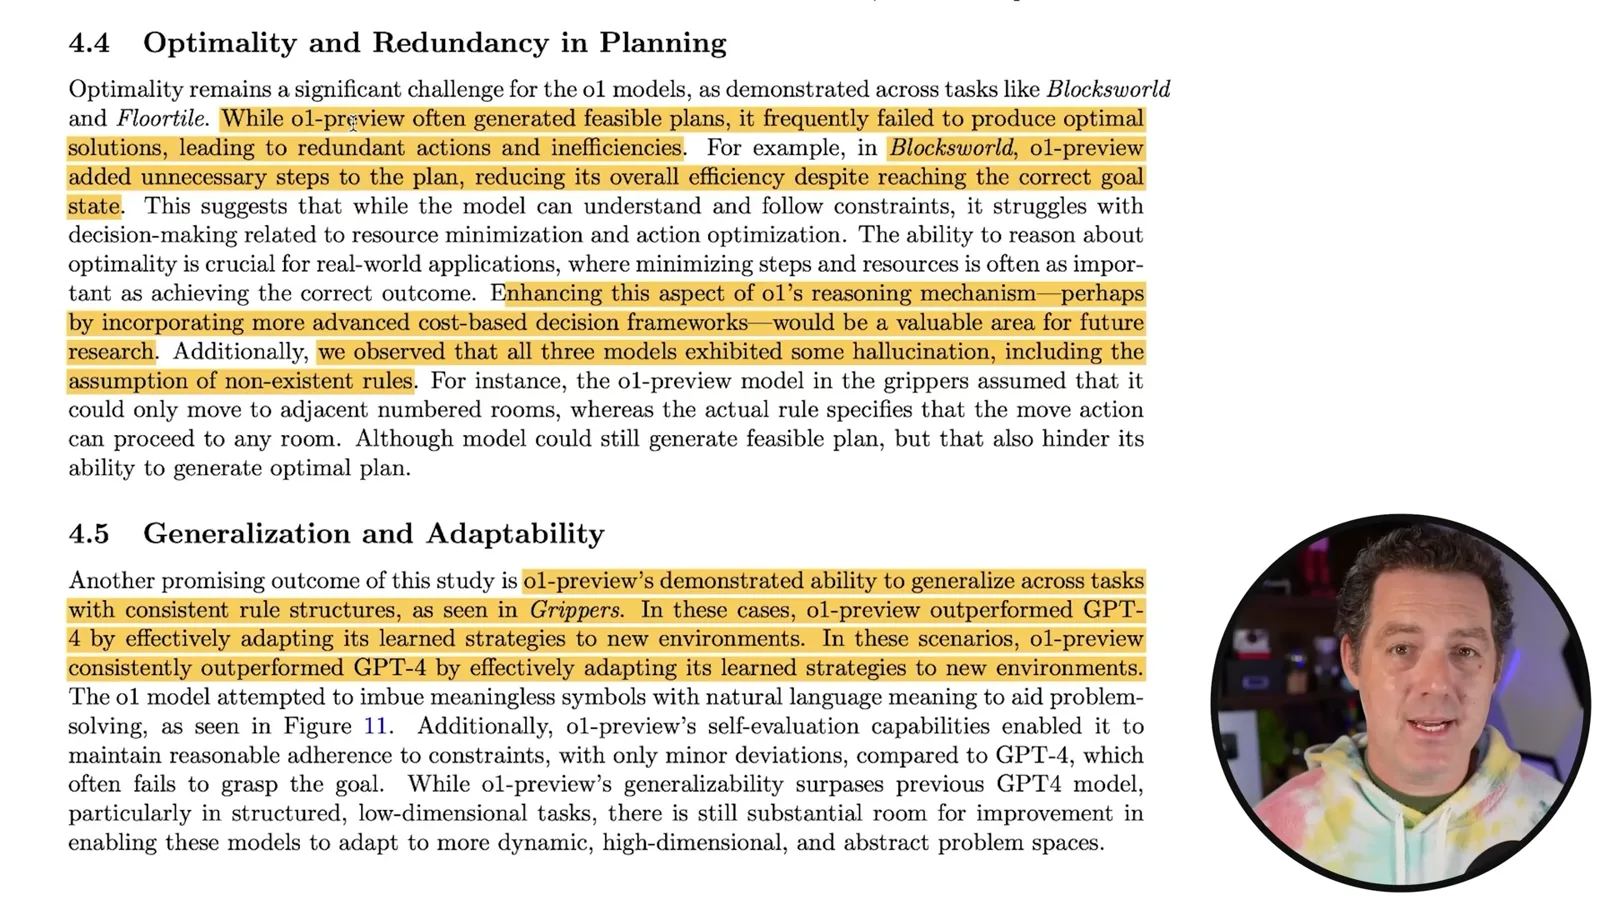
A feasible plan may still contain redundant steps. The paper suggests investigating cost-based decision frameworks to improve optimality. It also sees some evidence of adaptation across structured problems, alongside substantial difficulty with abstract and more complex settings.
The study summarizes improvements in understanding requirements, following constraints and managing states in some tasks. At the same time, performance remains weaker in higher-dimensional and abstract problems. I see the ability to generalize as an important open challenge.
The paper proposes several research directions: better resource-aware decisions, improved memory, self-evaluation, multimodal input, multi-agent frameworks and human feedback. I am particularly enthusiastic about agents working together. These are proposed avenues for improvement, not results shown to solve the benchmark failures.
My takeaway is that the o1 models made gains in some planning tasks but still have significant limitations. I use generalization as a way to think about progress toward general intelligence, while the study itself remains a narrow pilot evaluation.
Más de este canal
 34:21EN
 Matthew Berman· 27 oct 2026Matthew Berman Examines Anthropic’s IPO Filing, AI Growth and GovernanceMatthew Berman, Sam Altman · Forward FutureThe presenter reviews the S-1’s financial metrics, compute strategy and voting structure while questioning the tension between rapid AI development and safety.
 0:36ENMatthew Berman· 25 oct 2026Kimi K3.1 and a Rubik’s Cube Solver DemonstrationMatthew Berman · Forward FutureMatthew Berman shows a scrambled virtual cube being solved and gives the Kimi K3.1 test a favorable assessment.
 25:50ENMatthew Berman· 24 oct 2026Kimi K3.1 Pro Tested: Strong 3D Demos, Uneven Results and Competitive PricingMatthew Berman · Forward FutureMatthew Berman tests the open-weight model on coding, 3D rendering and visual explanations, then compares benchmark results and prices.
 32:20ENMatthew Berman· 23 oct 2026Who Is Local AI For? The Costs, Trade-offs and a Hybrid FutureMatthew Berman · Forward FutureMatthew Berman weighs data control and independence against hardware cost, setup complexity and inference speed.
 1:03:37ENMatthew Berman· 23 oct 2026Matthew Berman’s Team Tests Kimi K3.1 on Animation, Games, and ChartsMatthew Berman, Alex, Brian · Forward FutureA live team AMA turns into an informal test of Kimi K3.1, from personal-agent workflows to motion graphics, a browser game, and a benchmark chart.
 0:53ENMatthew Berman· 22 oct 2026Sam Altman on AI and the Discovery of New KnowledgeSam Altman · OpenAIAltman expects progress in mathematical discovery to extend to biology, materials and energy.