En 30 segundos
In January 2025, Matthew Berman tests DeepSeek R1 through Open WebUI on infrastructure provided by video sponsor Vultr. He finds working examples of Snake and Tetris and favorable answers on several reasoning puzzles, then observes a refusal about Tiananmen and a one-sided answer about Taiwan. These are individual observations under one configuration, not a comprehensive benchmark or proof of exactly how the model or hosting stack produced the responses.
- 1Full R1 on cloud hardwareBerman uses Open WebUI with a sponsor-provided Vultr deployment; the developer reports 671B total and 37B activated parameters.
- 2Generating SnakeThe model generates a playable Python Snake game in Berman’s single attempt.
- 3Tetris after a long responseThe generated game runs and clears lines, although it has no score or next-piece preview.
- 4A unit-conversion puzzleThe model converts millimeters to centimeters and considers envelope orientation in Berman’s example.
- 5Sensitive-topic testsThe tested deployment refuses one historical question and gives a one-sided Taiwan response; Berman’s conjecture about the mechanism remains unverified.
Conclusiones
- The full DeepSeek R1 mixture-of-experts model has 671 billion total parameters and approximately 37 billion active per token.
- Berman runs the model on eight cloud GPUs supplied by sponsor Vultr and observes its generated reasoning text.
- His one-shot Snake and Tetris examples run, although the latter lacks scoring and a next-piece preview.
- Several logic examples receive passes, but the small and subjective test set does not establish flawless performance.
- The sensitive-topic results show what this setup returned for specific prompts; they do not identify the precise source of the behavior.
Lee el texto editado por capítulos
Setup and game programming
Berman introduces the sponsored cloud setup and inspects R1’s generated reasoning. He tries Snake and Tetris programs.
I am testing the full DeepSeek R1 reasoning model against my usual collection of prompts. Vultr sponsors this video and provides the cloud GPUs used for the demonstration. The full model has 671 billion total parameters; DeepSeek reports roughly 37 billion active per token in its mixture-of-experts architecture.
The model runs on a cloud machine through Open WebUI, rather than DeepSeek’s own hosted chat interface. As a basic check, I ask how many times the letter R appears in “strawberry.” The model displays text inside thinking tags and correctly answers three.
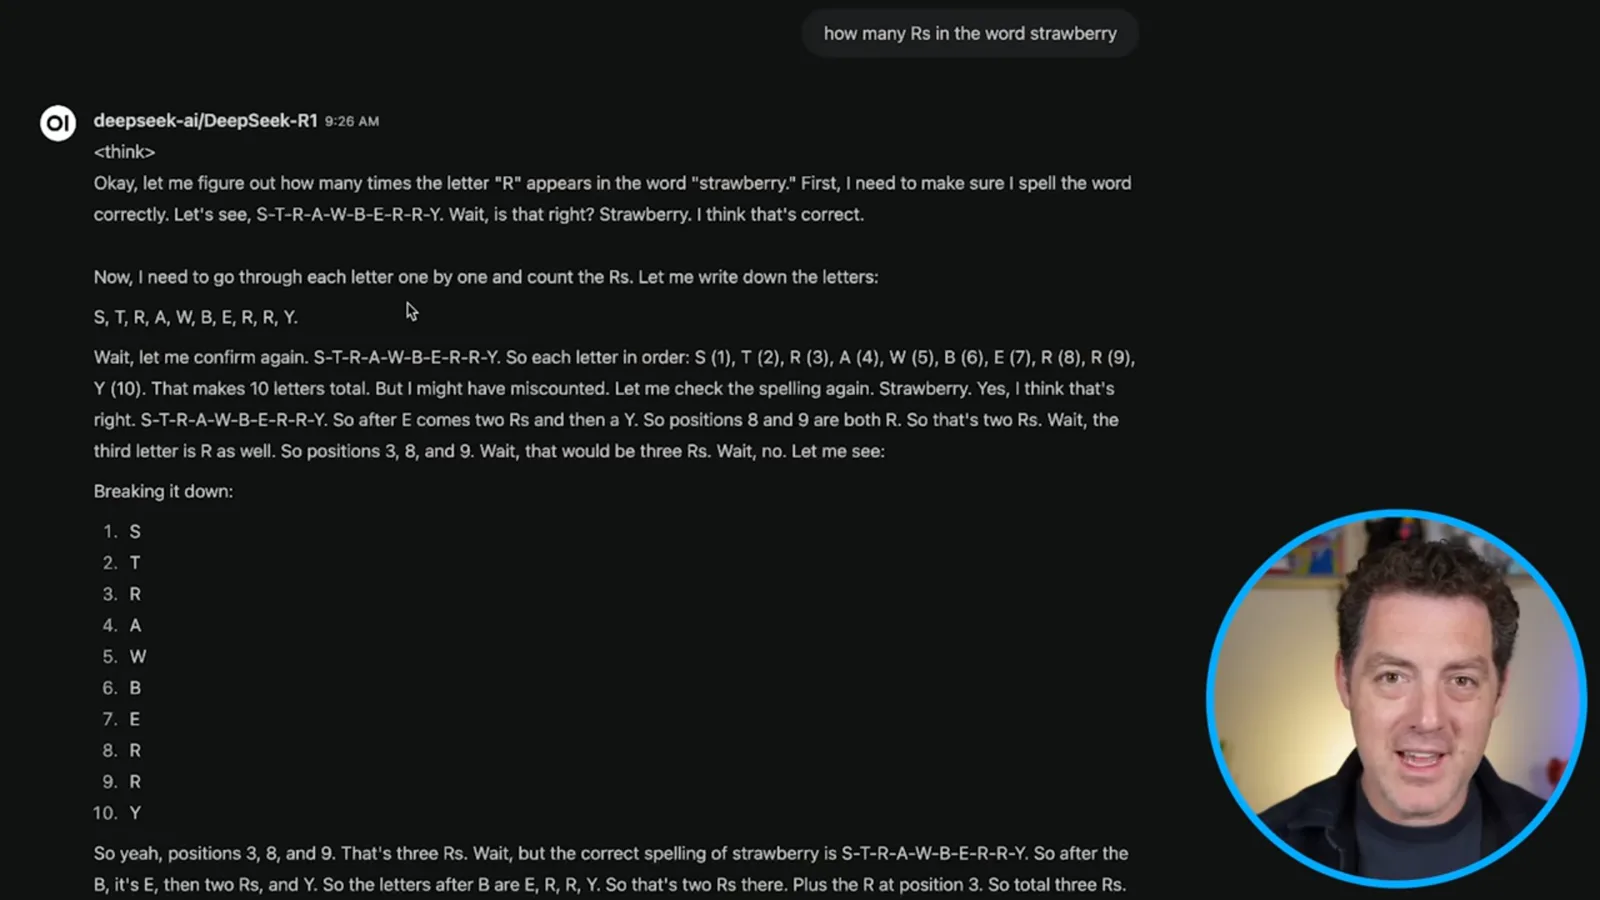
I find the visible back-and-forth interesting because the generated text revisits and checks its answer. It reads to me like a human internal monologue, although the text alone does not establish that its internal process is human-like or that every explanation faithfully represents how the answer was produced.
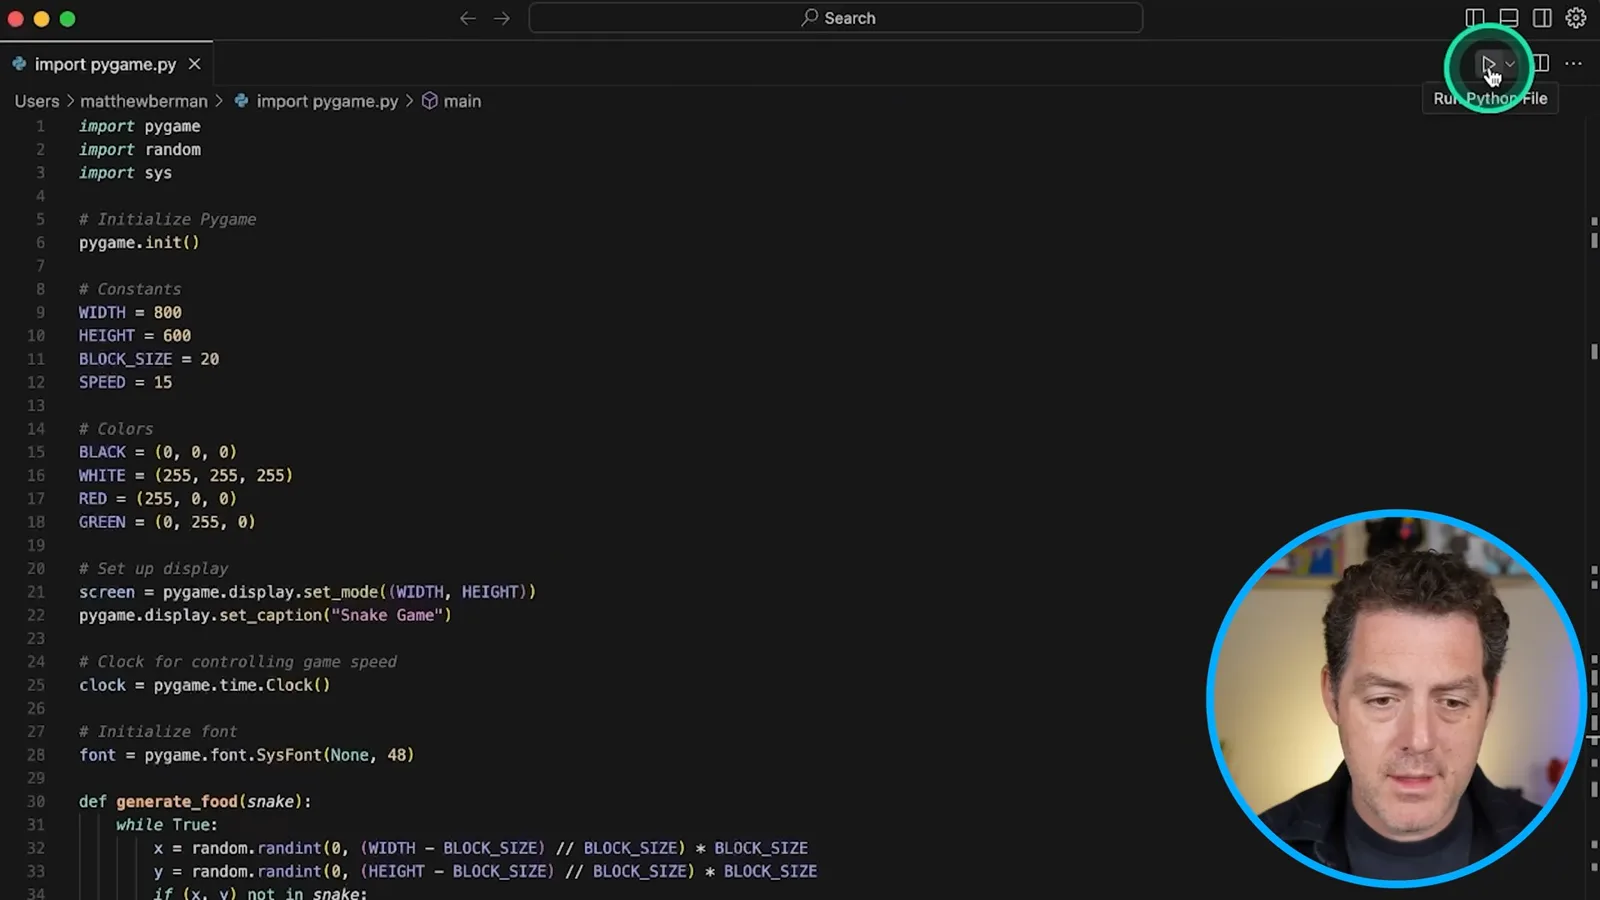
For a first coding challenge, I ask for Snake in Python. R1 outlines an approach using Pygame, then outputs code and instructions. I copy the program into my local editor and run it: the movement, score and restart behavior appear to work in this demonstration, so I give it a pass.
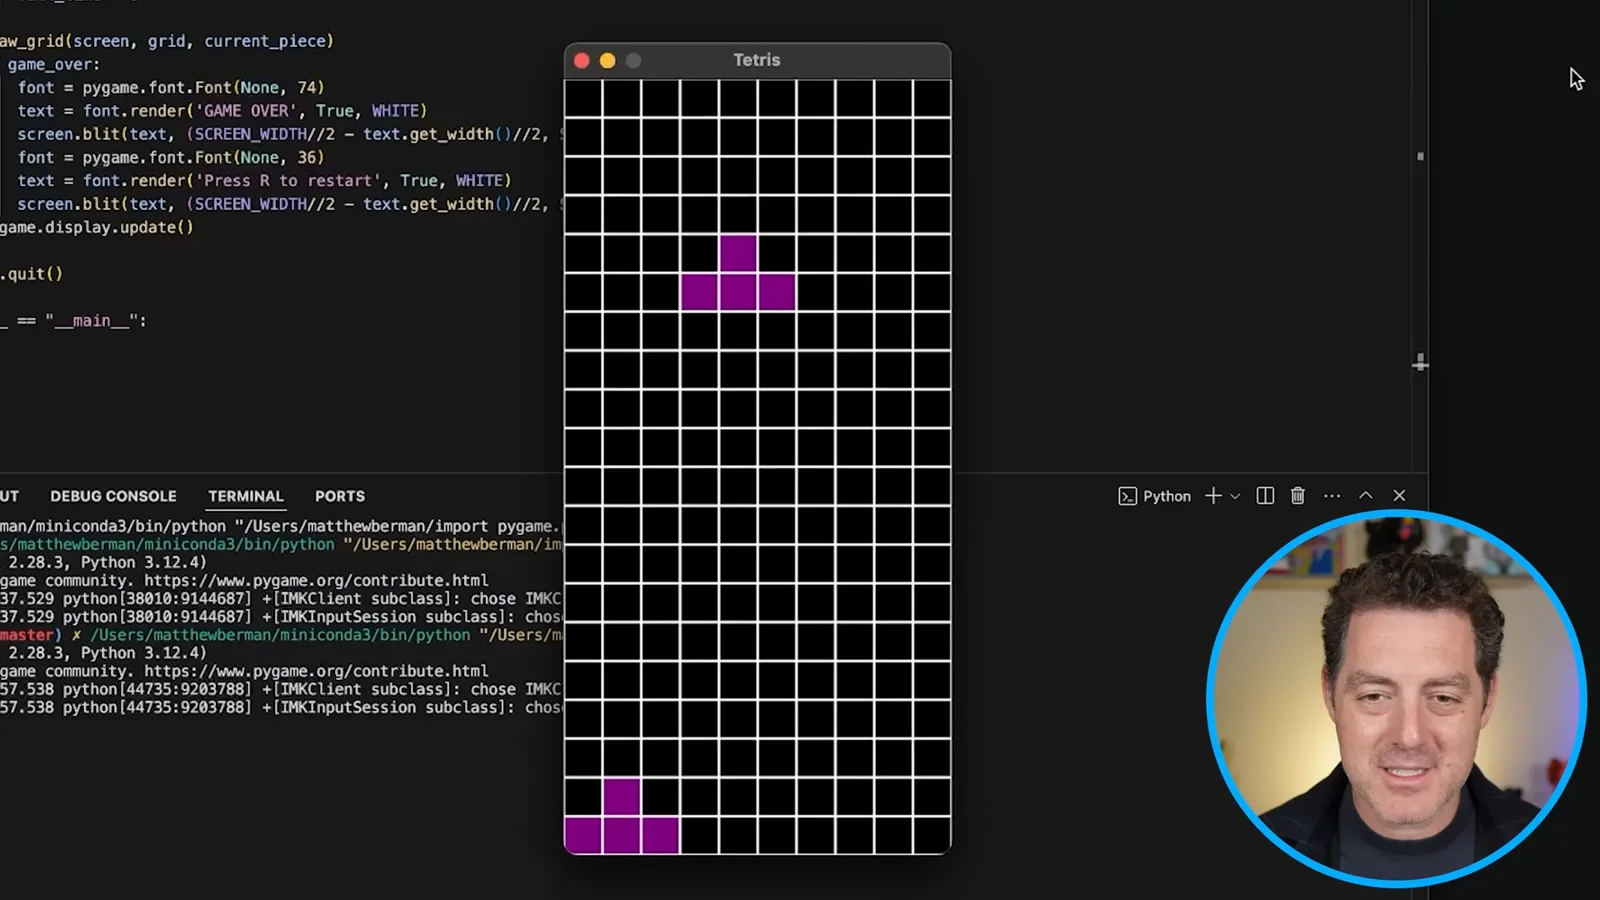
Next I ask for Tetris, a harder task in my personal rubric. The model spends time laying out pieces, collisions and rotation before producing a 179-line program. I am impressed by the attention to edge cases, although this is a single output rather than a controlled comparison of models.
After several minutes of generation, I run the program. Pieces appear and completed lines clear; I notice it does not keep score or preview the next piece. I still count the example as a pass because the main game works in my brief test.
The sponsored Vultr system shown has 128 CPU cores and eight AMD Instinct GPUs, each with 192 GB of GPU memory. That describes the hardware used in this run, not the only possible configuration for R1 or smaller distilled models. The promotion mentioned in the video was a January 2025 offer.
Logic and numerical puzzles
He tests envelope dimensions, self-referential word count, killers, a marble and decimal comparison. The passes are his judgments of individual examples.
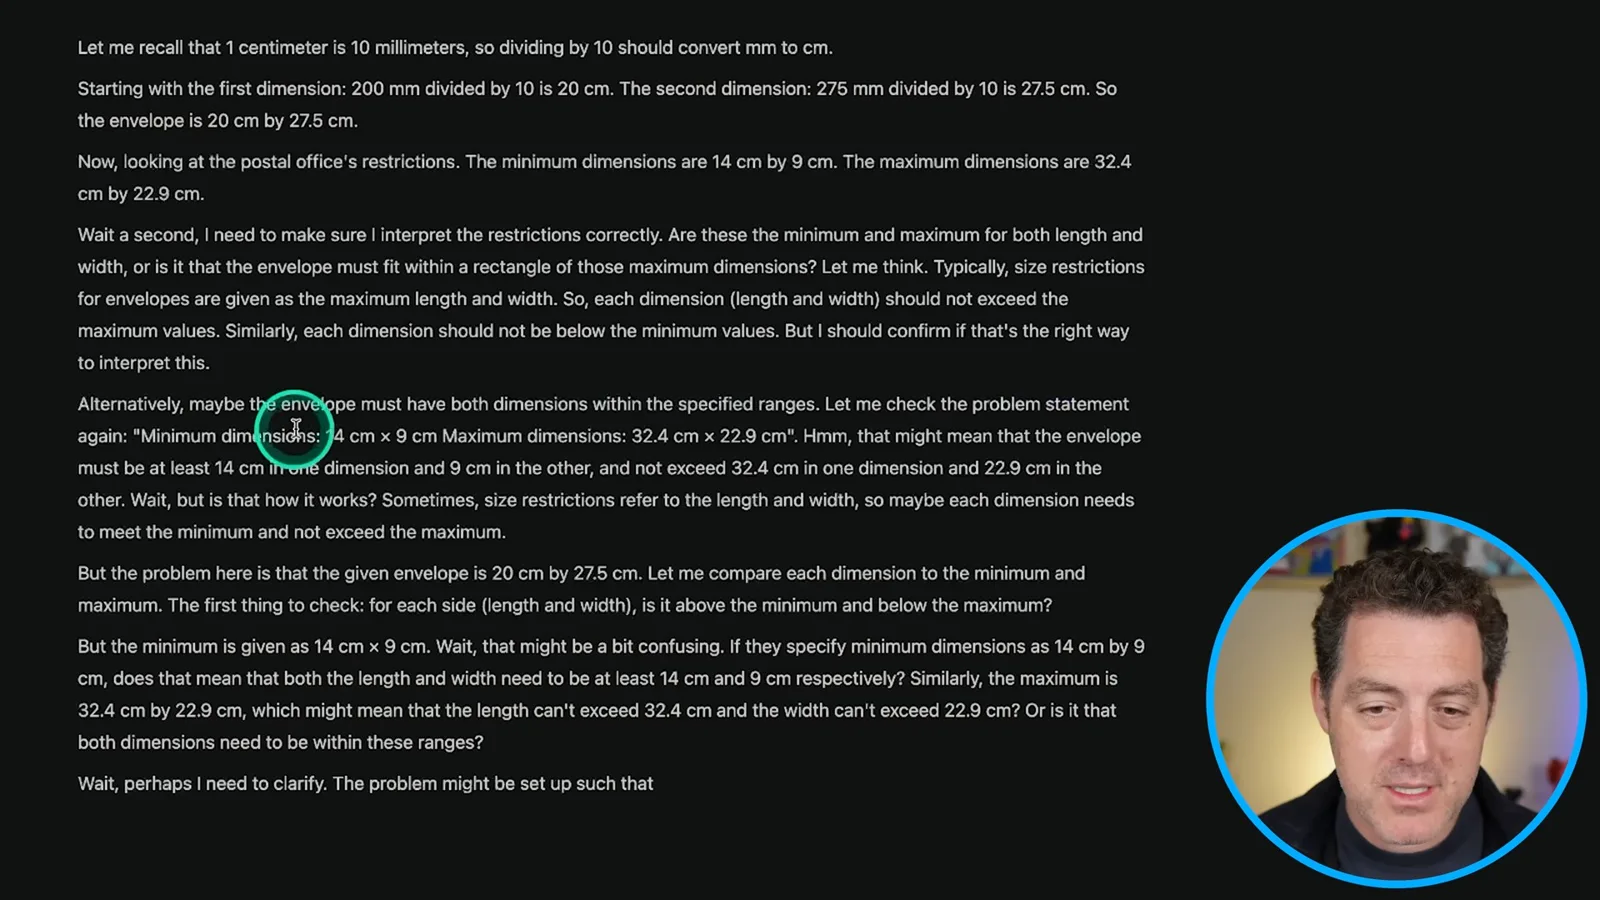
For a postal-envelope puzzle, the model converts a 200-by-275-millimeter envelope to 20 by 27.5 centimeters and considers how to orient it against the stated minimum and maximum dimensions. It concludes that the envelope fits, which I count as a pass for the dimensions given in the prompt.
I ask the self-referential question of how many words are in the response. The model considers several possible wordings and answers with a seven-word sentence, followed by an explanation. I count that as a pass by treating the sentence as the answer, though counting the entire response could lead to a different judgment.
In the three-killers puzzle, the model reasons that the person entering and killing one of the original three becomes a killer too. It answers three living killers, while discussing possible ambiguity about counting the deceased person. I like that the displayed reasoning considers the assumptions rather than only producing a number.
The model also answers the inverted glass and marble puzzle: when the glass is lifted and moved, the marble remains on the table under the ordinary assumptions. In a decimal comparison, it correctly identifies 9.9 as larger than 9.11 by writing 9.9 as 9.90.
Sensitive topics and conclusion
Berman tests politically sensitive questions in his deployment and a separate safety-related prompt. He ends with a sentence-generation test and his overall assessment.
I then test politically sensitive questions in this self-hosted deployment. It refuses a question about Tiananmen Square and gives a one-sided response reflecting the Chinese government’s position when asked about Taiwan. These are outputs for particular prompts, not a complete assessment of the model’s political behavior.
I had heard that restrictions might apply only to the hosted service, but this deployment also produces a refusal. I speculate that the Taiwan response may be hardcoded because the displayed thinking section is empty. The demonstration does not establish whether the behavior comes from model training, prompts, serving software or another part of the configuration.
I contrast this with a separate request about committing a crime and observe that the model appears willing to answer. A refusal to provide harmful instructions is a safety behavior, not automatically a reasoning failure; one prompt also cannot establish the model’s overall safety profile.
For the final prompt, I ask for ten sentences ending in “apple,” and the displayed results satisfy that requirement. I come away impressed by these selected tests and the visible reasoning. My description of the performance as flawless is a personal assessment of a small sample, not a comprehensive measurement.
Más de este canal
 34:21EN
 Matthew Berman· 27 oct 2026Matthew Berman Examines Anthropic’s IPO Filing, AI Growth and GovernanceMatthew Berman, Sam Altman · Forward FutureThe presenter reviews the S-1’s financial metrics, compute strategy and voting structure while questioning the tension between rapid AI development and safety.
 0:26ENMatthew Berman· 25 oct 2026Sam Altman on Human Values and Problem-Solving in an AI WorldSam Altman · OpenAIIn a short interview excerpt, Altman considers the enjoyment of solving hard problems and the human role in interpreting results.
 0:36ENMatthew Berman· 25 oct 2026Kimi K3.1 and a Rubik’s Cube Solver DemonstrationMatthew Berman · Forward FutureMatthew Berman shows a scrambled virtual cube being solved and gives the Kimi K3.1 test a favorable assessment.
 0:21ENMatthew Berman· 24 oct 2026An AI-Generated Kimi Benchmark Chart Used Invented ScoresMatthew Berman · Forward FutureMatthew Berman asks for a graph of Kimi K3.1 Pro benchmarks, then discovers that the displayed figures are illustrative placeholders.
 25:50ENMatthew Berman· 24 oct 2026Kimi K3.1 Pro Tested: Strong 3D Demos, Uneven Results and Competitive PricingMatthew Berman · Forward FutureMatthew Berman tests the open-weight model on coding, 3D rendering and visual explanations, then compares benchmark results and prices.
 32:20ENMatthew Berman· 23 oct 2026Who Is Local AI For? The Costs, Trade-offs and a Hybrid FutureMatthew Berman · Forward FutureMatthew Berman weighs data control and independence against hardware cost, setup complexity and inference speed.