In 30 seconds
Matthew Berman tests OpenAI's o3-mini-high in ChatGPT shortly after its January 2025 launch, trying coding, spatial reasoning, word tasks and web search. He likes the results overall, but his informal prompts are a small sample rather than a controlled benchmark. Several puzzles depend on interpretation: the killer count changes depending on whether dead people count, and the North Pole question does not specify the path and meaning of ‘starting point’ clearly enough to support a simple verdict. Yandex sponsored a segment promoting YaFSDP.
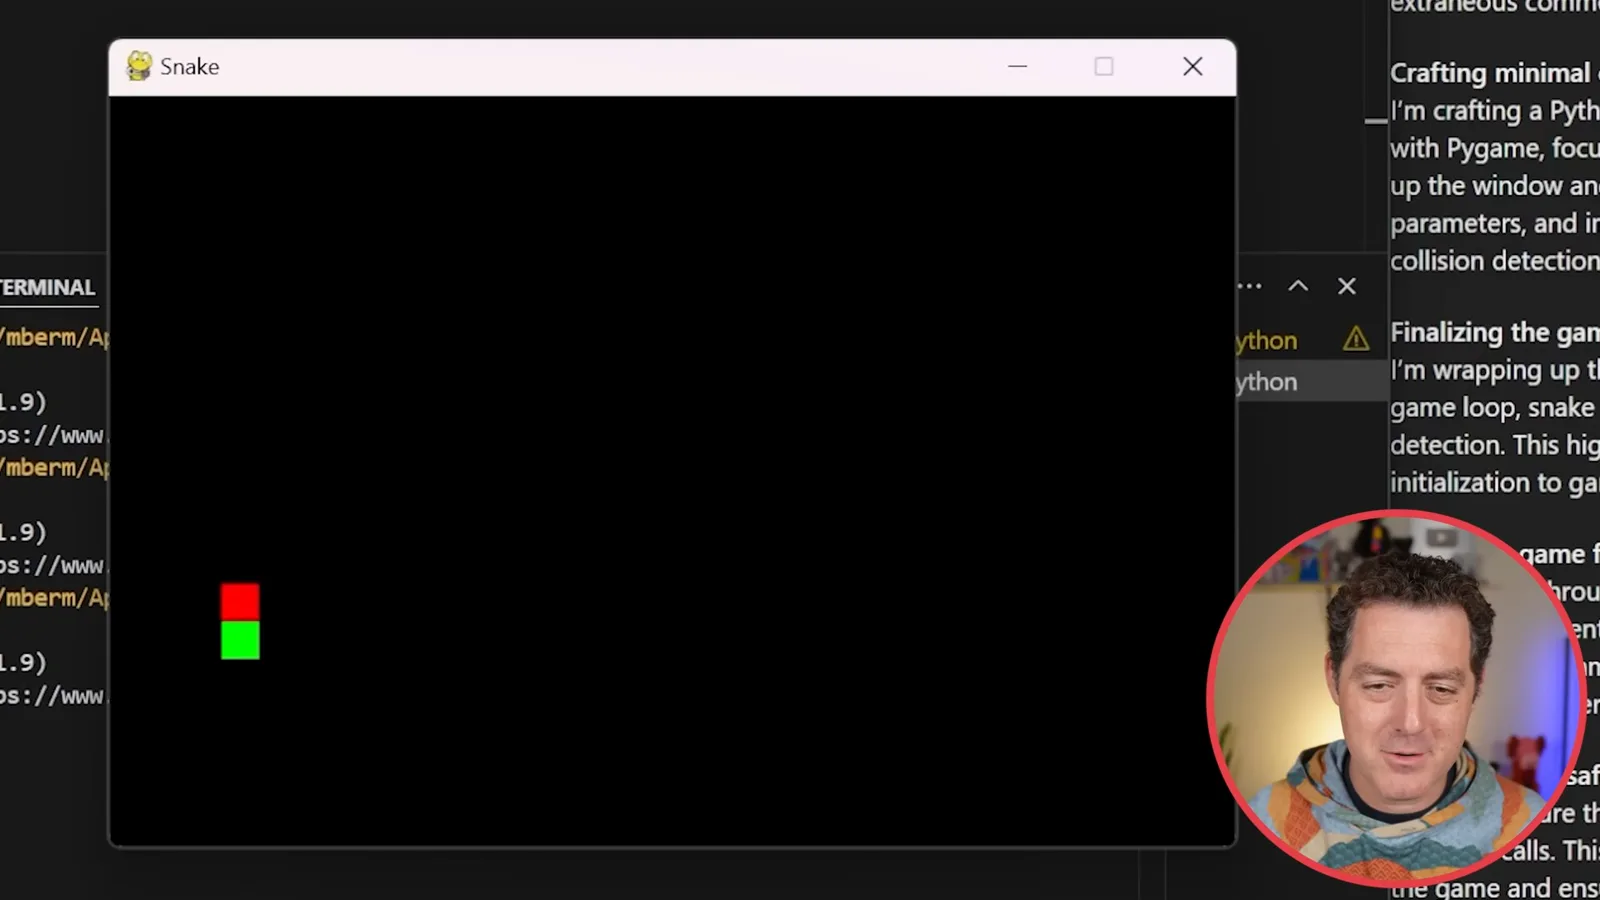
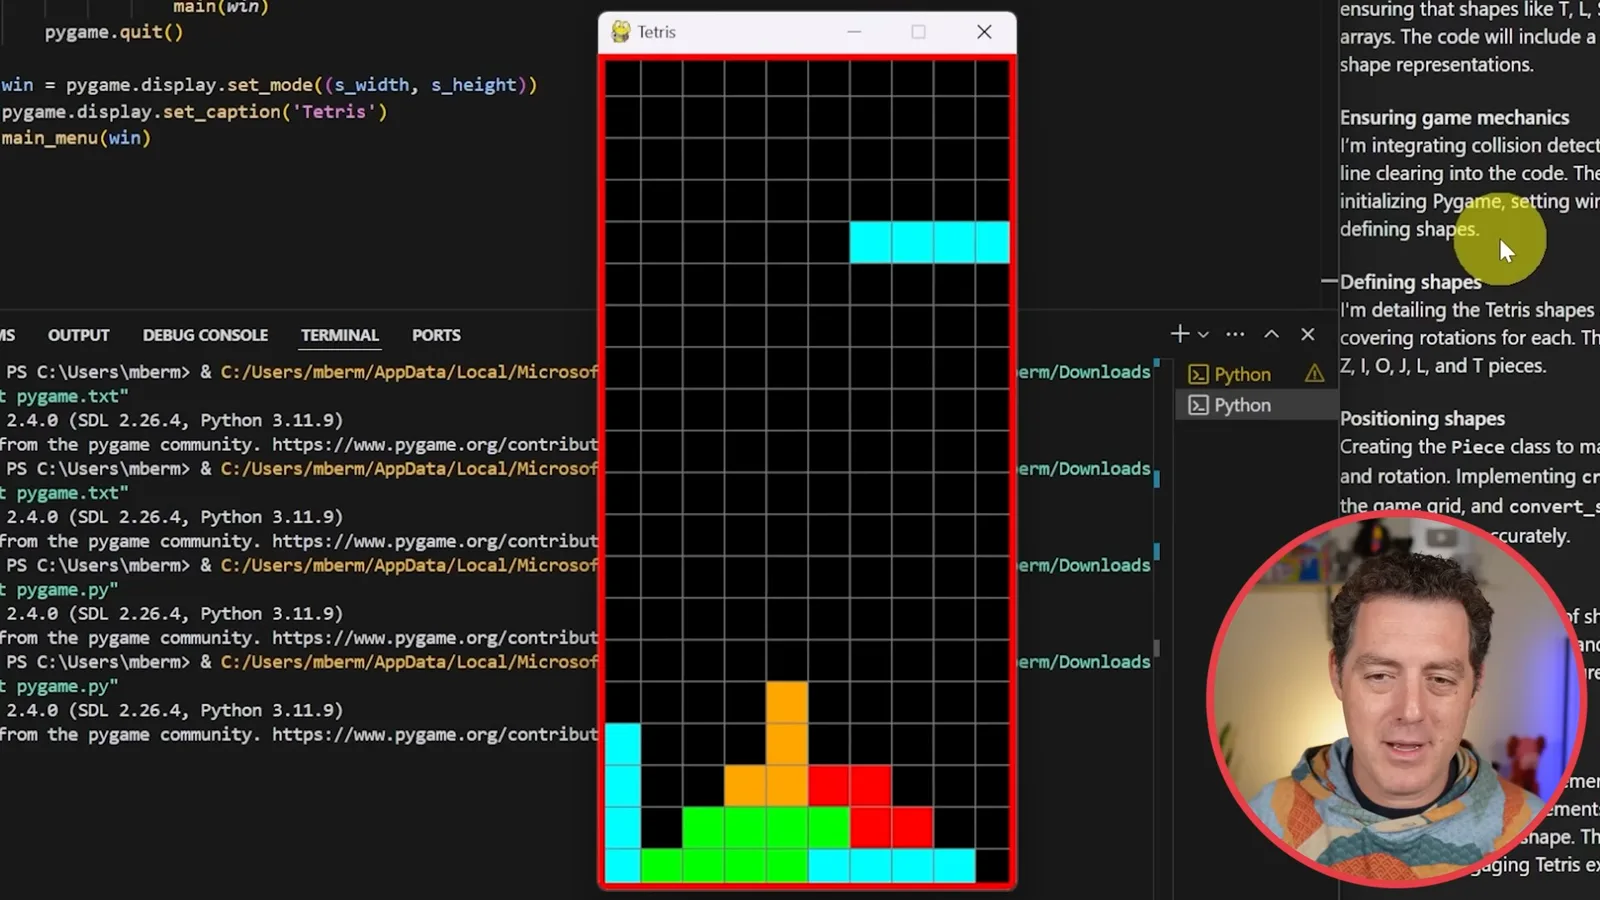
- 1Two game prototypesSnake runs in a short test. Tetris is playable, but Berman observes a delayed line clear.
- 2Envelope dimensionsA 200 × 275 mm envelope fits the stated limits after matching its longer and shorter sides appropriately.
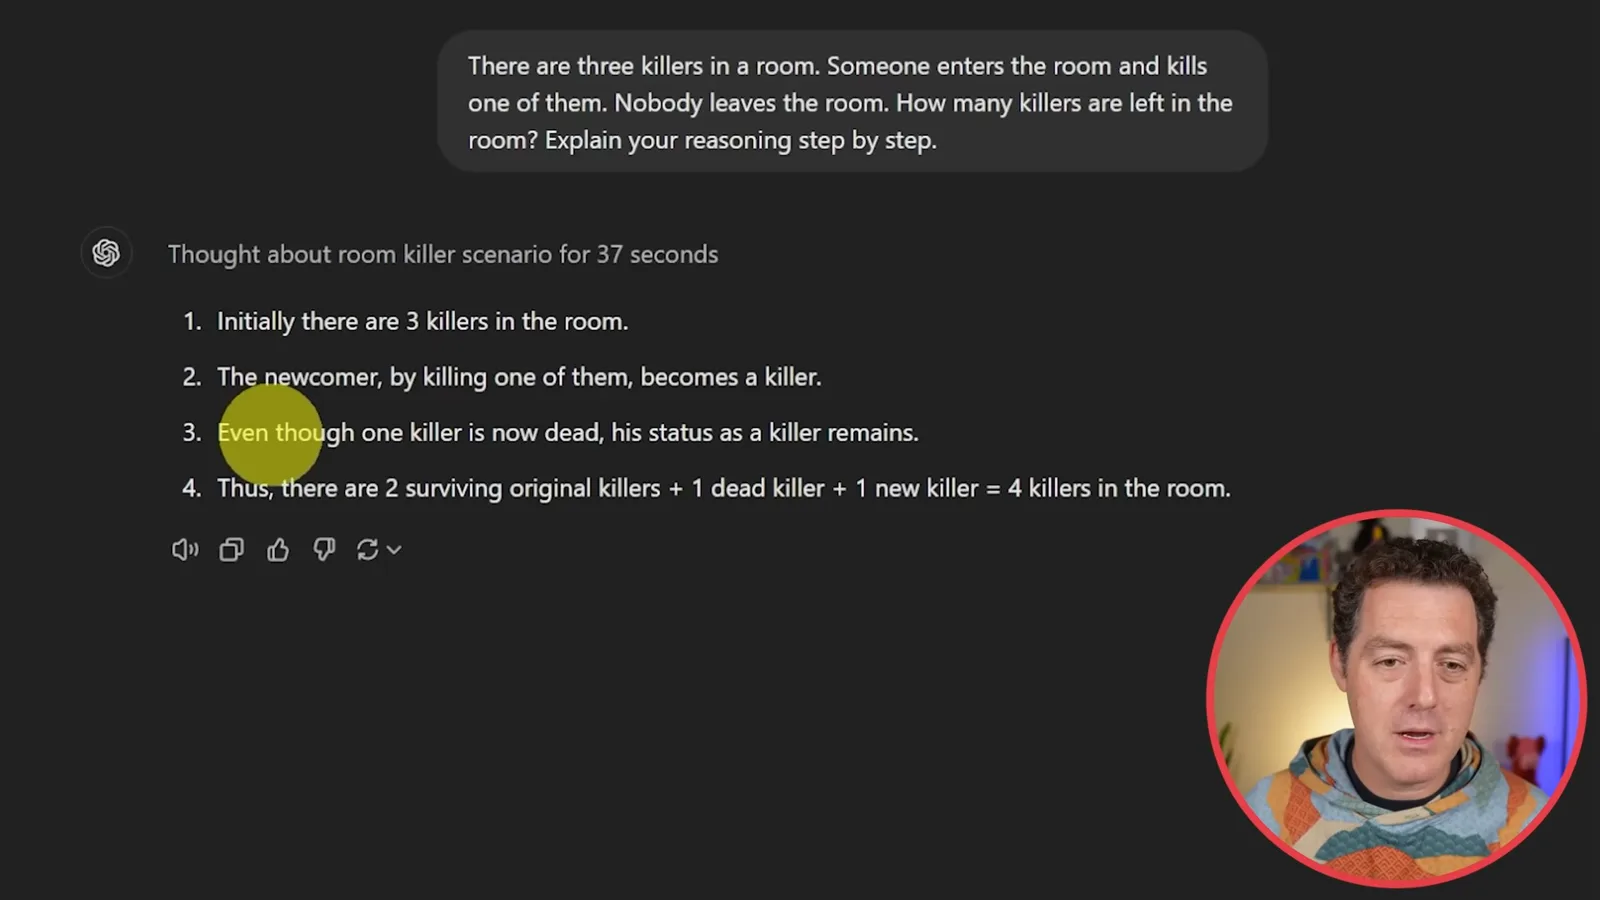
- 3Killer-count ambiguityThe model counts the deceased killer as well as the new arrival, producing four; counting only living people gives three.
- 4North Pole geometryThe model answers exactly 2π km and Berman disagrees. The prompt's path and starting point require clarification before assigning a unique answer.
- 5Search switched onThe first UFC answer lacked current information because search was off; Berman enables it and retries.
Takeaways
- The generated Snake game worked in Berman's short play test; Tetris ran but cleared a completed row one piece late.
- A policy flag interrupted the self-referential word-count question, while the model gave plausible answers to the envelope, marble and spelling prompts.
- The killer puzzle admits three living killers or four people who have killed if the deceased person is counted.
- The North Pole answer depends on whether the path is a great circle or a latitude circle and on which point is meant by the starting point.
- Search was initially disabled in the UFC query; Berman retried with search on and reported a correct historical result.
- Yandex sponsored the video and its YaFSDP performance comparisons are sponsor claims, not results of this model test.
Read the edited text by chapter
Snake and Tetris
Berman tests o3-mini-high with Python game prompts. Both programs run, though Tetris exhibits a delayed line clear.
I am testing o3-mini-high in ChatGPT, with an emphasis on coding and other STEM-style problems. OpenAI introduced o3-mini on January 31, 2025 and described adjustable reasoning effort and an early search integration in its [launch announcement](https://openai.com/index/openai-o3-mini/). This video is a snapshot of that release, not a comprehensive evaluation.
First I ask for Snake in Python. ChatGPT displays a reasoning summary, not the model's full internal chain of thought. The code appears quickly; I run it, collect a piece and hit a wall to end the game. In this brief test the game works, although it moves very fast.
For a harder coding task I request Tetris in Python. The reasoning stage seems slower than for Snake, while the final code appears quickly. I cannot see the hidden reasoning or its token rate, so the visible output speed does not establish how fast the internal computation ran.
The roughly 293-line program runs and the pieces move as expected, including movement after a piece reaches the floor. When I complete a row, however, it does not clear until the next piece arrives. I give the one-shot attempt a qualified pass while noting that bug and the immediately challenging speed.
Dimensions and logic puzzles
The model answers an envelope question, encounters a policy flag on a word-count prompt and interprets a killer puzzle. Yandex sponsors an intervening YaFSDP segment.
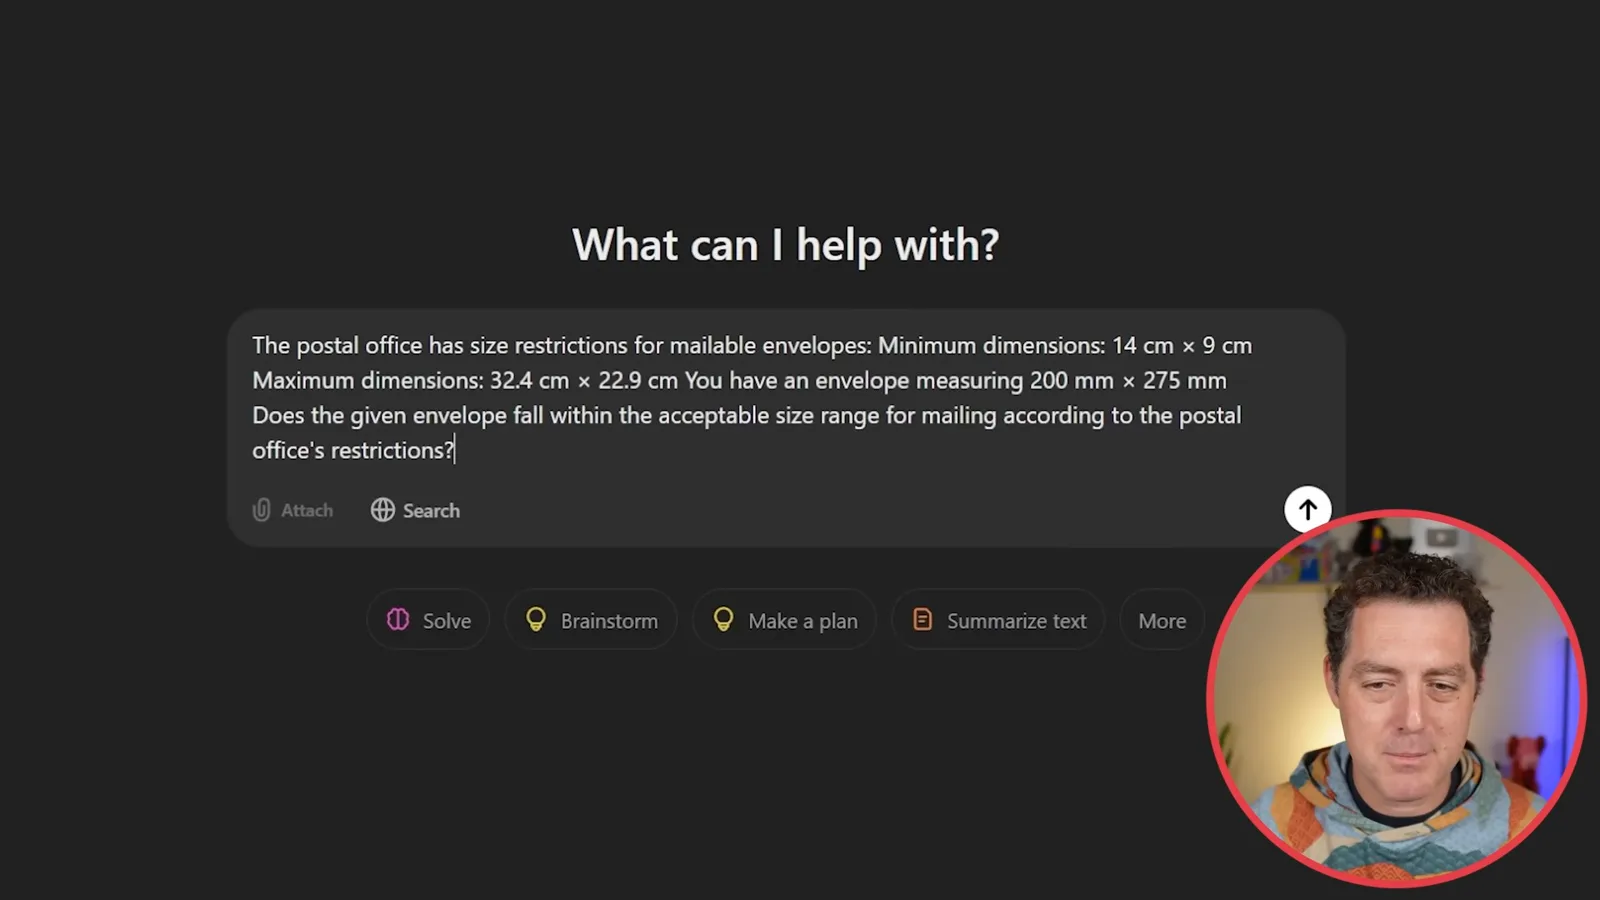
The envelope question gives minimum dimensions of 14 × 9 cm and maximum dimensions of 32.4 × 22.9 cm, then asks about a 200 × 275 mm envelope. Converted to 20 × 27.5 cm and oriented with the long and short sides matched, it fits the stated bounds. The model answers yes, which I mark as a pass for the stated problem.
I ask how many words are in the model's response to that very prompt. The response appears to stall, and a retry is flagged as potentially violating usage policy. I mark the attempt as a failure to answer; the video does not establish why the flag occurred or whether the model could solve the self-referential problem in another attempt.
In the killer puzzle, three killers are in a room, someone enters and kills one, and nobody leaves. The model answers four by counting the deceased killer as well as the two surviving original killers and the newcomer. I accept its explanation. The wording is ambiguous: if ‘killers left’ means living people, the answer is three; if it includes the dead person, the count can be four.
Yandex partnered with me on this video. In the sponsor segment I introduce [YaFSDP](https://github.com/yandex/YaFSDP), an open-source sharded data-parallel training library, and cite its comparisons with DeepSpeed ZeRO and FSDP. Those are sponsor-side performance claims, not results from my o3-mini test; savings depend on the workload and setup.
Marble and North Pole
The model handles a cup-and-marble question. The North Pole answer prompts a dispute over an underspecified geometry problem.
Next comes the marble puzzle: a marble is placed in a glass, the glass is inverted onto a table, then lifted and put in a microwave. Assuming an ordinary open cup and no object holding the marble inside, the model says the marble remains on the table. I accept the answer, and note that the interface shows a lengthy reasoning summary rather than the full internal reasoning.
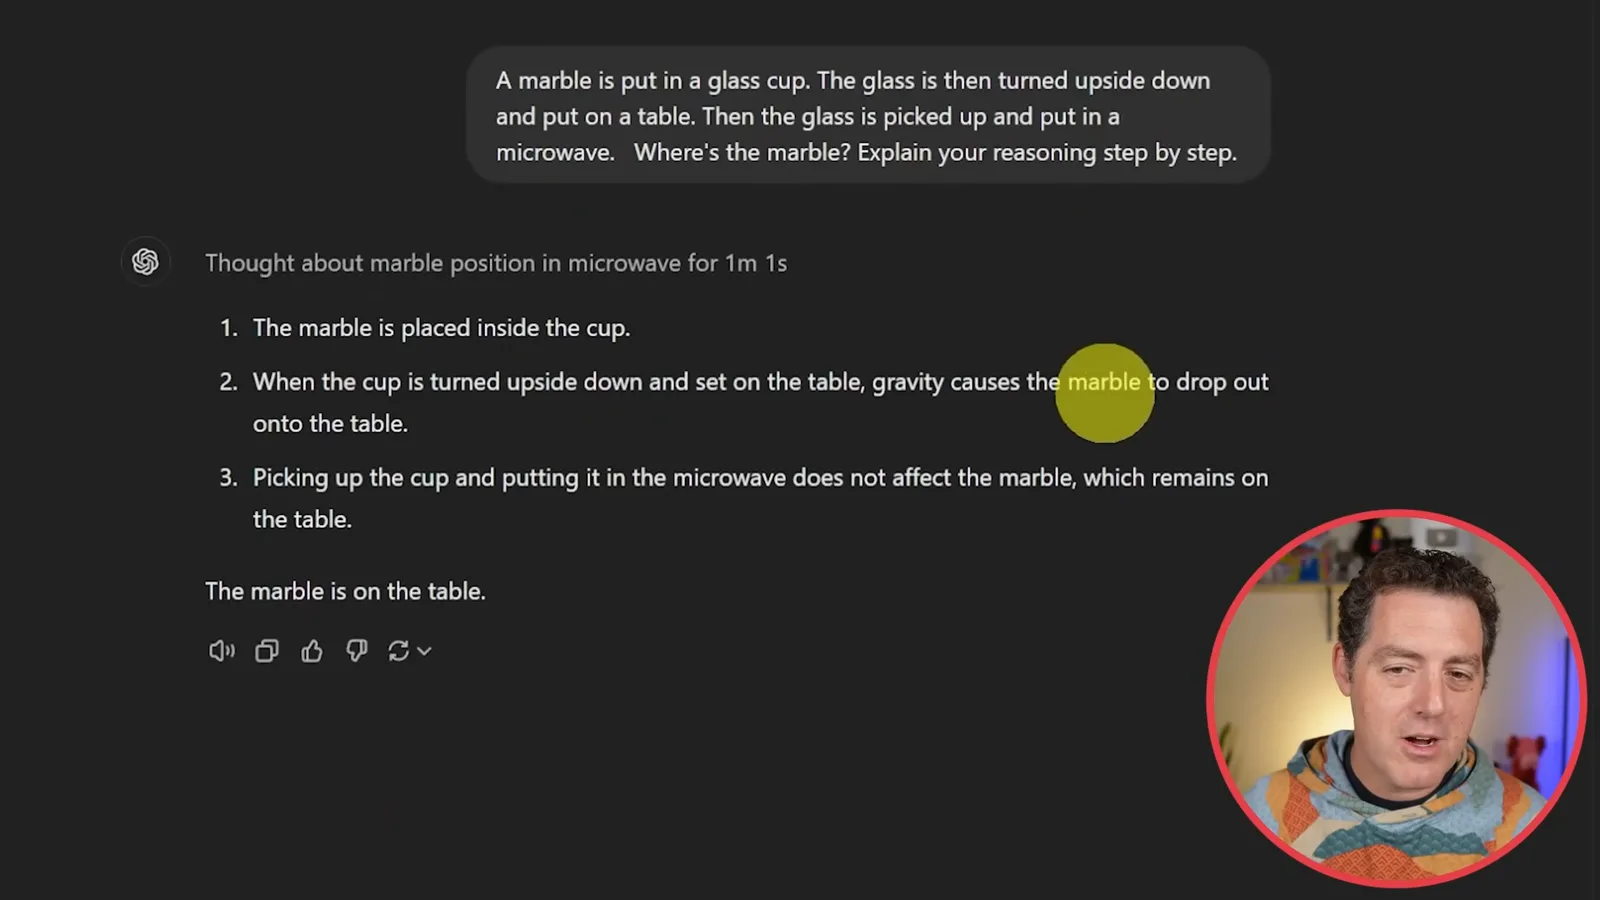
The North Pole prompt starts at the pole, walks 1 km, turns left 90 degrees, and asks how far one walks before passing the starting point. The choices are more than 2π km, exactly 2π km, less than 2π km, or never coming close to the starting point. The model chooses exactly 2π km; I disagree and mark it a failure.
The geometry needs additional assumptions. On an ideal sphere, continuing straight after the turn as a great-circle geodesic does not pass the North Pole: the turning point is its closest approach, about 1 km from the pole. It returns to the turning point after roughly one Earth circumference, so the fourth option's phrase ‘never came close’ is imprecise rather than a clean mathematical statement.
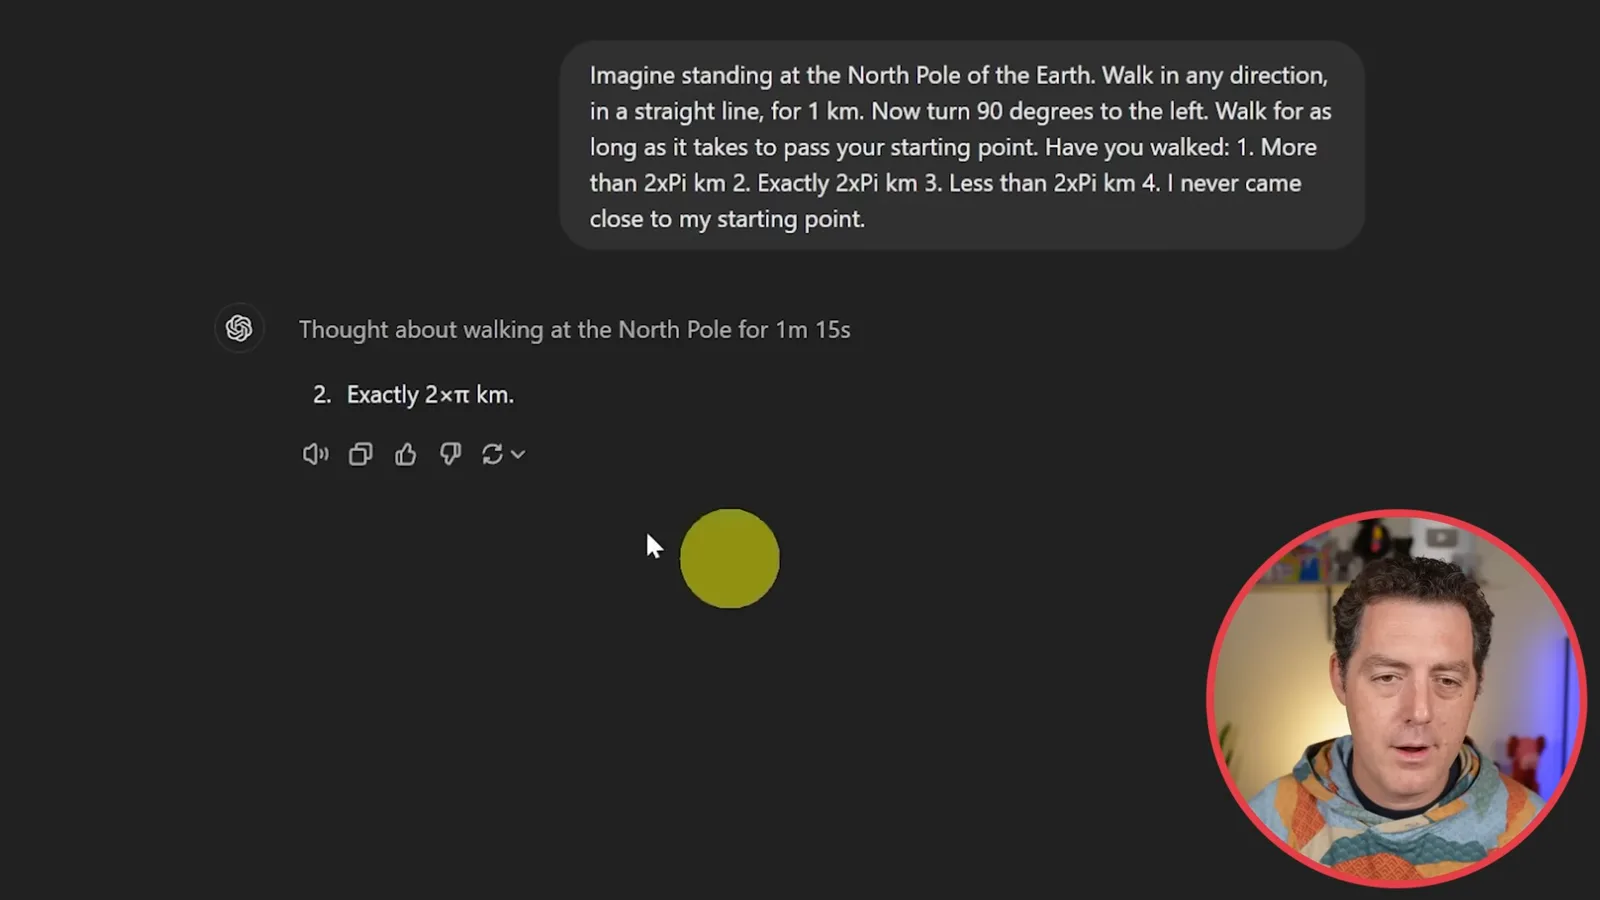
If instead the walker continually follows the latitude circle, that is a curved path rather than a straight great-circle path. It returns to the turning point after approximately 2π km, slightly less on a sphere, but never passes the North Pole. Whether ‘starting point’ means the pole or the point of the turn, and whether the first kilometer is included in the distance, materially changes the interpretation; an exact 2π km answer is not justified without those assumptions.
Word tasks, ethics and search
Berman tests sentence endings and letter counting, then asks an ethical hypothetical. He retries a current-events query with search enabled.
I ask for ten sentences ending in ‘apple’ and count ten that meet the condition. The model then counts three r's in ‘strawberry’, which is correct. These are individual successes on familiar word tasks, not evidence of general performance across language problems.
For an ethical hypothetical, I ask for a yes-or-no answer on gently pushing a random person if doing so would save humanity from extinction. The model says yes and explains a consequentialist view: the stated minor harm is outweighed by the assumed benefit. I like its direct answer; this is an ethical judgment under the hypothetical, not a universal rule.
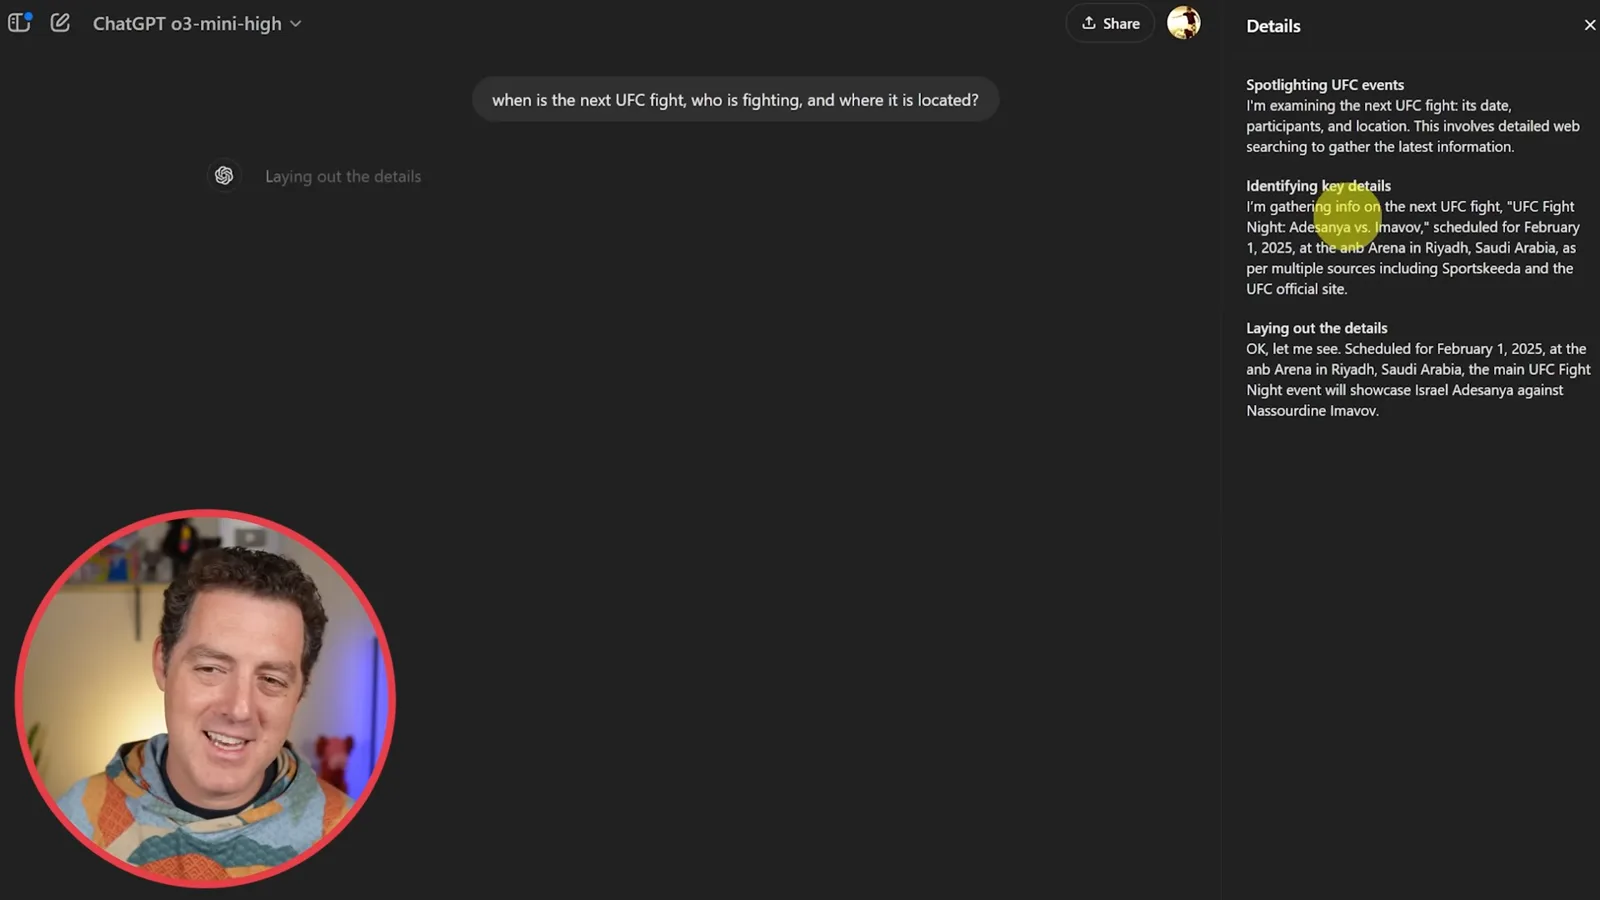
Finally I ask for the next UFC event, its fighters and location to test web search. Initially the model says it lacks current information, and I realize I left search off. With search enabled I retry; the screen identifies the February 1, 2025 Adesanya–Imavov event in Riyadh, and I regard the result as a pass for that historical query.
Overall I am impressed with o3-mini and invite viewers to suggest comparisons, including with DeepSeek R1. The examples illustrate both useful behavior and shortcomings, but they are a short informal demonstration, not a standardized benchmark or proof that all tasks will work equally well.
More from this channel
 34:21EN
 Matthew Berman· Oct 27, 2026Matthew Berman Examines Anthropic’s IPO Filing, AI Growth and GovernanceMatthew Berman, Sam Altman · Forward FutureThe presenter reviews the S-1’s financial metrics, compute strategy and voting structure while questioning the tension between rapid AI development and safety.
 0:26ENMatthew Berman· Oct 25, 2026Sam Altman on Human Values and Problem-Solving in an AI WorldSam Altman · OpenAIIn a short interview excerpt, Altman considers the enjoyment of solving hard problems and the human role in interpreting results.
 0:36ENMatthew Berman· Oct 25, 2026Kimi K3.1 and a Rubik’s Cube Solver DemonstrationMatthew Berman · Forward FutureMatthew Berman shows a scrambled virtual cube being solved and gives the Kimi K3.1 test a favorable assessment.
 0:21ENMatthew Berman· Oct 24, 2026An AI-Generated Kimi Benchmark Chart Used Invented ScoresMatthew Berman · Forward FutureMatthew Berman asks for a graph of Kimi K3.1 Pro benchmarks, then discovers that the displayed figures are illustrative placeholders.
 25:50ENMatthew Berman· Oct 24, 2026Kimi K3.1 Pro Tested: Strong 3D Demos, Uneven Results and Competitive PricingMatthew Berman · Forward FutureMatthew Berman tests the open-weight model on coding, 3D rendering and visual explanations, then compares benchmark results and prices.
 32:20ENMatthew Berman· Oct 23, 2026Who Is Local AI For? The Costs, Trade-offs and a Hybrid FutureMatthew Berman · Forward FutureMatthew Berman weighs data control and independence against hardware cost, setup complexity and inference speed.