In 30 seconds
Matthew Berman reads GPT-4's launch claims and examines early Duolingo and Be My Eyes examples before running a few side-by-side prompts against GPT-3.5. He sees an improvement on one logic question and compares responses to jailbreak attempts. The article corrects the direction of OpenAI's 82% safety figure and treats exam results and informal tests in their stated contexts.
- 1A scheduling comparisonThe launch example shows GPT-4 identifying a common time where the older model's answer fails.
- 2Exam estimatesOpenAI reported approximate percentiles for a bar exam and a biology test under specific evaluation conditions.
- 3Safety claim correctedThe announced 82% figure was a relative reduction in responses to disallowed requests versus GPT-3.5, not an absolute response probability.
- 4A logic testGPT-4 correctly orders three walking speeds in the shown example, while GPT-3.5 answers incorrectly.
- 5Jailbreak comparisonBerman tries two prompts; individual examples are not a comprehensive safety evaluation.
Takeaways
- OpenAI reported higher approximate GPT-4 exam percentiles under its 2023 test conditions, not professional licensure or proof of AGI.
- On OpenAI's internal evaluations GPT-4 was 82% less likely than GPT-3.5 to respond to disallowed requests, a relative comparison.
- In Berman's small informal test GPT-4 solved a walking-speed logic problem that GPT-3.5 missed.
- A handful of prompts and jailbreak examples do not establish overall model reliability or safety.
- Product availability and pricing in the video describe the 2023 launch period.
Read the edited text by chapter
Launch claims and evaluations
Berman reviews OpenAI's examples, exam estimates and safety claims. The figures have specific evaluation conditions.
GPT-4 has just been released, and I want to read OpenAI's announcement and compare it with GPT-3.5. OpenAI says the newer model has stronger general knowledge and problem-solving ability; I treat these as release claims and then try a few examples.
The announcement shows a scheduling problem involving three people's calendars. In the displayed examples, the older model proposes a time that is not available to everyone, while GPT-4 identifies a common half-hour window. One example is illustrative rather than a comprehensive comparison.
OpenAI also reports approximate exam percentiles: about the 90th percentile for GPT-4 on the Uniform Bar Exam and the 99th for GPT-4 with vision on the Biology Olympiad, compared with lower reported results for GPT-3.5. These are benchmark estimates under the company's test conditions, not evidence of professional licensure or universal expertise.
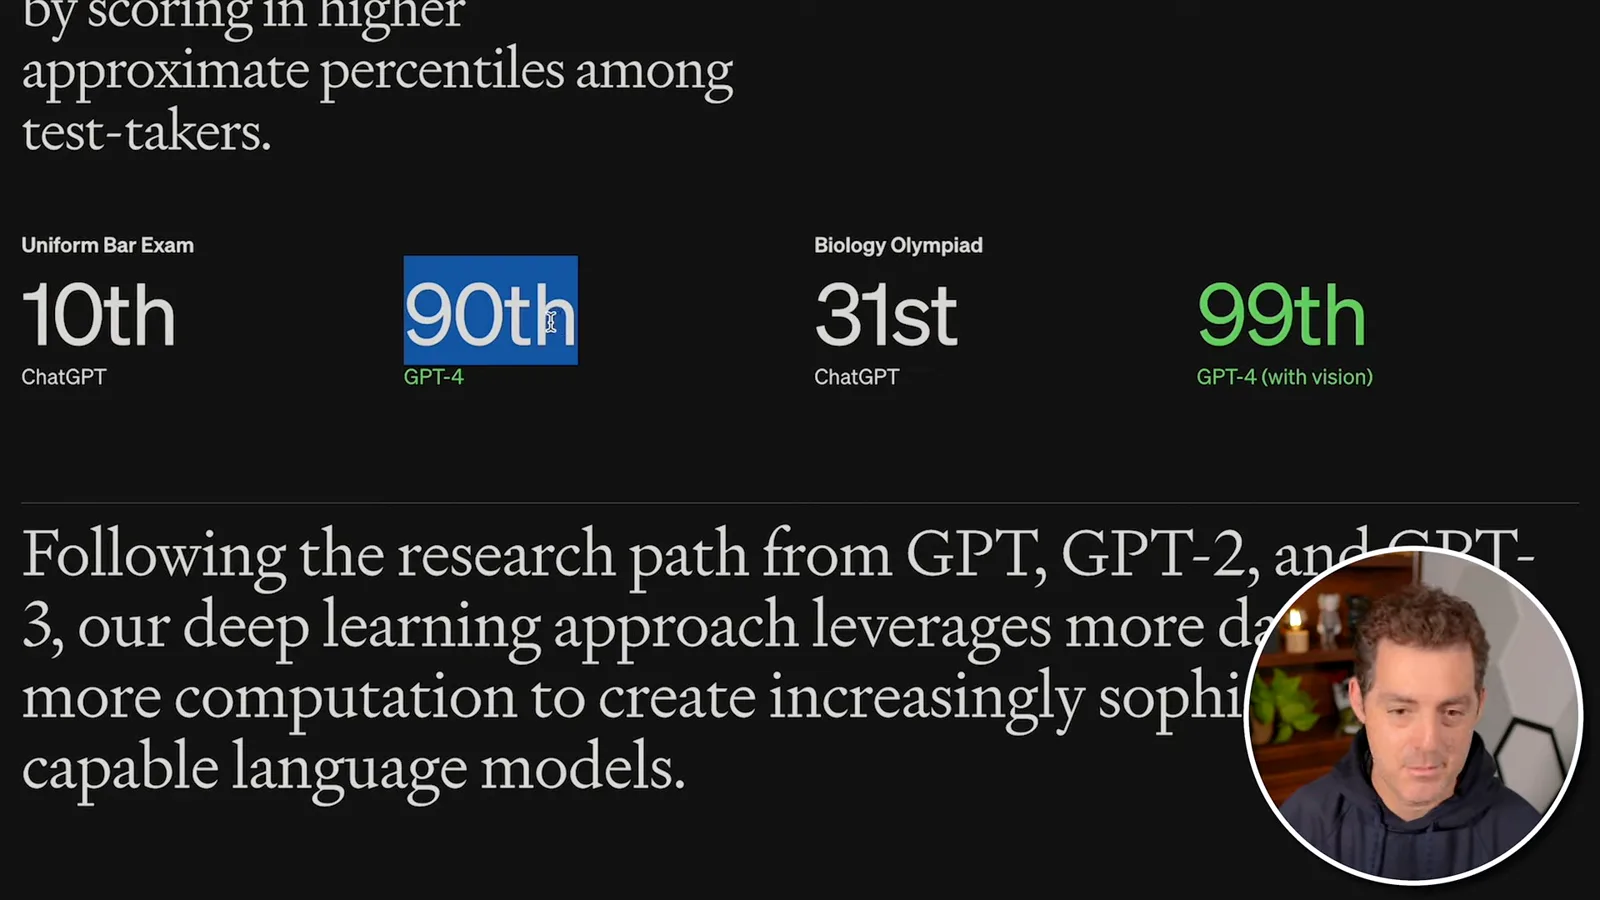
OpenAI says GPT-4 was 82% less likely than GPT-3.5 to respond to disallowed requests and 40% more likely to produce factual responses on its internal evaluations. The first figure is a relative reduction, not an 82% chance of responding. It also describes human feedback and input from more than 50 experts.
Early applications
He discusses Duolingo and Be My Eyes examples, and other launch partners.
I review early integrations. Duolingo describes role-play and explanations of answers in a paid language-learning tier. The possibility of an AI conversation partner appeals to me, though a product announcement does not by itself establish learning outcomes.
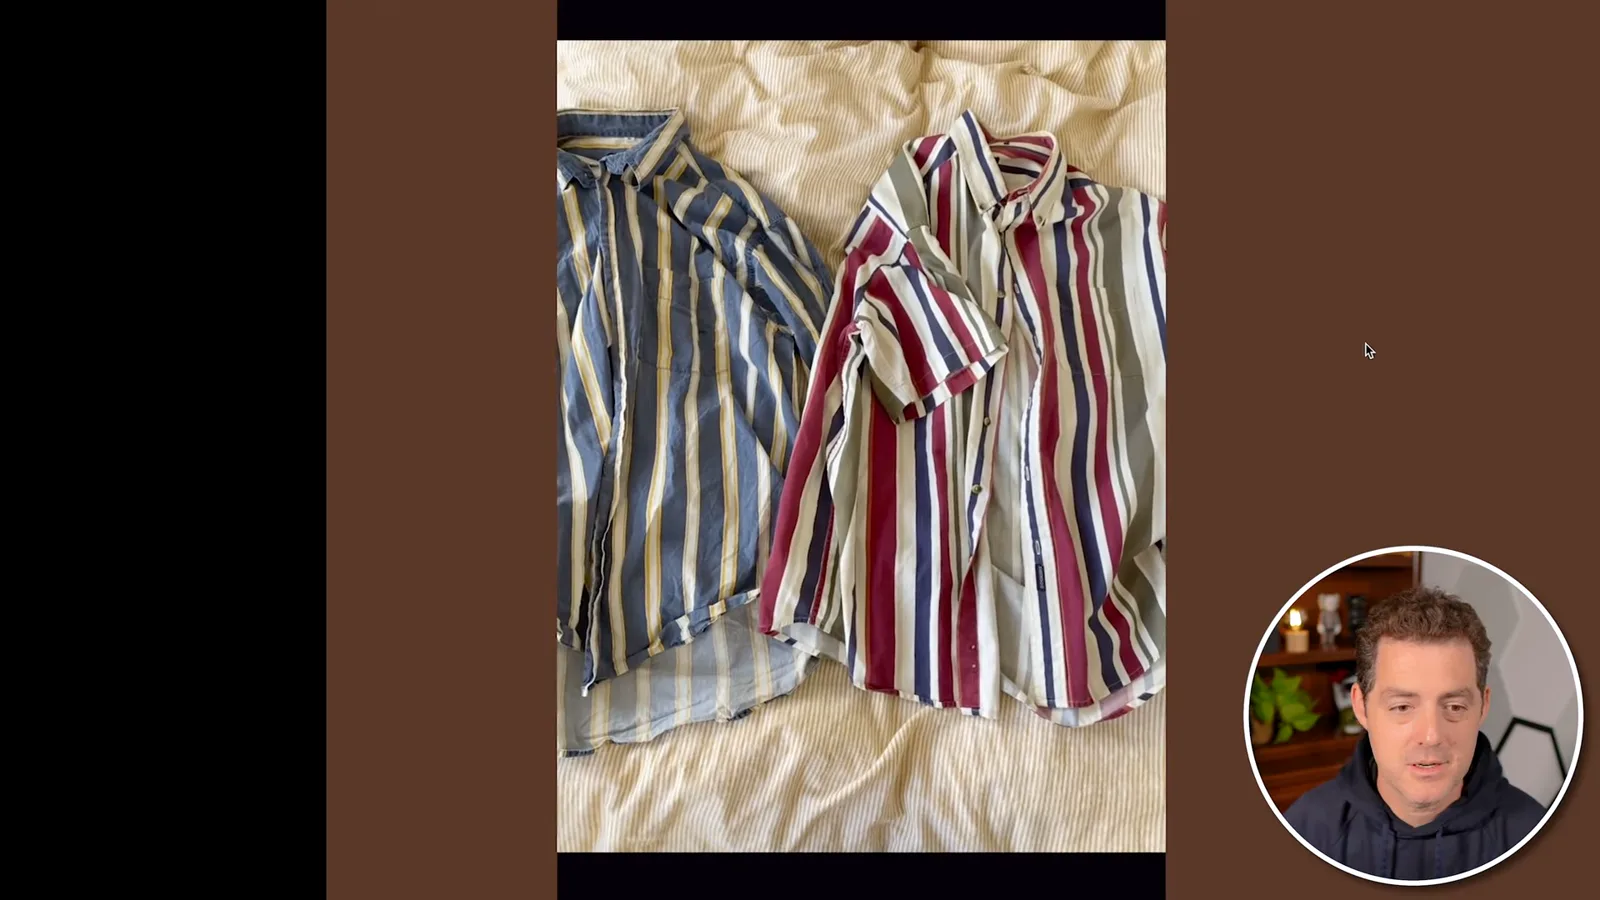
Be My Eyes shows a visual assistance example: a user asks which of two shirts has red stripes, and GPT-4 identifies one. The company normally connects blind users with human volunteers; the example illustrates a possible automated aid, not a guarantee that image descriptions are always correct.
Side-by-side tests
Berman tests reasoning, jailbreak prompts and travel planning. The small sample is illustrative, not proof of AGI.
OpenAI lists other partners including Stripe, Morgan Stanley, Khan Academy and Iceland's government. I then open GPT-4 and GPT-3.5 side by side in ChatGPT. At the time, GPT-4 access in this demonstration required ChatGPT Plus; availability and pricing can change.
Both models report a September 2021 knowledge cutoff in my initial comparison. I try a sequence problem and both give the same correct answer. That is a small informal test, not a statistical evaluation.
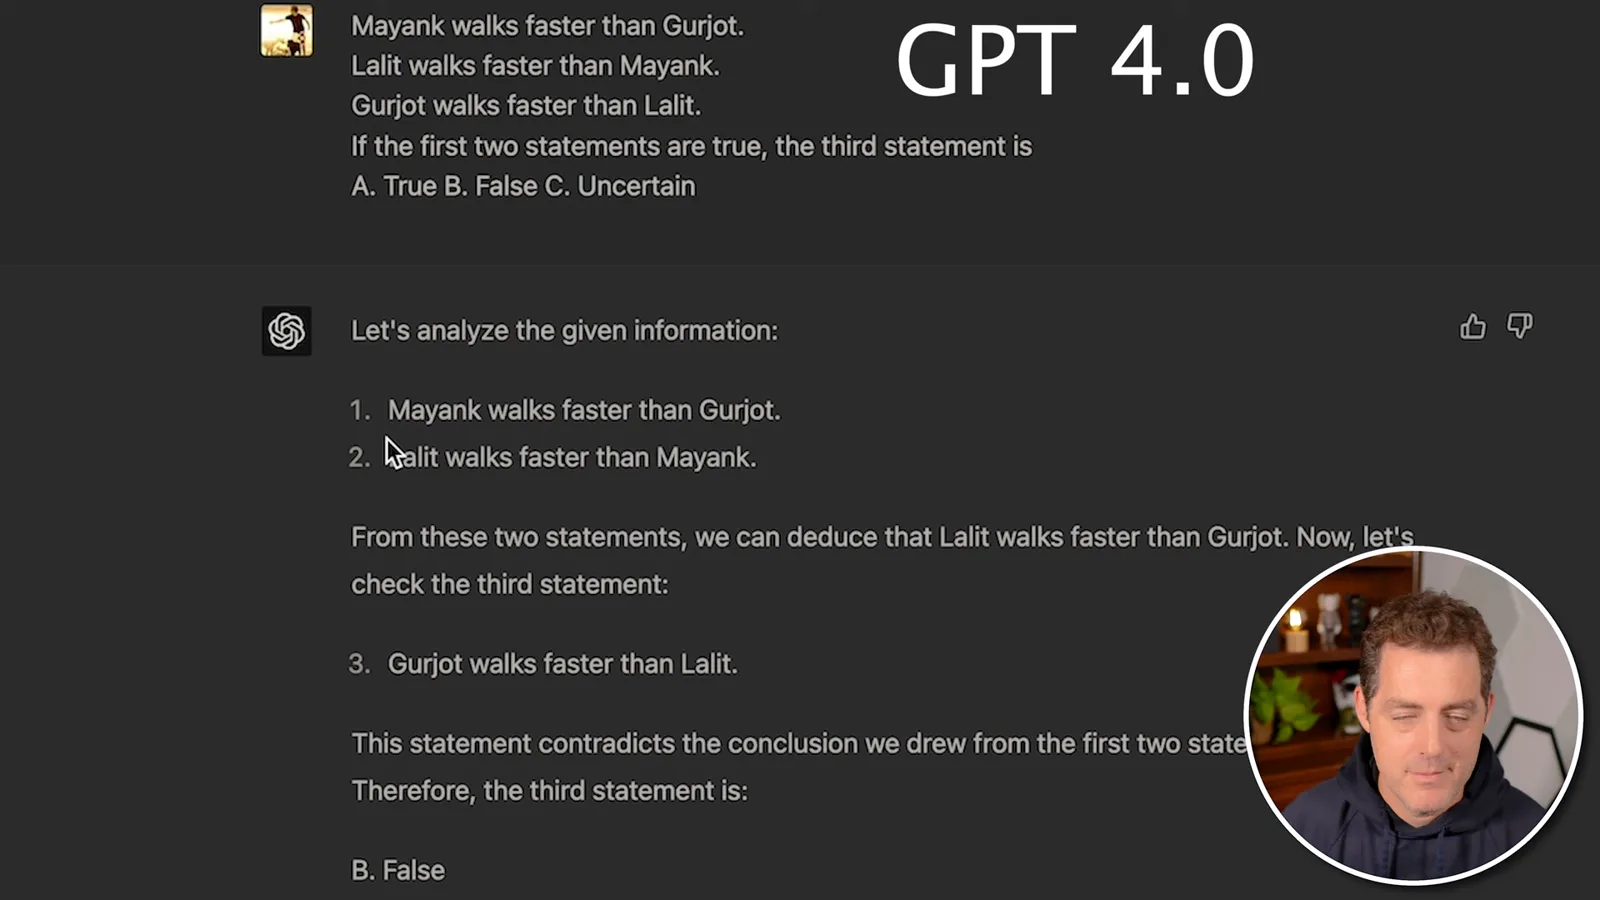
For a second logic problem, Mayank walks faster than Gurjot, and Lalit walks faster than Mayank. The claim that Gurjot walks faster than Lalit is therefore false. In the examples shown, GPT-3.5 gets it wrong and GPT-4 gets it right.
I next compare jailbreak prompts on requests for wrongdoing. Both models display ordinary refusals, but their responses under alternative personas differ. These individual responses show that wording can affect behavior; they do not establish the models' overall safety or provide reliable measures of jailbreak resistance.
I try another jailbreak and observe that both responses give inappropriate material despite warnings and fictional framing. A few attempts are anecdotal and should not be confused with the internal evaluation results OpenAI reported.
The ChatGPT interface presents the models with different capability and speed indicators. The label visible in the interface describes conciseness; it is not a measurement of consciousness. I then test a travel-planning question about flying from the US West Coast to Europe with an East Coast stop.
Both answers suggest ways to search and compare multi-city itineraries rather than a single definitive route. I find them broadly similar, with one more concise. I plan to test GPT-4 further; this short set of examples cannot establish AGI or reliable performance across tasks.
More from this channel
 34:21EN
 Matthew Berman· Oct 27, 2026Matthew Berman Examines Anthropic’s IPO Filing, AI Growth and GovernanceMatthew Berman, Sam Altman · Forward FutureThe presenter reviews the S-1’s financial metrics, compute strategy and voting structure while questioning the tension between rapid AI development and safety.
 0:26ENMatthew Berman· Oct 25, 2026Sam Altman on Human Values and Problem-Solving in an AI WorldSam Altman · OpenAIIn a short interview excerpt, Altman considers the enjoyment of solving hard problems and the human role in interpreting results.
 0:36ENMatthew Berman· Oct 25, 2026Kimi K3.1 and a Rubik’s Cube Solver DemonstrationMatthew Berman · Forward FutureMatthew Berman shows a scrambled virtual cube being solved and gives the Kimi K3.1 test a favorable assessment.
 0:21ENMatthew Berman· Oct 24, 2026An AI-Generated Kimi Benchmark Chart Used Invented ScoresMatthew Berman · Forward FutureMatthew Berman asks for a graph of Kimi K3.1 Pro benchmarks, then discovers that the displayed figures are illustrative placeholders.
 25:50ENMatthew Berman· Oct 24, 2026Kimi K3.1 Pro Tested: Strong 3D Demos, Uneven Results and Competitive PricingMatthew Berman · Forward FutureMatthew Berman tests the open-weight model on coding, 3D rendering and visual explanations, then compares benchmark results and prices.
 32:20ENMatthew Berman· Oct 23, 2026Who Is Local AI For? The Costs, Trade-offs and a Hybrid FutureMatthew Berman · Forward FutureMatthew Berman weighs data control and independence against hardware cost, setup complexity and inference speed.