In 30 seconds
In this June 2025 video, Matthew Berman examines Reddit’s civil complaint against Anthropic, focusing on alleged crawling, model training, user privacy and the value of licensing Reddit content. He also questions whether a chatbot’s statements reliably establish its training sources. Anthropic disputed Reddit’s claims. A federal court remanded the case to California state court in March 2026; in September 2026, a state judge allowed three claims to proceed and sustained challenges to two others with leave to amend. Those procedural decisions are not findings that the allegations are true or a final judgment on liability.
- 1The complaintReddit brought a civil suit with claims including breach of contract and unfair competition. Anthropic denied the allegations.
- 2Crawler and privacy allegationsReddit alleges Anthropic ignored restrictions and continued automated access after a block-list statement. The assertions remain disputed.
- 3Training data and chatbot answersThe complaint cites an Anthropic research paper and a Claude response; Berman cautions that a model’s self-description is not conclusive evidence.
- 4The licensing disputeReddit alleges unauthorized use harms its licensing market; Berman discusses possible diversion of users without claiming to have measured it.
- 5Remedies requestedThe complaint seeks monetary relief and an injunction, among other remedies. A request for relief is not an award.
Takeaways
- Reddit alleges unauthorized access to and use of its user content; Anthropic disputes the claims.
- The complaint alleges more than 100,000 bot accesses after Anthropic said Reddit had been placed on a crawler block list; the count is Reddit’s allegation.
- A chatbot’s own answer about its training data is not a reliable audit of what data was used.
- Deleting source data and removing its influence from an already trained model are different technical questions.
- In September 2026, three claims survived an early challenge while two others were subject to amendment; that ruling did not establish liability.
Read the edited text by chapter
A civil complaint against Anthropic
Berman introduces the Reddit complaint and its claims. The allegations are disputed, and later procedural decisions did not resolve the merits.
In June 2025, Matthew Berman reviews Reddit’s civil lawsuit against Anthropic, the company behind Claude. Reddit alleges unauthorized scraping and use of its users’ content; Anthropic said it disagreed and would defend itself. Berman reads the [complaint](https://redditinc.com/hubfs/Reddit%20Inc/Content/PDFs/Docket%20Stamped%20Complaint.pdf), whose accusations are the plaintiff’s position, not established facts or a criminal conviction.
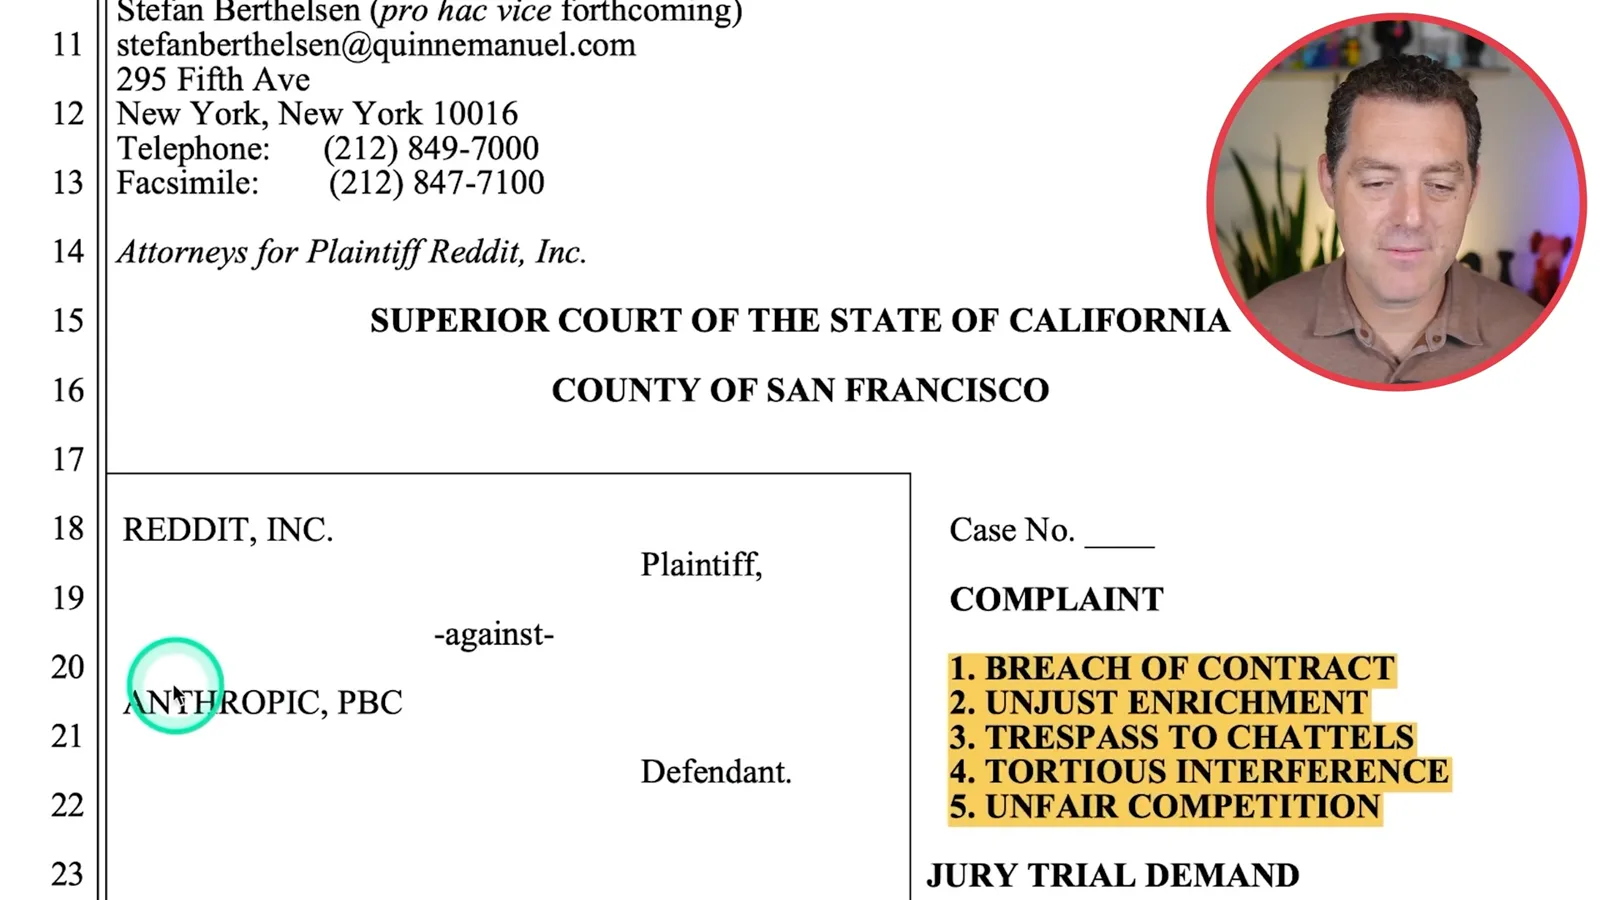
Reddit filed in California Superior Court in San Francisco, alleging breach of contract, unjust enrichment, trespass to chattels, interference with contractual relations and unfair competition, and requesting a jury trial. In a subsequent development, a [federal court remanded the case](https://www.courthousenews.com/wp-content/uploads/2026/03/reddit-v-anthropic-remand-order.pdf) to state court in March 2026 after Anthropic sought federal jurisdiction.
The complaint uses sharp language to contrast Anthropic’s public emphasis on honesty and safety with conduct Reddit alleges. Berman agrees with the complaint’s criticism of the company’s positioning. That evaluation is his opinion; neither the complaint’s rhetoric nor Berman’s agreement proves that Anthropic breached an agreement or acted unlawfully.
Bots, privacy and public statements
The complaint challenges Anthropic’s statements on personal data and robots.txt. It alleges continued automated access after the company said it had blocked Reddit.
Reddit alleges that Anthropic intentionally trained on personal data from Reddit users without requesting their consent, despite public statements about not intending to train models on personal data. Reddit also alleges that Anthropic failed to honor robots.txt directives. A robots.txt file communicates crawling preferences, but the legal effect of any particular access is a matter for the case, not established merely by the presence of a file.
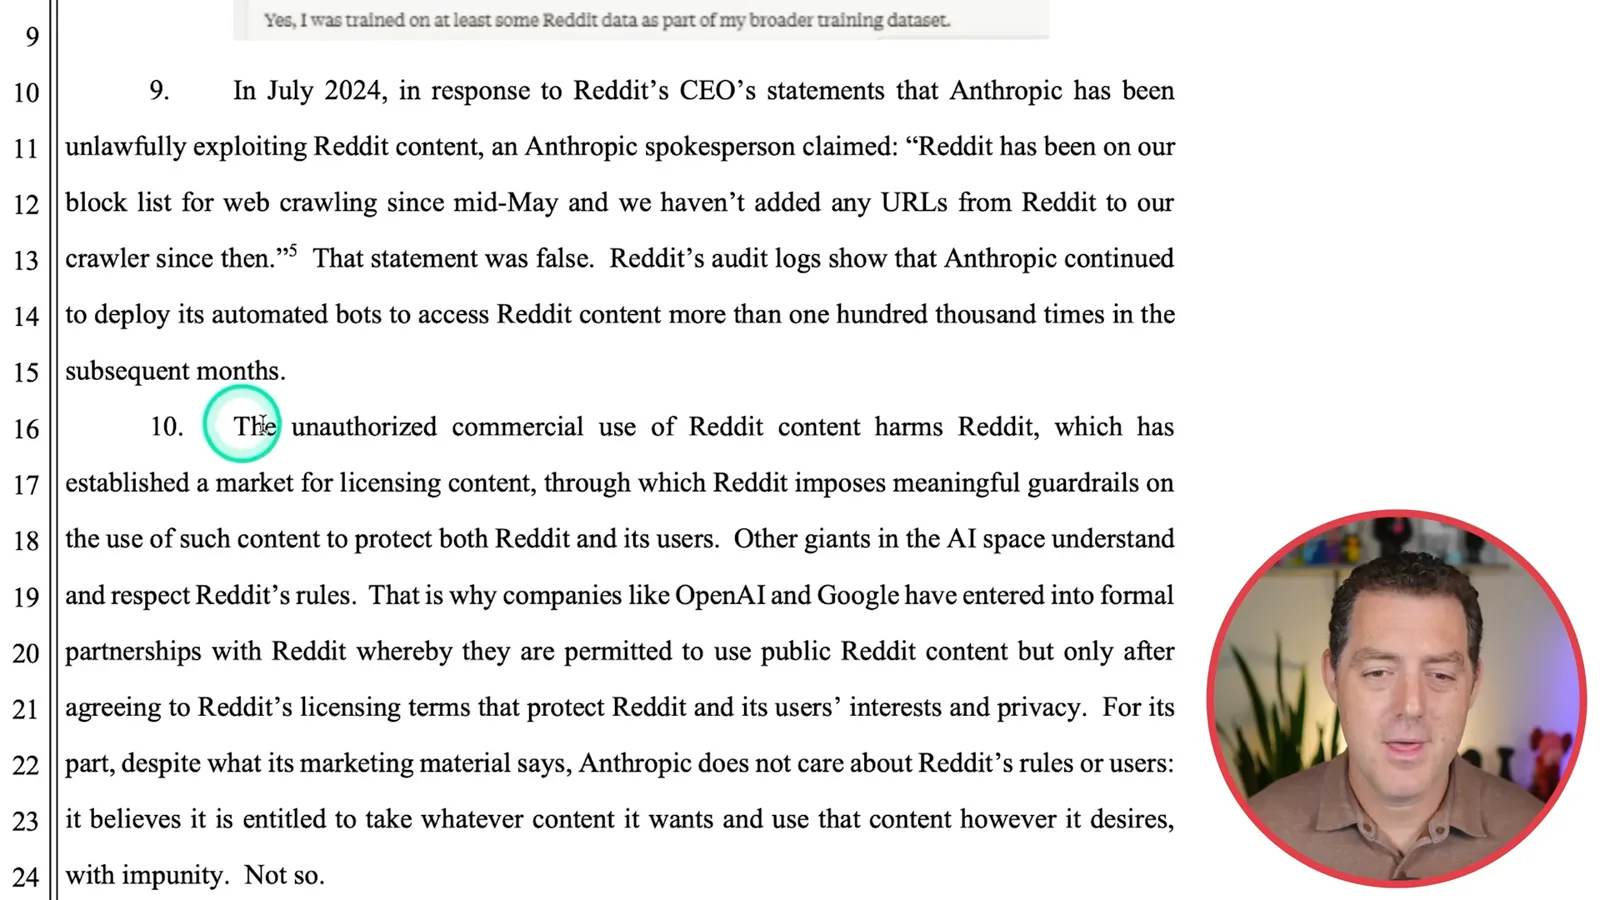
The complaint says an Anthropic spokesperson stated in July 2024 that Reddit had been on its web-crawler block list since mid-May. Reddit alleges its audit logs show Anthropic bots accessed its content more than 100,000 times in the following months. That is Reddit’s account of its logs; the video does not independently establish what each request retrieved or whether the statement was false.
Reddit also contends Anthropic did not agree to protections it seeks for users, including handling posts that users delete. Berman views Reddit alongside YouTube and other social platforms as a particularly valuable collection of human-created information. His assessment of the economic value of those datasets is an opinion about the market, not a legal finding.
Training data and licensing
Reddit cites research and a chatbot exchange to support its case. Berman considers the evidentiary limits of a model’s self-description and discusses economic harm.
Reddit alleges that Anthropic used Reddit posts in training as early as December 2021 and points to research coauthored by Anthropic researchers including CEO Dario Amodei. The complaint cites research discussing Reddit comments in preference-modeling data; the precise implications for the disputed conduct remain part of Reddit’s case.
The complaint also includes a conversation in which Claude says it was trained on some Reddit data. Berman questions whether such an answer would hold up as evidence: a model may be mistaken, generate an unsupported answer or encounter material via other sources. A chatbot’s self-description is not a reliable audit of its actual training data.
Berman returns to Reddit’s allegation that automated access continued after the block-list statement. Reddit claims unauthorized commercial use damages a market in which it licenses content, and contrasts Anthropic with agreements it has made with OpenAI and Google. Whether a particular action was unauthorized and whether it caused damages are disputed issues for the litigation.
Berman considers whether users might ask Claude for information derived from Reddit instead of visiting the site. He says he still values reading and participating in the conversations directly, but sees potential economic harm. This is his interpretation, not a measured estimate of lost traffic or a finding by the court.
Deleted content and requested remedies
A chatbot exchange raises questions about deleted posts and trained models. Berman reviews Reddit’s requests for damages and an injunction.
Another exchange in the complaint asks Claude about deleted Reddit posts. The chatbot says it lacks certainty about the original source or current deletion status of individual training items. Reddit argues that the response does not identify an automatic deletion mechanism; a model’s answer alone does not establish the company’s internal data-handling practices.
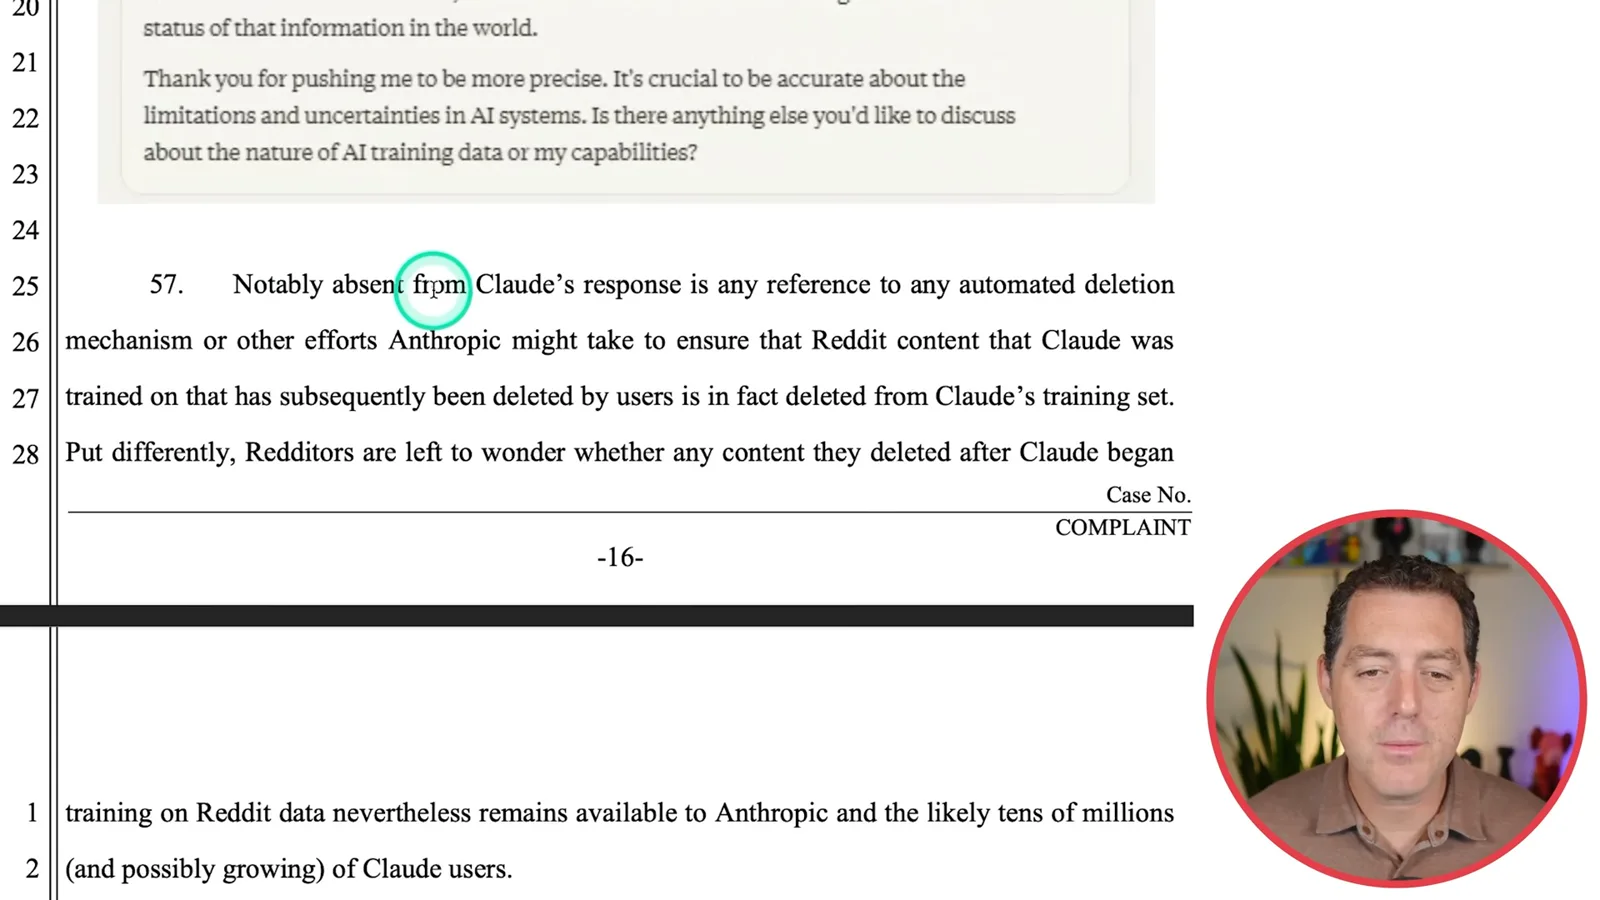
Berman argues that removing the influence of one item after training is difficult and suggests continuous retraining might be necessary. This is his technical judgment, not a demonstrated impossibility: deleting an entry from a stored dataset and altering a trained model are separate problems, and approaches to removing or suppressing learned information have different limitations.
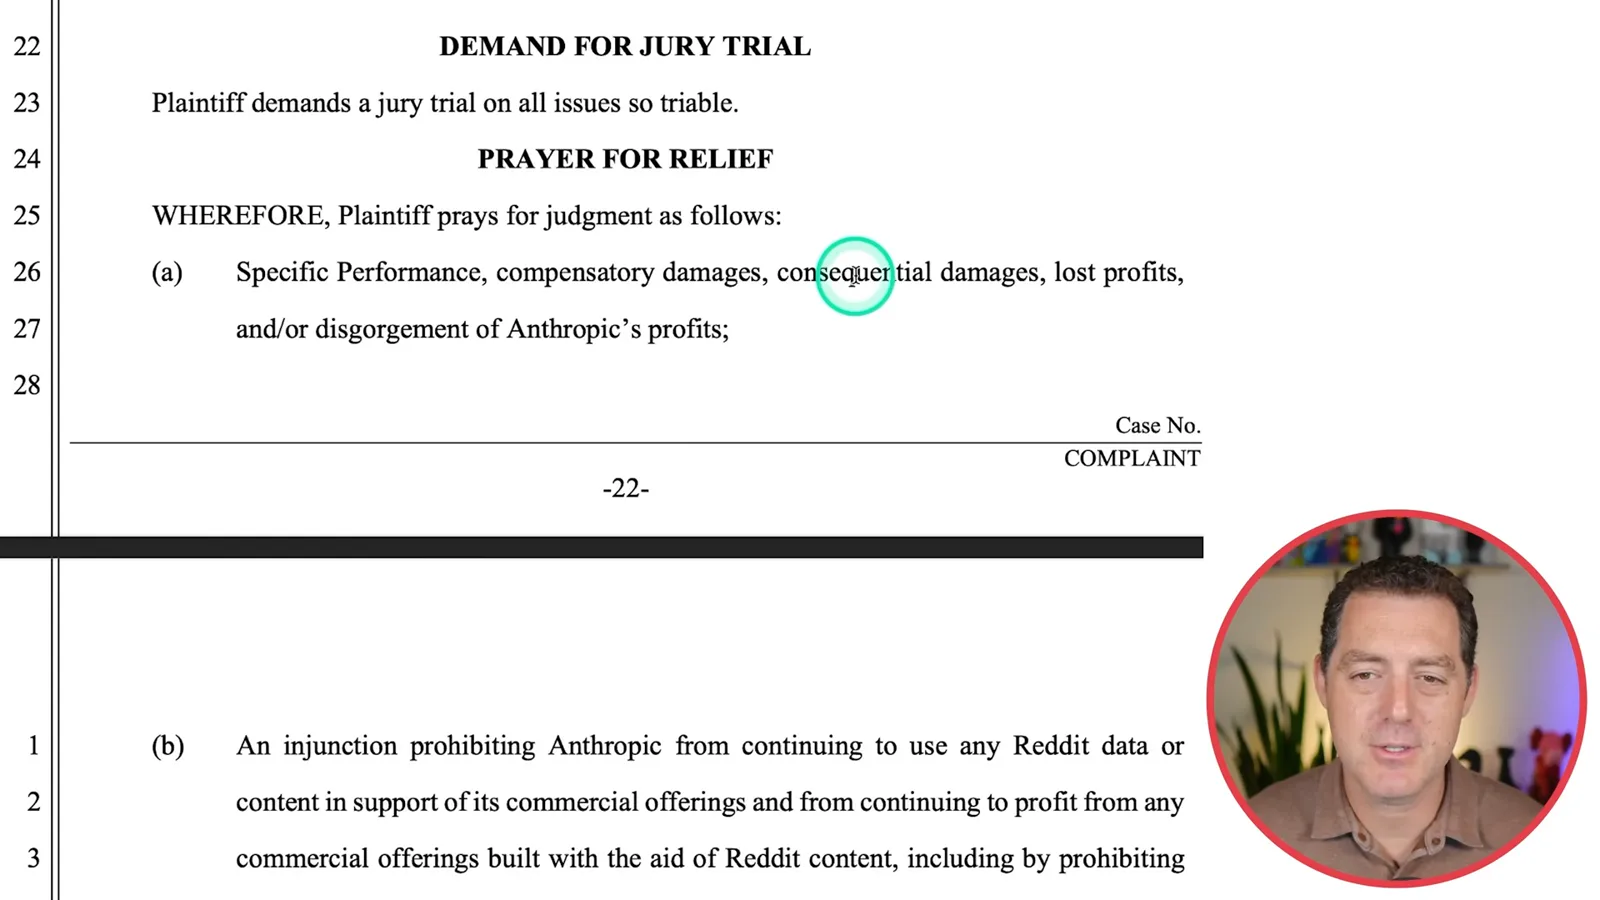
Reddit asks for relief including specific performance, compensatory and consequential damages, lost profits or disgorgement, an injunction against specified commercial use of Reddit content, restitution, punitive damages and attorney fees. These are requested remedies, not an award. Berman says he will follow the litigation for updates.
For later context, a September 2026 [state-court procedural order](https://trellis.law/doc/290965239/order-overruling-demurrer-to-complaint-to-breach-contract-interference-with-contract-ucl-causes-action-sustaining-demurrer-with-leave-to-amend-to-unjust-enrichments-trespass-to-chattels-cause-action-see-scanned-order-for) allowed the contract, interference and unfair-competition claims to proceed, while sustaining challenges to unjust enrichment and trespass to chattels with leave to amend. This ruling assessed the pleadings and did not decide whether Reddit’s allegations are true or Anthropic is liable.
More from this channel
 34:21EN
 Matthew Berman· Oct 27, 2026Matthew Berman Examines Anthropic’s IPO Filing, AI Growth and GovernanceMatthew Berman, Sam Altman · Forward FutureThe presenter reviews the S-1’s financial metrics, compute strategy and voting structure while questioning the tension between rapid AI development and safety.
 0:36ENMatthew Berman· Oct 25, 2026Kimi K3.1 and a Rubik’s Cube Solver DemonstrationMatthew Berman · Forward FutureMatthew Berman shows a scrambled virtual cube being solved and gives the Kimi K3.1 test a favorable assessment.
 25:50ENMatthew Berman· Oct 24, 2026Kimi K3.1 Pro Tested: Strong 3D Demos, Uneven Results and Competitive PricingMatthew Berman · Forward FutureMatthew Berman tests the open-weight model on coding, 3D rendering and visual explanations, then compares benchmark results and prices.
 32:20ENMatthew Berman· Oct 23, 2026Who Is Local AI For? The Costs, Trade-offs and a Hybrid FutureMatthew Berman · Forward FutureMatthew Berman weighs data control and independence against hardware cost, setup complexity and inference speed.
 1:03:37ENMatthew Berman· Oct 23, 2026Matthew Berman’s Team Tests Kimi K3.1 on Animation, Games, and ChartsMatthew Berman, Alex, Brian · Forward FutureA live team AMA turns into an informal test of Kimi K3.1, from personal-agent workflows to motion graphics, a browser game, and a benchmark chart.
 0:53ENMatthew Berman· Oct 22, 2026Sam Altman on AI and the Discovery of New KnowledgeSam Altman · OpenAIAltman expects progress in mathematical discovery to extend to biology, materials and energy.