30초 요약
Jon Gjengset uses a small read-only benchmark to explain cache coherence, reader-writer lock contention and false sharing. He demonstrates the left-right data structure, then explains its memory, consistency and writer-side trade-offs and answers questions about hardware and synchronization implementations.
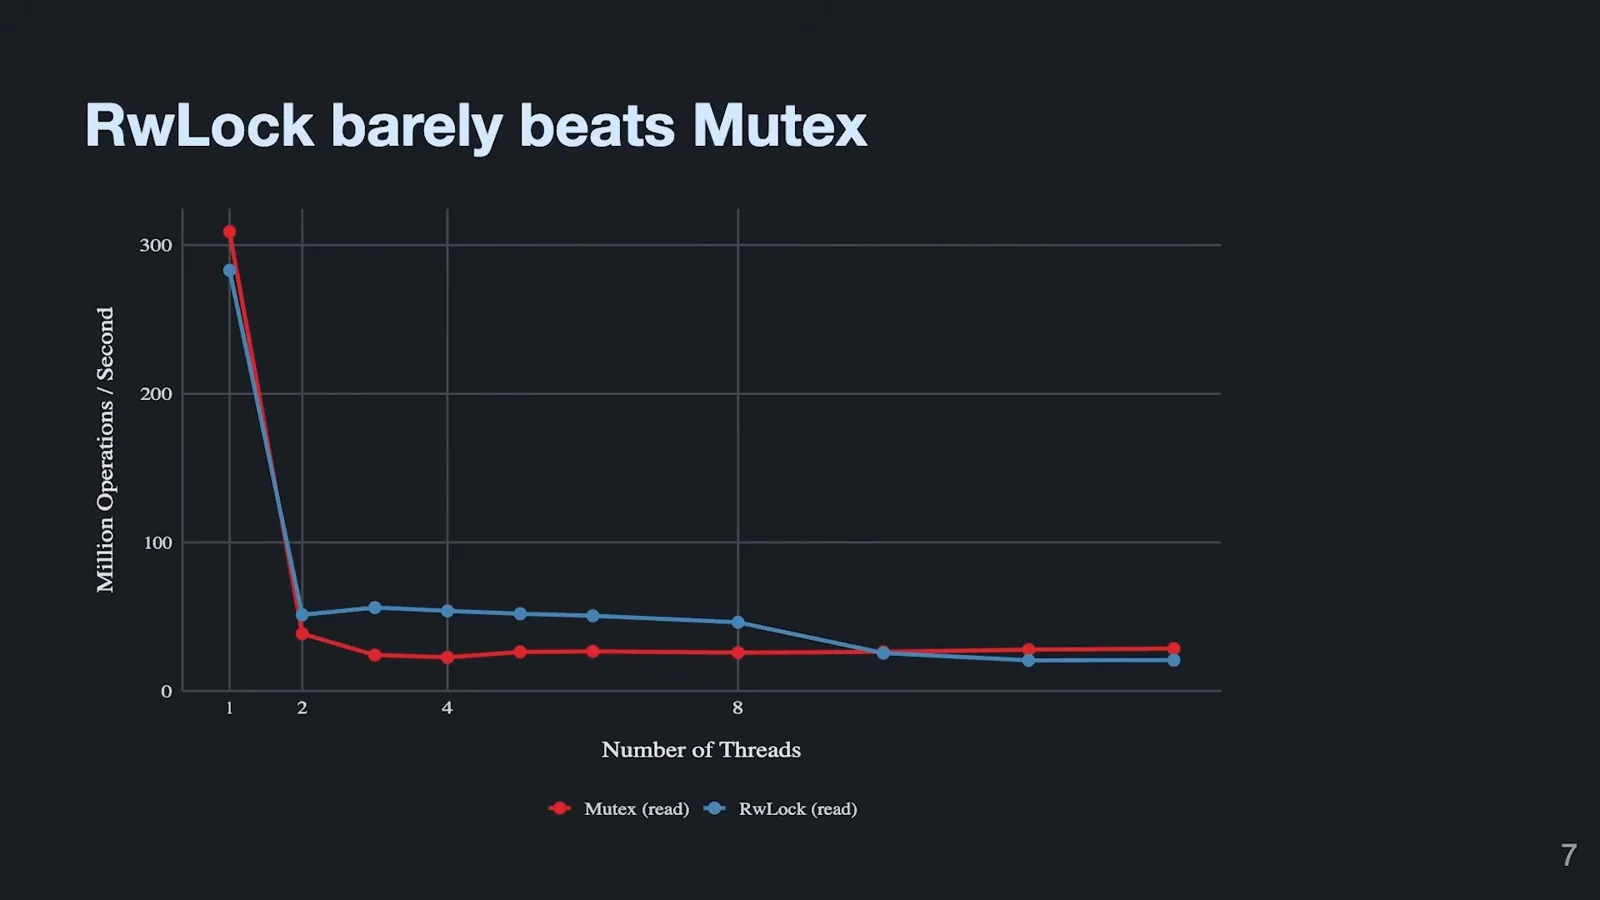
- 1A surprising read benchmarkA mutex-protected read falls sharply in throughput when a second core is added, and a reader-writer lock also scales poorly in this short critical section.
- 2Readers write lock stateReader-writer locks update a shared reader count, making cache-line ownership move among cores.
- 3Two copies and a pointerLeft-right lets readers use one copy while a writer updates the other and publishes it with a pointer swap.
- 4False sharing in practiceReader counters sharing a cache line caused a severe performance drop; aligning them separately fixed the observed benchmark.
- 5Trade-offs matterLeft-right consumes more memory, permits stale reads and has a single-writer design, so it is suitable only for some workloads.
핵심 정리
- A read lock can require writes to shared coordination state, creating contention among readers.
- Cache coherence operates on cache lines, so ownership transfers can dominate short critical sections.
- Left-right gives readers independent state and shifts work toward a less frequent writer.
- False sharing can make lock-free code contend when independent values share a cache line.
- Left-right trades memory and stronger consistency for read scalability and is not a universal replacement for locks.
- Choose and measure a synchronization design against the workload and consistency guarantees it needs.
챕터별로 다듬은 전문 읽기
Are mutexes slow?
A read-only benchmark shows throughput dropping with more threads. A reader-writer lock does not automatically fix the problem.
I want to look beyond the claim that mutexes are slow and ask what the CPU actually does when threads coordinate. The examples use a little Rust, but the ideas apply more broadly to concurrent algorithms and performance.
Consider a shared counter that many threads only read. Each takes a mutex, reads the counter and releases the lock. A black-box operation prevents the compiler from optimizing the read away; no thread writes the counter itself.
In my benchmark one thread reaches roughly 250 million reads per second, but adding a second core drops throughput to about 25 million. Adding further threads leaves it low. A mutex serializes access, but this is worse than simply keeping the same throughput as more threads arrive.
A reader-writer lock might appear to solve a read-heavy workload. Yet in this example its throughput also drops sharply, and as readers increase it eventually performs worse than the mutex. To understand the result, we need to look at caches.
Caches and coherence
Gjengset explains cache hierarchy, MESI states and cache-line ownership. Shared writes require coordination among cores.
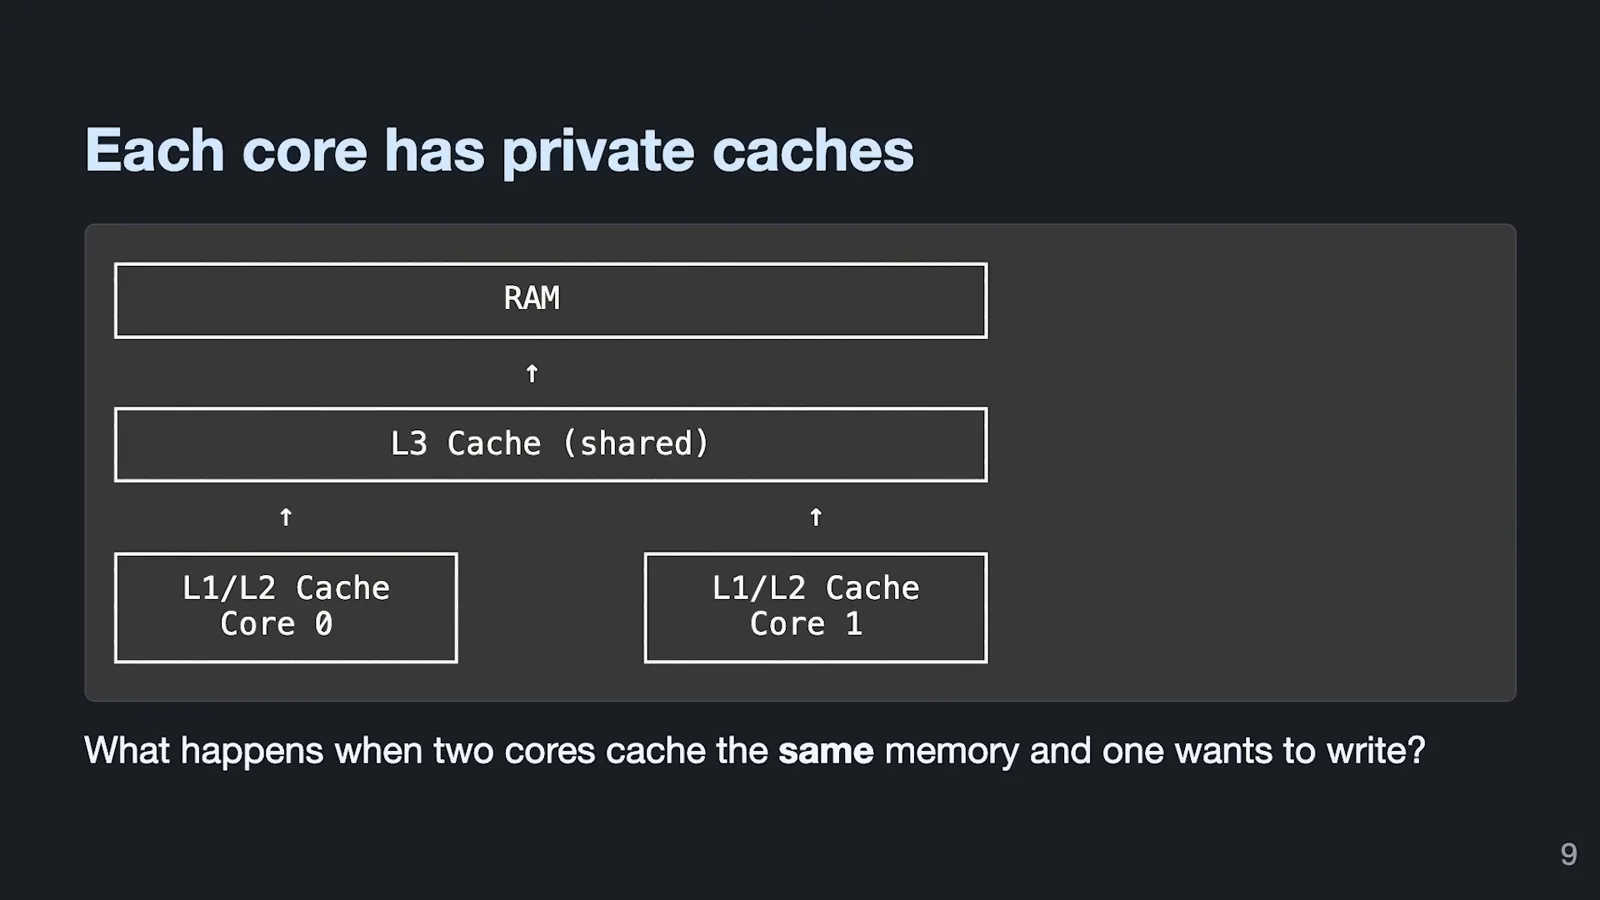
Main memory is far slower to access than a local CPU cache. Common processors have a hierarchy: a small per-core L1 cache, an intermediate L2 and a larger L3 often shared among cores. Exact arrangements vary by processor.
When different cores cache the same memory, a coherence protocol coordinates their access. MESI is a useful model: Modified means a core has a changed exclusive copy; Exclusive means its sole copy is clean; Shared means multiple valid copies agree; Invalid means a cached entry cannot be used.
Coherence operates on cache lines, commonly 64-byte chunks in the example, not individual variables. Before a core writes shared data, it must obtain exclusive ownership and invalidate other copies. That requires cross-core communication.
Why read locks contend
Readers update a shared counter when acquiring and releasing locks. Cache-line transfers can dominate very short critical sections.
A reader-writer lock typically maintains a shared reader count. Acquiring a read lock increments it and releasing decrements it, so even readers write the same shared cache line. With many cores, ownership moves repeatedly between them, introducing a sequential coordination cost.
For two readers, imagine core 0 owns the line and increments the count. Core 1 then needs the updated line to increment it; when core 0 releases, the line may have to move back so it can decrement. One acquisition and release can involve two cache-line transfers.
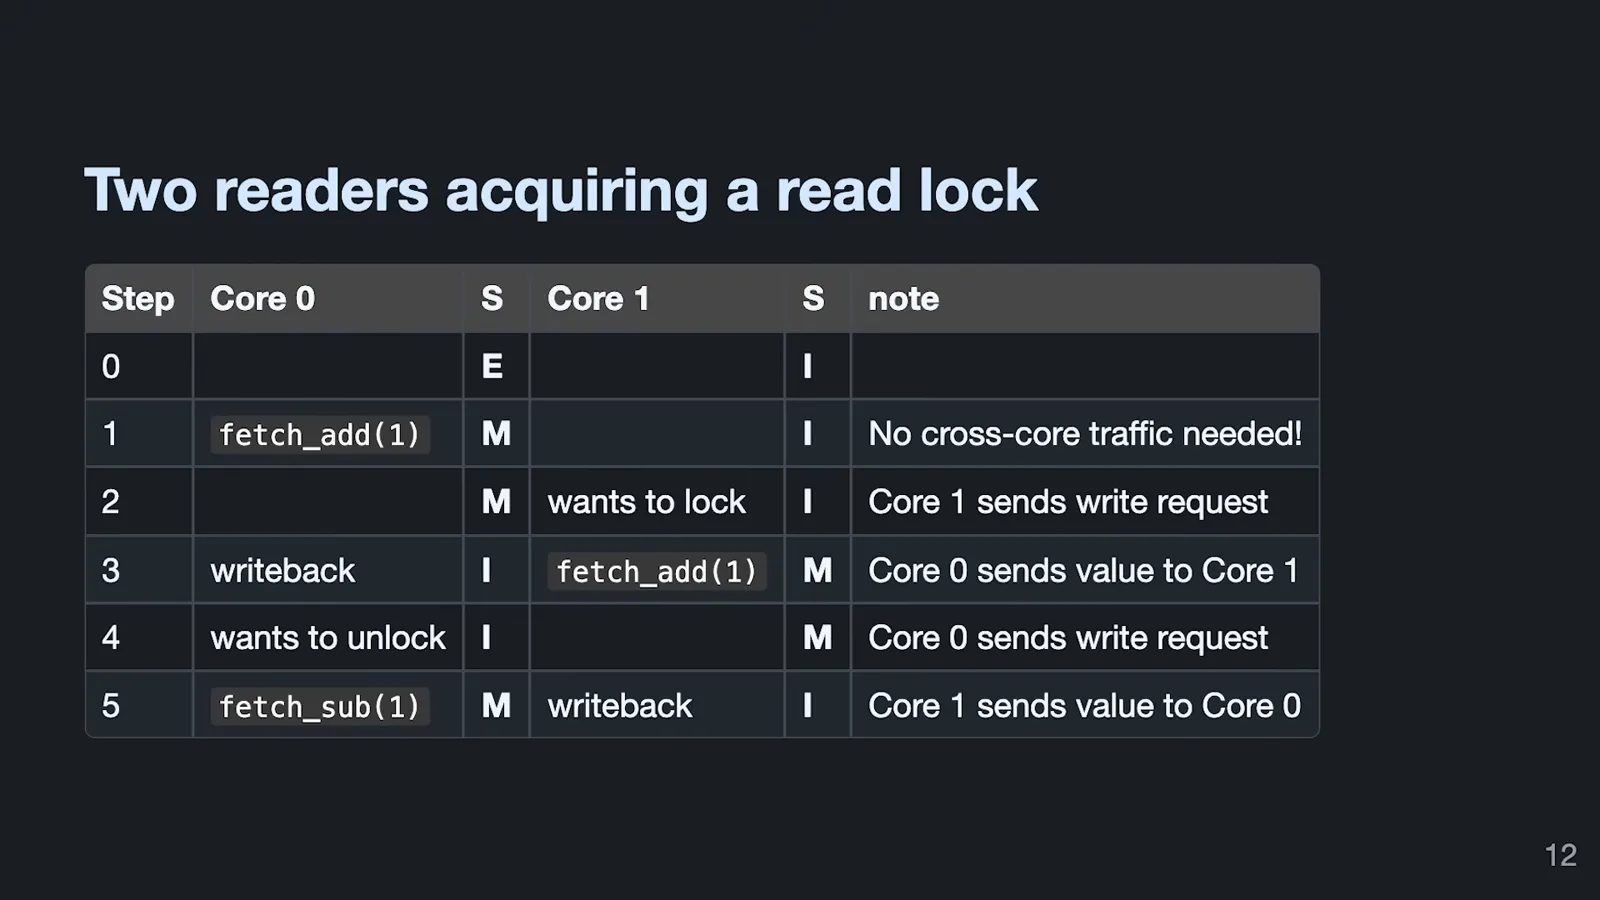
In the example, a local L1 access is about one nanosecond and a cross-core transfer roughly 30 nanoseconds; two transfers are already a large fraction of an approximately 100-nanosecond main-memory access. These are illustrative timings, not universal constants.
With a mutex, the holder has exclusive access until it releases, so the same reader-count ping-pong does not arise in the same way. A reader-writer lock can therefore scale worse in this particular short read-only benchmark, despite allowing multiple readers inside the protected region.
For a longer critical section, the work done under a lock can dwarf the acquisition overhead, and a mutex may be entirely appropriate. The trouble becomes prominent in hot, highly contended loops with very short critical sections. Real workloads need measurement.
The left-right alternative
Two copies and per-reader counters reduce contention for read-heavy workloads. The writer waits for old readers before reusing a copy.
As an alternative with different trade-offs, I used left-right in my PhD work, where reads vastly outnumbered writes and each read was a short hash-map lookup. The aim was to keep readers from repeatedly writing a shared cache line, shifting more work to the rare writer.
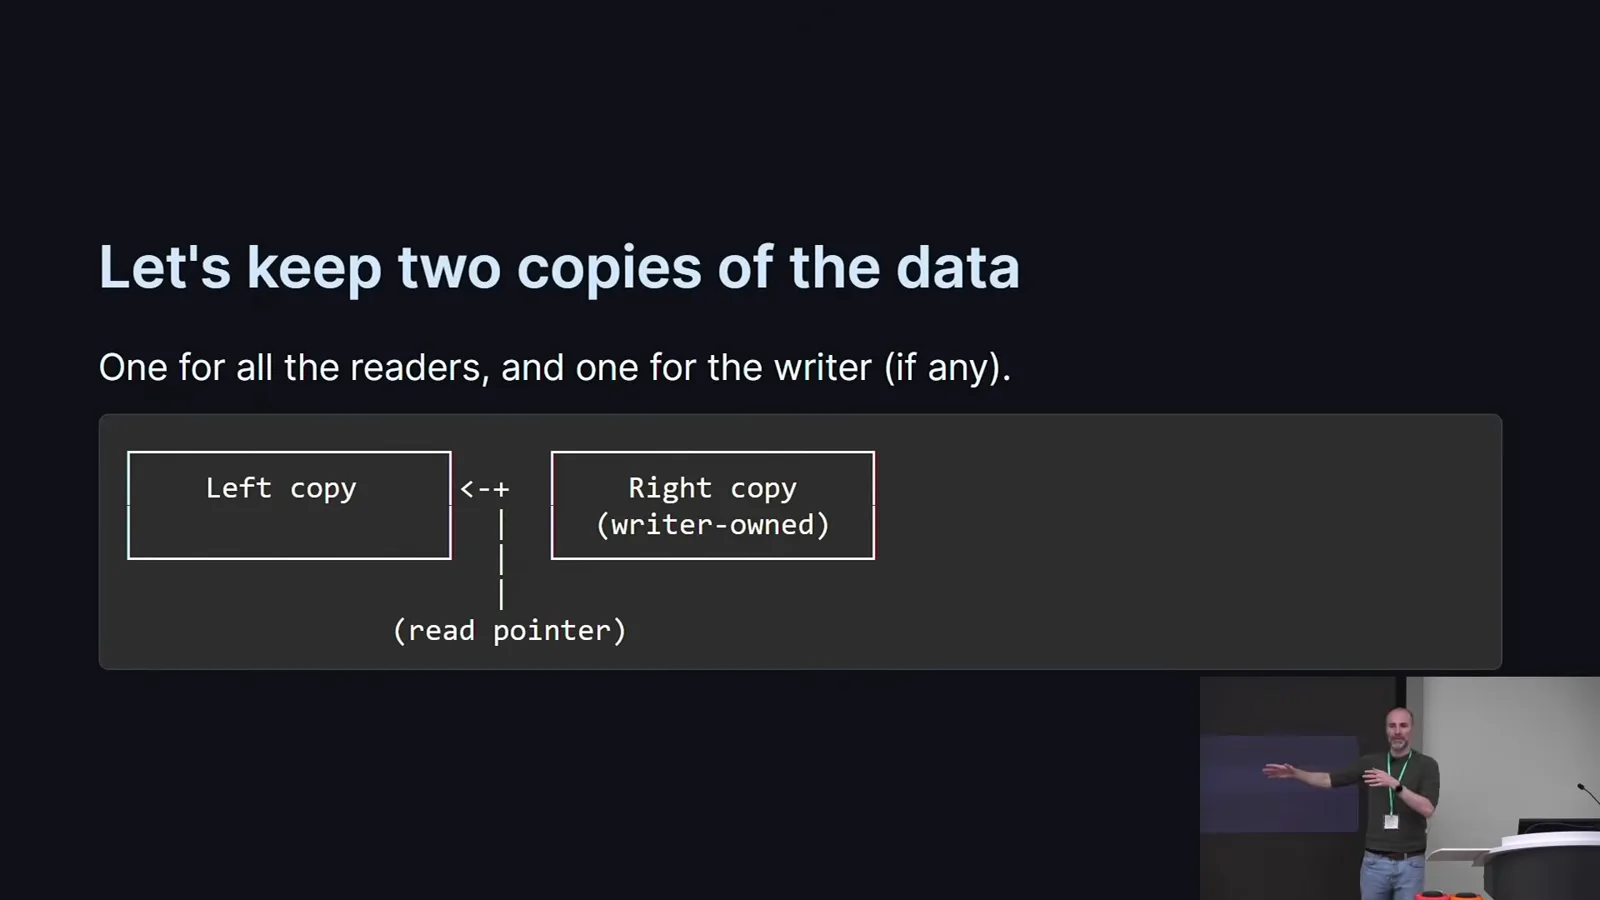
Left-right holds two copies of the data and an atomic pointer to the copy readers should use. The writer changes the other copy and then swaps the pointer. Readers starting afterward use the newly published copy; existing readers may still be using the old one.
Before modifying the old copy, the writer must know that earlier readers have finished with it. Each reader has its own counter, ideally on a separate cache line. The writer scans these counters after the swap to determine when it is safe to proceed.
Readers do not update a shared reader count or coordinate with one another. Their local counter can stay owned by their core except when a writer examines it. Reads can proceed without waiting for a concurrent writer; in this design the read path is wait-free.
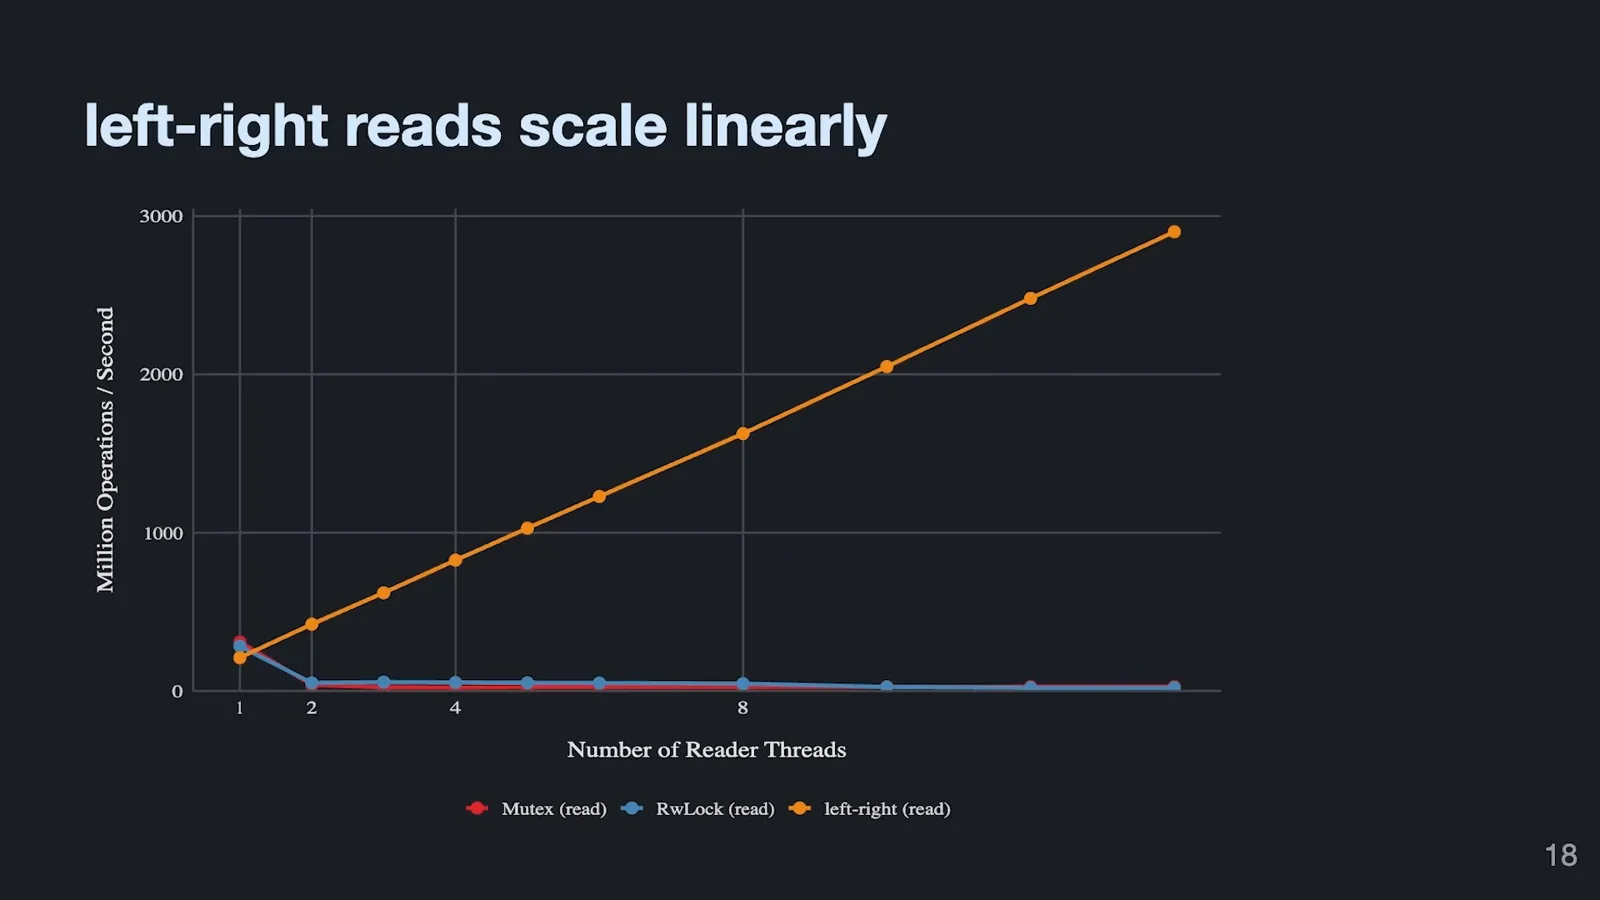
The read-only benchmark scales roughly linearly with reader threads, reaching around three billion operations per second in the example. That follows from keeping readers independent, but the benefit depends on writes being rare.
An audience member asks about a dormant reader. I clarify that each reader increments its counter at the beginning and end of an operation; the writer can recognize an inactive reader from an even count or a changed counter. A reader that remains inside an operation can delay the writer, though it does not stop other readers.
False sharing and trade-offs
A benchmark regression reveals counters sharing a cache line. Gjengset discusses memory, writer and consistency costs of left-right.
Frequent writes introduce more contention and writer work. With more writes than reads, left-right can perform worse than a reader-writer lock. It was designed to exploit a particular workload, not to win every benchmark.
While benchmarking, I found an unexpected roughly tenfold drop at four cores. The cause was false sharing: independent reader counters had landed on the same 64-byte cache line, so separate writes still moved ownership of that whole line between cores.
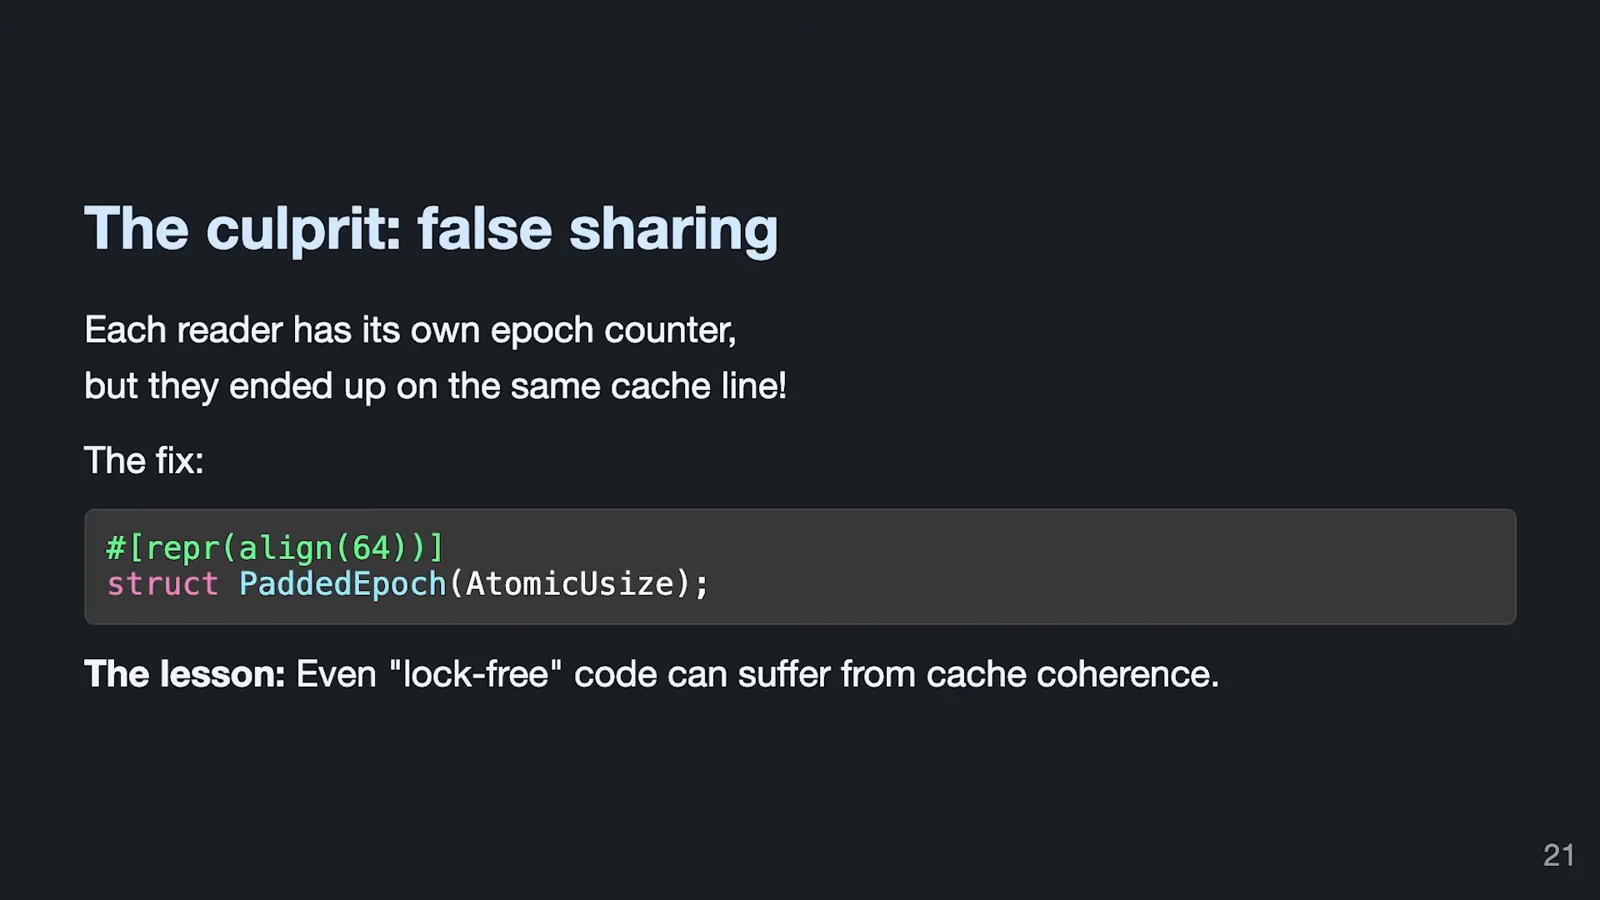
Adding 64-byte alignment to the counter type put counters on separate lines and fixed the observed problem. The lesson is that lock-free does not mean contention-free: hardware can still force cores to coordinate even when the program contains no lock.
Choose a concurrent algorithm for the actual data-transfer pattern, rather than picking the fastest-looking primitive from a benchmark. Left-right is not a drop-in replacement: two data copies cost memory; readers may see stale values; and the design supports a single writer unless additional synchronization is added.
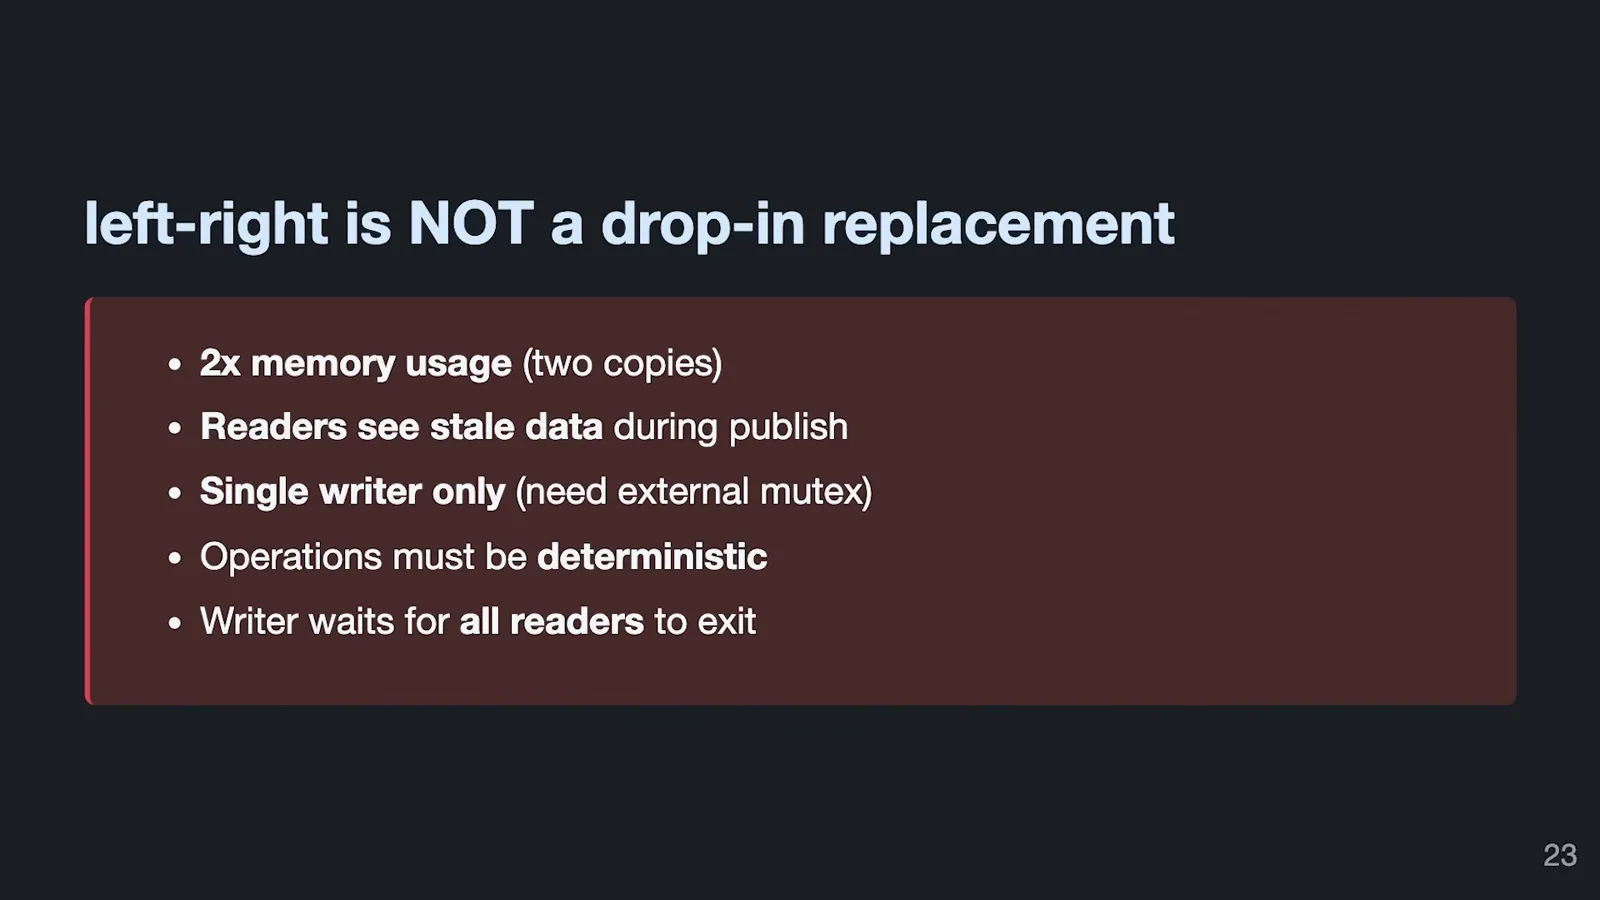
The writer can wait until readers have moved to the new copy, at an added cost. Updates also need deterministic operations and a log that can replay changes to the other copy; otherwise the copies diverge. The writer must wait for readers still using the old copy.
Left-right offers eventual consistency rather than linearizability, so I would consider it for caches or lookups, not financial transactions. It may not guarantee reading your own write immediately. Mutexes, reader-writer locks and left-right each make sense for different requirements.
Choosing and measuring
Workload ratios, critical-section length and consistency requirements inform the choice. Coordination rather than the lock interface alone drives cost.
Ask about read-to-write ratio, critical-section length, thread count and consistency requirements. Can readers tolerate stale data? Must they see their own writes or satisfy linearizability? Measure before optimizing, and use the answers to choose a design.
The main cost is coordination caused by cache coherence, with locks being one interface through which it appears. Other designs, including scalable reader-writer locks with per-core counters, can move coordination costs to writers. The right choice depends on the workload.
Audience questions
Questions cover hardware advances, reader registration, mutex implementations and compiler ordering barriers. Gjengset distinguishes known behavior from uncertain hardware details.
Asked about hardware advances, I mention improvements to MESI-like protocols and three-dimensional cache packaging, which can increase nearby cache capacity. I also describe research into combining fetch-add operations, while noting that proprietary implementations make current hardware details difficult to verify.
An audience member asks about readers joining and leaving left-right. Its current reader list is protected by a mutex during registration; existing readers do not take that mutex on every read. A lock-free list could reduce registration contention if it became a bottleneck, with care around the writer’s post-swap scan.
On mutex implementations, I describe Linux futex support and optimizations that reduce lock size. Packing small locks together can itself cause false sharing. Reader-writer locks retain more implementation variation, including approaches with per-core reader state.
Asked about compiler optimization, I explain that synchronization implementations use ordering barriers to prevent reads or writes moving across a lock in unsafe ways. Some constraints apply to the compiler, some to the CPU, and some to both; the implementation must provide the appropriate ordering.
같은 채널의 다른 글
 15:33EN
 1:48:29EN
 1:36:37EN
 1:05:45EN
 1:25:00EN
 1:16:29EN