30초 요약
Cyrus Omar demonstrates the Hazel research programming environment and argues for a live, type-theoretic computational commons. He discusses incomplete programs, incremental execution, agent feedback, collaborative editing and security, then answers questions about scale, data, adoption and deployment.
- 1Programming through holesHazel keeps structured feedback available while expressions are incomplete.
- 2Direct manipulationInteractive table and music controls are connected to executable code.
- 3Feedback for agent swarmsOmar argues that incremental tools can reduce delays for agents as well as people.
- 4Collaboration and securityStructured edits, versioning and scoped capabilities are proposed as foundations for shared work.
- 5Deployment in a live worldContent-addressed versions can remain available while updates happen deliberately.
핵심 정리
- Live feedback can expose useful values even while parts of a program are unfinished.
- Interactive graphics and code can provide connected views of the same computation.
- AI agents also benefit from timely feedback, although the proposed integrations remain under study.
- Structured collaboration, versioning and limited capabilities address different parts of trustworthy shared work.
- A live commons must also accommodate large external datasets and deliberate deployment.
챕터별로 다듬은 전문 읽기
Why feedback loops matter
Omar compares programming feedback to the immediacy of playing a piano. He introduces the gap caused by incomplete or erroneous programs.
Cyrus Omar begins with a simple question: what makes a feedback loop useful? A pianist hears the result of each key immediately and can adjust. Programming often imposes much longer delays between an edit and evidence of what it does.
Good feedback is timely and specific enough to connect an action with its consequences. If a piano only played its notes much later, learning and correcting a performance would be much harder; the same principle applies to programming tools.
Traditional editors and compilers can leave a gap when a program is incomplete or contains syntax and type errors. Services that depend on a successful parse or typecheck disappear precisely when a programmer is editing and may need feedback most.
Live programming in Hazel
A quicksort demonstration shows holes, probes, tests and recursive execution. Audience questions explore types, side effects and runtime limits.
Hazel is a research programming environment and language designed together to narrow this gap. Omar demonstrates a quicksort implementation to show how the editor can keep providing information while code is unfinished.
He starts with a recursive function: partition the tail of a list around its first element, recursively sort the resulting pieces, and combine them with the pivot. Hazel lets him leave parts of the expression as holes while he constructs the rest.
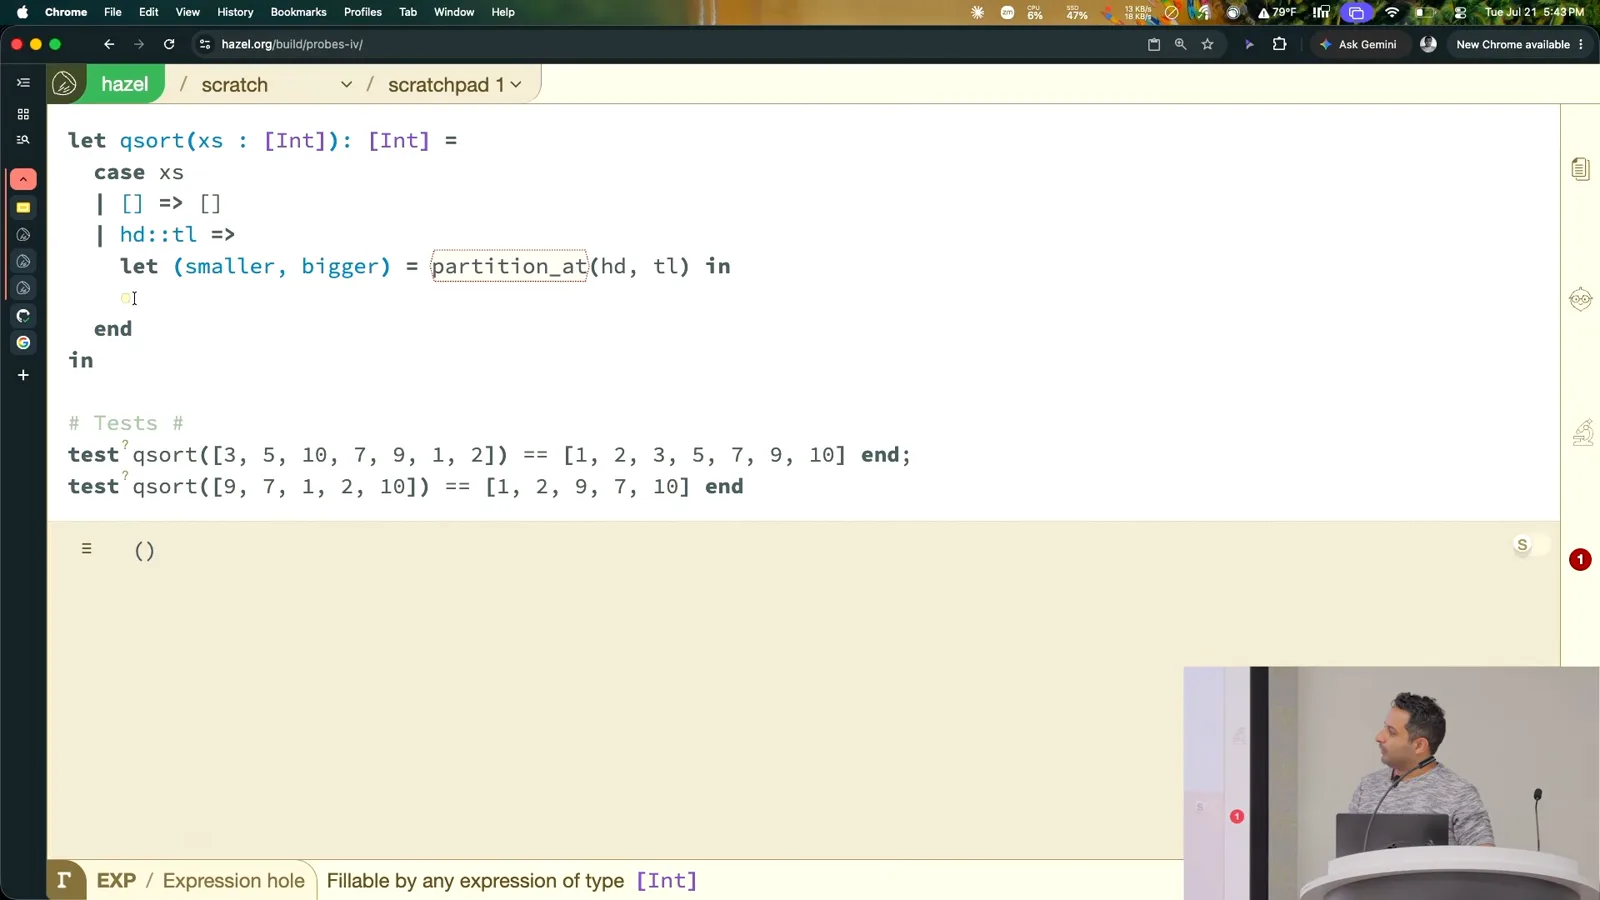
A conventional parser may reject an incomplete expression before the typechecker ever sees it. Hazel instead represents the missing or erroneous portion explicitly, allowing the rest of the program to retain a meaningful structure and continue receiving editor support.
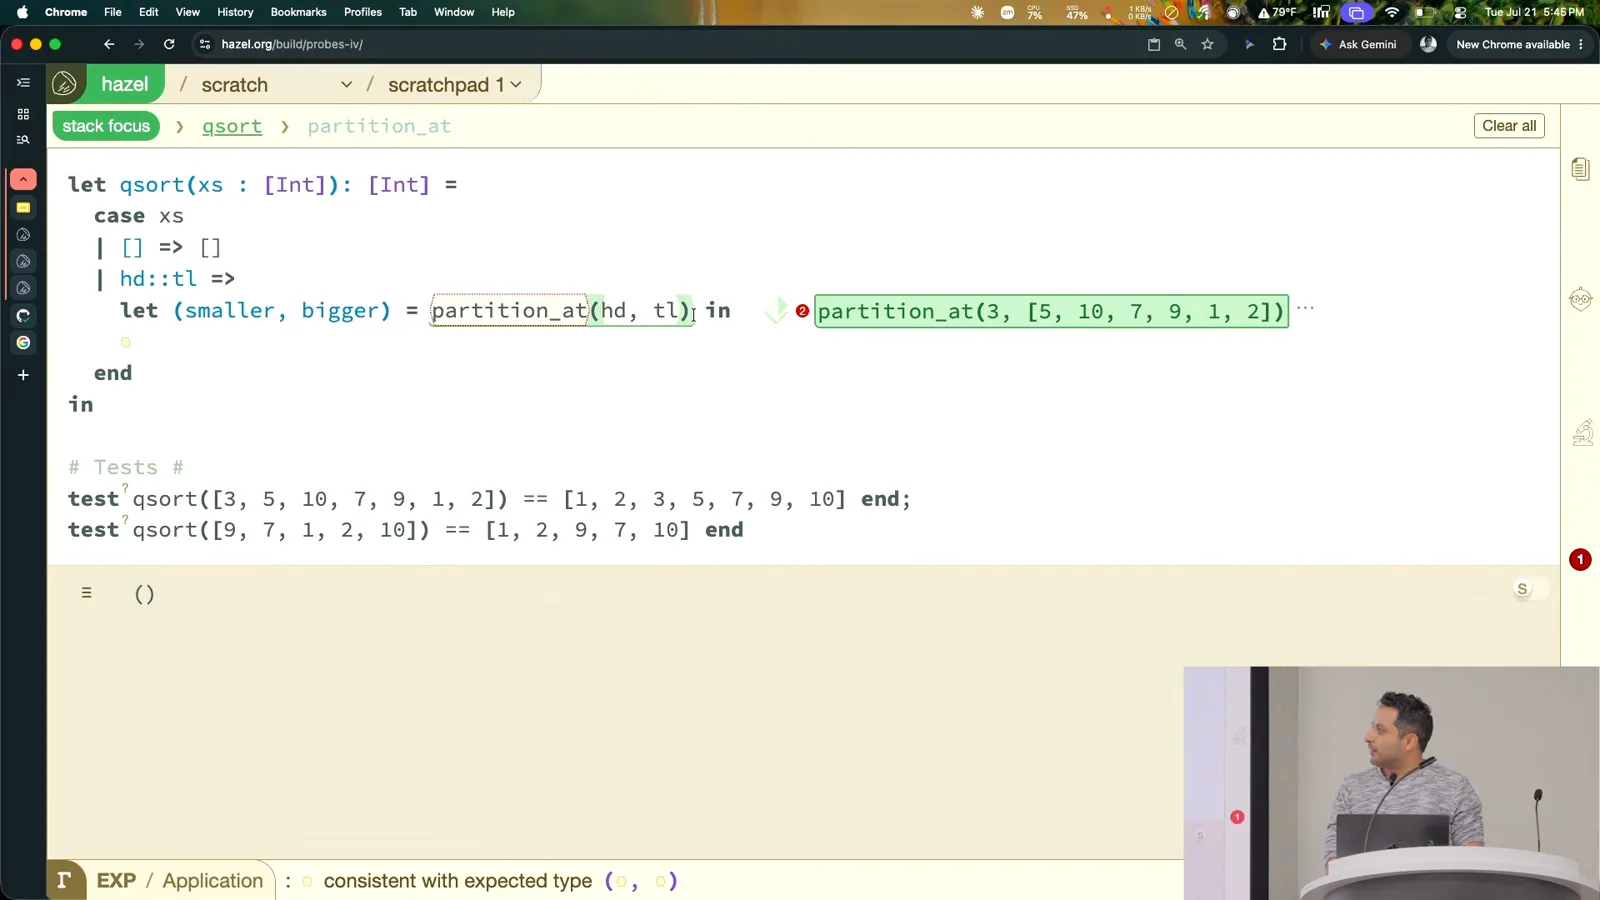
A probe can be placed on an expression to show the values it takes as the program runs. Even with a missing part, the result can contain a symbolic representation of the unfinished computation rather than giving no feedback at all.
The demonstration makes a mistake visible: the supposed sorted list contains repeated threes. Omar follows values through the recursive function rather than waiting until the whole program is complete and debugging only from its final output.
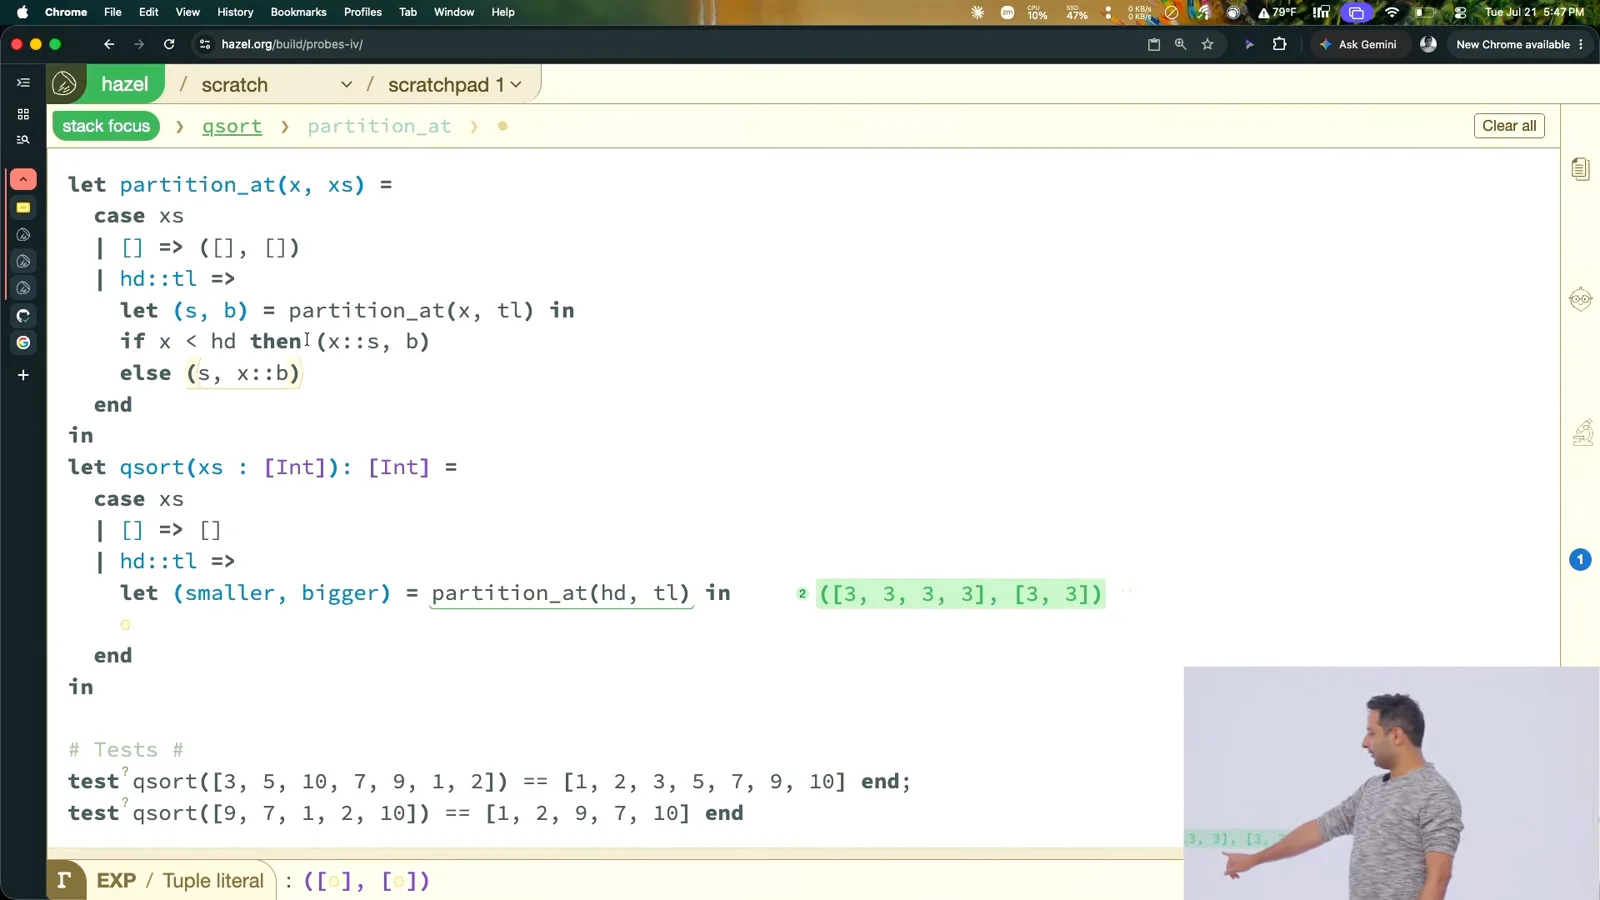
The intermediate results help locate the problem in how the pieces are assembled. By inspecting the partition and recursive calls, he can see that an apparently small change in the code affects the output immediately.
An audience member asks about recursion limits. Omar explains that the live environment must manage potentially unbounded computation, and that in practice it applies limits so that a nonterminating program does not freeze the editor.
Asked about side effects, Omar says Hazel is inspired by Haskell's treatment of effects: an I/O value could be computed as a value, then explicitly run when the user wants to perform the effect. This distinction matters when evaluation happens repeatedly during editing.
The test keyword reports the result of an assertion directly in the editor. Probes are different: they expose intermediate values, including values from multiple invocations of a recursive function, so that a programmer can inspect what happened inside the computation.
Stepping into a selected sample follows a call to its definition and selects the corresponding invocation. The interface can show multiple samples or focus on one, making the repeated execution of the same expression easier to understand.
An audience member asks whether replacing a part with a hole yields partially known values. Omar demonstrates that it does: the result can combine known list structure with a symbolic hole, continuing evaluation until the missing information is actually needed.
Another question concerns type inference when the program is incomplete or inconsistent. Hazel uses ideas from gradual typing and partial type information: it can present the information supported by constraints without pretending that all constraints have been successfully solved.
Collecting every intermediate value has a cost. Omar discusses controls such as limiting the number of samples collected at a point, and distinguishes the existing instrumentation from possible future optimizations such as a just-in-time compiler.
The audience also asks why some expressions appear highlighted even though a particular case has not run. Omar explains how the display relates to the samples available at a selected point; an unexecuted branch has no corresponding runtime sample.
Omar continues tracing the recursive calls and their partition results. Showing the successive contexts helps reveal what each recursive invocation receives and produces, rather than collapsing all executions into one value.
He adjusts the implementation and tests the result. The live tests provide immediate evidence of which cases pass, while an incorrect case exposes that a further correction is still needed.
Interactive tables and music
Graphical controls and data views are integrated with executable code. Direct manipulation changes the underlying program.
The next demonstration moves from lists of numbers to richer values. Hazel can render a table as an interactive object within the programming environment, connecting a visual view of data to the underlying program.
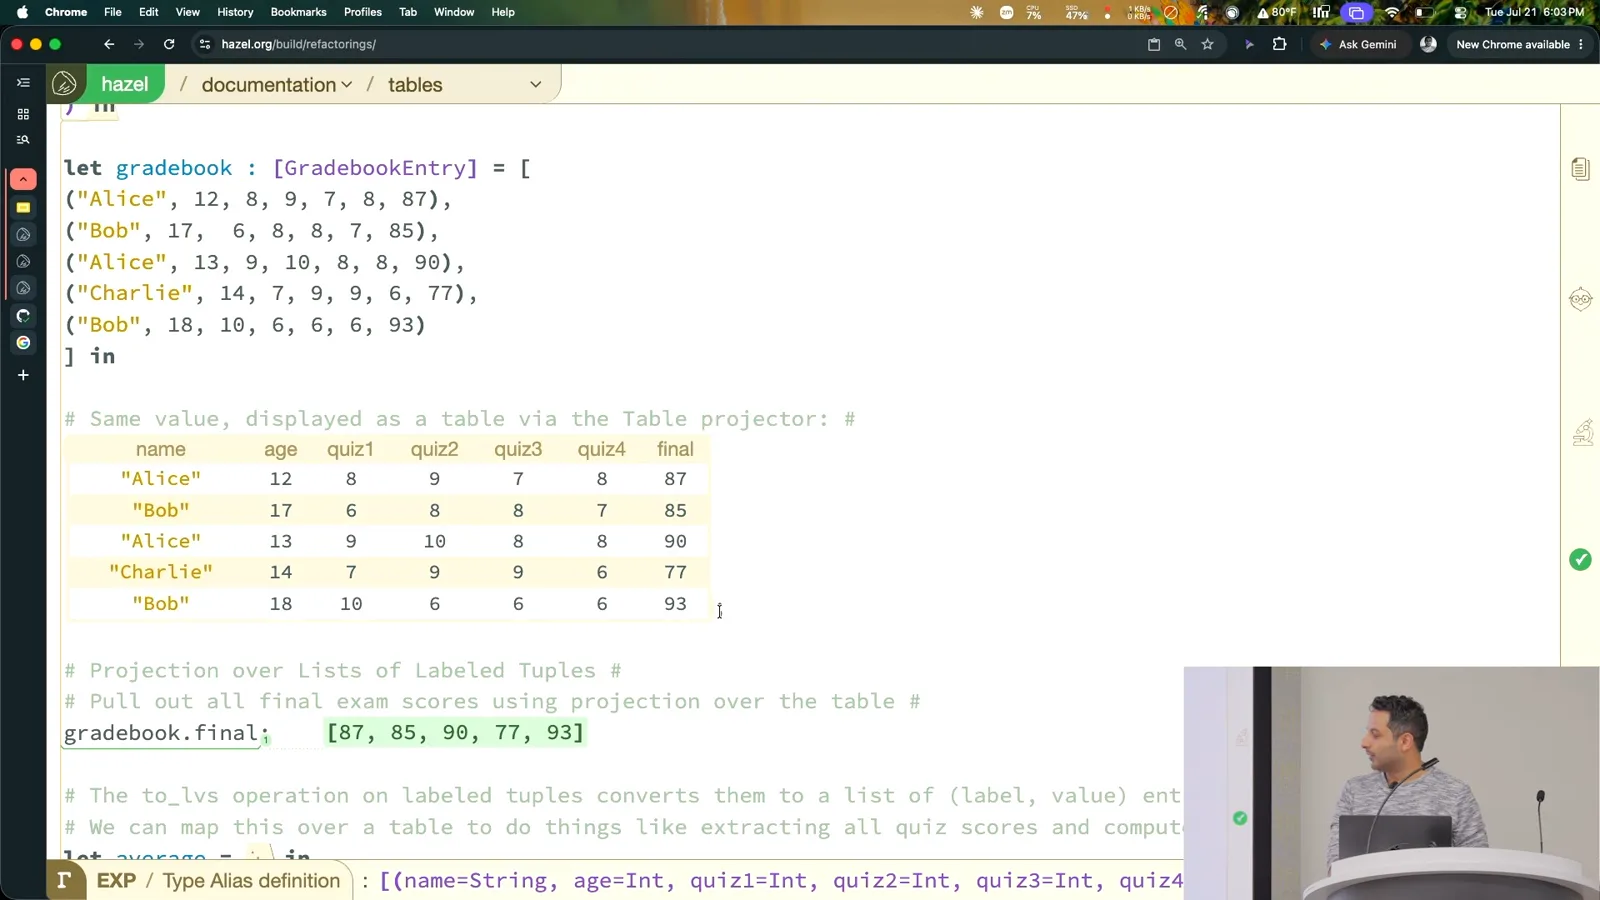
Sorting a grade table through its menu produces a corresponding program transformation. The graphical interaction and the textual code are two connected ways of working with the same computation, rather than a separate visualization detached from it.
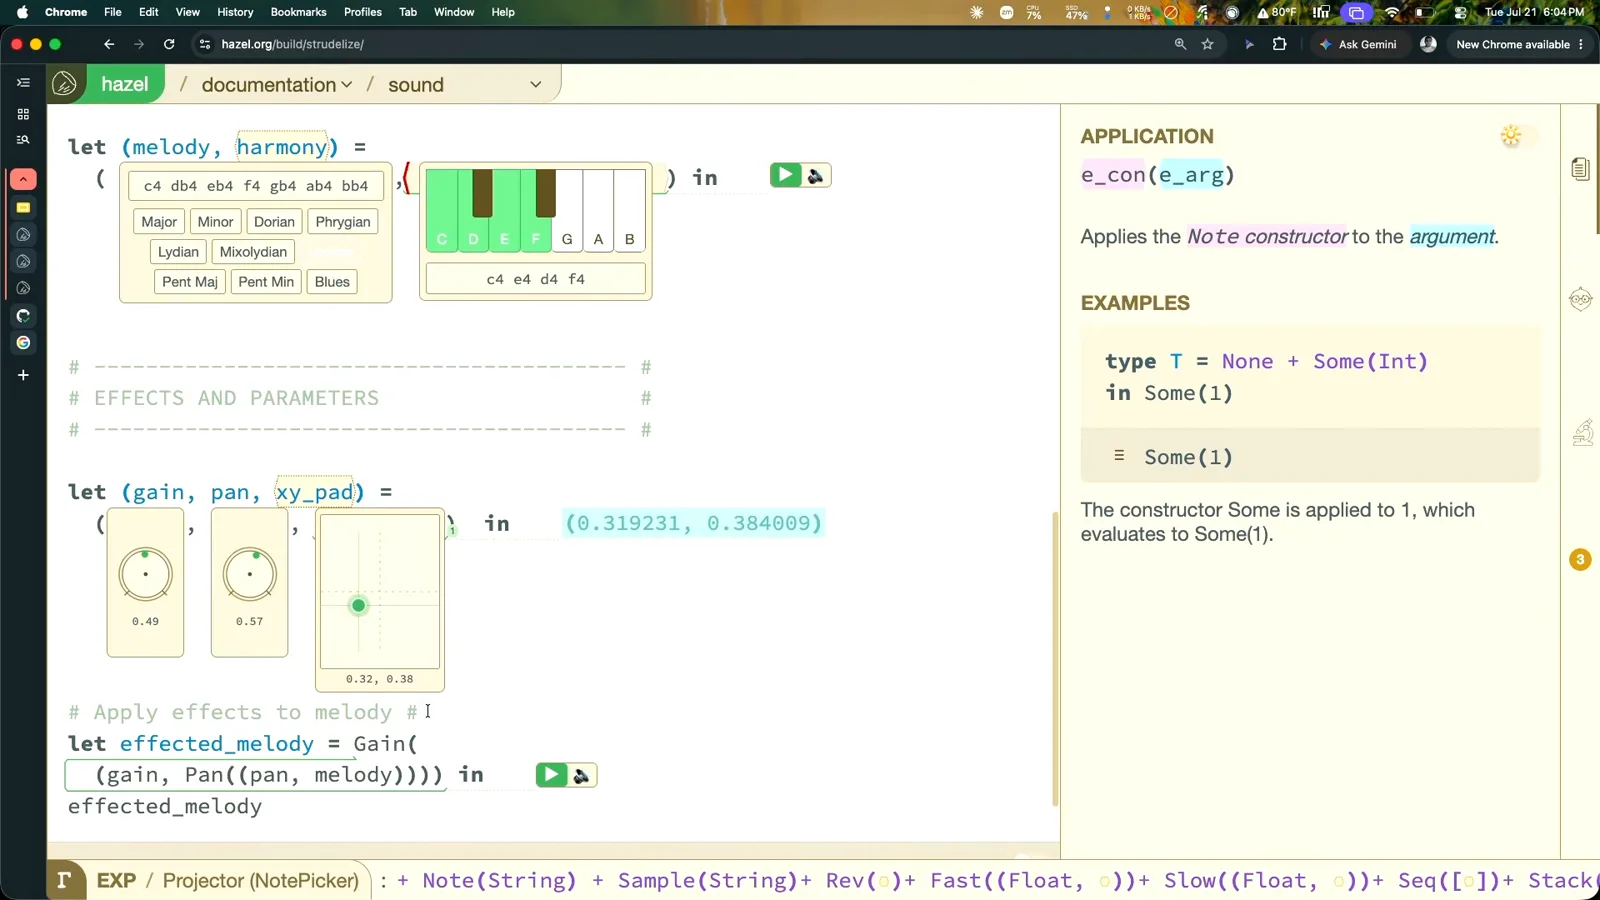
A music example combines a piano-like note selector, controls for gain and pan, and an interactive pad. These widgets let someone manipulate a program's values directly and hear the result, while remaining embedded in a compositional programming language.
Faster feedback for agents
Omar considers tool bottlenecks in agent swarms. He discusses incremental execution and early structured-agent experiments.
The same feedback problem extends to AI agents. In a swarm, many agents may work on one codebase and need to coordinate with one another as well as with people. Slow tools and verbose output can delay their feedback too.
As model generation becomes faster, recompilation, re-execution and re-establishing context can become bottlenecks. Agents also have to process large textual logs and recover the information needed for a subsequent action.
Omar argues that live, incremental environments can help agents as well as humans. Even if agents usually produce syntactically valid code, they still need timely information about the behavior and meaning of their changes.
Incremental execution reuses previous work when a program changes. Instead of rerunning every test from scratch after each small edit, an environment can track the affected computation and update what needs to change.
The team has been investing in incrementality for both execution and typechecking, with formal work on the underlying semantics. Omar describes shortcut memoization as research toward making repeated computations cheaper, not as a blanket guarantee that all work disappears.
An agent can also interact with Hazel through a structured action language rather than relying solely on shell commands and textual search. Actions can expose semantic information about code and changes in a form the agent can use directly.
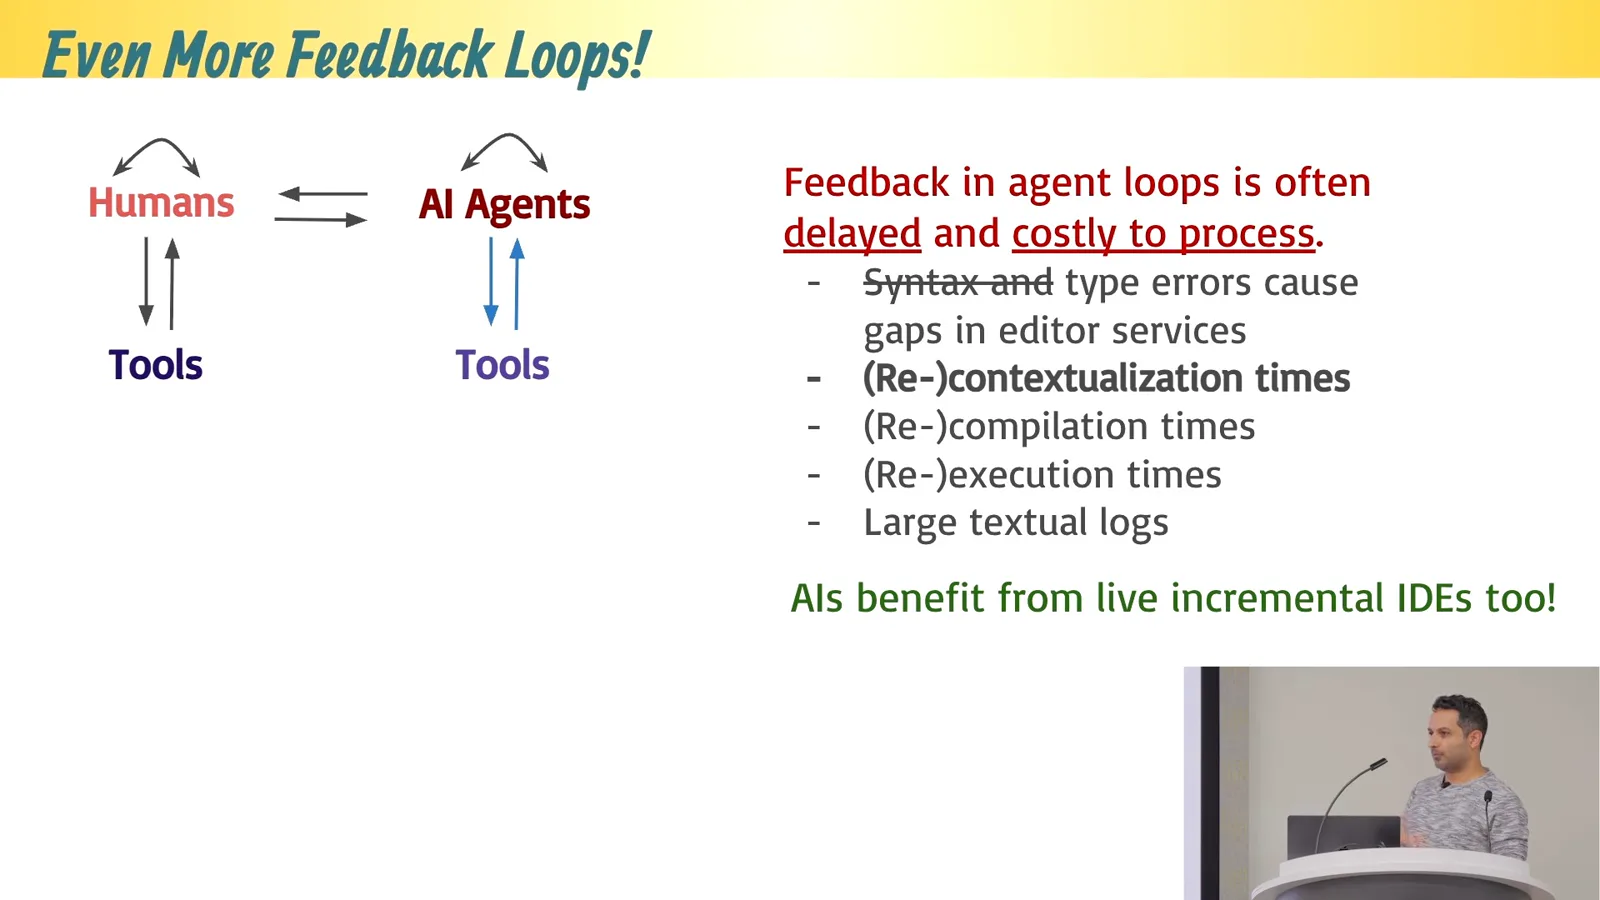
These agent integrations are early experiments, and Omar says formal studies are ongoing. The hypothesis is that shorter, more informative feedback may reduce the work and tokens needed for an agent to check its own progress; he does not claim a settled benchmark result.
Review, collaboration and security
Change tours help people review agent-generated work. Structured editing, versioning and capabilities provide possible foundations for collaboration.
Human review is another feedback loop. With AI increasing the rate of proposed changes, a reviewer may face a growing backlog of pull requests and need help understanding not just a diff, but the reasoning and sequence behind it.
Omar describes a VS Code plugin for narrativized change tours: a structured explanation can guide a reviewer through changes in an order that makes sense. Its goal is to help the person assess what happened instead of leaving them to reconstruct the story from a raw diff.
Collaboration also requires a representation that can support simultaneous edits. Omar describes research on structured collaborative editing with a conflict-free replicated data type, including moving code as a first-class operation so that relocations do not create unnecessary conflicts.
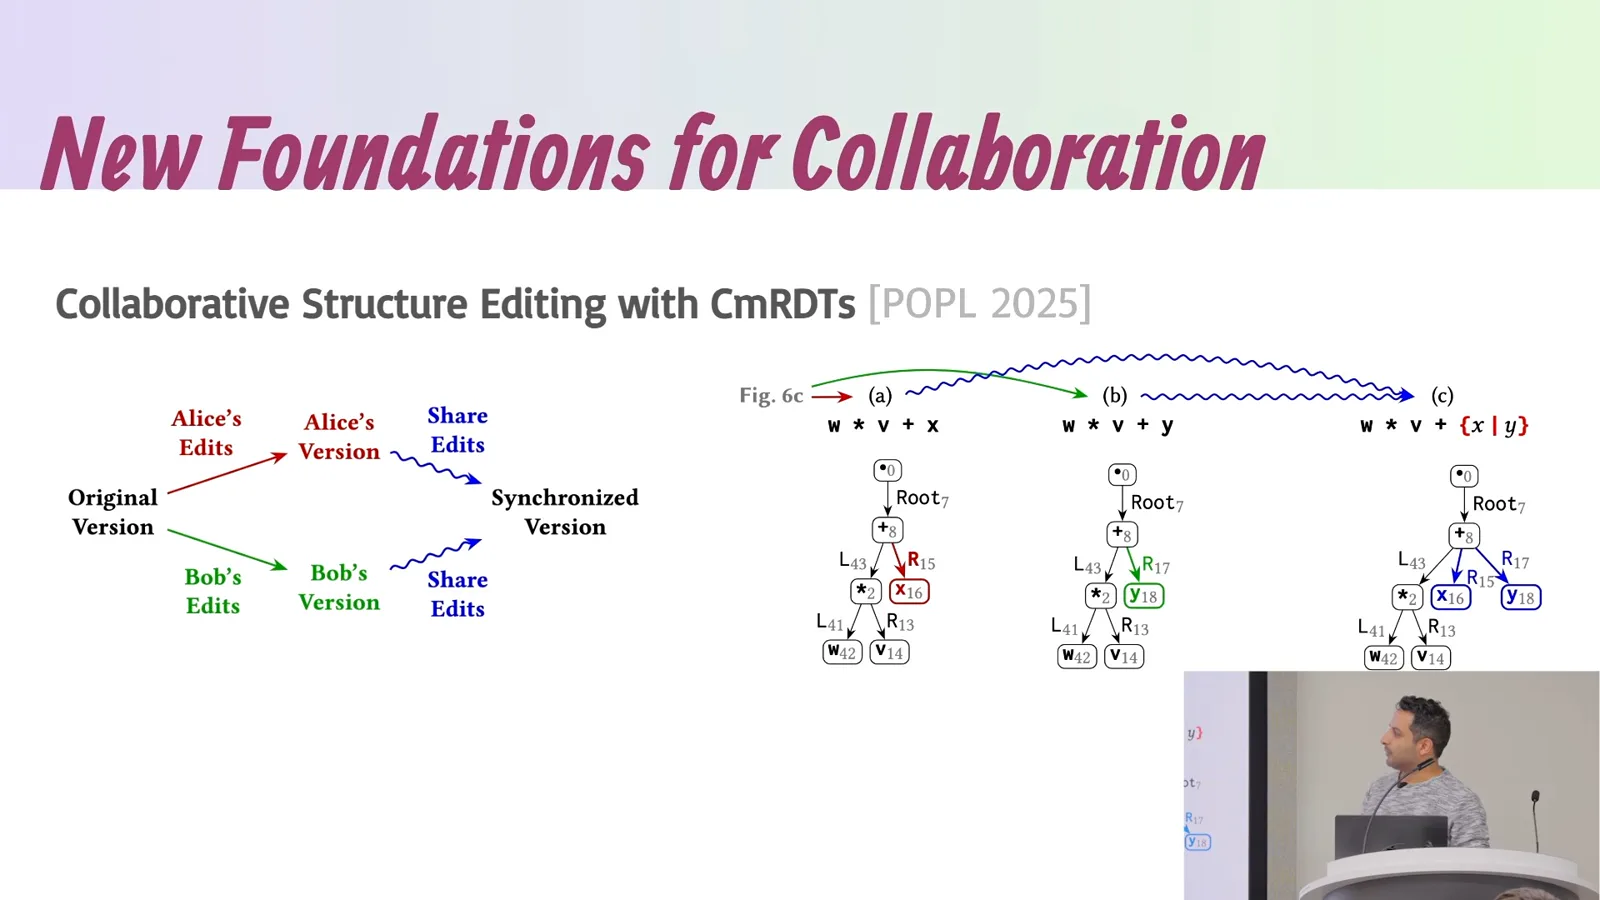
Versioning is a separate part of the problem. Drawing on Unison, he discusses identifying definitions by content and retaining old versions, so a new version can coexist with existing references and updates can be made deliberately.
Security becomes especially important when agents have access to tools and shared resources. Omar argues for fine-grained object capabilities: an agent should receive capabilities appropriate to a particular task, rather than unrestricted access to everything available to its operator.
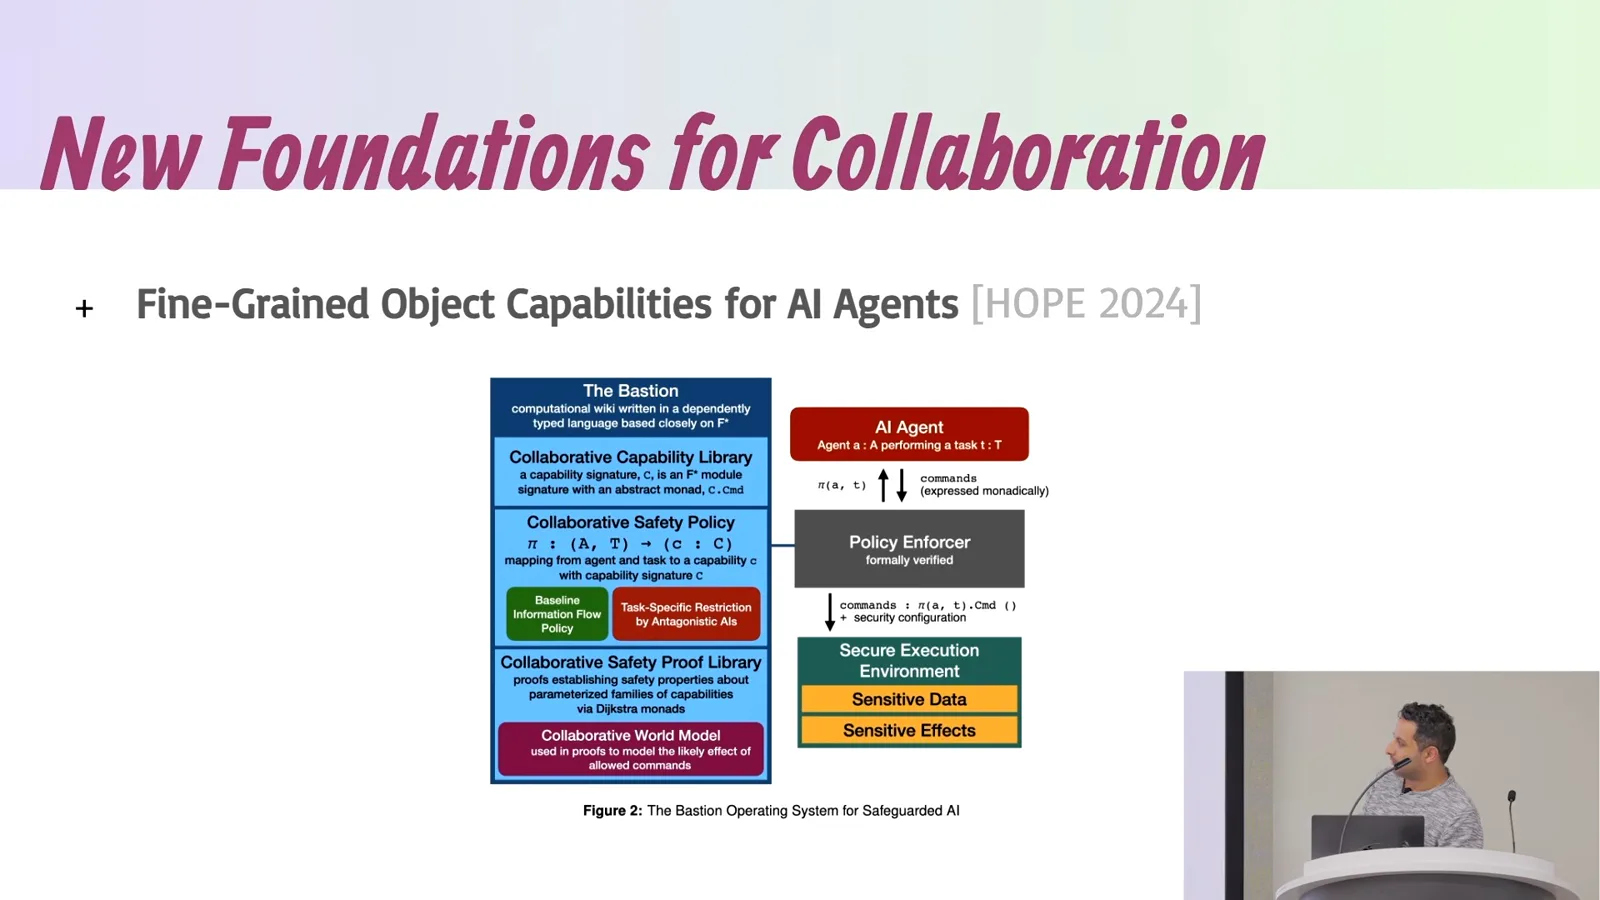
The proposed architecture combines a baseline policy and proofs with task-specific restrictions. He discusses the possibility of other agents helping supervise or restrict access, and information-flow policies for sensitive settings such as medical data. This is a research direction, not a claim that the whole problem is solved.
A computational commons
The vision brings people, agents, data and programs together in a live environment. Graphical interfaces could broaden participation.
Omar's larger vision is a live computational commons where people and agents collaborate on shared data, programs and explanations. Rich graphical interfaces could make useful participation possible for people who are not professional programmers.
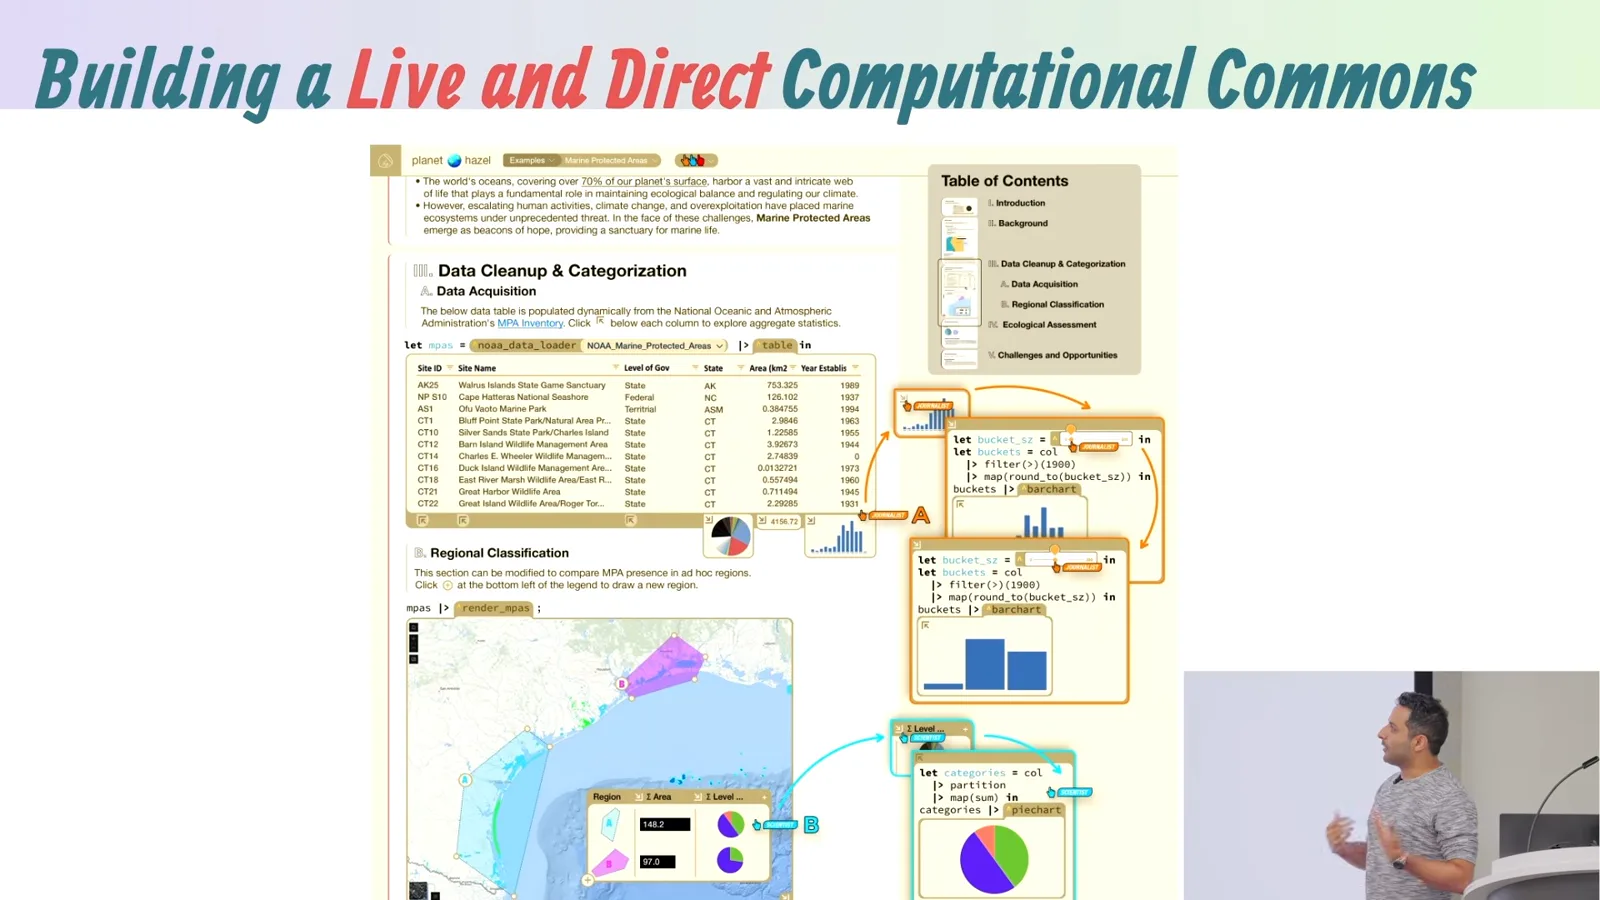
He illustrates the idea with an environmental data workspace combining prose, tables, maps, charts and executable transformations. Different participants could work with appropriate views while the underlying computation stays connected and can update as inputs change.
Questions on scale and foundations
The audience asks about existing agent workflows, proofs and large external datasets. Omar distinguishes research hypotheses from established results.
An audience member challenges the claim that existing tools are inadequate: their organization already runs thousands of agents with Git. Omar accepts that Git can work, and says the open question is when finer-grained structured collaboration becomes useful, especially for concurrent work.
He distinguishes the team's foundational results from proof that the approach works at the scale of a large production swarm. That empirical validation remains to be done; the talk offers a direction for experiments rather than a demonstrated replacement for current workflows.
In discussion of verification, Omar points to work on formal foundations and proof tools. A proof can establish properties of a specified model, but designing the system and making it practical for real collaborative work remain substantial research tasks.
An audience member asks how the commons would handle very large external datasets. Omar compares the conceptual model to a spreadsheet but says planetary-scale data would not literally reside in the editor's memory.
A foreign data interface could connect the runtime to external stores and push operations such as filters down to them, in a way inspired by Apache Spark. Omar suggests a possible just-in-time path to Spark for large datasets and invites further discussion.
Adoption and deployment
The closing discussion covers type theory, graphical tools, language adoption and versioned deployment. Omar emphasizes deliberate updates and continuing human processes.
Asked whether the essential prescription is that all code must be a tree, Omar says his stronger claim is about type theory as a foundation for ontologies. Products, sums, functions and modules can represent different kinds of things and relationships more effectively than treating every fact as an untyped binary relation.
He describes his approach to research translation as making an attractive, mathematically grounded system that others may either develop further or draw ideas from. He points to broader work on graphical code, live programming and holes as examples of ideas that can spread across communities.
Purity helps make evaluation on every keystroke safe. For languages with effects, a tool can instead accept the consequences of running them or conservatively identify expressions that appear pure; Omar cites Chrome developer tools as an example of the latter approach.
Another audience member asks how much people will understand as code becomes graphical and agents manipulate underlying layers. Omar credits collaborators for the design and observes that the cost of adopting a new language may have changed as AI makes porting code and building libraries easier.
His group has experimented with porting material such as Jupyter notebooks into Hazel for data-analysis case studies. He sees an opportunity for computer scientists to reconsider what tools should look like rather than assuming the cost of constructing an ecosystem must always be the same.
A final question asks how deployment works when a live environment is constantly changing. Omar sees value in more current climate data and models, but also recognizes that software users need stability and should not have dependencies silently changed beneath them.
He returns to Unison's approach: old content-addressed versions remain available, and updating existing code to a new version can be a deliberate decision. Good organizational processes and communication still matter alongside the technical machinery. He closes by thanking the audience.
같은 채널의 다른 글
 15:33EN
 1:48:29EN
 1:36:37EN
 1:25:00EN
 1:16:29EN
 27:39EN