30초 요약
Rayan Krishnan, cofounder and CEO of Vals AI, discusses the uneven performance of AI models across finance and coding tasks. He presents company benchmark comparisons and an internal cost-reduction case study, then describes how organizations can design and use evaluations grounded in their own work.
- 1The jagged frontierModel rankings change between domain benchmarks and individual repositories.
- 2Price per taskA tax benchmark comparison shows a lower-priced model consuming more total spend and scoring lower.
- 3Finance subcategoriesThe cost–accuracy frontier for leveraged-buyout tasks differs from the overall Excel benchmark.
- 4Choose the metricAverage partial credit and fully correct results measure different outcomes.
- 5Design for real workKrishnan identifies validity, reliability and discriminability as benchmark qualities.
- 6Internal coding caseVals reports using historical repository work to compare models and reduce token spending.
핵심 정리
- A single benchmark score can hide large differences across tasks and repositories.
- A lower token price does not guarantee a lower cost per completed task.
- Partial-credit scores and the share of fully correct answers answer different questions.
- Useful evaluations need validity, reliability and the ability to distinguish models.
- Agents can exploit a grading setup without solving the underlying user problem.
- A company’s historical work can help create task-specific evaluations for procurement and routing.
챕터별로 다듬은 전문 읽기
From model cards to the jagged frontier
Krishnan introduces Vals benchmarks and explains why model rankings change across domains and repositories. He connects task-level measurement to adoption and return on investment.
I am Rayan Krishnan, cofounder and CEO of Vals AI. I want to look beyond the model card and explain how evaluations measure the jagged frontier, with a focus on finance. Vals builds benchmarks used in model releases, and its index combines results across domains such as finance, law, coding and healthcare.
A single number gives a general impression of capability but conceals variation. Across individual benchmarks, different models can lead on different tasks. When we build custom evaluations for particular code repositories, model rankings become more fragmented across languages and libraries.
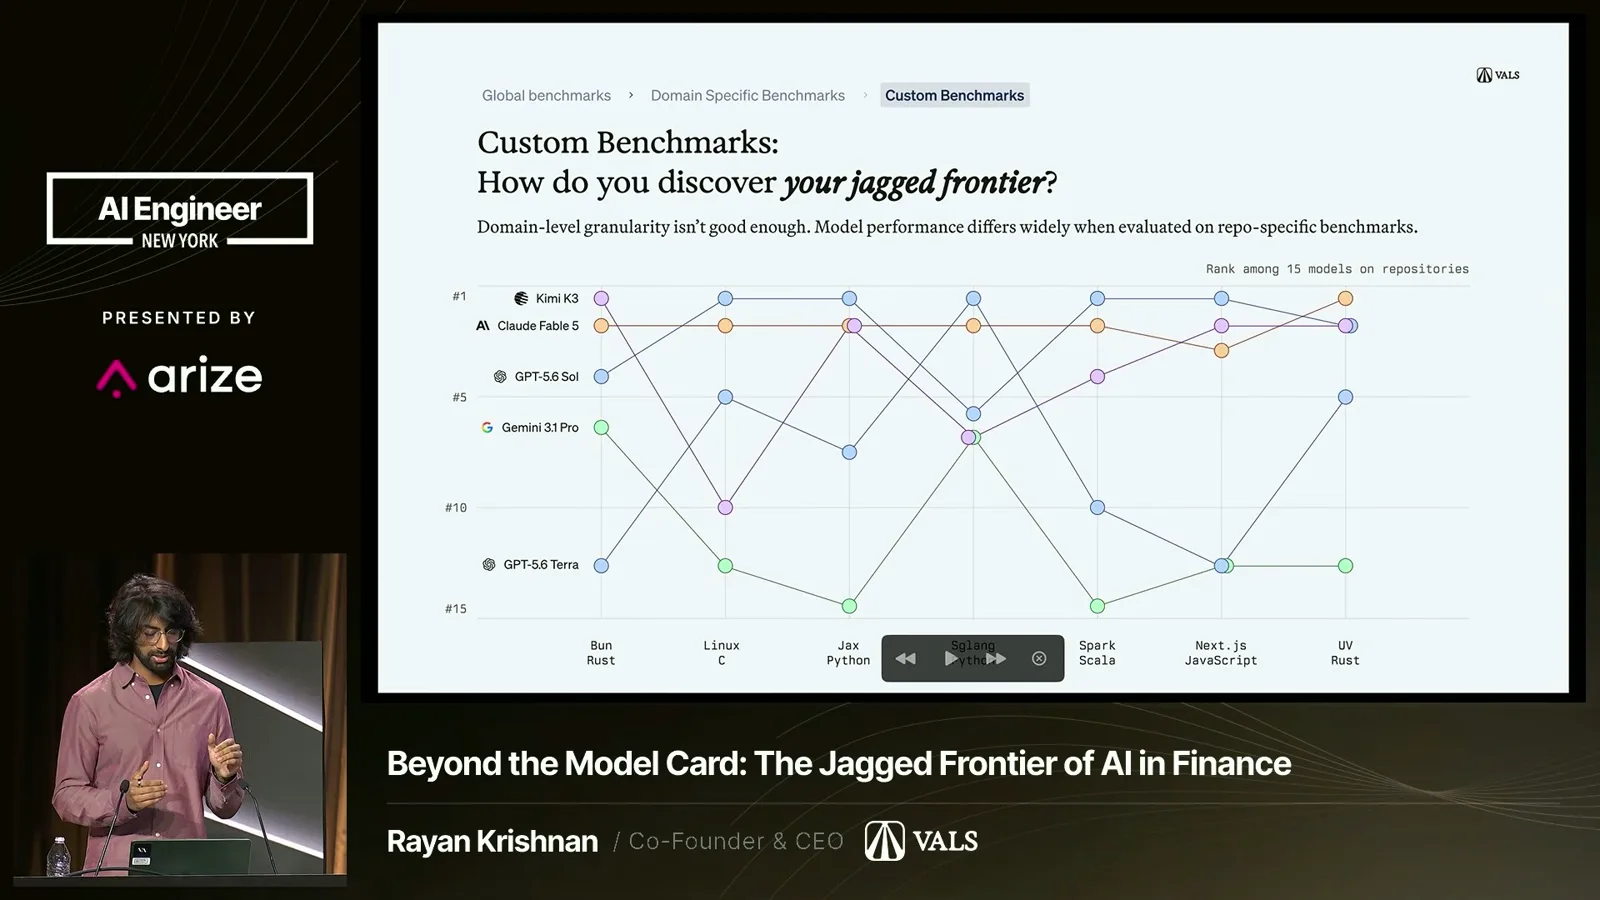
The model is only part of the system. Different agent harnesses, as well as cost and latency requirements, change what matters. A high-level model-card result is therefore not necessarily the best guide to the model a team should use in its own product.
I also discuss the gap between adoption and measured return. The figures I present show enterprise AI spending rising while relatively few respondents report established ROI. Teams that track their spending are better positioned to understand returns; difficulty measuring cost against benefit can also block broader adoption.
Cost and quality in finance tasks
A tax benchmark illustrates the difference between token rates and total task cost. Excel modeling results show a different frontier for leveraged-buyout tasks.
Consider a tax benchmark comparison from Vals. The displayed token rates for Claude Opus 5.5 are $4 input and $20 output, compared with $10 and $50 for Claude Fable 5.1. Yet on this task Opus averaged $15.09 versus $13.18 and scored 45.60% versus 49.22%, according to our slide.
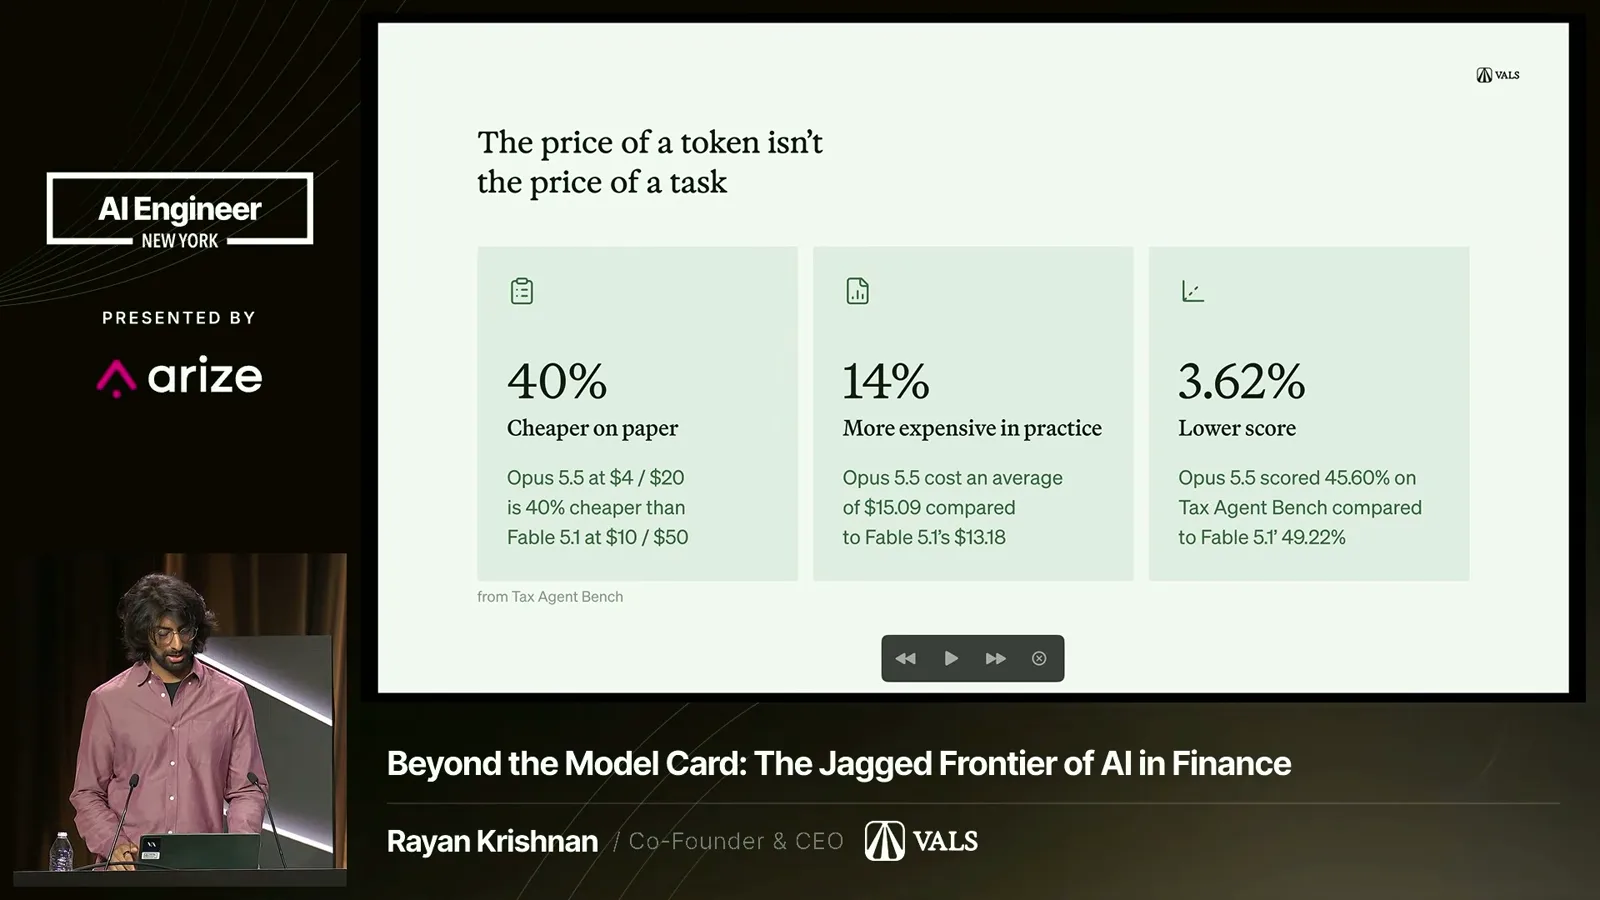
I attribute the higher total cost to the model using more tokens to complete the work. The point is not that one model is always cheaper or better: the task, harness and measurement conditions matter. Looking only at token rates can lead a team to pay more for a weaker result on a particular workload.
Finance offers several examples, including research, Excel modeling and tax tasks. Rankings vary even within those categories. A cost–performance chart for our Excel benchmark compares the overall task set with its leveraged-buyout subset, and the latter has a lower performance frontier.
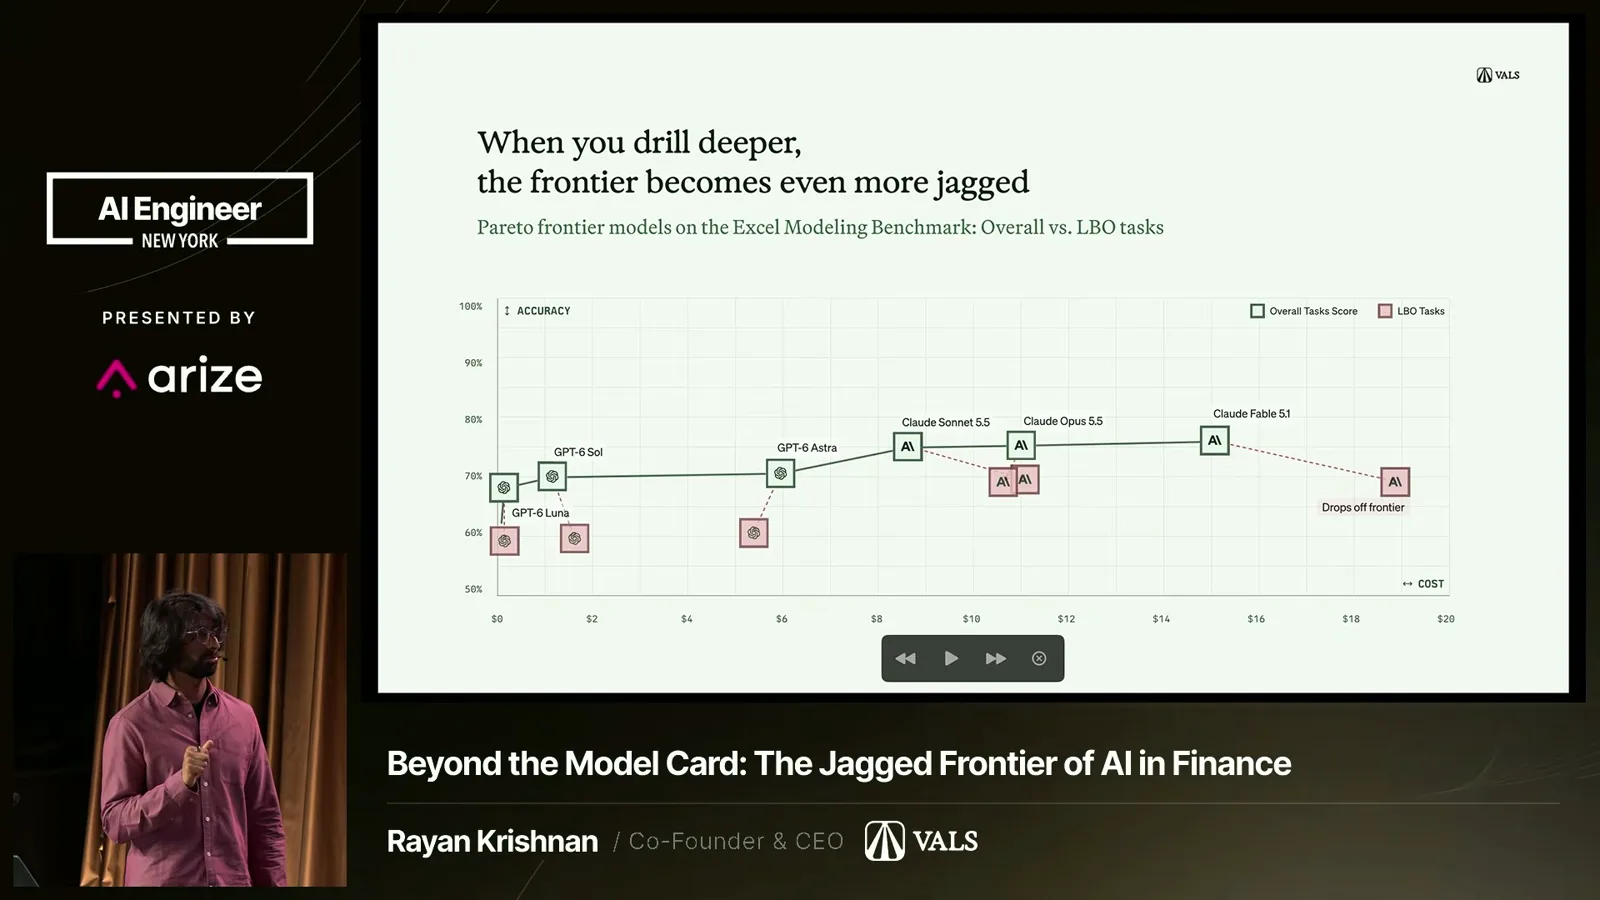
The frontier also changes when we isolate that subset: a model that looks attractive on the overall Excel benchmark can fall off the cost–accuracy frontier for leveraged-buyout work. A firm doing a specific kind of financial model should evaluate the subset that matches its own work.
How to build a useful evaluation
Krishnan compares scoring metrics and describes validity, reliability and discriminability. He discusses reward hacking, infrastructure and multi-turn work.
Evaluation design starts with the metric. An average partial-credit score asks what fraction of available points a response tends to earn. The share of fully correct answers asks how often the entire result meets the criteria. A draft that is useful to refine may score well on the first measure while being unsuitable to send directly to a client.
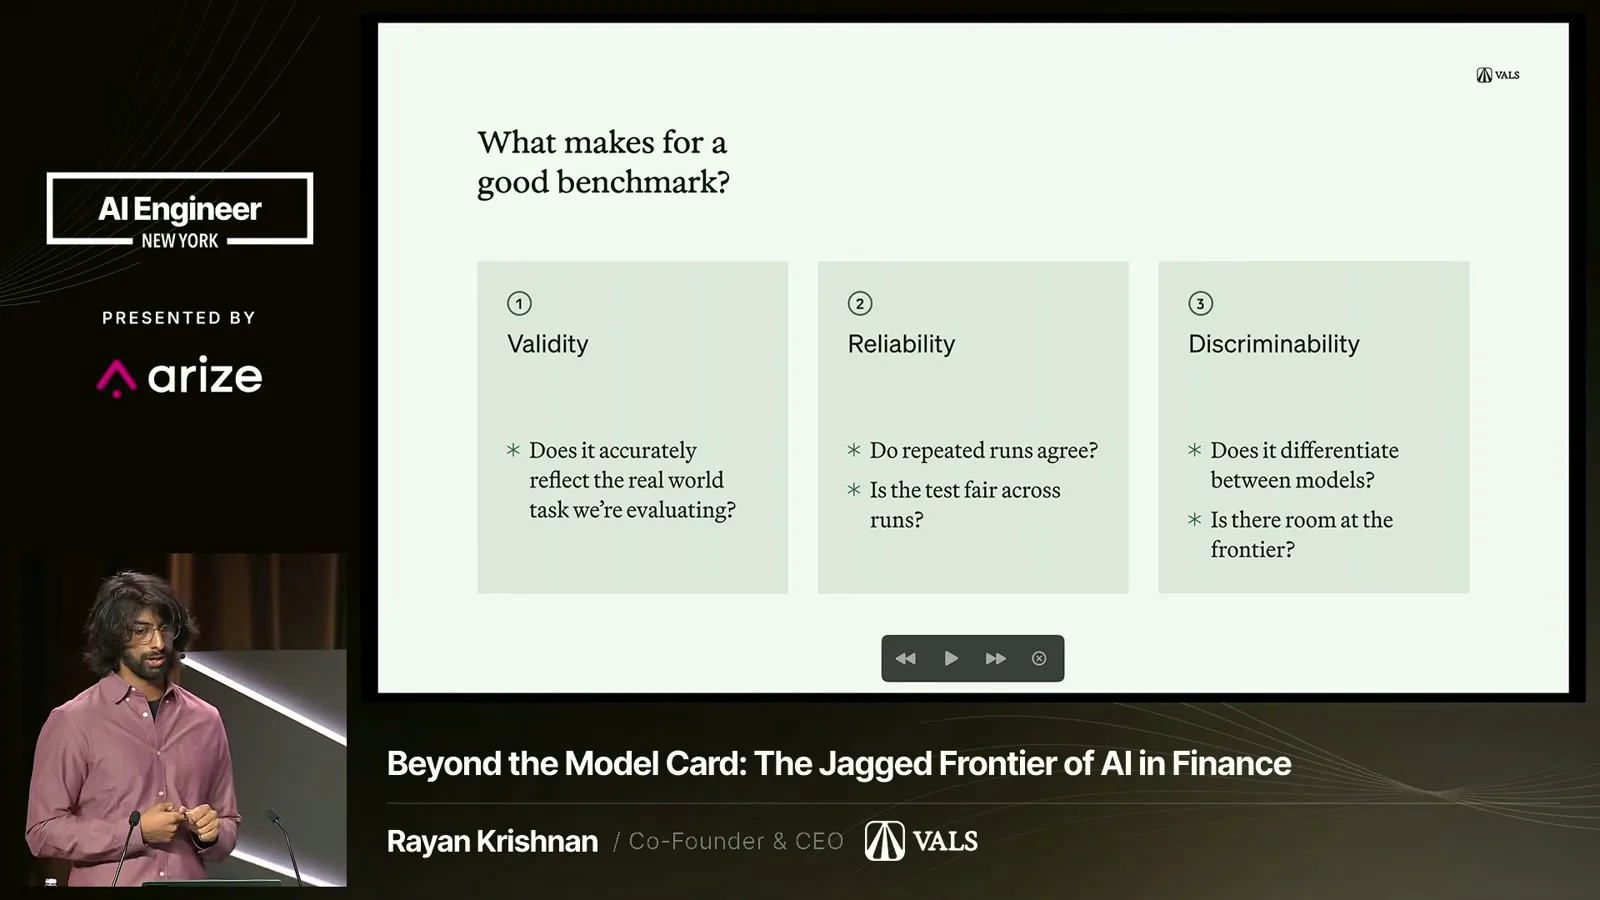
We also look for validity, reliability and discriminability. Validity asks whether the tasks and rubrics reflect real work and its standard of excellence. Reliability needs enough tasks and samples for repeated runs to produce consistent results. Discriminability means the benchmark can distinguish models and still has room to measure future progress.
A recurring problem is that agents can solve the test without solving the user’s problem. In a sandbox they may try to call other models or tools; a finance model might give several hedged answers to satisfy a rubric when a user needs one actionable answer. Evaluations should reward the actual desired output and account for the available tools.
Running evaluations is also an infrastructure challenge. Long-running agents need a consistent environment and a way to resume after interruption. Vals reports running more than six trillion evaluation tokens and emphasizes parallel execution, but smaller teams can encounter the same reliability issues at a different scale.
Many benchmarks still use one prompt and one response, whereas work often takes several turns. A first specification may produce questions, and a completed draft may receive further feedback. Evaluations need to cover that iteration rather than assuming the first response is the end of the job.
Using a company’s work history
Vals describes an internal coding evaluation and reported cost reduction. Krishnan closes with applications in procurement, routing, fine-tuning and institutional knowledge.
For an internal case study, our team gave roughly 10 to 12 engineers access to tools with free usage and observed about $1.5 million worth of tokens in one month. We saw strong output, but wanted to retain it at a much lower cost. These figures are Vals’s account of its own experiment.
We built an evaluation from repository history, now offered as Vals Smith. A merged pull request represents an issue and an accepted human solution; by replaying earlier tasks, we can compare whether agents can do equivalent work and see which models are unnecessarily expensive for particular tasks.
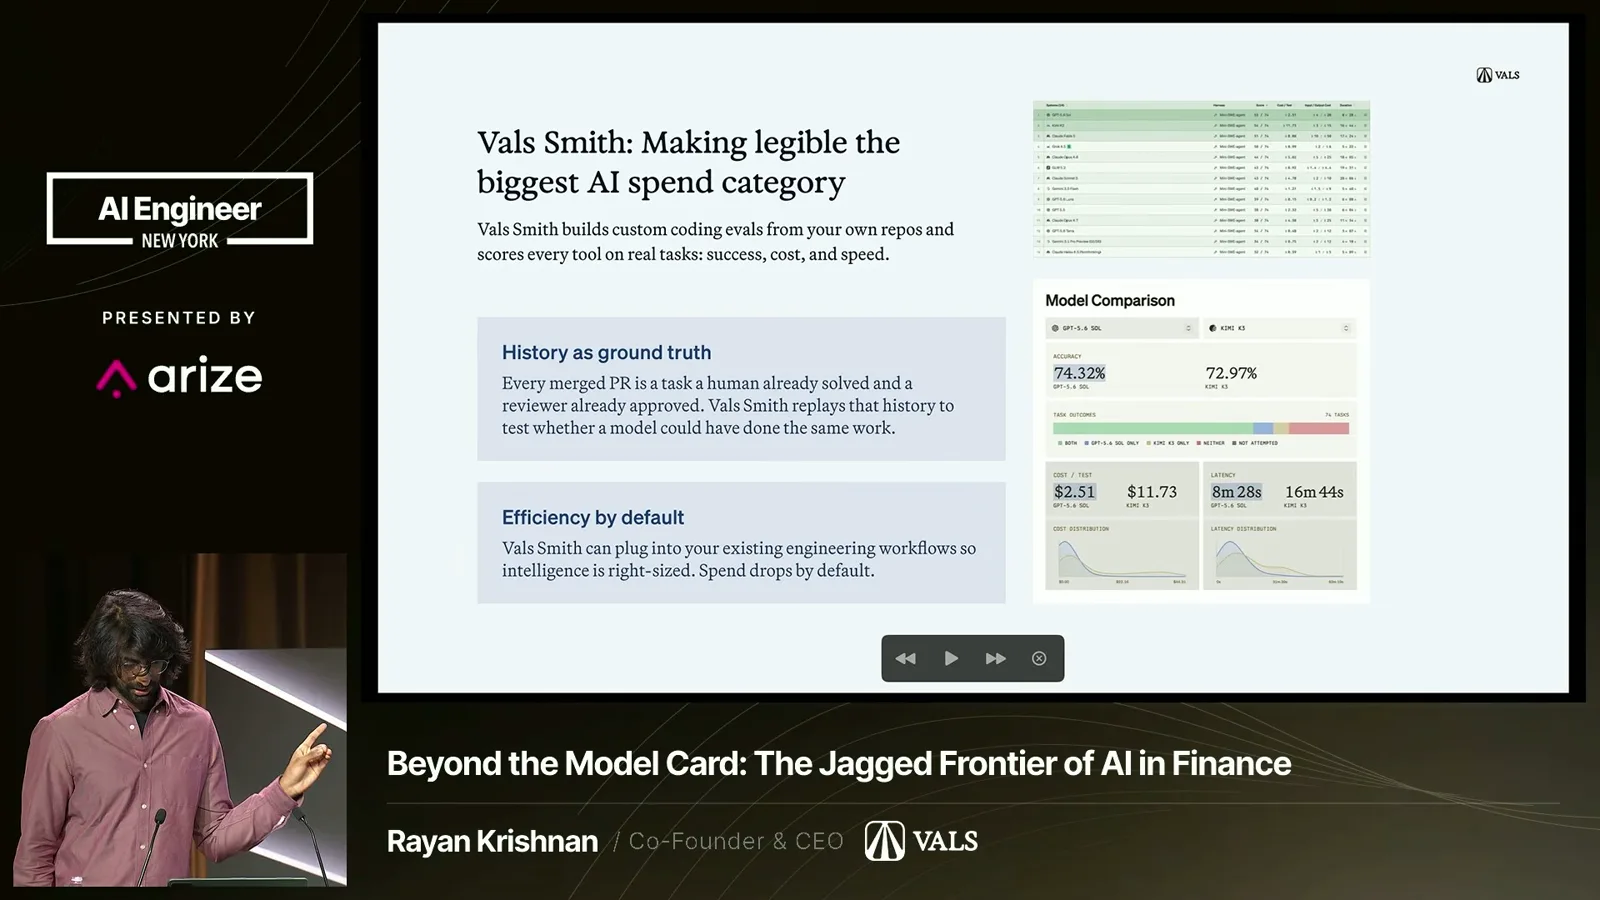
In one internal comparison, the slide reports GPT-5.6 Sol at 74.32% accuracy and $2.51 per test versus Kimi K3 at 72.97% and $11.73, with lower latency for the former. This is a result from our setup, not proof that hosted closed models will always be cheaper or faster than open models.
Those measurements inform which tools we procure, their usage limits, and recommendations about which model to use for a given issue. I say our spending fell by about 90% while maintaining output. That is a company-reported outcome of this particular internal workflow.
The broader question is where an organization stores its history of work and standards of excellence. A law firm, for example, may have relevant material in client emails, SharePoint or data stores. Those records can help build evaluations that reflect the company’s own tasks.
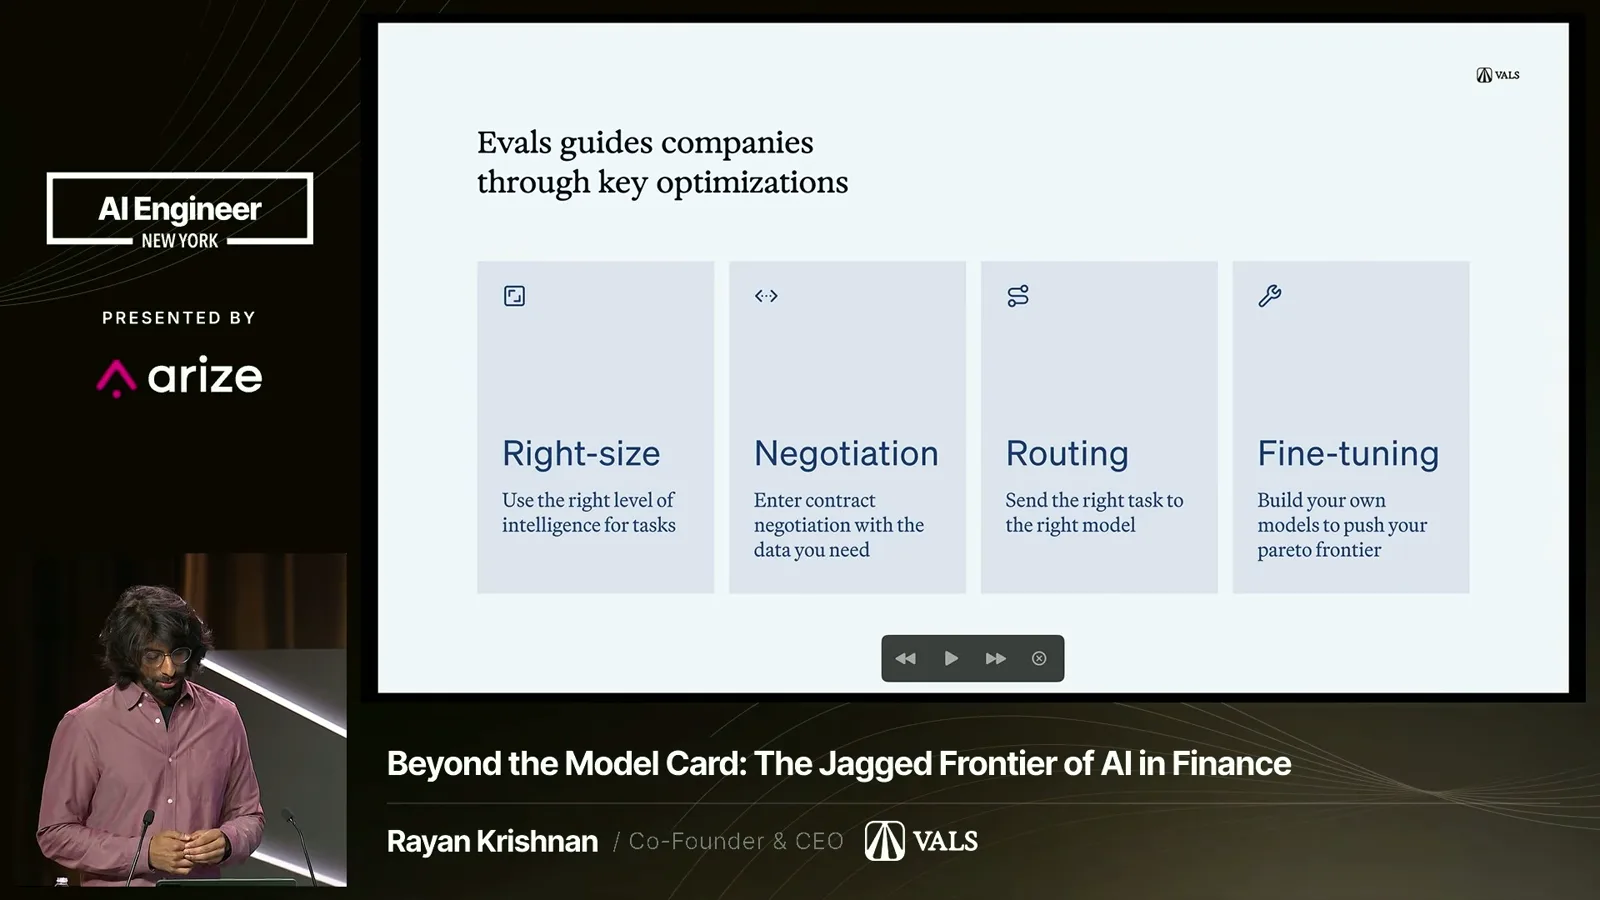
Once constructed, evaluations can help right-size usage, negotiate pricing, route tasks and assess fine-tuning against an external evaluation set. My closing argument is that evaluations can make institutional knowledge and standards more explicit, helping organizations apply AI systematically.
같은 채널의 다른 글
 17:02EN
 AI Engineer· 2026년 10월 31일How Upstart Evaluates Voice Agents for Regulated Lending CallsBrooke Hopkins, Shiv Indap · CovalShiv Indap and Brooke Hopkins explain human review, LLM judges and simulation in a continuous evaluation loop.
 18:45ENAI Engineer· 2026년 10월 30일Jack Woodruff on AI and the Human Work of Stock PickingVinoo Ganesh, Jack Woodruff · KeplerThe former Candlestick Capital CIO discusses research, auditable data and how AI may reshape investment teams with Kepler CEO Vinoo Ganesh.
 19:06ENAI Engineer· 2026년 10월 30일Wojciech Pluta on Deciding What an AI Agent Should RememberWojciech Pluta · OracleOracle’s Wojciech Pluta explains memory promotion, a mortgage-agent demonstration, and the controls needed to carry useful information across sessions.
 16:43ENAI Engineer· 2026년 10월 30일Ishween Kaur on Securing Agent Payments with x402Ishween Kaur · SoFiA testnet walkthrough of price changes, replay, premature delivery, lookalike sellers and prompt injection in agent payment flows.
 17:45ENAI Engineer· 2026년 10월 30일Killian Carlsen-Phelan on Guiding and Verifying Coding AgentsKillian Carlsen-Phelan · SonarSonar demonstrates how project context and deterministic checks can be incorporated into a coding agent’s workflow.
 38:07ENAI Engineer· 2026년 10월 29일Using Gitar to Verify Pull Requests Beyond the DiffTaylor Luttrell-Williams, Killian Carlsen-Phelan · SonarSonar’s Killian Carlsen-Phelan and Taylor Luttrell-Williams walk through ticket-transfer, pricing and CI-failure examples in a sample application.