30초 요약
Matthew Berman compares a SWE-bench Pro table with a DeepSWE leaderboard and argues that the rankings differ from what users feel when using the models. His criticism is an interpretation of the results, not proof that either benchmark is invalid.
- 1A benchmark questionedBerman says some people no longer take SWE-bench scores seriously because the ranking conflicts with their impressions.
- 2A different leaderboardHe says DeepSWE better reflects users' experience and cites approximately 70% for GPT-5.5 versus 54% for Opus 4.7.
- 3The opposite orderingThe displayed SWE-bench Pro table puts Opus 4.7 ahead of GPT-5.5 and shows a higher score for Opus 4.8.
핵심 정리
- Berman questions whether SWE-bench scores reflect users' experience of coding models.
- He cites DeepSWE results of approximately 70% for GPT-5.5 and 54% for Claude Opus 4.7.
- The displayed SWE-bench Pro chart ranks Opus 4.7 ahead of GPT-5.5 and shows a further increase for Opus 4.8.
챕터별로 다듬은 전문 읽기
Comparing SWE-bench and DeepSWE
Berman questions the fit between SWE-bench rankings and users' impressions. He compares the displayed results with DeepSWE and comments on Opus 4.8 and Gemini 3.1 Pro.
This is where it gets interesting. A lot of people are saying SWE-bench is done: with scores like these, they don't think it can be taken seriously. Opus 4.7 is about seven or eight points ahead of GPT-5.5 on the chart, which doesn't match their impression of using the models.
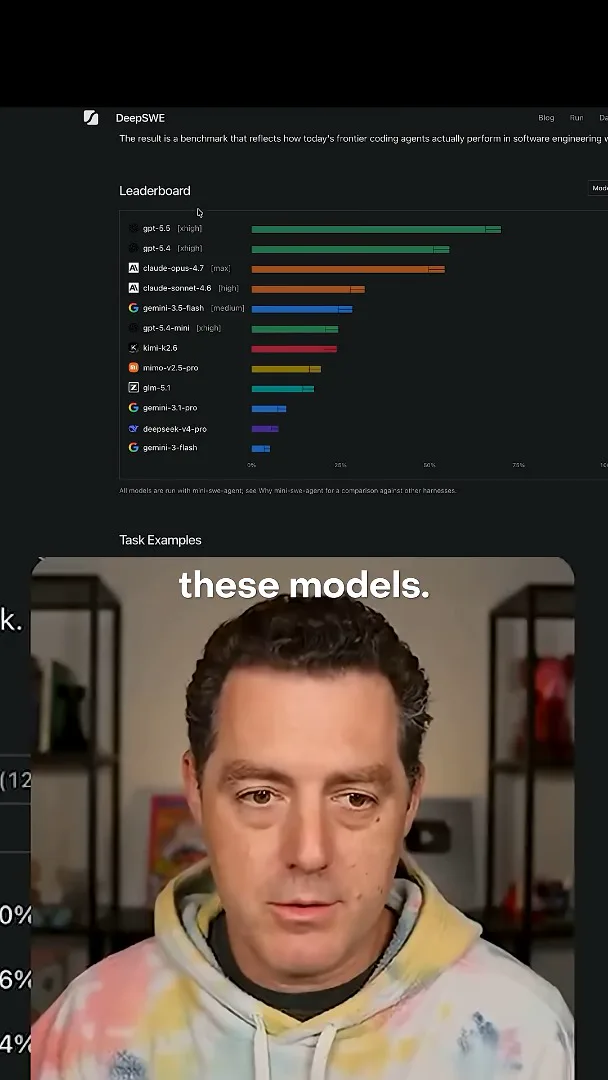
I made a video about DeepSWE, and I think it reflects what people feel when they use these models much better. On that leaderboard, GPT-5.5 at extra high is at about 70%, while Claude Opus 4.7 is at about 54%—a large difference.
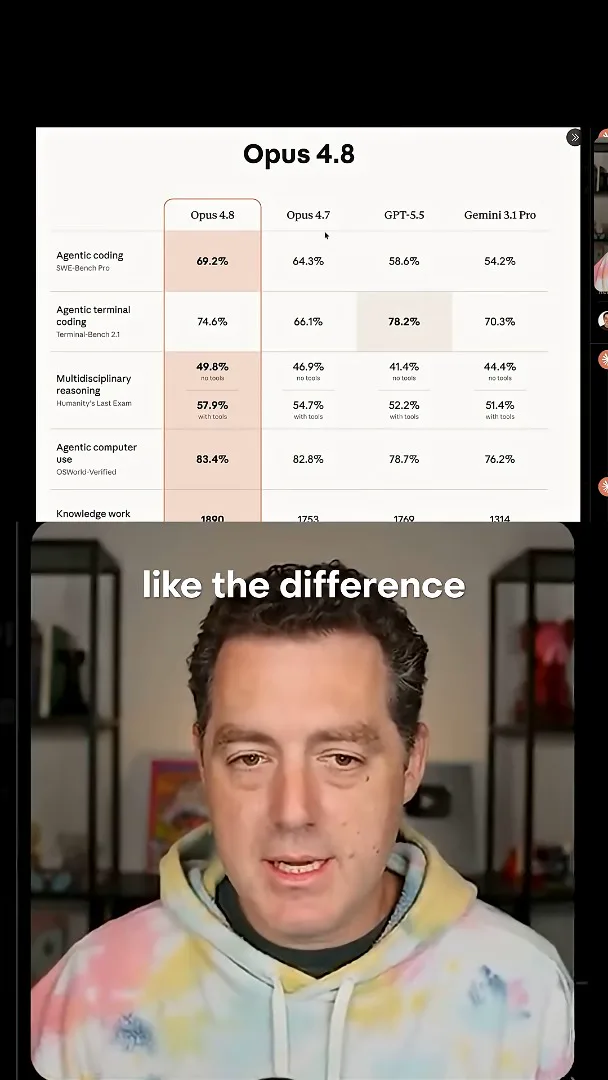
Back on the SWE-bench chart, the difference between GPT-5.5 and Opus 4.7 is substantial in the other direction. Now Opus 4.8 makes another large jump.
Come on, Google. Do something.
같은 채널의 다른 글
 14:45EN
 Matthew Berman· 2026년 10월 29일Matthew Berman Examines Google’s Gemini 4 Carbon AnnouncementMatthew Berman · Forward FutureMatthew Berman reviews Google’s reported benchmark results, staged rollout and pricing for Gemini 4 Carbon, while noting he has not yet used the model.
 21:11ENMatthew Berman· 2026년 10월 28일Matthew Berman tests DeepSeek V4.1 Flash: coding, vision and local appsMatthew Berman · Forward FutureA hands-on tour of visual coding, image reasoning, local applications and provider economics reveals both impressive results and visible flaws.
 34:21ENMatthew Berman· 2026년 10월 27일Matthew Berman Examines Anthropic’s IPO Filing, AI Growth and GovernanceMatthew Berman, Sam Altman · Forward FutureThe presenter reviews the S-1’s financial metrics, compute strategy and voting structure while questioning the tension between rapid AI development and safety.
 0:26ENMatthew Berman· 2026년 10월 25일Sam Altman on Human Values and Problem-Solving in an AI WorldSam Altman · OpenAIIn a short interview excerpt, Altman considers the enjoyment of solving hard problems and the human role in interpreting results.
 0:36ENMatthew Berman· 2026년 10월 25일Kimi K3.1 and a Rubik’s Cube Solver DemonstrationMatthew Berman · Forward FutureMatthew Berman shows a scrambled virtual cube being solved and gives the Kimi K3.1 test a favorable assessment.
 0:21ENMatthew Berman· 2026년 10월 24일An AI-Generated Kimi Benchmark Chart Used Invented ScoresMatthew Berman · Forward FutureMatthew Berman asks for a graph of Kimi K3.1 Pro benchmarks, then discovers that the displayed figures are illustrative placeholders.