30초 요약
This edited supercut collects presentations from Google I/O on May 14, 2024. Sundar Pichai, Demis Hassabis and other Google presenters describe Gemini, demonstrate research prototypes and outline product and developer plans. The showcase mixes previews and planned releases with hypothetical workflows and staged demonstrations. Its timing and claims reflect the 2024 event rather than a current product guide.
- 1Longer context in stagesGemini Advanced gained access to a one-million-token context in 35 languages; Google announced a larger window with restricted initial access.
- 2Astra as a research prototypeGoogle showed a camera-based assistant identifying objects, interpreting code and remembering the location of glasses.
- 3Gemini in GmailA roof-repair example used email summaries, bid comparison and contextual replies to illustrate a proposed mobile workflow.
- 4A virtual teammateThe Chip prototype searched project conversations to answer a question, while Google acknowledged work remained before such agents could be brought into Workspace.
- 5A simulated scam warningAn on-device demonstration showed Gemini Nano warning during a staged fraudulent bank call.
- 6Open-weight developer modelsGoogle introduced PaliGemma and announced plans for a 27-billion-parameter Gemma 2 model.
핵심 정리
- Google presented Gemini 1.5 Flash as a lighter, lower-latency counterpart to Pro and expanded long-context access in stages.
- Project Astra illustrated a multimodal assistant prototype through selected real-time demonstrations.
- Google showed how Gemini might help with email, documents, video and reusable customized instructions.
- Imagen 3, Music AI Sandbox and Veo showcased Google’s generative media work, with capabilities illustrated through selected examples.
- Android demonstrations combined context-aware assistance with an on-device scam-warning scenario.
- Developer announcements included Gemini API features, PaliGemma and a planned larger Gemma 2 model.
챕터별로 다듬은 전문 읽기
Gemini and long-context experiences
Pichai introduces multimodal Gemini and the 2024 expansion of context windows. An early NotebookLM audio demonstration illustrates a possible educational use.
At Google I/O 2024, CEO Sundar Pichai described Gemini as a model built to work across different kinds of information. He said more than 1.5 million developers were using the models and introduced examples spanning Search, Photos, Workspace, Android and the Gemini app. This video is an edited supercut of Google's May 2024 presentation, so its announcements and promised dates are historical.
Pichai said Ask Photos would roll out that summer, with more capabilities to follow. His larger point was that a multimodal model can connect information across formats rather than treat each input as an isolated task.
Gemini 1.5 Pro's one-million-token context was becoming available to Gemini Advanced users in 35 languages. Pichai also announced an expansion toward two million tokens. Google's developer announcement placed the two-million-token version on a waitlist, so the larger window should not be read as general availability at the time.
Josh Woodward demonstrated an early NotebookLM audio feature using material about Newton's laws. A generated dialogue between two voices explained force and motion; Woodward then asked for a basketball example for his son. The screen notes that the audio was pre-generated, and this presentation was a demonstration rather than evidence that the interaction always worked this way.
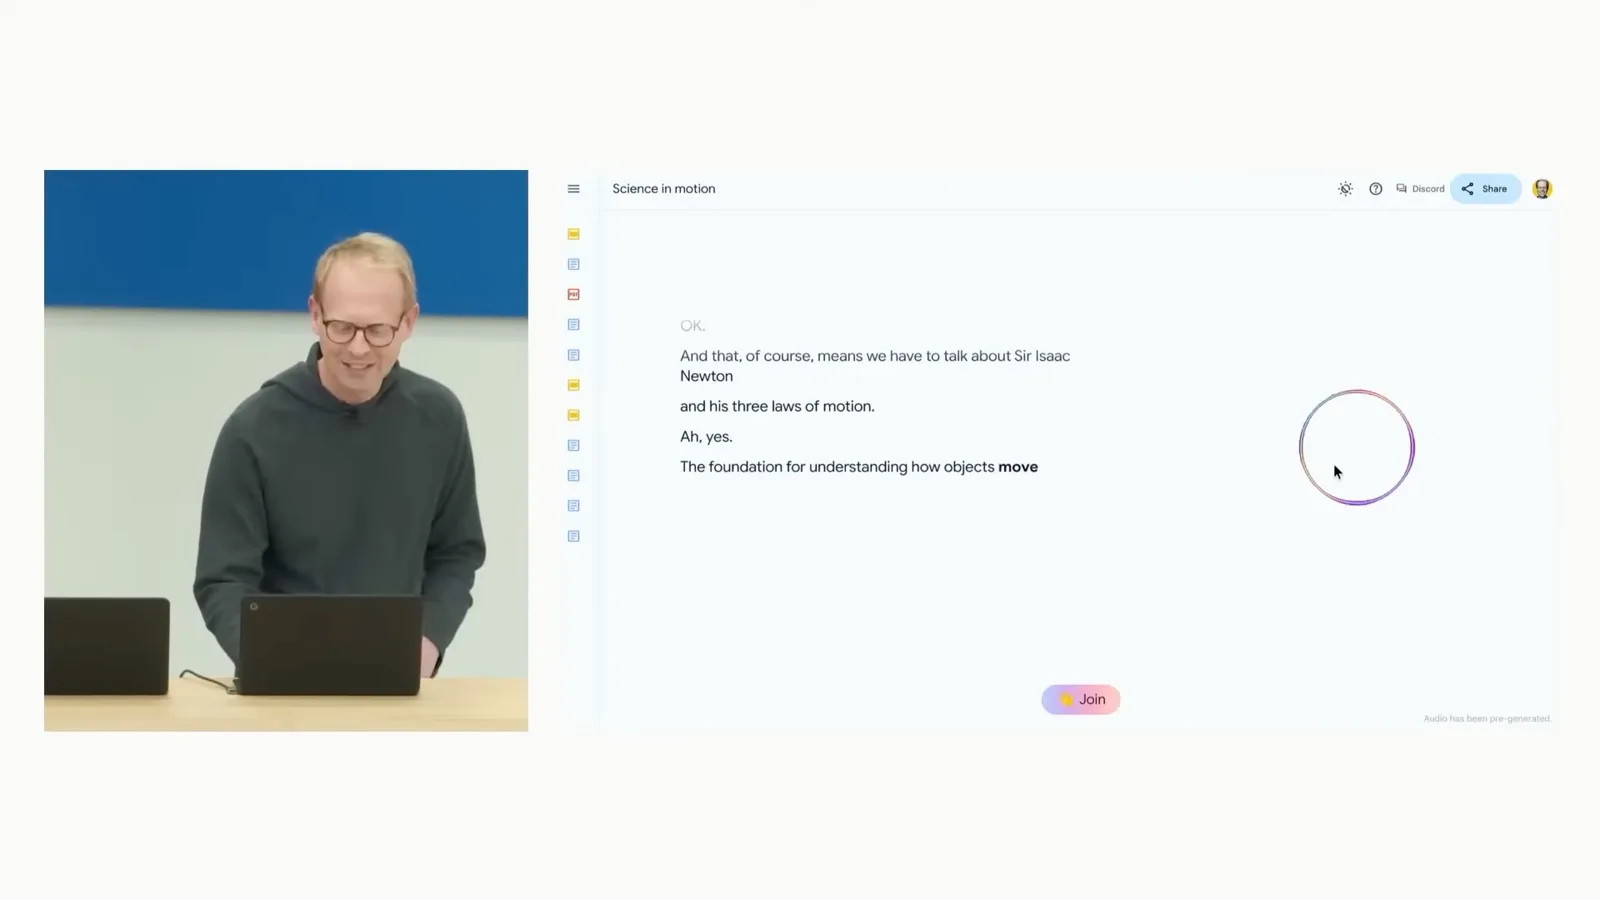
Pichai connected this sort of interaction to a broader vision of mixing input and output formats. He then defined an AI agent as a system with reasoning, planning and memory that can work across software to complete a multistep task on a user's behalf.
Agents, Flash and Project Astra
Google describes a hypothetical shopping agent and introduces the lighter Flash model. Project Astra demonstrates camera-based interaction and memory.
His shopping example was hypothetical: instead of manually returning ill-fitting shoes, a future agent might find a receipt and order number in email, complete a return form and arrange a pickup. The example illustrated the intended workflow, not an announced completed product.
Google DeepMind CEO Demis Hassabis introduced Gemini 1.5 Flash as a lighter model than Pro, intended for lower-latency, lower-cost applications while retaining multimodal and long-context capabilities. Its design trade-off was serving efficiently at scale, rather than presenting one model as ideal for every task.
Hassabis then introduced Project Astra, Google's prototype for a more universal assistant. The goal was an agent able to understand and remember what it sees, respond to a changing environment and converse naturally. Google presented a video in two parts, each said to be captured in a single real-time take.
In the first part, the demonstrator points a camera around a room. The prototype identifies a speaker and its tweeter, makes an alliteration about crayons, describes code on a screen and suggests the King's Cross area of London. Asked where it had seen the user's glasses, it recalls a desk near a red apple.
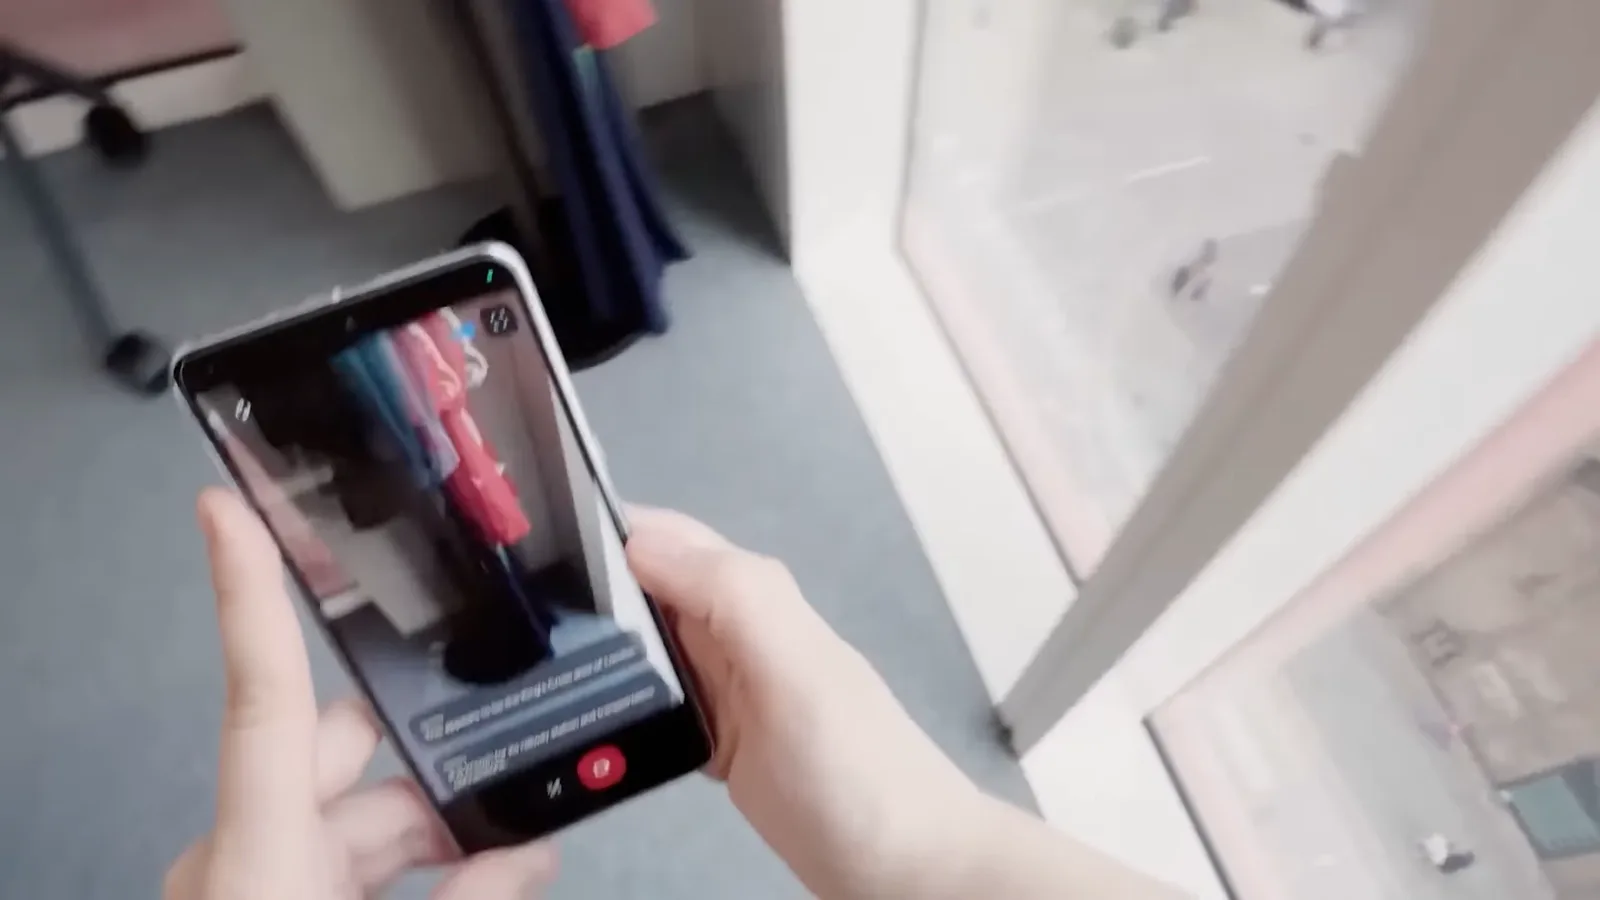
The demonstration continues with a system diagram: Astra suggests adding a cache between a server and database. It also responds to drawings and proposes a band name. These selected examples show the direction of the research prototype; they do not establish its reliability across arbitrary settings.
Image, music, video and infrastructure
Presenters showcase Imagen 3, Music AI Sandbox and Veo. Google also announces its Trillium TPU generation.
A Google presenter introduced Imagen 3, describing improvements in photorealism, detail, prompt following and visual artifacts. He said independent evaluators preferred it in some side-by-side comparisons and invited viewers to sign up for ImageFX; developer and enterprise access was planned. The preference claim was Google's account of those comparisons, not a universal ranking.
Google also described Music AI Sandbox, built with YouTube and artists to explore professional music tools, including generating instrumental sections and transferring styles. The presentation framed these as creative tools under development, with artists involved in shaping their use.
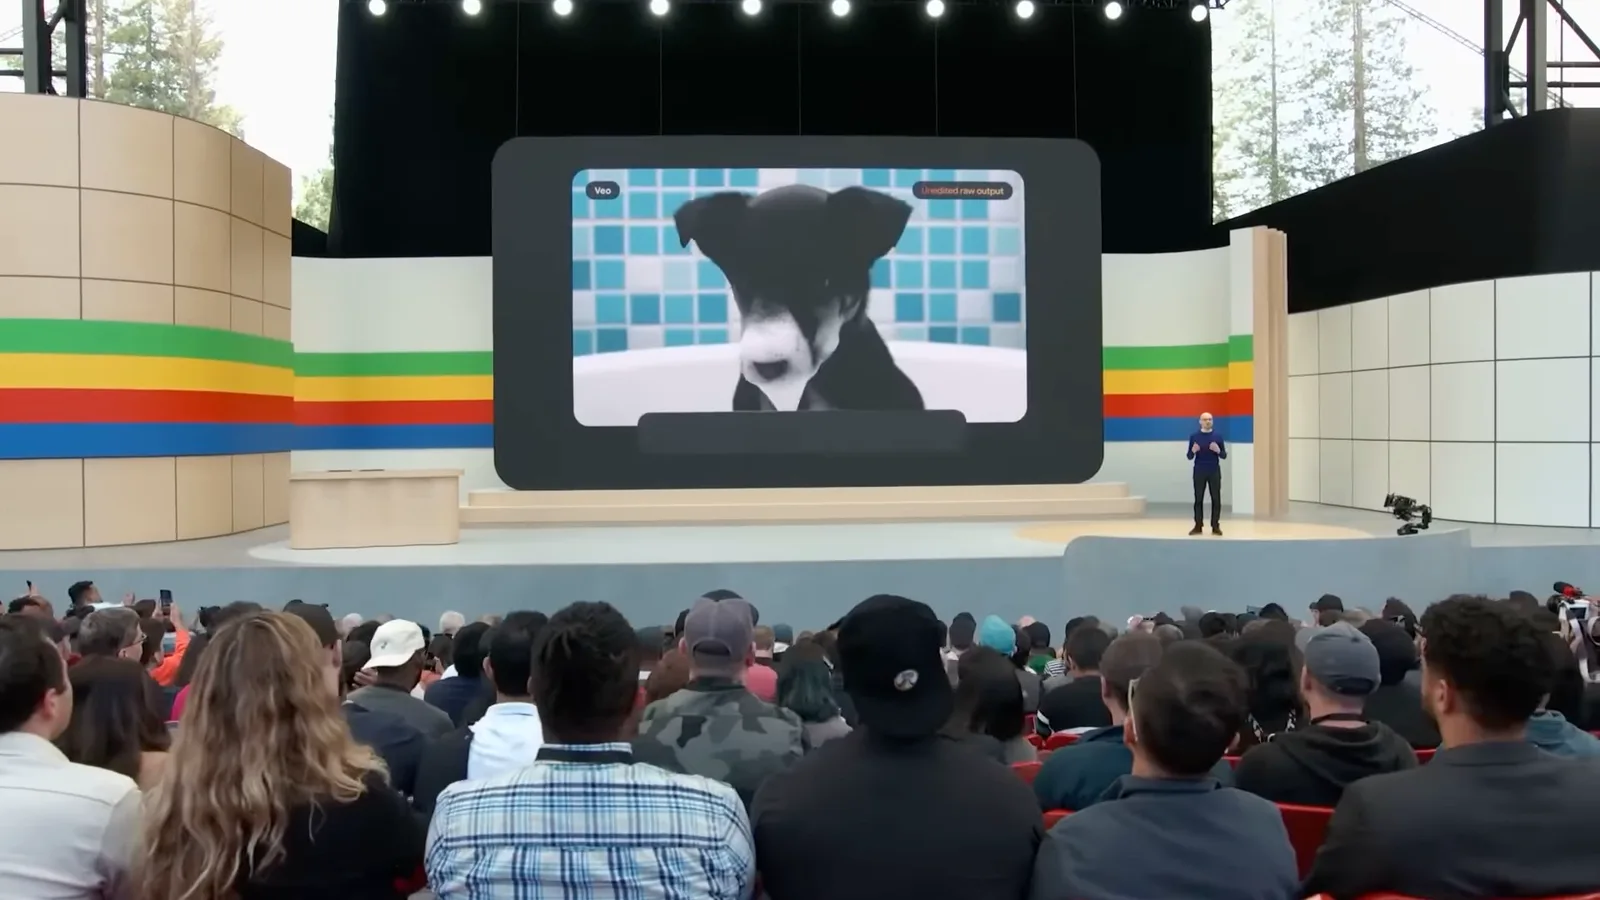
The presenter announced Veo, a generative video model that Google said could create 1080p video from text, image or video prompts, follow cinematic instructions such as aerial shots or time-lapses, and support further edits through prompts. The clips shown were selected demonstrations, not a guarantee of results on every request.
Google announced its sixth-generation TPU, Trillium. The company claimed a 4.7-fold improvement in peak compute performance per chip over TPU v5e and said it expected cloud availability in late 2024; that figure refers to a specific hardware comparison, not every workload's speedup.
Gemini for Workspace
A Gmail example summarizes a thread, compares bids and drafts a response. The Chip prototype shows a possible virtual teammate for group work.
The Workspace section said the Gemini-powered side panel was planned for general availability the following month. Google also highlighted automatic language detection and real-time meeting captions expanding to 68 languages, before turning to proposed Gemini 1.5 Pro features in Gmail mobile.
In a roof-repair example, the presenter opens a long email thread and uses a summary card to find a contractor's quote. Instead of searching separate messages by hand, she asks Gemini to compare bids by price and availability; the displayed response brings together details from different threads.
The presenter selects a contractor and shows a contextual Smart Reply. Gemini offers responses shaped by the thread and lets her preview a full draft before sending. Google said these Gmail capabilities would begin rolling out to Labs users that month, a 2024 rollout plan rather than a statement of present availability.
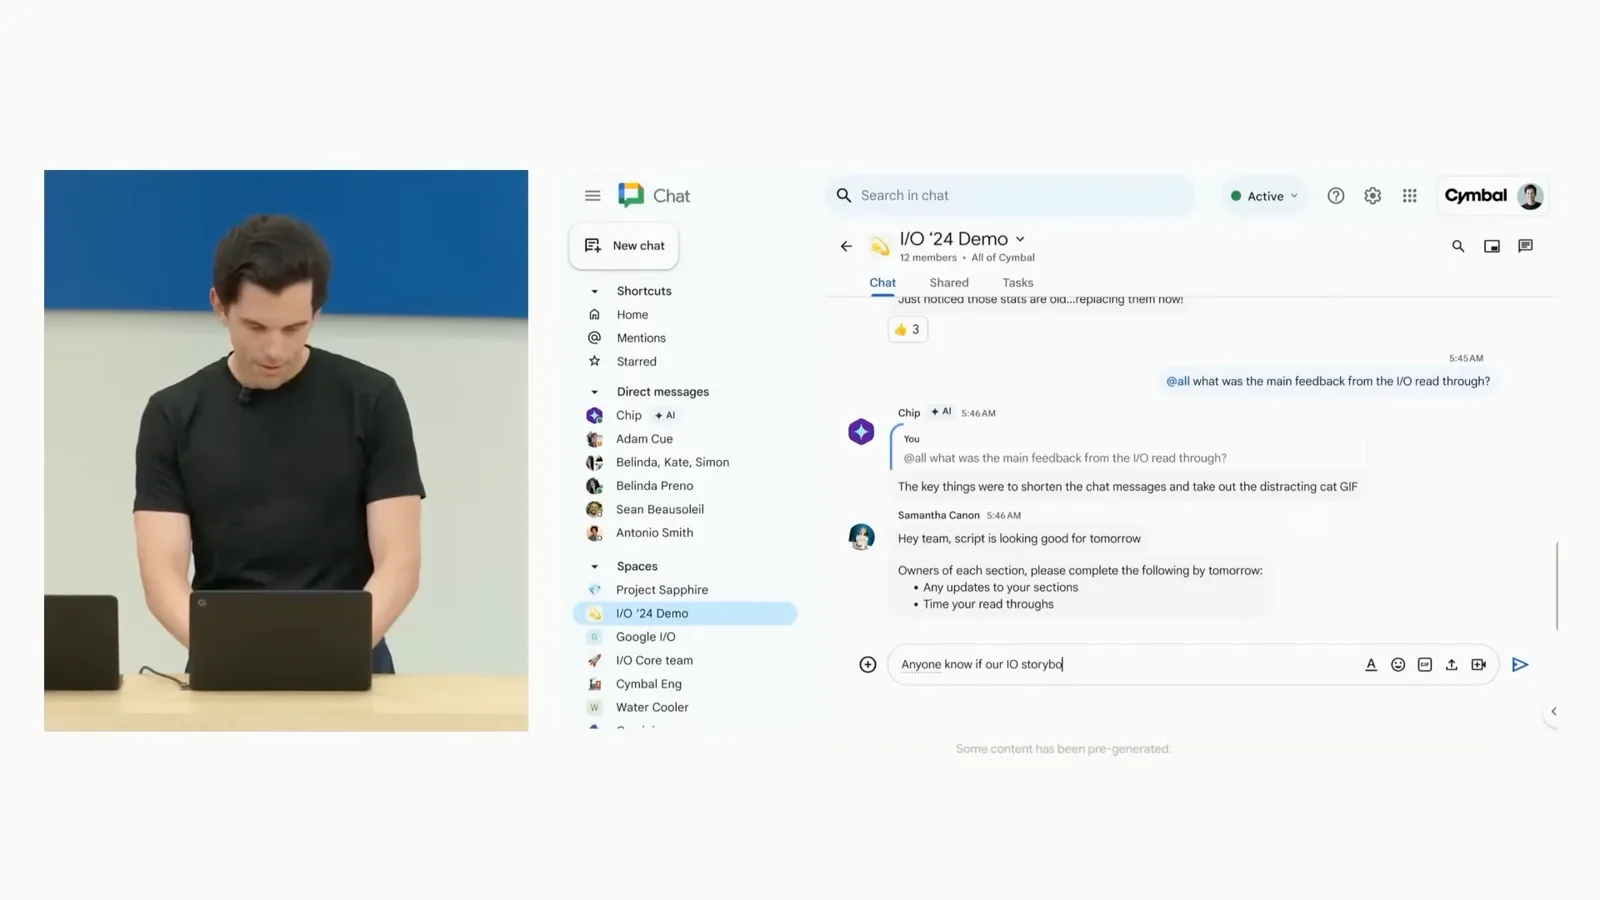
Looking toward 2025 and beyond, Google showed a prototype virtual teammate named Chip. In Google Chat, Tony asks whether I/O storyboards have been approved; Chip searches the conversations it was assigned to track and responds. The presentation says the teammate could build context as it joins more chats, files and email threads, while acknowledging substantial work remained.
Gemini app and Android
Google outlines conversational Live and customizable Gems. Android demonstrations use a video, a PDF and a simulated scam call.
The Gemini app presentation framed a personal assistant around text, voice and camera input. Google announced Gemini Live for later that summer, with more natural voice conversations and the ability to interrupt; it also intended to bring Astra's speed and video understanding to the app.
Google proposed opening a camera during a live conversation so Gemini could respond to the user's surroundings. It also introduced Gems: reusable customized instructions for a personal expert, such as a writing coach that specializes in short stories. Gems were described as coming in the following months, with trusted testers already trying them.
The Android section described a multiyear effort to put AI into the operating system: easier AI search, Gemini as an assistant and on-device models for faster and more private experiences. The speaker's privacy language describes Google's goal and architecture, not a blanket guarantee about all data handling.
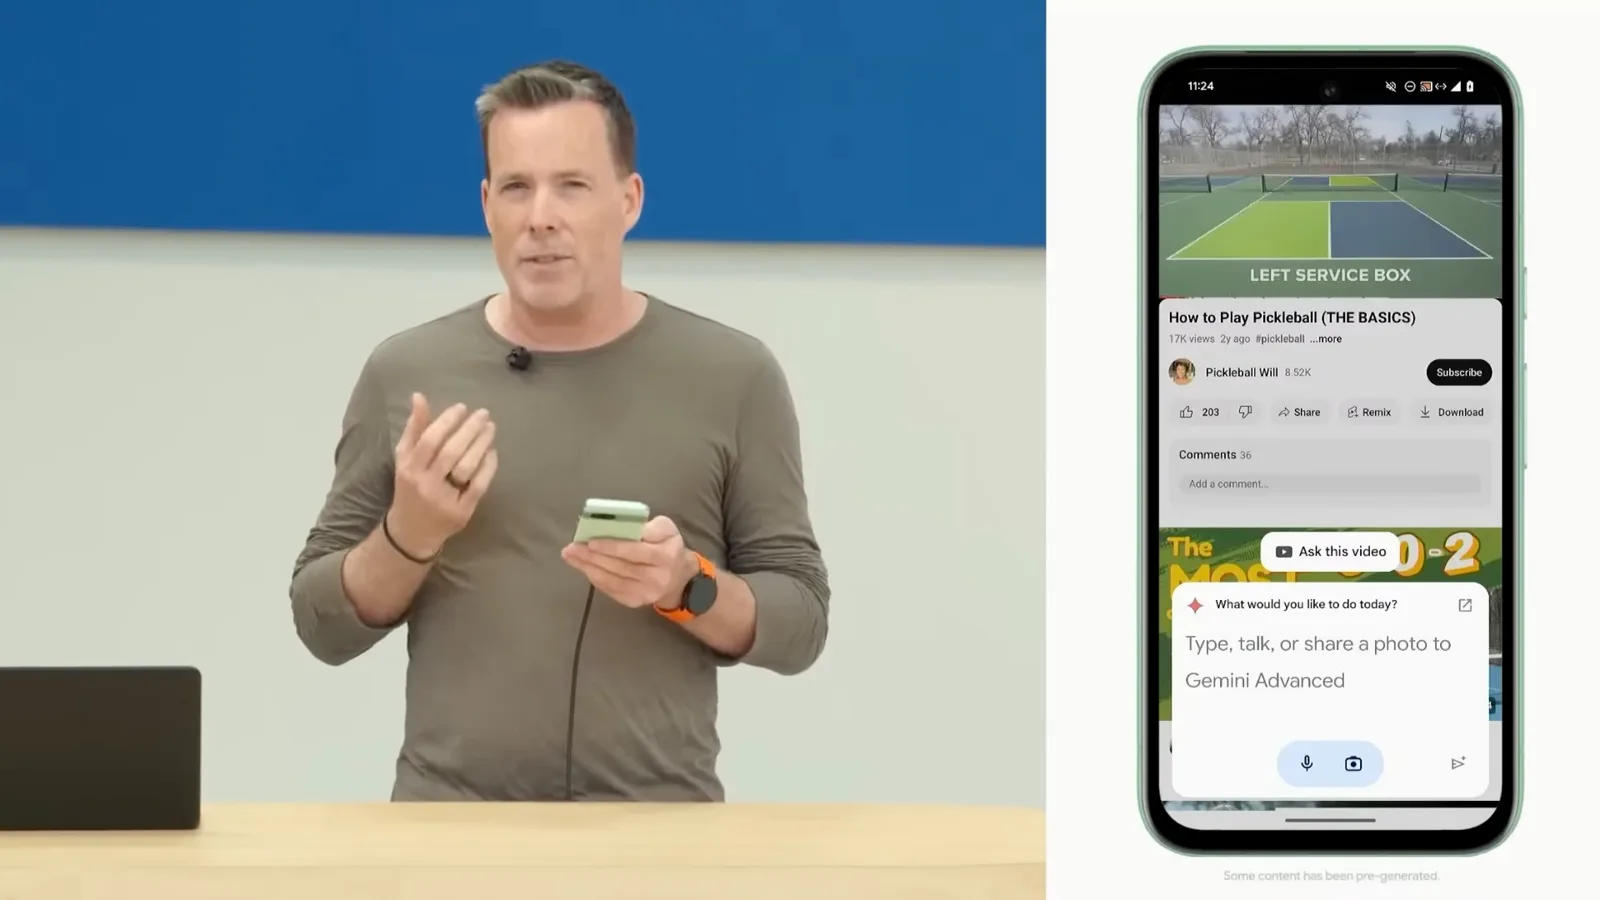
Dave demonstrated Gemini at the system level while receiving a pickleball video in a message. Because the user was viewing YouTube, Gemini offered an 'Ask this video' action. His question about the two-bounce rule produced a short explanation, with YouTube captions among the signals used.
Next he opened an 84-page pickleball rulebook as a PDF. Gemini offered an 'Ask this PDF' action, answered a question about spin serves and pointed to a source in the document. The presentation used a specific document and example; its answer should be checked against the relevant rules and edition rather than generalized to every form of spin.
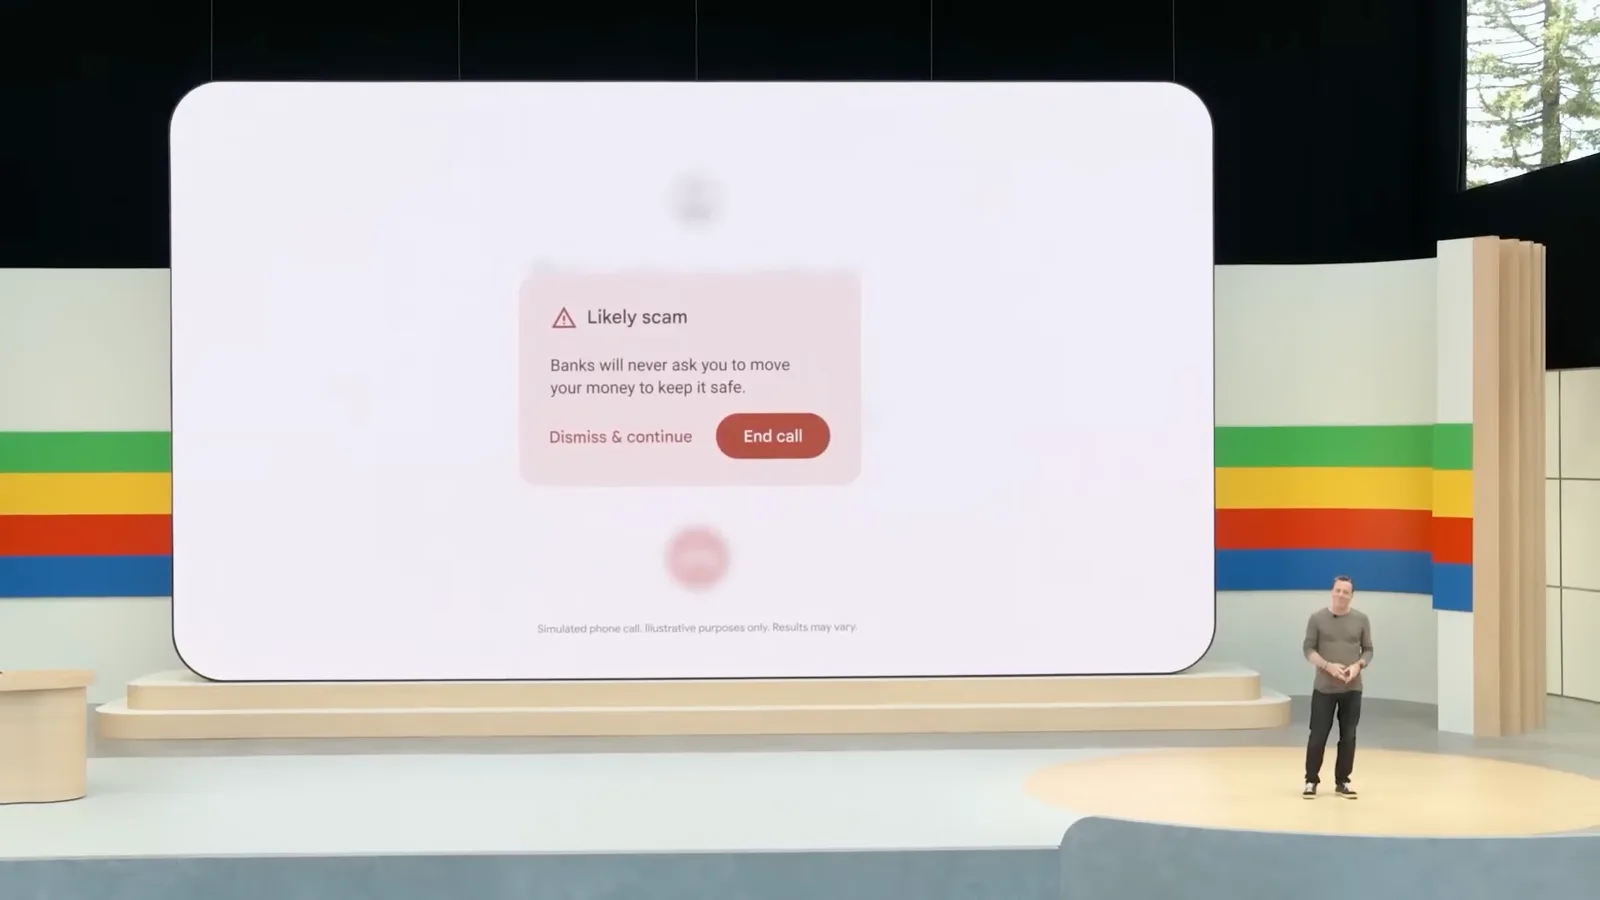
To illustrate on-device scam detection, Google staged a call from someone impersonating a bank employee and asking Dave to transfer money. Gemini Nano displayed a warning during the simulated call. It was a scenario demonstrating a proposed safeguard, not a measured fraud-detection accuracy or a promise to catch all scams.
Developer models and tools
The presentation covers the Gemini API and open-weight Gemma models. Google announces PaliGemma and a planned Gemma 2 release.
In the developer section, Google said Gemini 1.5 Pro and the new Flash were available in preview across more than 200 countries and territories. The presenter also discussed video-frame extraction, parallel function calling and context caching; caching was planned for the following month to make repeated use of long inputs more practical and affordable.
The Gemma family was presented as open models derived from related Google research, with 2-billion- and 7-billion-parameter sizes and variants including RecurrentGemma and CodeGemma. Google introduced PaliGemma, an open-weight vision-language model for tasks including image captioning, visual questions and image labeling; its use is subject to its license terms.
Google announced a forthcoming Gemma 2 model with 27 billion parameters, planned for June 2024. The presenter said it was optimized for NVIDIA GPUs and could run on a single TPU host in Vertex AI, and claimed it could outperform models more than twice its size. No general benchmark or universal superiority follows from that stage claim.
The presentation closed by inviting developers to build with the announced tools. Across the supercut, Google moved between available previews, scheduled rollouts, staged examples and research prototypes; each should be understood in its original 2024 context.
같은 채널의 다른 글
 34:21EN
 Matthew Berman· 2026년 10월 27일Matthew Berman Examines Anthropic’s IPO Filing, AI Growth and GovernanceMatthew Berman, Sam Altman · Forward FutureThe presenter reviews the S-1’s financial metrics, compute strategy and voting structure while questioning the tension between rapid AI development and safety.
 0:26ENMatthew Berman· 2026년 10월 25일Sam Altman on Human Values and Problem-Solving in an AI WorldSam Altman · OpenAIIn a short interview excerpt, Altman considers the enjoyment of solving hard problems and the human role in interpreting results.
 0:36ENMatthew Berman· 2026년 10월 25일Kimi K3.1 and a Rubik’s Cube Solver DemonstrationMatthew Berman · Forward FutureMatthew Berman shows a scrambled virtual cube being solved and gives the Kimi K3.1 test a favorable assessment.
 0:21ENMatthew Berman· 2026년 10월 24일An AI-Generated Kimi Benchmark Chart Used Invented ScoresMatthew Berman · Forward FutureMatthew Berman asks for a graph of Kimi K3.1 Pro benchmarks, then discovers that the displayed figures are illustrative placeholders.
 25:50ENMatthew Berman· 2026년 10월 24일Kimi K3.1 Pro Tested: Strong 3D Demos, Uneven Results and Competitive PricingMatthew Berman · Forward FutureMatthew Berman tests the open-weight model on coding, 3D rendering and visual explanations, then compares benchmark results and prices.
 32:20ENMatthew Berman· 2026년 10월 23일Who Is Local AI For? The Costs, Trade-offs and a Hybrid FutureMatthew Berman · Forward FutureMatthew Berman weighs data control and independence against hardware cost, setup complexity and inference speed.