30초 요약
In this March 2024 video, Matthew Berman discusses xAI’s release of Grok-1 base-model weights, architecture and example code under Apache 2.0. He interprets the release partly through Elon Musk’s dispute with OpenAI and offers his impressions of Grok. The released checkpoint was not fine-tuned for dialogue, and its weights do not by themselves provide the live X access associated with a hosted product.
- 1The dispute with OpenAIBerman connects the release to Musk’s public criticism and lawsuit, while attributing his proposed motive to interpretation.
- 2The model releasexAI published a large mixture-of-experts base checkpoint and example code under Apache 2.0.
- 3Base model versus productBerman compares his hosted Grok experience with GPT-4, but the released checkpoint is not the same as the hosted assistant.
- 4Training and safety claimsxAI describes text pretraining without task-specific fine-tuning; this does not establish the complete training corpus or absence of safety behavior.
핵심 정리
- xAI released Grok-1 base weights and architecture under Apache 2.0 on March 17, 2024.
- The 314-billion-parameter mixture-of-experts model uses two of eight experts for each token.
- The released checkpoint completed pretraining in October 2023 and was not fine-tuned for dialogue.
- The hosted Grok product and the downloadable base checkpoint are different systems; real-time X access requires a separate integration.
- Berman’s claims about Musk’s motives, model quality and censorship are interpretations or impressions rather than verified conclusions.
챕터별로 다듬은 전문 읽기
Musk, OpenAI and the release
Berman recounts Musk’s criticism of OpenAI and interprets the timing of the release. He comments on the public dispute and reaction.
Matthew Berman reports that xAI released Grok-1 on March 17, 2024, shortly after Elon Musk publicly criticized and sued OpenAI. Berman interprets Musk’s motive as partly competitive pressure and personal animosity; the release announcement does not establish those motives, and the lawsuit’s allegations are not findings of fact.
Berman recaps Musk’s posts criticizing OpenAI’s name and discusses reactions on X. He favors openly available AI models, then comments on public speculation surrounding OpenAI executives. His impressions of their motives and roles are personal commentary, not verified information about internal company decisions.
Grok-1 weights and architecture
Berman examines the download and technical details. xAI released an unfine-tuned base checkpoint with example code under Apache 2.0.
The release contains a 314-billion-parameter mixture-of-experts base model. The xAI repository specifies eight experts, with two selected per token, and provides JAX example code to load and sample from the checkpoint. The download shown in the video is hundreds of gigabytes; substantial memory is required to run the example.
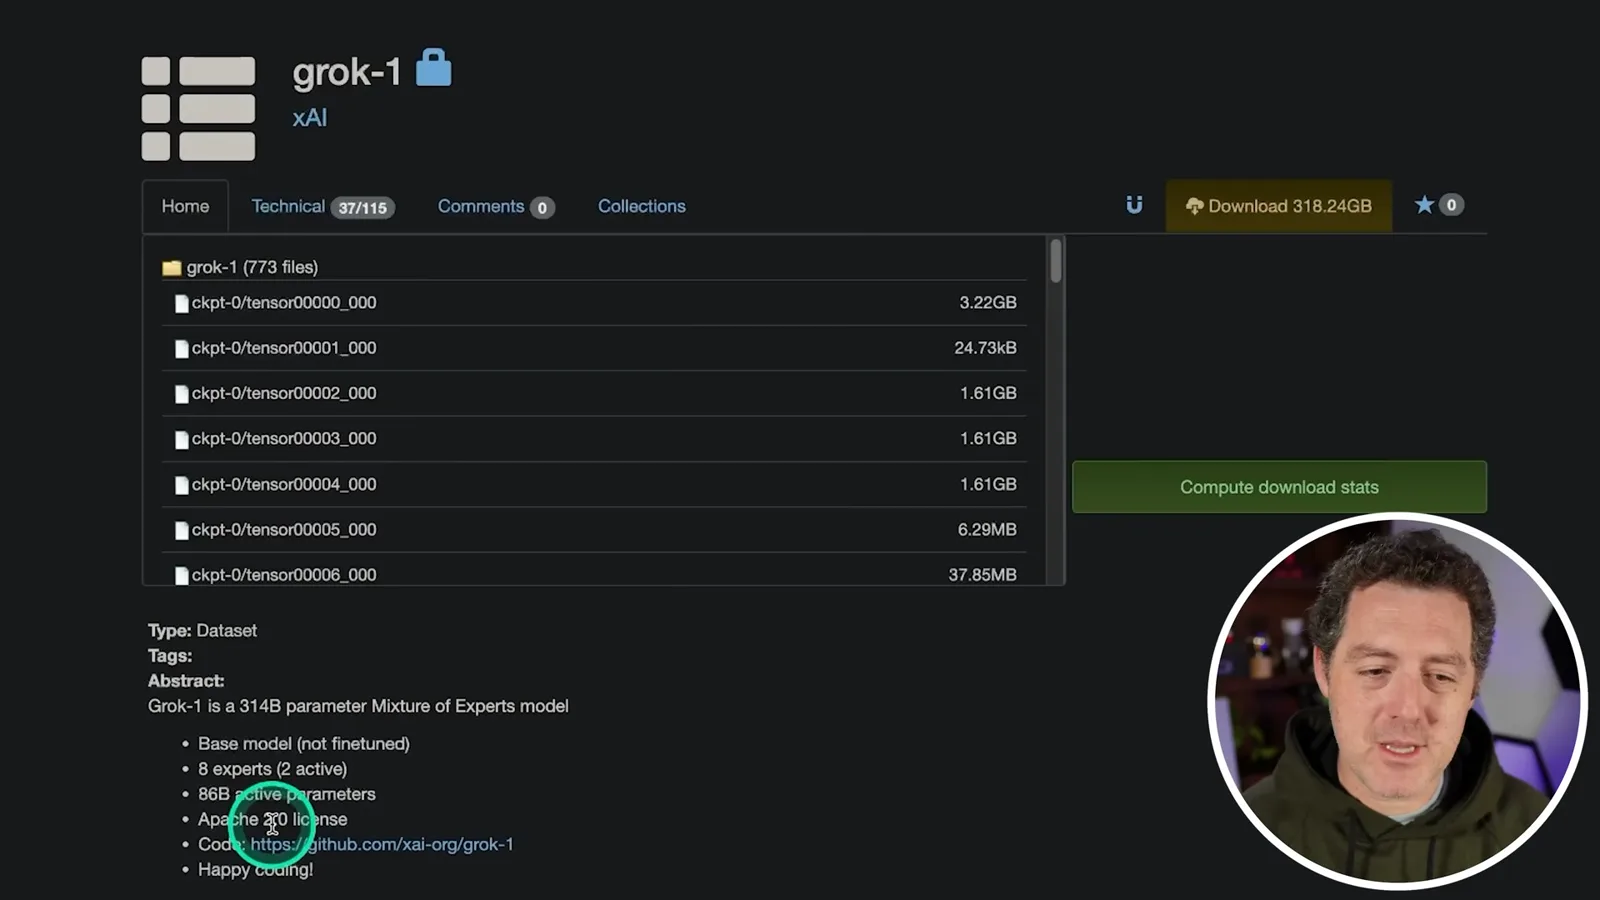
xAI released the associated code and weights under Apache 2.0. The announcement says the checkpoint comes from pretraining completed in October 2023 and was not fine-tuned for a particular application such as dialogue. The release of weights and example code should not be assumed to include all training data or the complete hosted product.
Hosted access and model limitations
Berman discusses Grok’s hosted experience and X data. The release itself does not establish live access or the full training corpus.
Berman says his previous experience with the hosted Grok assistant was merely adequate compared with GPT-4, while he values its access to information from X. That is his informal comparison, not a controlled benchmark. Real-time access is a product integration and does not come automatically with a downloadable base-model checkpoint.
Berman suggests that access to X gives xAI a distinctive data source and discusses changes to Twitter’s API. The release announcement describes training on a large amount of text but does not disclose a complete dataset, so the video does not establish exactly which X posts were used or what proportion they represented.
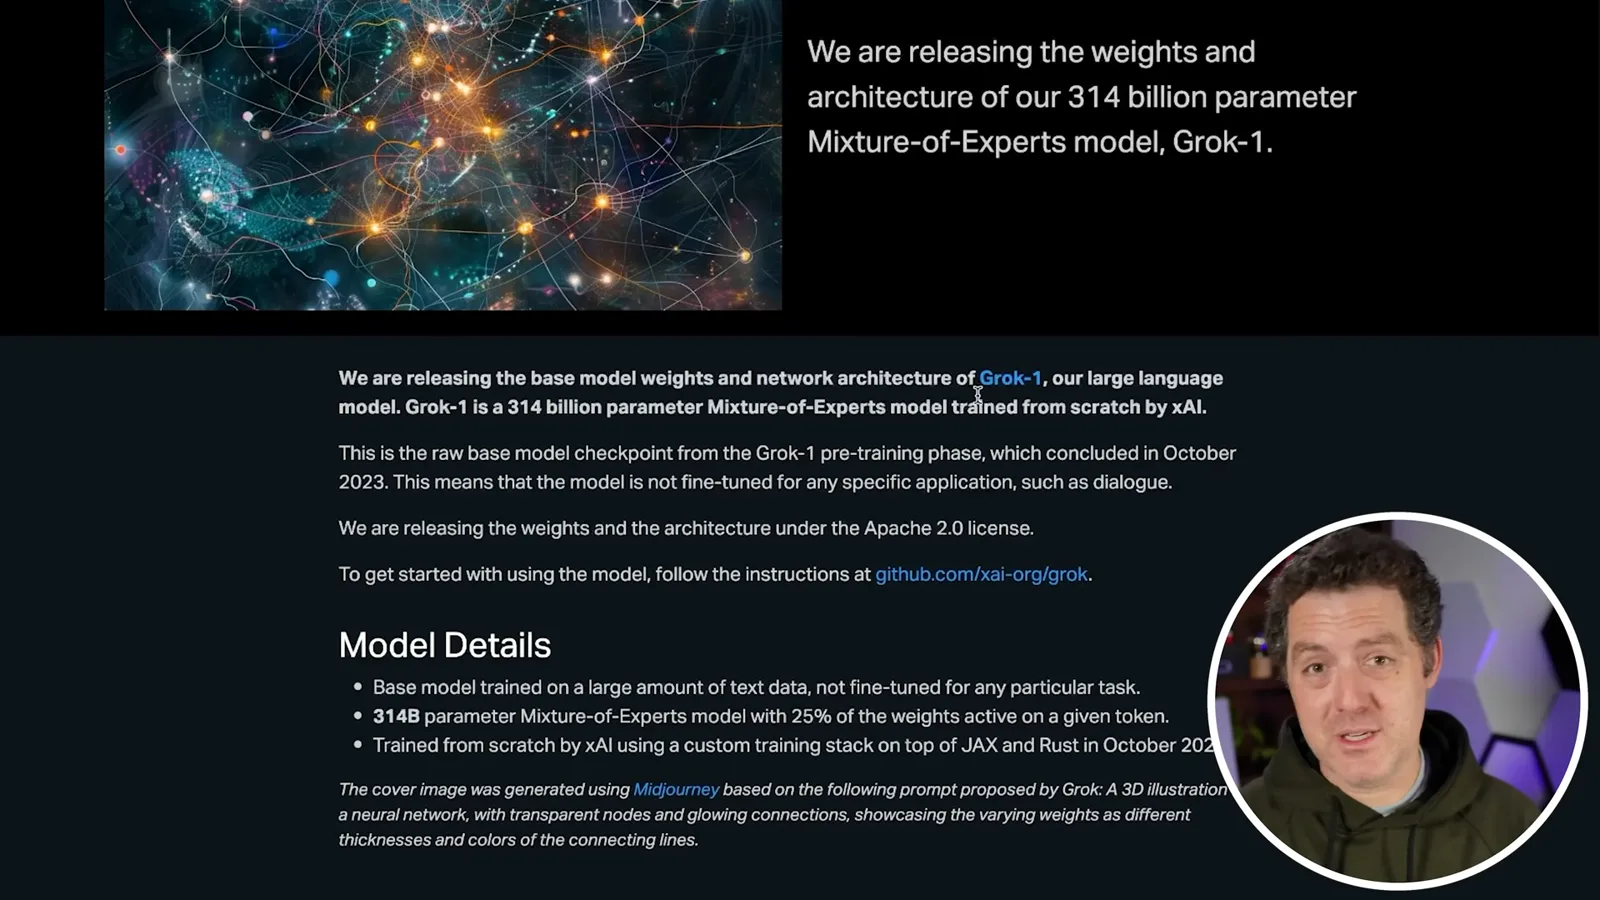
He emphasizes that the released model is a base checkpoint and believes it has little censorship. Lack of dialogue fine-tuning does not prove an absence of safety behavior or establish how the model will respond to every request; outputs also depend on any later fine-tuning and the system around the model.
Berman closes by inviting viewers to request a more complete test. The release is significant for developers who can work with the large checkpoint, but his remarks do not provide a systematic evaluation of its capabilities or safety.
같은 채널의 다른 글
 34:21EN
 Matthew Berman· 2026년 10월 27일Matthew Berman Examines Anthropic’s IPO Filing, AI Growth and GovernanceMatthew Berman, Sam Altman · Forward FutureThe presenter reviews the S-1’s financial metrics, compute strategy and voting structure while questioning the tension between rapid AI development and safety.
 0:26ENMatthew Berman· 2026년 10월 25일Sam Altman on Human Values and Problem-Solving in an AI WorldSam Altman · OpenAIIn a short interview excerpt, Altman considers the enjoyment of solving hard problems and the human role in interpreting results.
 0:36ENMatthew Berman· 2026년 10월 25일Kimi K3.1 and a Rubik’s Cube Solver DemonstrationMatthew Berman · Forward FutureMatthew Berman shows a scrambled virtual cube being solved and gives the Kimi K3.1 test a favorable assessment.
 0:21ENMatthew Berman· 2026년 10월 24일An AI-Generated Kimi Benchmark Chart Used Invented ScoresMatthew Berman · Forward FutureMatthew Berman asks for a graph of Kimi K3.1 Pro benchmarks, then discovers that the displayed figures are illustrative placeholders.
 25:50ENMatthew Berman· 2026년 10월 24일Kimi K3.1 Pro Tested: Strong 3D Demos, Uneven Results and Competitive PricingMatthew Berman · Forward FutureMatthew Berman tests the open-weight model on coding, 3D rendering and visual explanations, then compares benchmark results and prices.
 32:20ENMatthew Berman· 2026년 10월 23일Who Is Local AI For? The Costs, Trade-offs and a Hybrid FutureMatthew Berman · Forward FutureMatthew Berman weighs data control and independence against hardware cost, setup complexity and inference speed.