30초 요약
In this September 4, 2025 roundup, Matthew Berman covers xAI’s allegations against a former engineer, Microsoft’s MAI models, Anthropic’s funding and privacy changes, robotics, AI evaluations, medical research and OpenAI product news. The lawsuit allegations were contested and a separate later case against OpenAI was dismissed; the SeeMe results come from a small study, not a general clinical guarantee. The video is sponsored by Zapier.
- 1xAI’s allegationsThe original 2025 complaint targeted a former engineer, and the claims were allegations. A later separate suit against OpenAI was dismissed.
- 2Microsoft’s in-house modelsMAI-Voice-1 and MAI-1-preview were announced with company-reported performance and historical leaderboard claims.
- 3Funding and consumer dataAnthropic reported a $13 billion round and a $5 billion annualized run rate; its five-year retention was conditional on model-improvement settings.
- 4rStar2-Agent benchmarkThe reported 80.6% AIME24 average pass@1 concerns a specific math evaluation with tool use.
- 5SeeMe studyResearchers studied subtle responses in a small acute brain-injury cohort, finding earlier eye-opening detection than clinical examination.
- 6Crisis and teen featuresOpenAI announced planned support and parental-control measures; these features and their availability may change.
핵심 정리
- xAI’s 2025 suit alleged misconduct by former engineer Xuechen Li; the original suit did not name OpenAI as a defendant, and a separate later case against OpenAI was dismissed.
- Microsoft announced MAI-Voice-1 and MAI-1-preview; performance claims and leaderboard positions are historical snapshots.
- Anthropic’s $5 billion revenue run rate is an annualized snapshot, not revenue earned during a full year.
- Anthropic’s 2025 five-year retention applied to new or resumed consumer chats when model-improvement sharing was enabled, rather than all users.
- The SeeMe study involved 37 patients with acute brain injuries and reported earlier detection in that sample; it does not establish universal clinical safety or prove awareness in every case.
- The rStar2-Agent comparison concerns specified competition-math tests and tool settings, not general superiority over larger models.
- The video contains a Zapier sponsorship.
챕터별로 다듬은 전문 읽기
xAI lawsuit and Microsoft models
Berman reports trade-secret allegations and reviews MAI-Voice-1 and MAI-1-preview. He then presents a Zapier sponsorship.
I begin with Reuters reporting that xAI sued former engineer Xuechen Li over alleged trade-secret theft connected to his proposed move to OpenAI. xAI’s claims, including Musk’s assertion about an uploaded codebase, are allegations rather than established findings. The August 2025 action named Li, not OpenAI, as a defendant ([Reuters](https://www.investing.com/news/stock-market-news/musks-xai-sues-engineer-for-allegedly-taking-secrets-to-openai-4217045)).
The complaint alleged that Li worked on Grok, sold xAI stock and copied confidential information. In a separate later lawsuit against OpenAI, a federal judge dismissed xAI’s amended claims in June 2026 without leave to amend, finding the allegations insufficient against OpenAI. That ruling concerned the separate action and does not itself determine the outcome of the original case against Li ([court order](https://www.courthousenews.com/wp-content/uploads/2026/06/xai-v-openai-dismissal-order.pdf)).
Microsoft announced MAI-Voice-1 and MAI-1-preview as its own models. I interpret the move partly through its relationship with OpenAI, though that is my assessment of strategy. Microsoft had worked on other AI models before; its announcement describes MAI-1-preview as its first foundation model trained end to end by Microsoft AI, not Microsoft’s first AI work ([Microsoft](https://microsoft.ai/news/two-new-in-house-models/)).
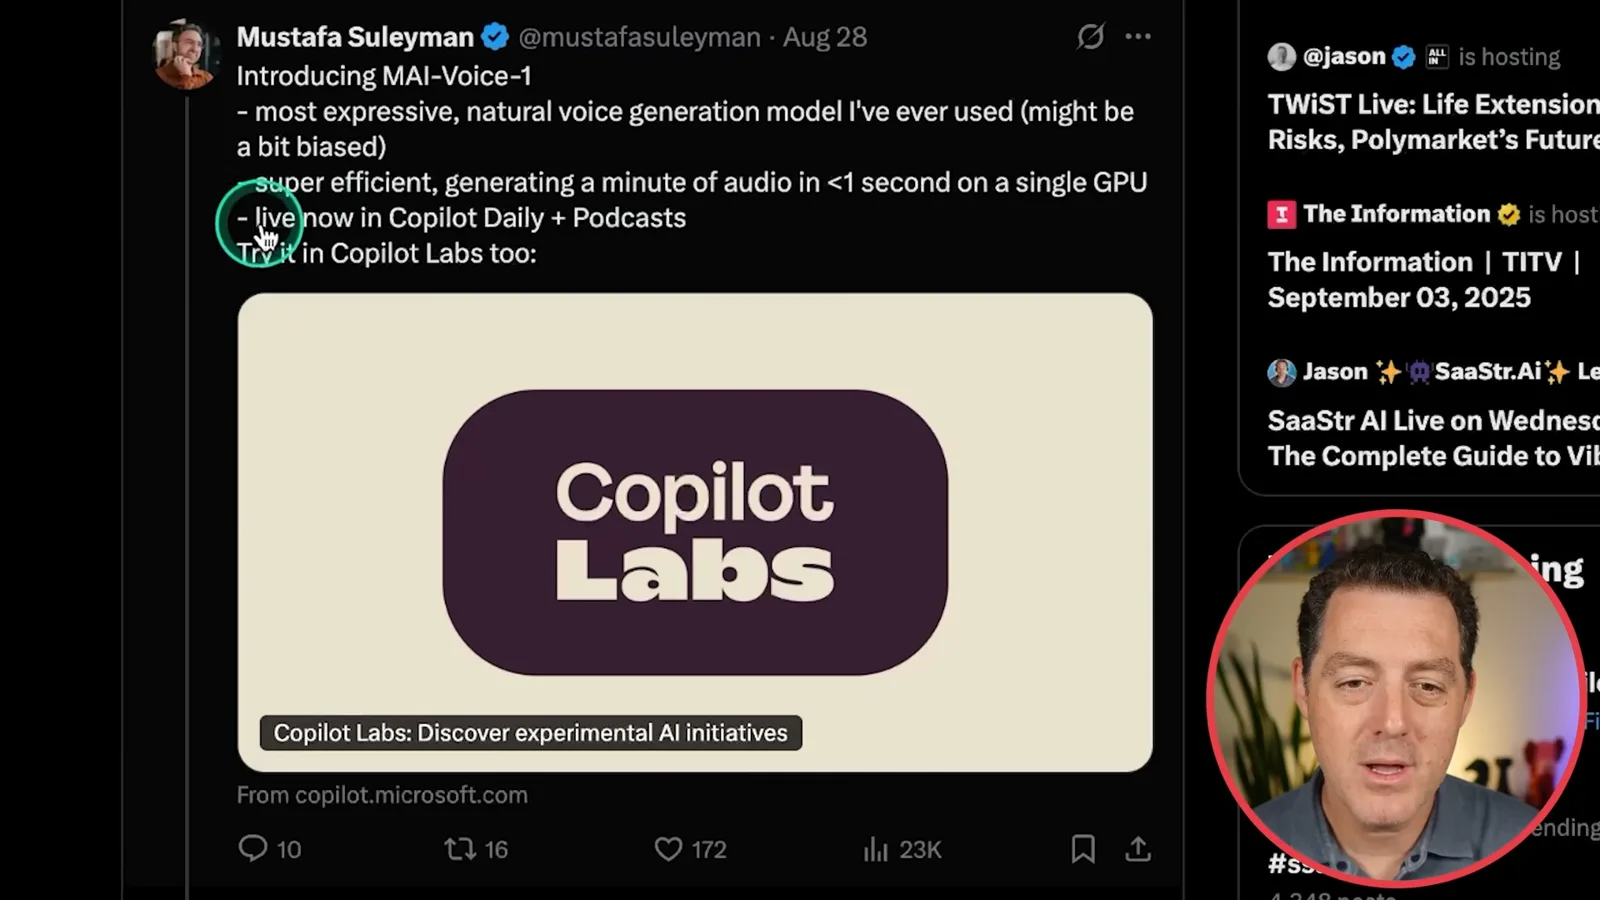
Microsoft says MAI-Voice-1 can generate a minute of audio in under a second on a single GPU and was being used in Copilot Daily and Podcasts. I listen to examples and find them convincing, while saying I need more testing. The speed and quality descriptions are company claims and personal impressions, not a controlled comparison.
MAI-1-preview was tested on LMArena and appeared around 13th in the ranking shown in the video. Microsoft describes it as a mixture-of-experts model trained using about 15,000 H100 GPUs. A leaderboard position is a snapshot under specific evaluation conditions and is not a permanent ranking or evidence of performance on every task.
Zapier sponsors the video. I describe Zapier Agents, integrations and support for connecting tools to agents, and suggest trying the service. The number of supported apps, pricing and integration capabilities are promotional claims and can change.
Anthropic funding, privacy and robotics
The video discusses Anthropic’s historical funding and consumer data changes, a Figure robot demo and the Google antitrust remedy.
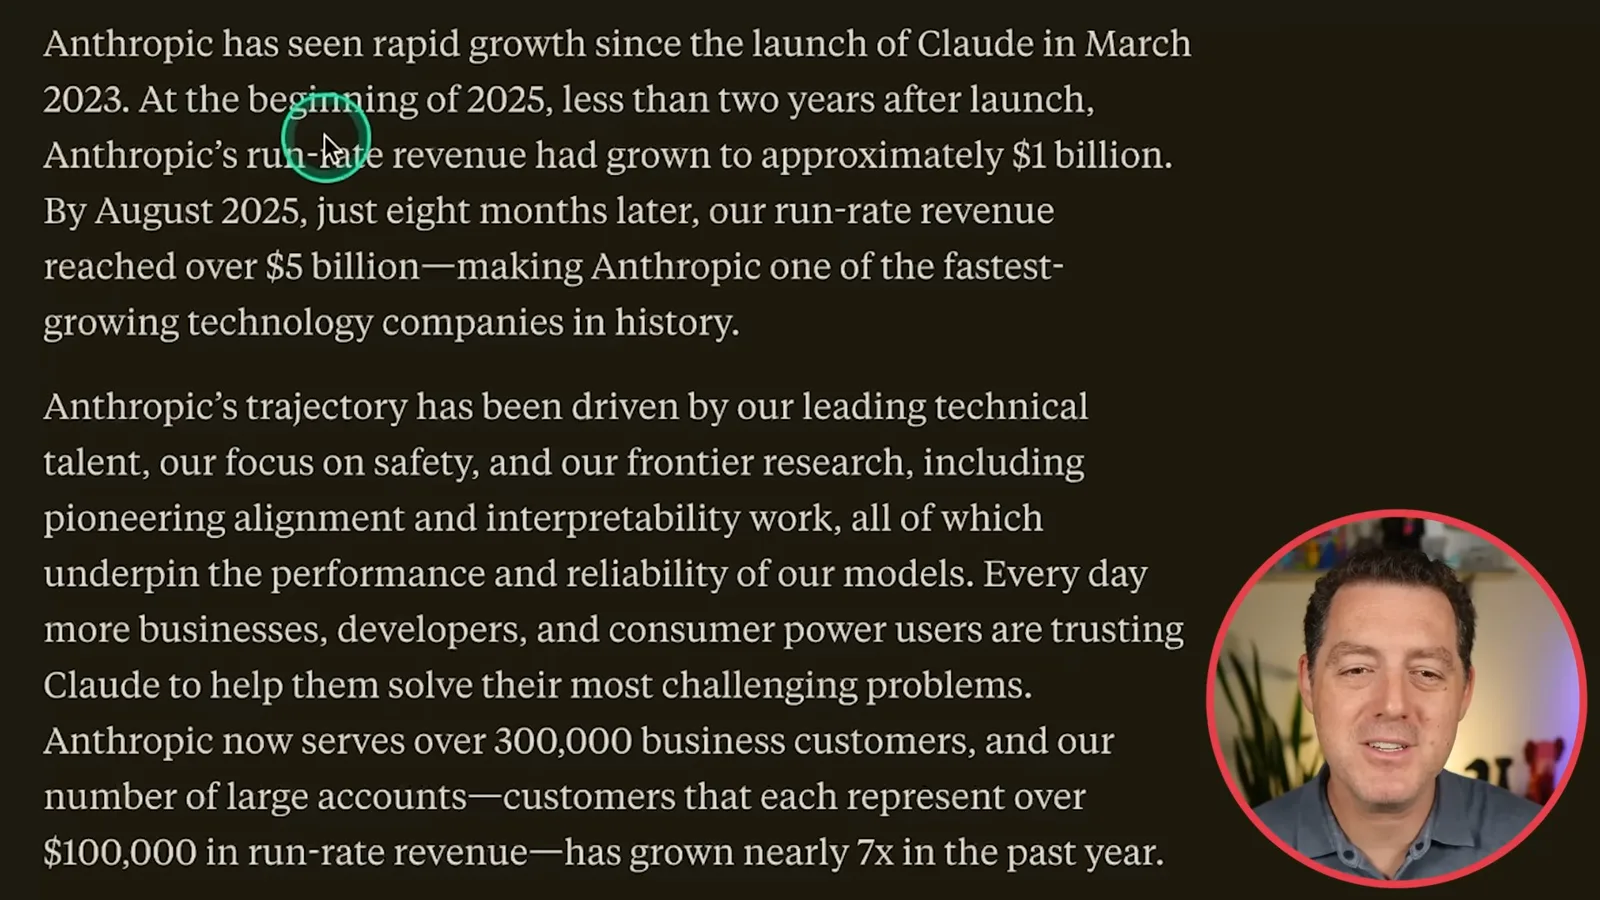
Anthropic announced a $13 billion Series F at a $183 billion post-money valuation. It reported a revenue run rate of roughly $1 billion at the start of 2025 and over $5 billion by August. A run rate annualizes a recent pace and is not the revenue actually earned over a full year ([Anthropic](https://www.anthropic.com/news/anthropic-raises-series-f-at-usd183b-post-money-valuation)).
I discuss Anthropic’s consumer privacy changes and say chats would be retained for five years. The company’s [notice](https://www.anthropic.com/news/updates-to-our-consumer-terms) makes that conditional: for new or resumed consumer chats and coding sessions, the five-year period applied when model-improvement sharing was enabled; users who did not choose it continued with the existing 30-day period, subject to stated exceptions. Commercial services had different terms, and the notice later listed October 8, 2025 as the selection deadline.
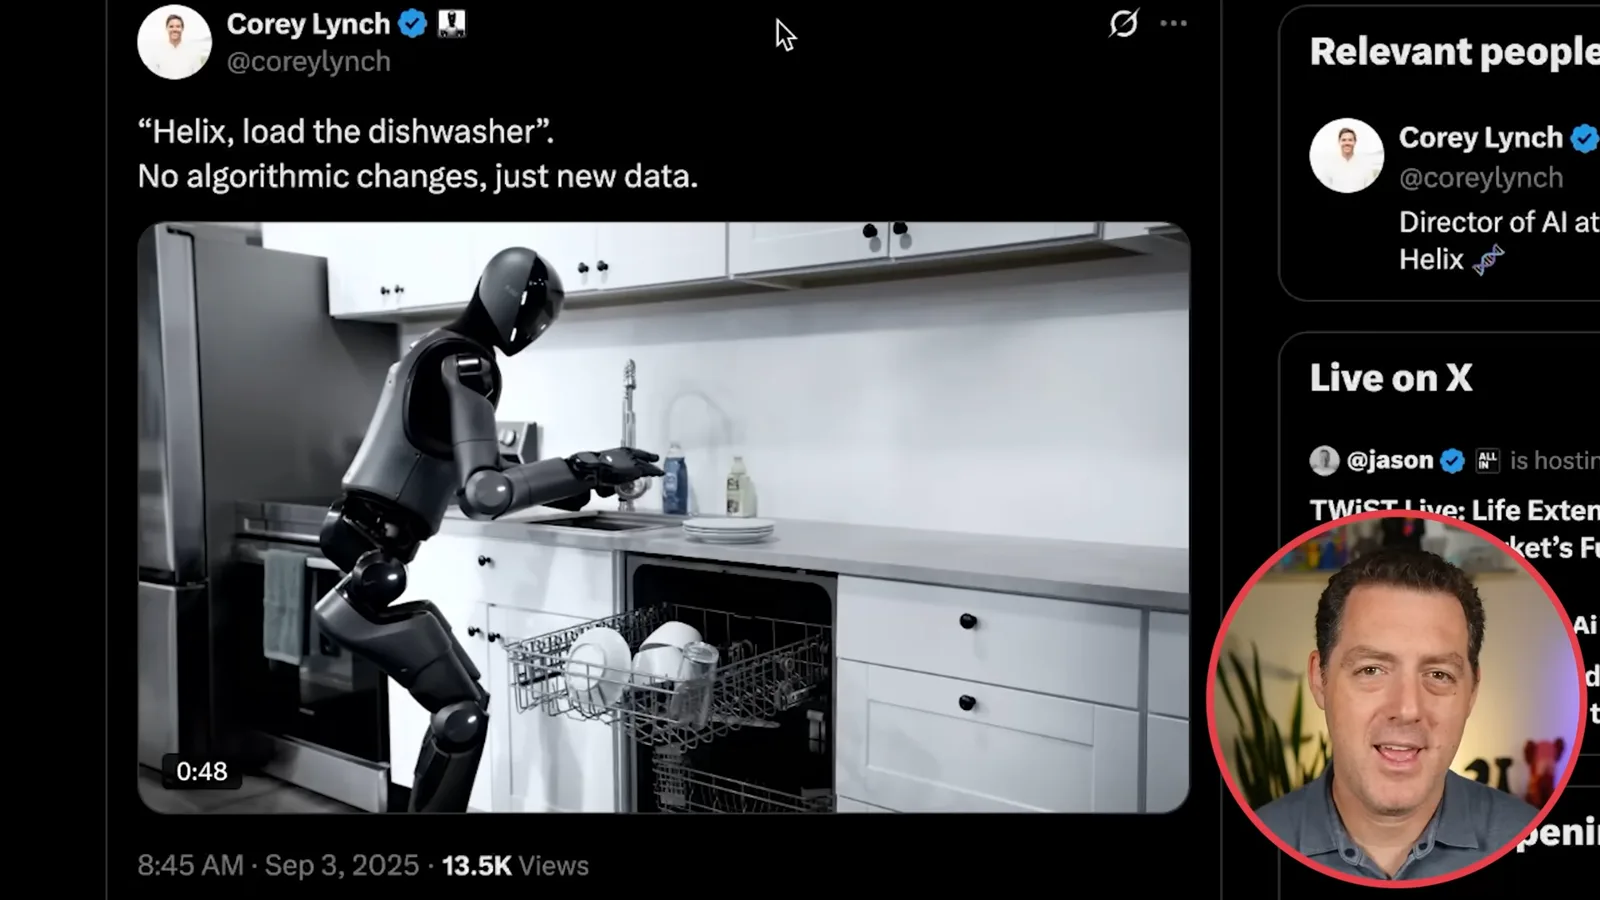
A Figure video shows a humanoid robot loading a dishwasher. I am impressed by its handling of dishes, although it moves slowly and makes small mistakes. This selected demonstration shows a particular task and setup; it does not establish reliable autonomous dishwashing in arbitrary homes.
I report that the court did not order Google to divest Chrome or Android in the search antitrust remedy, and that Alphabet shares rose. The ruling concerned remedies in that case, not a finding that Google had done nothing wrong. I speculate that browsers and mobile operating systems could become important interfaces for AI agents.
Audio generation and model evaluations
Berman reviews HunyuanVideo-Foley, Artificial Analysis and Microsoft research, then a Krea demonstration and Chinese AI-content labels.
Tencent announced HunyuanVideo-Foley, a text-and-video-to-audio framework. The company reports training on a 100,000-hour multimodal dataset; I listen to snowboarding, lion and skateboarding examples and like the apparent timing. These are selected demonstrations, and the [model license](https://github.com/Tencent-Hunyuan/HunyuanVideo-Foley/blob/main/LICENSE) has conditions, so availability is not the same as unrestricted use.
Artificial Analysis updates its intelligence index to version 3 with additional agent-oriented evaluations. I show the historical ordering of models on its index and appreciate that it runs tests itself. An aggregate ranking depends on the selected tasks, weights, evaluation setup and date.
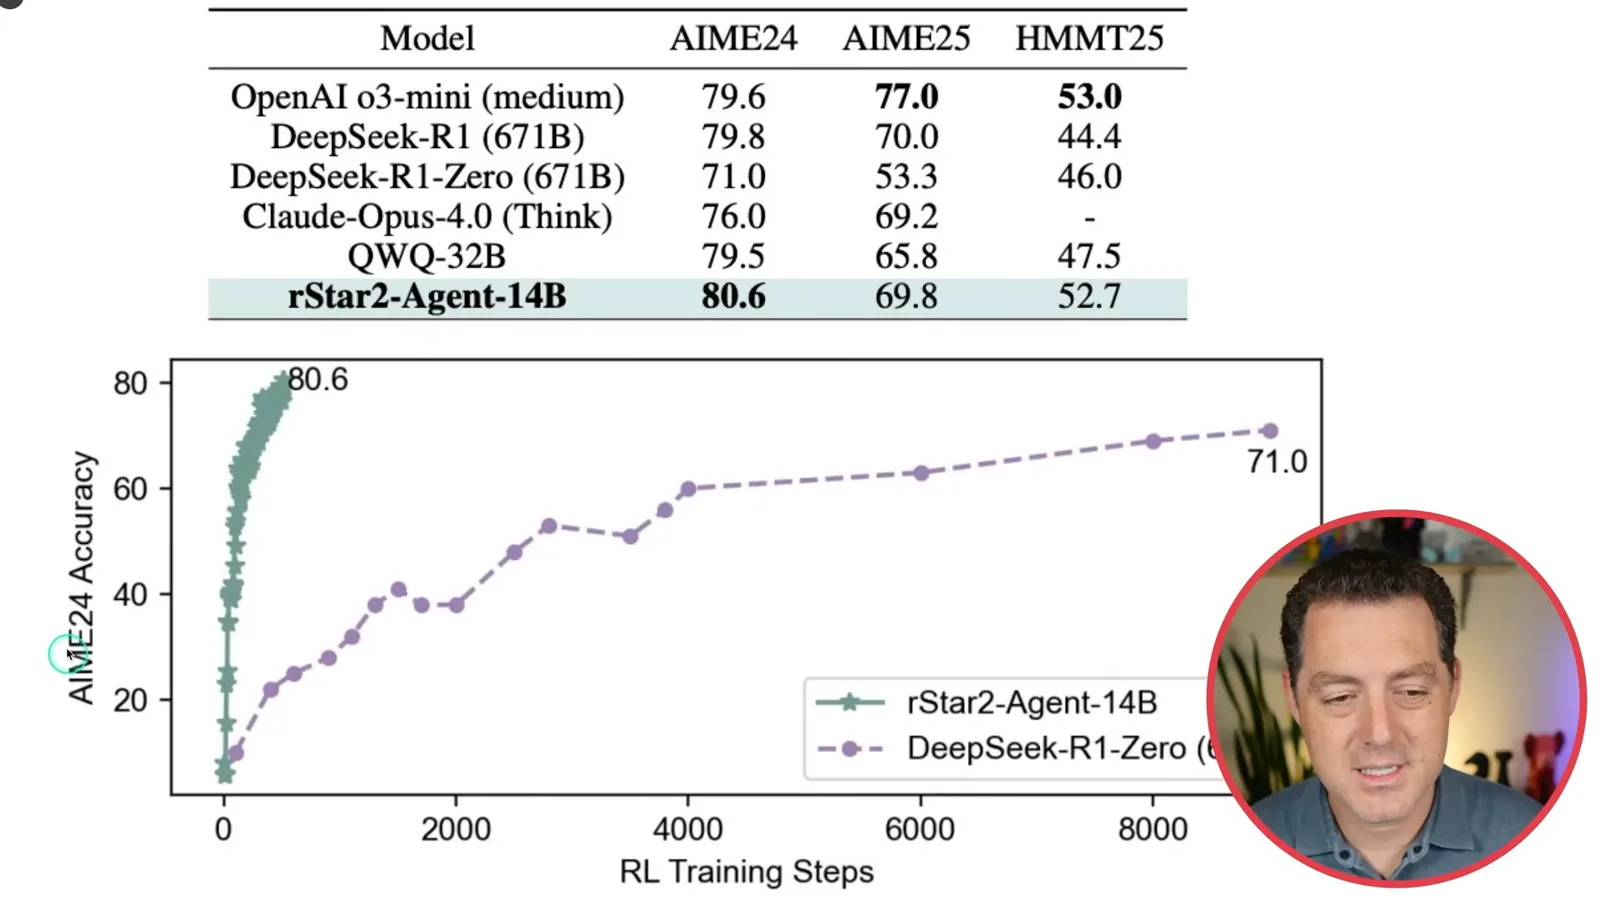
Microsoft researchers introduce rStar2-Agent, a 14-billion-parameter model using reinforcement learning and Python tools. Their [technical report](https://arxiv.org/abs/2508.20722) reports 80.6% average pass@1 on AIME 2024 and 69.8% on AIME 2025, with comparisons to larger models under specified settings. The chart shows a math benchmark and training trajectory, not a general claim that the smaller model outperforms DeepSeek-R1 at everything.
Krea demonstrates interactive real-time video generation: a user moves a rough fish or flower drawing and the output updates. I find the interaction striking. At the time the service was on a waitlist, and the selected demo does not establish its reliability across all prompts or devices.
I discuss Chinese platforms introducing labels for AI-generated content under rules taking effect in September 2025, including WeChat, Douyin, Weibo and Xiaohongshu. I support labeling and would like other platforms to do more. Implementation details and legal requirements depend on the relevant service, content and rules.
Medical research, safety and acquisitions
The roundup covers SeeMe, OpenRouter usage, ChatGPT safety plans, Statsig and Waymo. The health findings and product plans have specific limitations.
A [Communications Medicine study](https://www.research.ed.ac.uk/en/publications/computer-vision-detects-covert-voluntary-facial-movements-in-unre/) describes SeeMe, a computer-vision system measuring subtle facial responses to spoken commands. It enrolled 37 adults with acute brain injuries and 16 healthy volunteers; researchers report detecting eye opening on average 4.1 days earlier than clinical exams in the studied cohort. This is a small research study, not proof that the tool can diagnose awareness reliably in every patient.
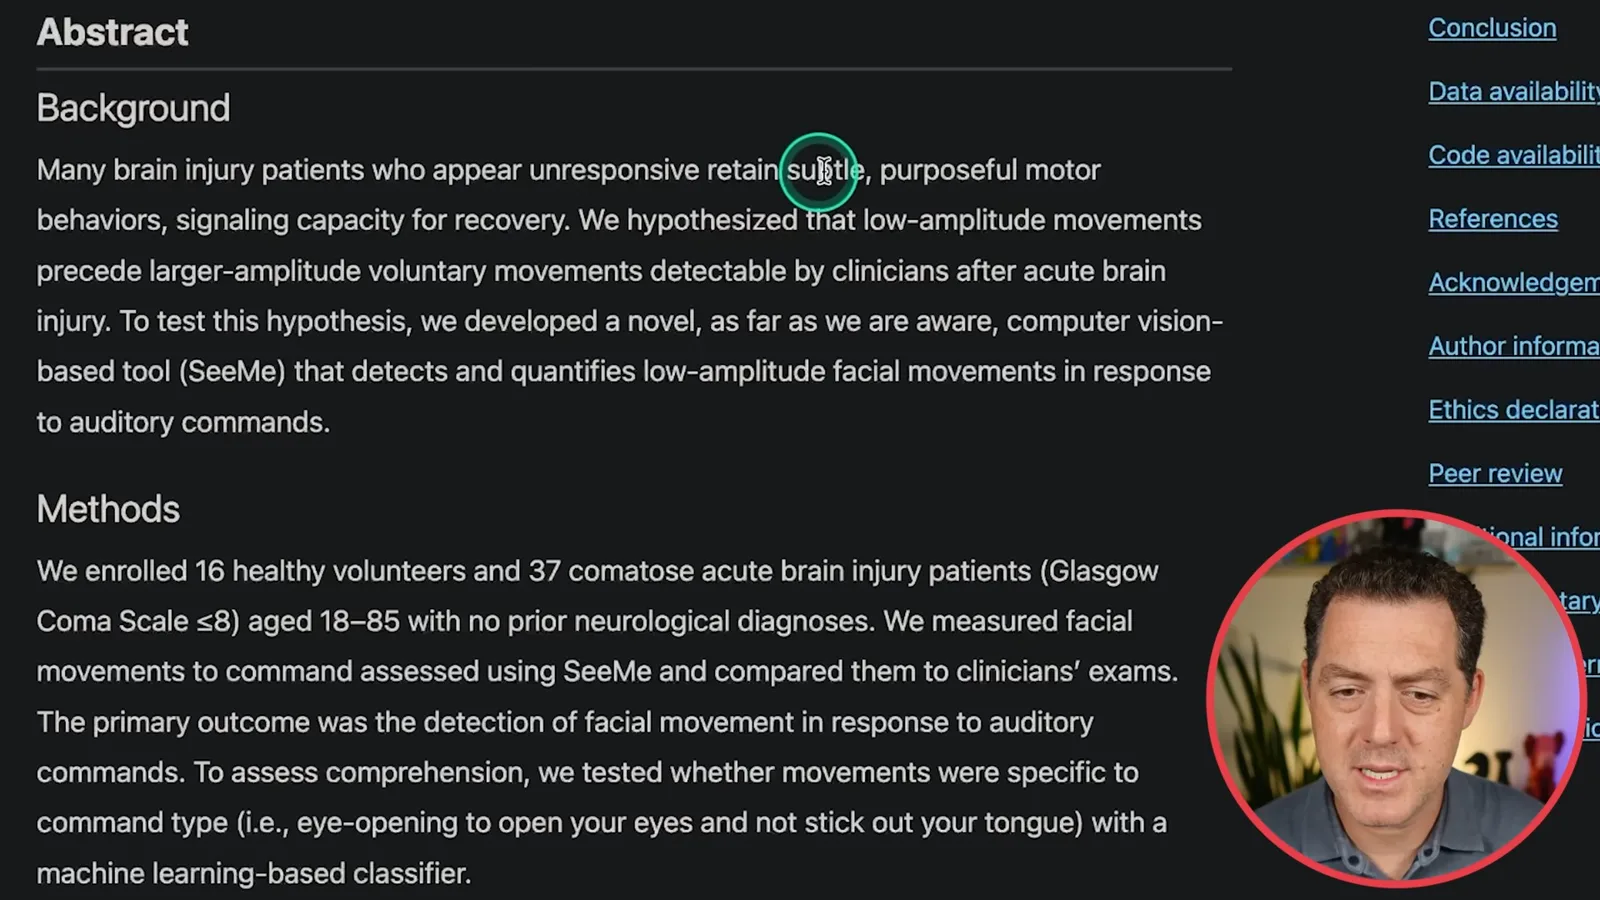
I argue that clinicians should be augmented by AI and say there is no downside. That is too broad: health systems also need clinical validation, monitoring and attention to errors, bias and privacy. An observed movement may be clinically meaningful but should not by itself be treated as definitive evidence of consciousness or recovery.
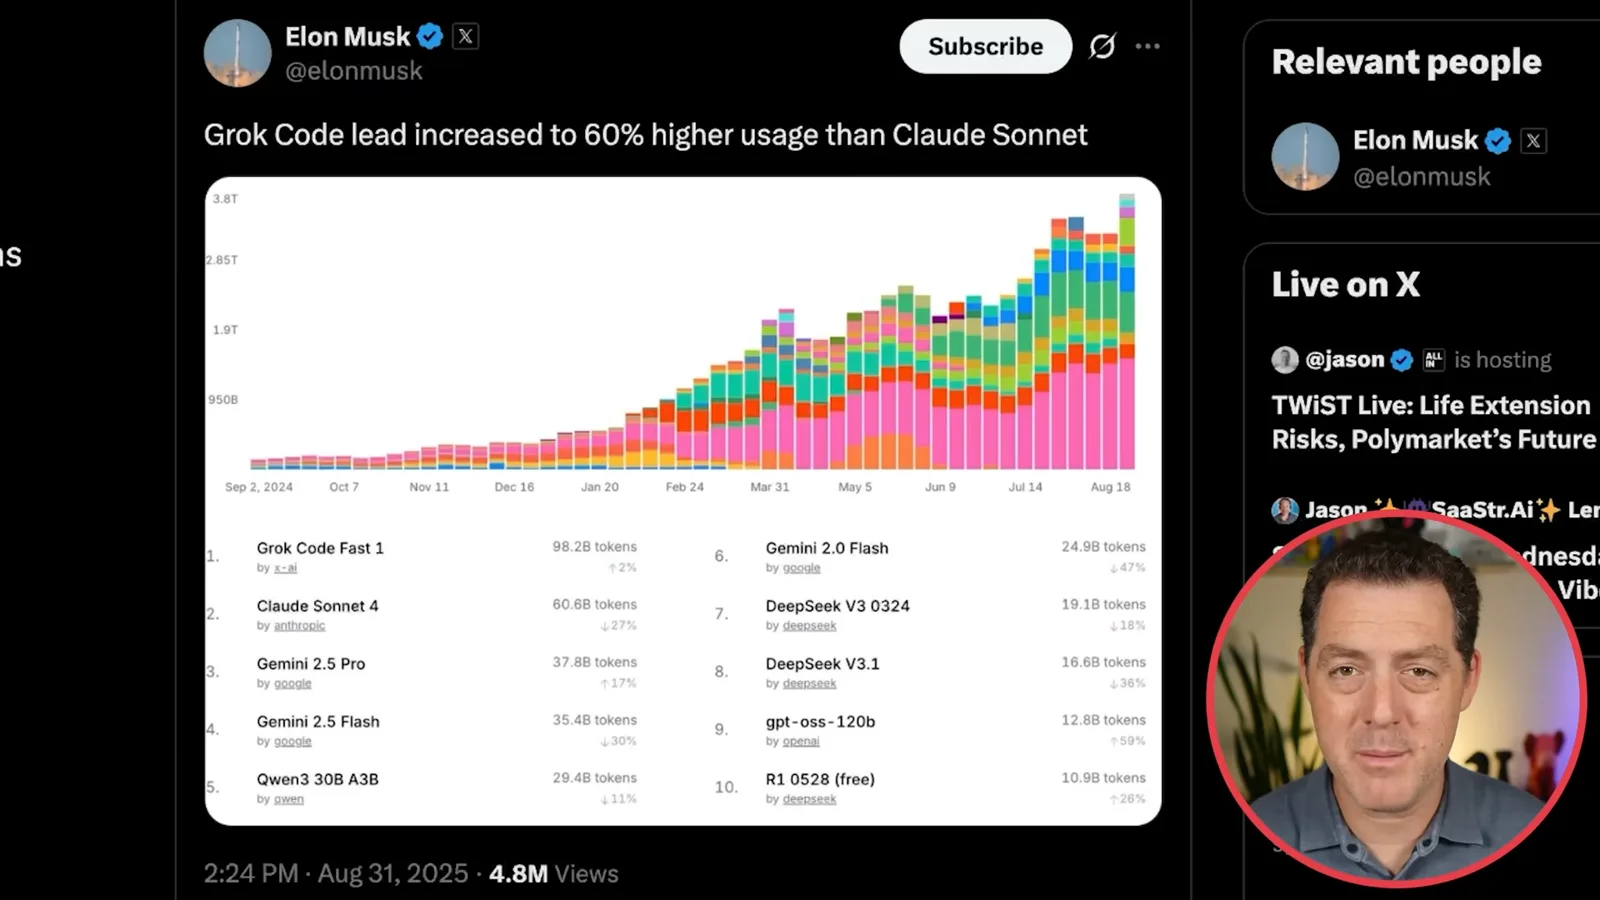
Elon Musk shares a chart showing Grok Code usage above Claude Sonnet on OpenRouter. I note that a free promotion and recent release could affect demand. The chart covers activity on that platform during a particular period, not all usage across every provider; price and novelty are plausible influences, not proven causes.
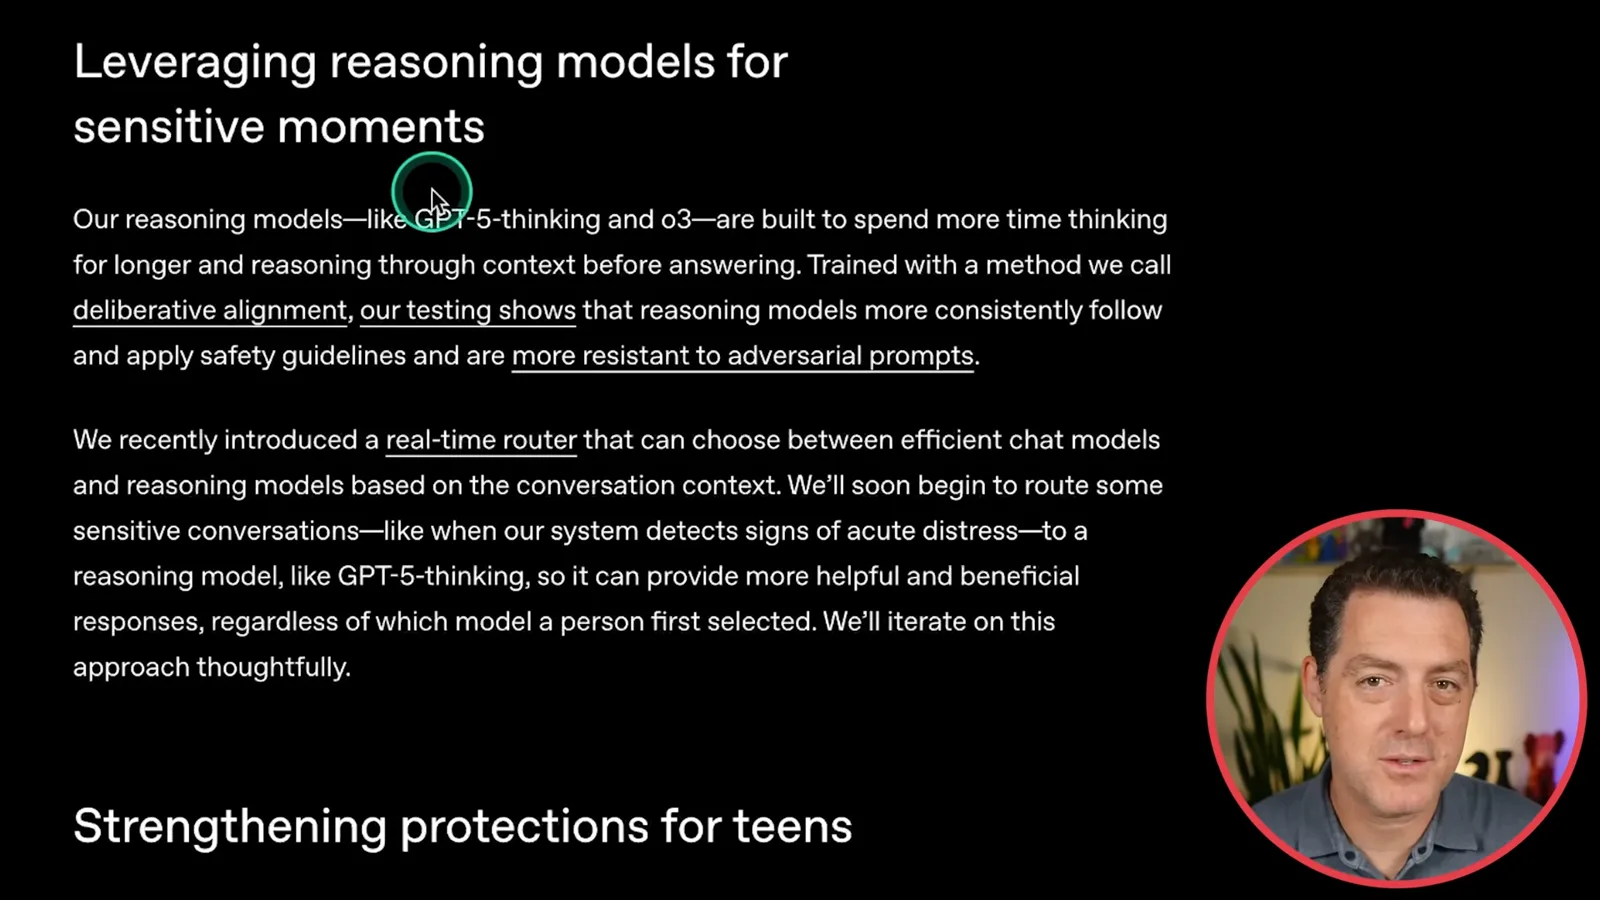
OpenAI announced plans for improved crisis interventions, easier access to support, trusted contacts and stronger protections for teens. It also described routing some sensitive conversations to reasoning models and developing parental controls. These were company plans in September 2025, not a guarantee that a chatbot can reliably identify every crisis or replace professional care ([OpenAI](https://openai.com/index/building-more-helpful-chatgpt-experiences-for-everyone/)).
I report that OpenAI agreed to acquire Statsig, a product experimentation company, in a reported $1.1 billion all-stock deal. OpenAI confirmed that Statsig founder Vijaye Raji would become CTO of Applications; the deal value and financing description are reported transaction details rather than information established by the official announcement ([OpenAI](https://openai.com/index/vijaye-raji-to-become-cto-of-applications-with-acquisition-of-statsig/)).
Finally, I discuss Waymo’s announced expansion plans for Seattle and Denver and share my positive personal experience riding in its vehicles. Those were plans at the time of the video, not proof that the service was already generally available in both cities.
같은 채널의 다른 글
 34:21EN
 Matthew Berman· 2026년 10월 27일Matthew Berman Examines Anthropic’s IPO Filing, AI Growth and GovernanceMatthew Berman, Sam Altman · Forward FutureThe presenter reviews the S-1’s financial metrics, compute strategy and voting structure while questioning the tension between rapid AI development and safety.
 0:26ENMatthew Berman· 2026년 10월 25일Sam Altman on Human Values and Problem-Solving in an AI WorldSam Altman · OpenAIIn a short interview excerpt, Altman considers the enjoyment of solving hard problems and the human role in interpreting results.
 0:36ENMatthew Berman· 2026년 10월 25일Kimi K3.1 and a Rubik’s Cube Solver DemonstrationMatthew Berman · Forward FutureMatthew Berman shows a scrambled virtual cube being solved and gives the Kimi K3.1 test a favorable assessment.
 0:21ENMatthew Berman· 2026년 10월 24일An AI-Generated Kimi Benchmark Chart Used Invented ScoresMatthew Berman · Forward FutureMatthew Berman asks for a graph of Kimi K3.1 Pro benchmarks, then discovers that the displayed figures are illustrative placeholders.
 25:50ENMatthew Berman· 2026년 10월 24일Kimi K3.1 Pro Tested: Strong 3D Demos, Uneven Results and Competitive PricingMatthew Berman · Forward FutureMatthew Berman tests the open-weight model on coding, 3D rendering and visual explanations, then compares benchmark results and prices.
 32:20ENMatthew Berman· 2026년 10월 23일Who Is Local AI For? The Costs, Trade-offs and a Hybrid FutureMatthew Berman · Forward FutureMatthew Berman weighs data control and independence against hardware cost, setup complexity and inference speed.