30초 요약
In this January 2026 short, Matthew Berman discusses OpenAI’s agreement to deploy Cerebras inference systems, shows a gpt-oss-120B provider-speed chart and speculates about a future acquisition. Cerebras CEO Andrew Feldman also appears briefly to comment on a type of memory. The shown chart does not substantiate a general 100-fold ChatGPT speedup. Subsequent Cerebras securities filings clarify the agreement’s staged deployment and contract terms, and the company’s own specifications list both on-chip and external memory.
- 1A multi-year capacity agreementThe companies announced 750 MW of Cerebras inference capacity; later filings provide the rollout and term details.
- 2An acquisition predictionBerman imagines a possible OpenAI acquisition of Cerebras, but presents no evidence of such a deal.
- 3A model-specific speed chartThe displayed gpt-oss-120B output-speed comparison shows Cerebras ahead in that chart, not a measured 100× improvement for ChatGPT overall.
- 4Wafer memoryOn-chip SRAM reduces some off-chip data movement, but Cerebras also specifies external memory for its systems.
핵심 정리
- OpenAI and Cerebras announced a multi-year agreement for 750 MW of inference capacity, with staged deployment beginning in 2026.
- Cerebras later disclosed deployment expected through 2028, with each capacity tranche initially contracted for three or four years.
- The displayed gpt-oss-120B output-speed chart is not evidence that all ChatGPT responses are 100 times faster.
- Cerebras’s wafer has on-chip SRAM, but its systems also offer external memory; the video does not establish immunity from all memory supply pressures.
- Berman’s suggestion that OpenAI might acquire Cerebras is speculation, not an announced transaction.
챕터별로 다듬은 전문 읽기
OpenAI and Cerebras agree on inference capacity
Berman describes a multi-billion-dollar arrangement and speculates about a possible acquisition. Later company filings clarify staged deployment and contract terms.
Matthew Berman reports that OpenAI and Cerebras have agreed to deploy Cerebras systems for faster AI inference. In the January 2026 announcement, the companies described a multi-year agreement for 750 megawatts of capacity, to be deployed in stages starting in 2026. The figure describes capacity in power terms, not a measurement of inference speed.
Berman cites reporting that the deal was worth more than $10 billion and describes 750 MW over three years. A later [Cerebras securities filing](https://www.sec.gov/Archives/edgar/data/2021728/000162828026025762/cerebras-sx1april2026.htm) says OpenAI committed to buy 750 MW of inference capacity and related services, with tranches expected in 2026–2028; each tranche has a three- or four-year term, extendable to five years. The filing describes the deal as worth more than $20 billion and includes an option for additional capacity. These details distinguish the rollout period from the term of each tranche.
Berman says he can imagine OpenAI acquiring Cerebras and notes that he recently interviewed Cerebras CEO Andrew Feldman. The acquisition idea is his speculation; the announced agreement is a computing partnership, not an announced acquisition.
Speed and memory architecture
A model-specific chart shows provider output speeds, followed by a discussion of wafer-scale memory. The chart does not establish a general 100× ChatGPT speedup.
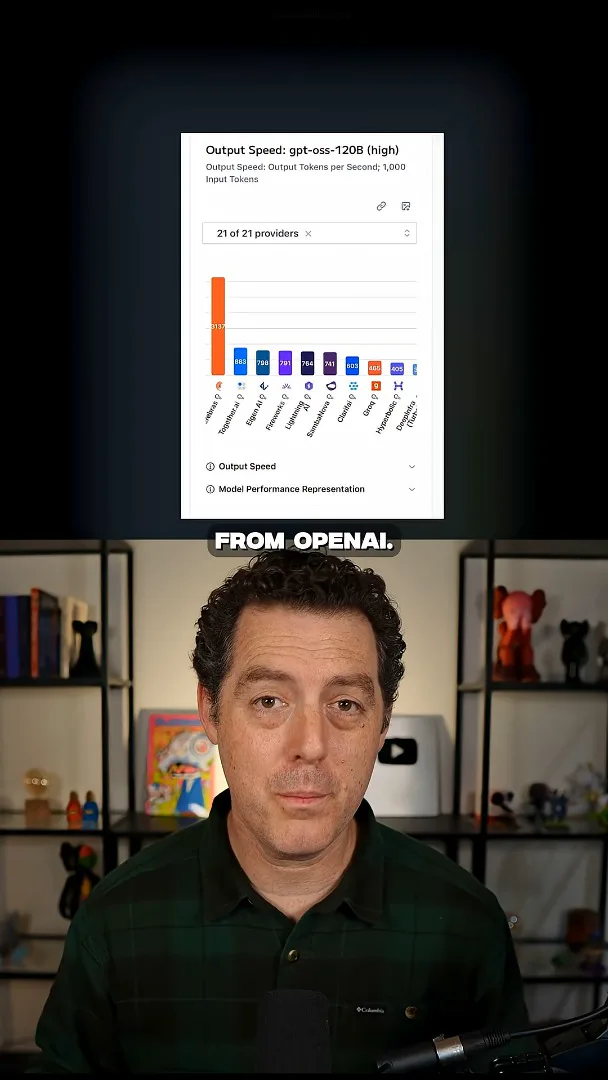
The video shows a provider output-speed chart for OpenAI’s open-weight gpt-oss-120B model, with a 1,000-token input. Cerebras leads the visible entries at roughly 3,137 output tokens per second, versus about 863 for the next visible provider—around 3.6 times in that displayed comparison. The chart neither compares ChatGPT as a whole nor demonstrates the headline’s 100-fold claim; speeds depend on model, workload, provider and measurement conditions.
Berman attributes Cerebras’s speed in part to putting memory on its wafer-scale chip and contrasts it with memory supplies affecting other hardware. On-chip SRAM is an important feature, but it is not the whole memory system: [Cerebras specifies 44 GB of on-chip SRAM and external-memory options](https://www.cerebras.ai/press-release/cerebras-announces-third-generation-wafer-scale-engine) for WSE-3 systems. The discussion does not establish that Cerebras is unaffected by all memory shortages or that all workloads keep all data on the wafer.
A brief comment from Cerebras’s CEO
Andrew Feldman says Cerebras does not use the memory type under discussion and sees a benefit. The clip does not establish that the company is immune to every memory supply constraint.
In a brief clip from Berman’s earlier interview, Feldman says Cerebras does not use the particular memory type under discussion and sees that as a benefit. Berman expects faster inference ultimately to benefit users. The clip does not quantify a universal speedup or the effect of supply constraints on the company’s complete systems.
같은 채널의 다른 글
 34:21EN
 Matthew Berman· 2026년 10월 27일Matthew Berman Examines Anthropic’s IPO Filing, AI Growth and GovernanceMatthew Berman, Sam Altman · Forward FutureThe presenter reviews the S-1’s financial metrics, compute strategy and voting structure while questioning the tension between rapid AI development and safety.
 0:36ENMatthew Berman· 2026년 10월 25일Kimi K3.1 and a Rubik’s Cube Solver DemonstrationMatthew Berman · Forward FutureMatthew Berman shows a scrambled virtual cube being solved and gives the Kimi K3.1 test a favorable assessment.
 25:50ENMatthew Berman· 2026년 10월 24일Kimi K3.1 Pro Tested: Strong 3D Demos, Uneven Results and Competitive PricingMatthew Berman · Forward FutureMatthew Berman tests the open-weight model on coding, 3D rendering and visual explanations, then compares benchmark results and prices.
 32:20ENMatthew Berman· 2026년 10월 23일Who Is Local AI For? The Costs, Trade-offs and a Hybrid FutureMatthew Berman · Forward FutureMatthew Berman weighs data control and independence against hardware cost, setup complexity and inference speed.
 1:03:37ENMatthew Berman· 2026년 10월 23일Matthew Berman’s Team Tests Kimi K3.1 on Animation, Games, and ChartsMatthew Berman, Alex, Brian · Forward FutureA live team AMA turns into an informal test of Kimi K3.1, from personal-agent workflows to motion graphics, a browser game, and a benchmark chart.
 0:53ENMatthew Berman· 2026년 10월 22일Sam Altman on AI and the Discovery of New KnowledgeSam Altman · OpenAIAltman expects progress in mathematical discovery to extend to biology, materials and energy.