30초 요약
Matthew Berman introduces NVIDIA's 2024 Multi-LoRA support for its RTX AI Toolkit. Multiple fine-tuned adapters can share one base model in memory. NVIDIA reports up to sixfold faster inference under a particular benchmark configuration; Berman discloses NVIDIA's partnership on the video.
- 1Multiple customizationsBerman describes an application that needs multiple fine-tuned variants of a base model.
- 2Shared base modelMulti-LoRA serving can load a single base model alongside multiple adapters, reducing duplication in memory.
- 3A conditional performance claimNVIDIA reports up to 6x inference throughput in a particular RTX 4090 configuration; the video is an NVIDIA partnership.
핵심 정리
- Multi-LoRA serving uses multiple fine-tuned adapters with a shared base model rather than loading separate full copies.
- NVIDIA's up-to-6x figure is a vendor-reported inference throughput result for a specific configuration, not a universal latency or speed guarantee.
- Berman describes it as a useful deployment approach; the best choice depends on the workload and hardware.
- NVIDIA partnered with Berman on this video.
챕터별로 다듬은 전문 읽기
Serving multiple adapters
Berman introduces the need for model customizations and describes sharing a base model across adapters.
Matthew Berman asks developers to imagine needing several fine-tuned versions of a model for different use cases. NVIDIA's RTX AI Toolkit added Multi-LoRA support, allowing multiple adapters to share a single base model in memory rather than requiring a separate full model for each variant.
Berman cites a sixfold performance improvement. NVIDIA's 2024 announcement describes up to 6x inference throughput under a particular RTX 4090 setup, with a 3B model, specific sequence lengths and batch sizes; that is not a promise of the same gain in every deployment or for single-request latency.
Performance and disclosure
He cites NVIDIA's reported speedup and recommends the toolkit. NVIDIA partnered with him on the video.
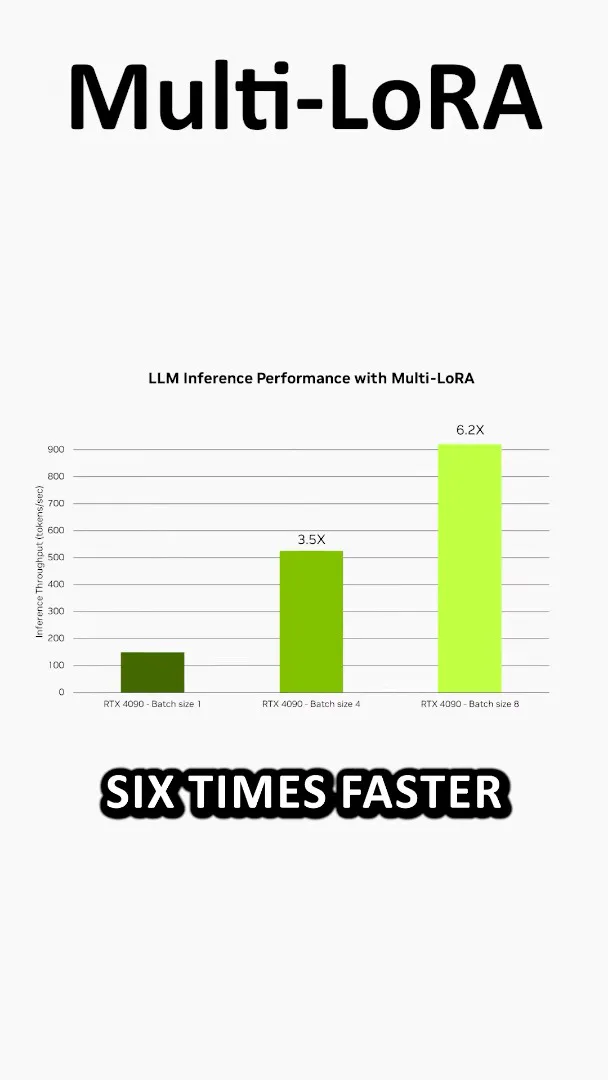
Berman recommends the approach for serving multiple fine-tuned variants locally or in the cloud and points to NVIDIA's technical article. He discloses that NVIDIA partnered on the video. Choosing a production approach still depends on hardware, workload and evaluation.
같은 채널의 다른 글
 34:21EN
 Matthew Berman· 2026년 10월 27일Matthew Berman Examines Anthropic’s IPO Filing, AI Growth and GovernanceMatthew Berman, Sam Altman · Forward FutureThe presenter reviews the S-1’s financial metrics, compute strategy and voting structure while questioning the tension between rapid AI development and safety.
 0:36ENMatthew Berman· 2026년 10월 25일Kimi K3.1 and a Rubik’s Cube Solver DemonstrationMatthew Berman · Forward FutureMatthew Berman shows a scrambled virtual cube being solved and gives the Kimi K3.1 test a favorable assessment.
 25:50ENMatthew Berman· 2026년 10월 24일Kimi K3.1 Pro Tested: Strong 3D Demos, Uneven Results and Competitive PricingMatthew Berman · Forward FutureMatthew Berman tests the open-weight model on coding, 3D rendering and visual explanations, then compares benchmark results and prices.
 32:20ENMatthew Berman· 2026년 10월 23일Who Is Local AI For? The Costs, Trade-offs and a Hybrid FutureMatthew Berman · Forward FutureMatthew Berman weighs data control and independence against hardware cost, setup complexity and inference speed.
 1:03:37ENMatthew Berman· 2026년 10월 23일Matthew Berman’s Team Tests Kimi K3.1 on Animation, Games, and ChartsMatthew Berman, Alex, Brian · Forward FutureA live team AMA turns into an informal test of Kimi K3.1, from personal-agent workflows to motion graphics, a browser game, and a benchmark chart.
 0:53ENMatthew Berman· 2026년 10월 22일Sam Altman on AI and the Discovery of New KnowledgeSam Altman · OpenAIAltman expects progress in mathematical discovery to extend to biology, materials and energy.