30초 요약
Robinhood reports that roughly 60% of its data-pipeline pull requests merged without human review as of August 2026. Chetas Joshi credits a hybrid gate: deterministic checks verify registry and lineage facts, an AI reviewer searches code for risks those checks miss, and people handle sensitive or uncertain cases. The team reports a roughly 2% miss rate and updates its rules manually from human feedback; its proposed unified architecture is not yet built.
- 1Scripts, agent and people own different parts of reviewMerge requires both passing deterministic checks and an approval. Sensitive and uncertain decisions go to a person.
- 2A green schema change hid an unregistered downstream failureThe agent found a job writing a widened column into a narrower destination. A human verified it was live and fixed the downstream table first.
- 3Humans update the rules weekly; the reviewer does not retrain itselfReview replies are collected daily and the on-call engineer manually adjusts the rules.
- 4A 2% reported miss rate comes without one clean false-escalation numberJoshi says an overcautious reviewer can also waste human time, so both kinds of mistake matter.
- 560% of pipeline PRs merged without human reviewAs of August 31, 2026, Joshi also reports 75% less manual review effort and about 132 engineering hours saved monthly.
- 6The current parallel systems lack a shared runtime viewThe agent cannot see the scripts’ actual outcomes or call live checks. A proposed unified entry point has not been built.
핵심 정리
- Use deterministic checks for facts available from authoritative systems, and an agent for context-dependent judgment.
- Require a person for sensitive grants, changes in data meaning and low-confidence decisions.
- Treat “no consumer found in the searched code” differently from proof that no consumer exists.
- Measure missed bad changes and unnecessary escalations; both shape review rules.
- Keep human feedback and rule updates explicit rather than assuming the reviewer learns automatically.
챕터별로 다듬은 전문 읽기
Why green CI does not prove a pipeline change is safe
AI-created pull requests arrive faster than a small data-platform team can review. The team divides work among scripts, an agent and people.
A pull request changes a schema in a data pipeline and passes every automated check. That still does not prove it is safe: a downstream consumer might break, a freshness deadline might slip, or a change might expose data that should remain restricted.
Chetas Joshi builds data-ingestion and processing systems on Robinhood’s data platform team. He describes a reviewer for production data-pipeline changes, including schemas, code, configuration and access grants. Coding assistants can open these requests faster than the small group with the context to review them can read them.
Existing CI and human review catch broken code, inefficient queries, downstream failures and sensitive-data risks. The constraint is the human reviewer’s time and knowledge: who reads a table, how large it is and how sensitive its contents are.
The team divides responsibility three ways. Deterministic scripts verify facts against authoritative systems; an AI agent judges risks requiring context; people retain decisions the system explicitly protects. Both the checks and an approving review are required before merge.
A failed script check turns CI red and blocks the request. The agent’s instructions describe what those scripts cover so it can focus on other risks. Joshi says that division also saves cost by avoiding model calls to rediscover facts a script can look up.
A schema change passes checks but may hide a consumer
Scripts check contracts, tags, recorded lineage and performance. Their view is limited by the systems they query.
The running example adds a column to a data-lake table and widens an existing column from integer to big integer. Widening looks harmless until the team asks who reads the column downstream and whether all readers appear in the lineage system.
Layer-one scripts compare schema and keys with the schema registry, check that each table has an owner and that personal information is labeled, and block the PR if those facts do not match the required state. In the example, the new upstream column and the tags pass.
Another script walks recorded lineage to see whether registered downstream jobs break. A staging performance test uses mock data at production volume to check cluster sizing and freshness deadlines. Both checks pass in the example, but lineage can only cover relationships it actually records.
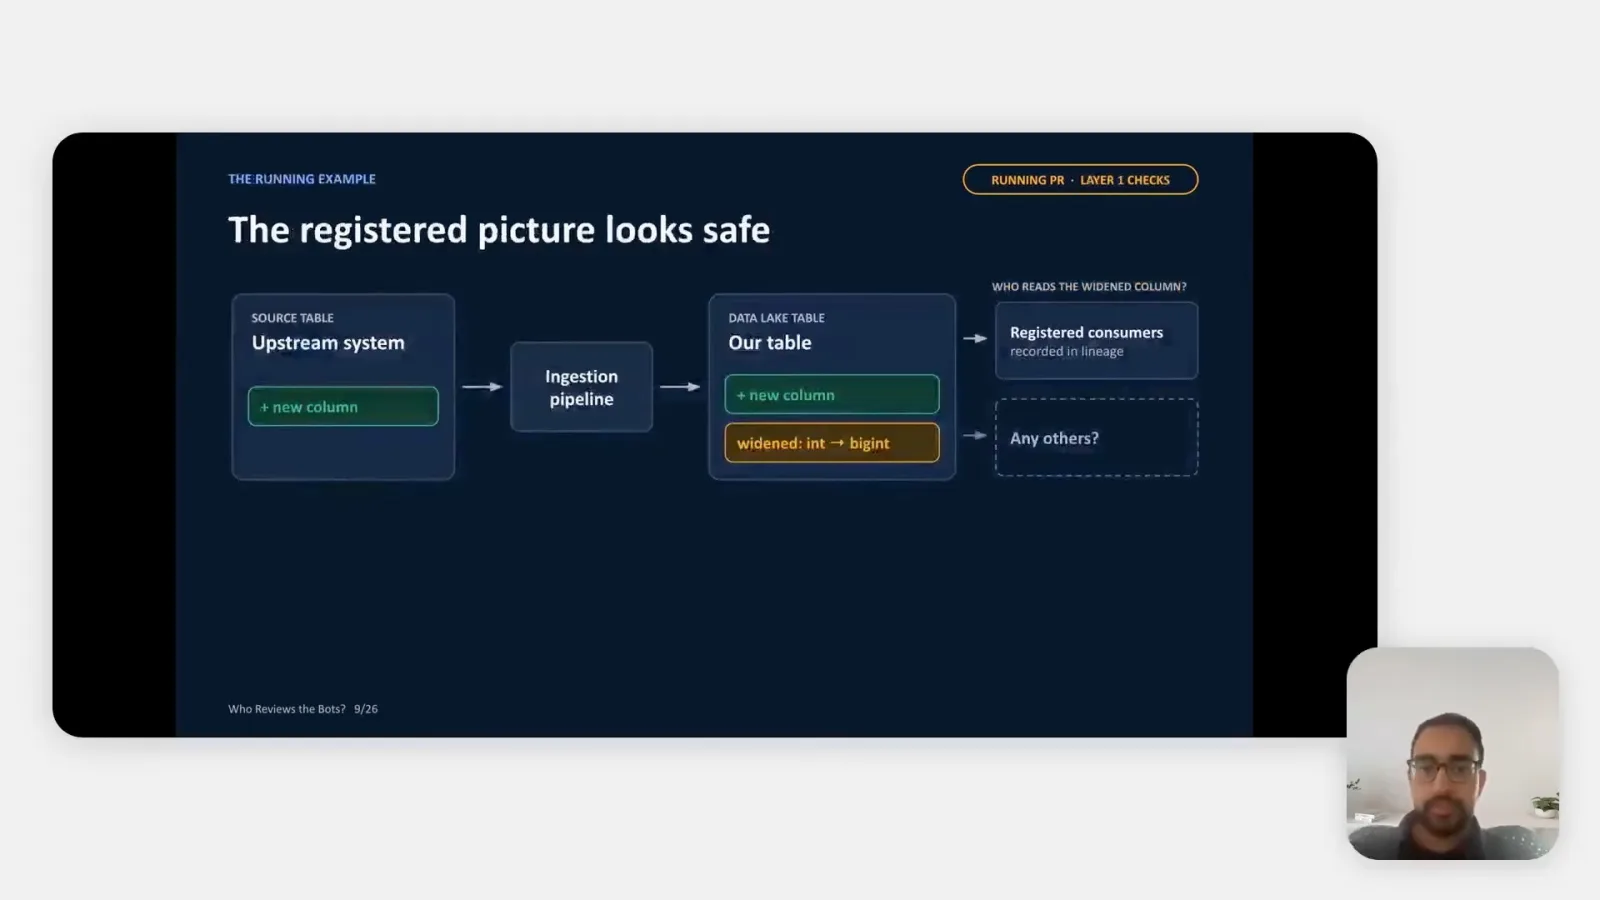
The agent finds an unregistered downstream job
Repository search finds a narrower destination type that registered lineage missed. A human verifies the job and fixes the downstream table first.
The agent reads the diff, PR description and commit messages, then searches files across the repository. The author’s intent provides context but cannot override contradictory code. Its tools can read, search and list repository files; they cannot query the live catalog, lineage system or production state.
Rules vary by change type and target problems such as expensive query patterns, sensitive-data access and consumers absent from lineage. The agent follows pipeline definitions and access grants to find relationships that a person might otherwise have to trace manually.
In the example, the agent finds an unregistered job reading the widened column and writing it to another table where the destination remains an integer. Once a value exceeds the old type’s capacity, that write will fail even though every registered check was green.
Different query engines publish their own lineage, so a missing publication leaves a gap. Repository search has a different blind spot: ad hoc queries and dashboards outside the codebase do not appear. The agent may say it found no consumer in the places searched; it cannot claim no consumer exists anywhere.
The review gives line-specific comments, the reasoning and a risk score. Low-risk requests can receive agent approval; serious risk is escalated with enough evidence for a human to investigate. Passing scripts and an approval from either the agent or an authorized human are both needed to merge.
For the widened column, a human confirmed that the unregistered consumer was active in production. The team widened the downstream destination first and merged the original change afterward. Joshi describes this as a sequencing fix that avoided an incident, not a rejection of the change.
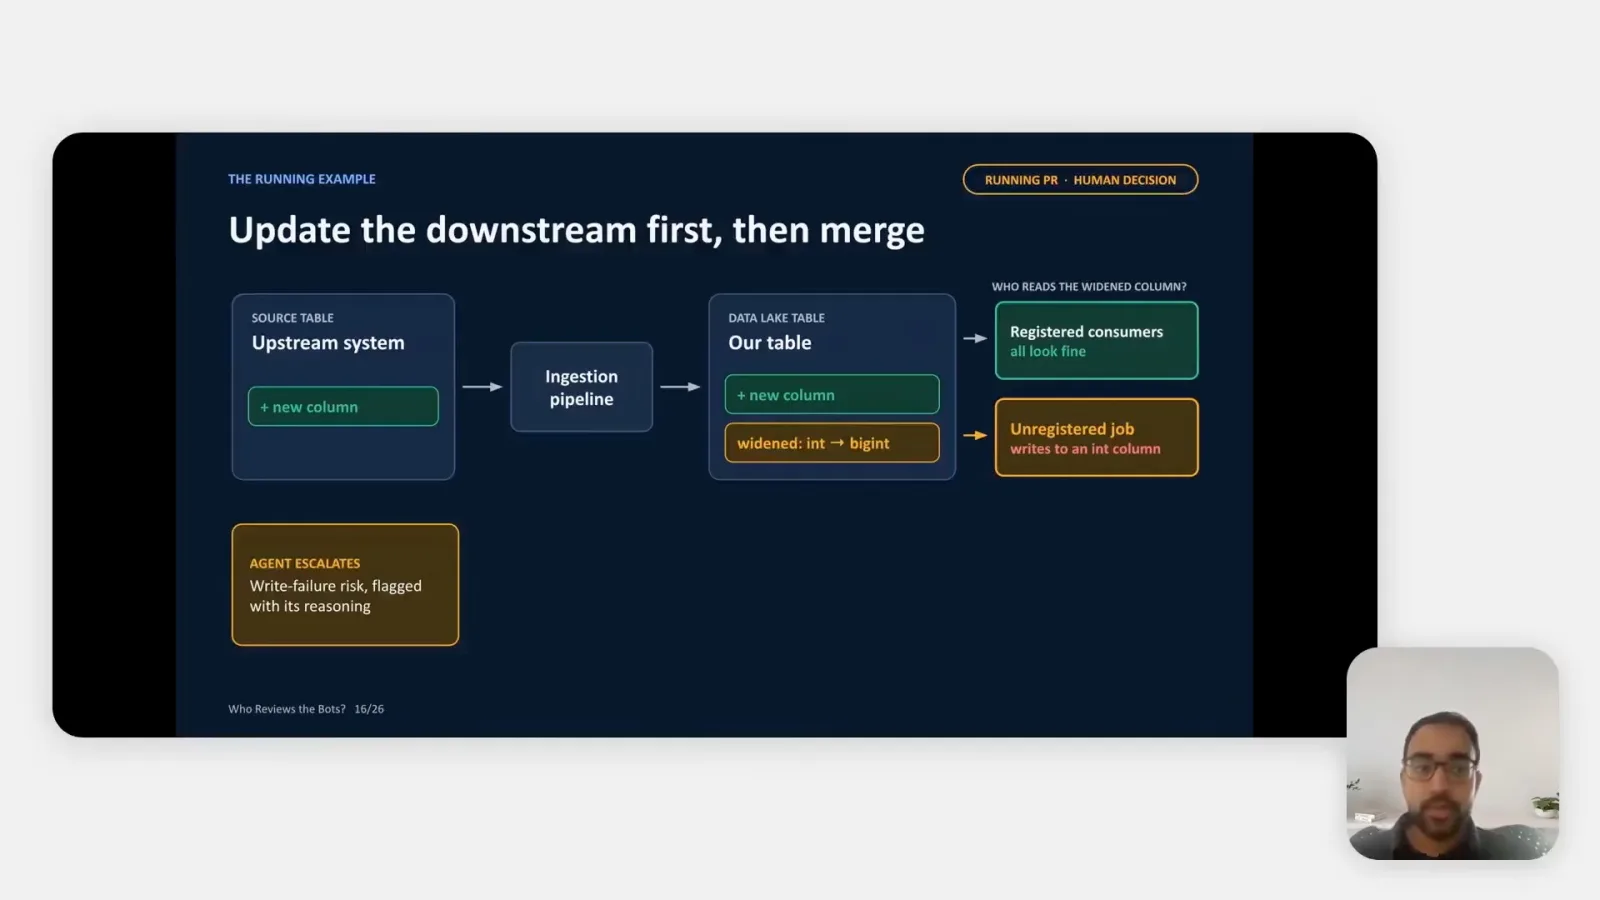
Protected decisions and human feedback
Sensitive grants, semantic migrations and uncertain verdicts require people. On-call engineers manually revise rules based on review replies.
Some decisions always go to a person: grants involving sensitive data, migrations that change the meaning or intent of data, and reviews where the agent lacks confidence. The agent can explain the risk, but it cannot approve these protected cases simply because no concrete problem was found.
Human reviewers reply to agent comments with agreement or disagreement and an explanation. Replies are collected daily; once a week the on-call engineer reads them and manually updates review rules. Nothing currently retrains or changes the rules automatically, and a proposed investigation agent to help is not built yet.
In a separate case, a source column was labeled personal information but the pipeline encrypted it before writing to the data lake. The agent objected to a nonsensitive lake label; the author and a human reviewer considered the classification appropriate in that specific pipeline. The correction can prevent similar needless escalations.
Joshi cautions that this is not a general rule that encryption makes data nonsensitive. The conclusion depends on the specific pipeline and its treatment of the value before the write.
Count missed risks and needless escalations
The team reports a 2% miss rate but no single clean false-escalation figure. One missed privacy-retagging case became a new rule.
The team tracks two error types: a bad request approved by the agent, and a safe request unnecessarily escalated to a person. Escalating everything might avoid misses but would not reduce review work. As of August 31, 2026, the reported miss rate was about 2%; Joshi says there was no clean single false-escalation figure.
One missed case involved columns retagged as sensitive and moved from an open data copy to a restricted one. A downstream reader still depended on the old copy, so it broke after the columns disappeared. The team added a rule to search for readers of columns that will leave the open copy.
Results and an unbuilt architecture proposal
Joshi reports less review effort and fewer incidents as of August 2026. The existing parallel systems lack a shared runtime picture.
Joshi reports that, as of August 31, about 60% of data-pipeline PRs merged without human review, manual review effort fell about 75%, and the team saved roughly 132 engineering hours per month. Incidents tied to those PRs fell about 30%. Protected decisions still require people.
The current design has a weakness: scripts and the agent run independently in parallel. The agent knows what the scripts are configured to check, but not their actual pass, fail or outage state. Neither side has the complete runtime picture, and a human must step in when one side cannot finish.
The platform team is exploring a single entry point that would consider the whole PR, decide which changes to review together and expose layer-one checks as callable tools to the agent. Joshi explicitly describes this as a proposal, not a system already in production.
His closing advice is to prove authoritative facts with inexpensive deterministic checks, reserve sensitive or uncertain decisions for humans, and count false escalations as well as missed problems. The goal is to reduce review work without giving up accountability.
같은 채널의 다른 글
 38:50EN
 AI Engineer· 2026년 11월 10일LinkedIn’s self-improving agent first had to fix its judgesZiwei Guo, Saloni Gandhi · LinkedInA prompt-optimization loop improved a career agent, but unreliable evaluators required human calibration first.
 12:57ENAI Engineer· 2026년 11월 10일Harvey’s agents scaled until their platform and merge queue brokeJoey Wang · HarveyAfter an alert spawned 900 agents and one engineer launched 950 tasks, Harvey added deduplication and fair scheduling.
 19:41ENAI Engineer· 2026년 11월 9일A high-reliability automation starts by routing the hard cases awayMatthew Jewkes · Standard CyberneticsMatthew Jewkes describes separating critical errors, ambiguous decisions and unusual exceptions in a biopharma indexing workflow.
 52:08ENAI Engineer· 2026년 11월 9일When coding agents overwhelm a self-hosted model, reject earlyHarshul Jain, Parv Khatri · AudibleAdmission control can protect GPU capacity, but benchmark it against every offered request—including the ones rejected.
 22:01ENAI Engineer· 2026년 11월 9일Zach Lloyd: make the software factory measurable and editableZach Lloyd · WarpWarp’s CEO proposes recording agent runs, scoring failures and testing changes to the workflow on real tasks.
 27:35ENAI Engineer· 2026년 11월 9일Uber traded an always-green trunk for faster AI-scale mergesPreetam Dwivedi, Manjari Akella · UberIts merge queue now relaxes some conflicts and validates the combined state after landing, with a verified-good fallback.