30초 요약
Warp CEO Zach Lloyd argues that coding agents need an environment teams can govern and improve, not just individual prompts. His proposed factory stores agent runs and defines its workflows in version-controlled code. Scoring agents identify recurring problems and propose changes, while benchmarks replay a company’s own tasks to compare model cost and quality. His demonstration uses Warp’s proprietary platform and model-judged scores; he also recommends sandboxing, specification-based verification and measuring cost per pull request.
- 1Sandbox agents and make their tools auditableLloyd says local agents can inherit user access and individual configurations can be hard to govern.
- 2Keep the factory definition in version-controlled codeWorkflows, tools and execution settings can then be tested across versions and changed through pull requests.
- 3Score real runs to find repeated failuresHis demo uses model judges, including a scorer for redundant tests, and aggregates findings for proposed workflow fixes.
- 4Replay your own tasks to compare modelsLloyd’s internal example compares model-judged correctness against cost; he says human grading is also sensible.
- 5Use specifications and user-facing evidence to verify changesLloyd suggests these can reduce the review burden created by many generated pull requests.
- 6Warp Factories is proprietaryLloyd says the platform supports existing tools and is available beyond enterprises, but is geared toward teams.
핵심 정리
- Record representative agent runs and outcomes so recurring failures can be investigated.
- Version workflows, agent definitions and tools to make changes testable.
- Compare model cost and quality on tasks from your own codebase.
- Sandbox agents and decide who controls data, infrastructure and inference.
- Measure verification and evaluation costs alongside cost per pull request.
챕터별로 다듬은 전문 읽기
From individual prompting to governed workflows
Lloyd describes the limitations he sees in local agents and his proposal for sandboxed software factories.
Zach Lloyd, founder and CEO of Warp and a former Google Docs engineering lead, describes software factories as infrastructure for development with agents. Warp sells a factory platform, which he uses for his demonstration.
Lloyd says many companies are still at interactive prompting: engineers direct local agents to build features and fix bugs. They want more automated development that delivers business value with manageable cost and governance, but a person can become the bottleneck.
He argues that a compromised local agent may have the same access as its user, while individually configured tools and skills are difficult to audit. His proposed approach is to sandbox agents and run them in the cloud.
In his model, people submit work and agents participate in triage, specifications, implementation and verification. Organizations define how people and agents interact, then measure and improve the workflow over time.
Define and measure the factory
He recommends versioned configuration, control of data and compute, and benchmarks based on real work.
Lloyd recommends treating the factory as an infrastructure stack, open to different models and agent frameworks and adaptable to existing systems. Define workflows, skills, tools and execution environments in version-controlled code, so versions can be tested and agents can propose changes.
He says larger customers want control over their input and output data, infrastructure and inference, with the ability to choose models and frameworks. He calls this AI sovereignty and argues that companies should own the core ingredients of the system.
Public benchmarks are not enough to select a model for a particular organization, Lloyd argues. Record real tasks, score agent runs, use the results to find failure patterns and build benchmarks that compare configurations on the company's own work.
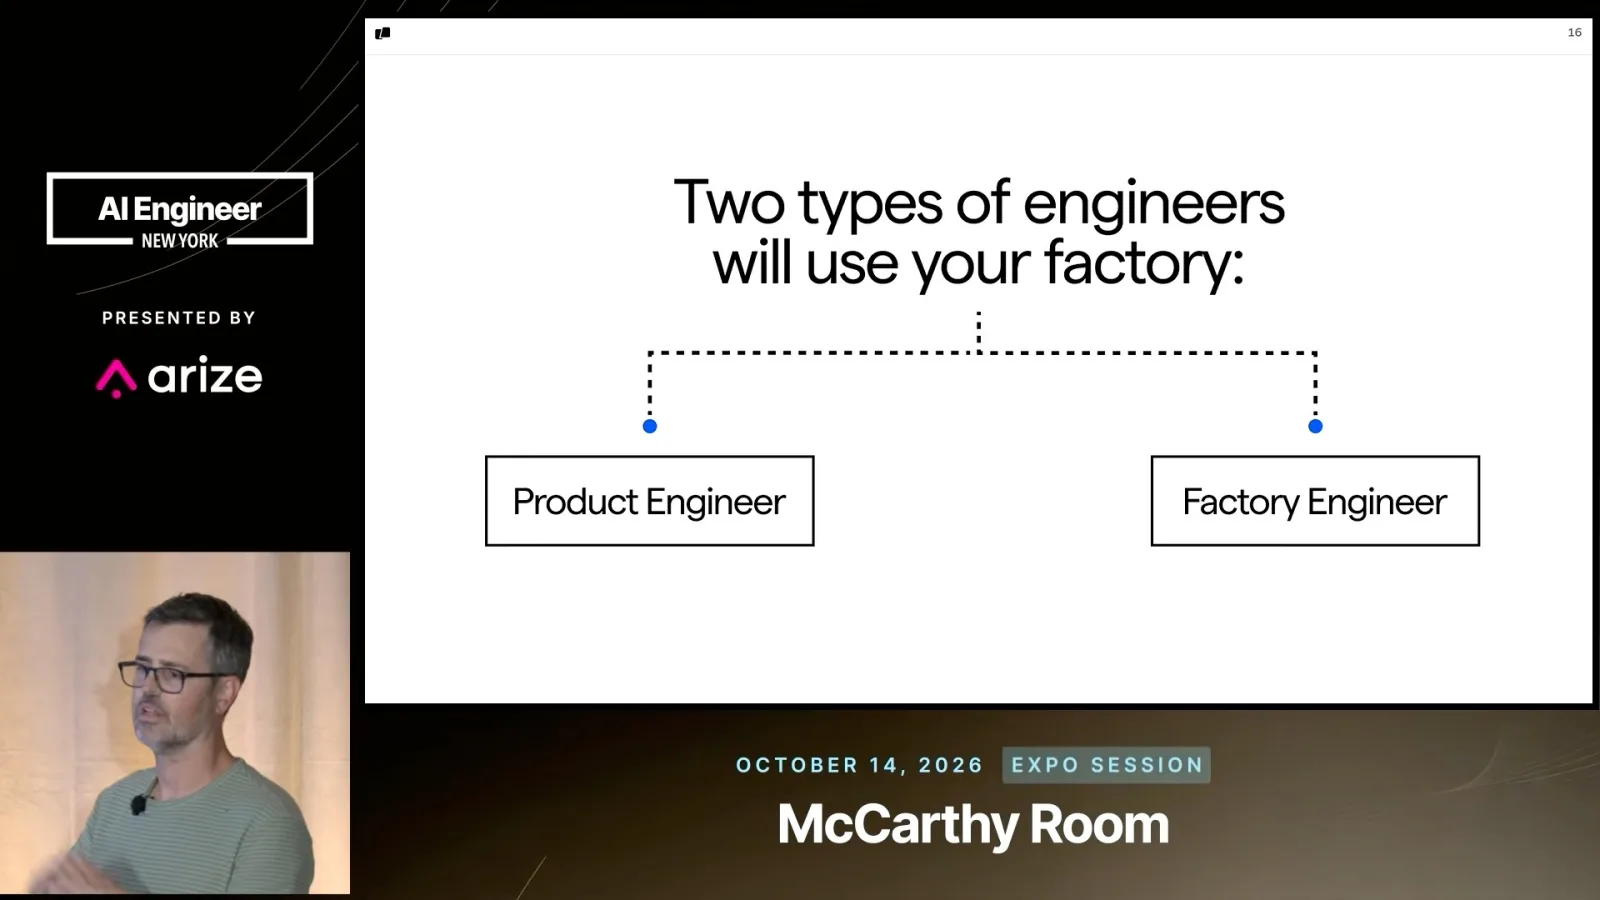
He distinguishes product engineering, where people use the factory to build features and fix bugs, from factory engineering: improving skills, context and model choices so the system itself performs better. Platform teams or product engineers can do that work.
A demonstration of runs and self-improvement
Warp’s platform collects runs and scores recurring failures, which agents use to propose configuration changes.
In a Warp Factories demonstration, Lloyd shows a manager's view of productivity, automation, cycle time and spending. The system records agent runs, conversations and artifacts, which become material for examining and improving the process.
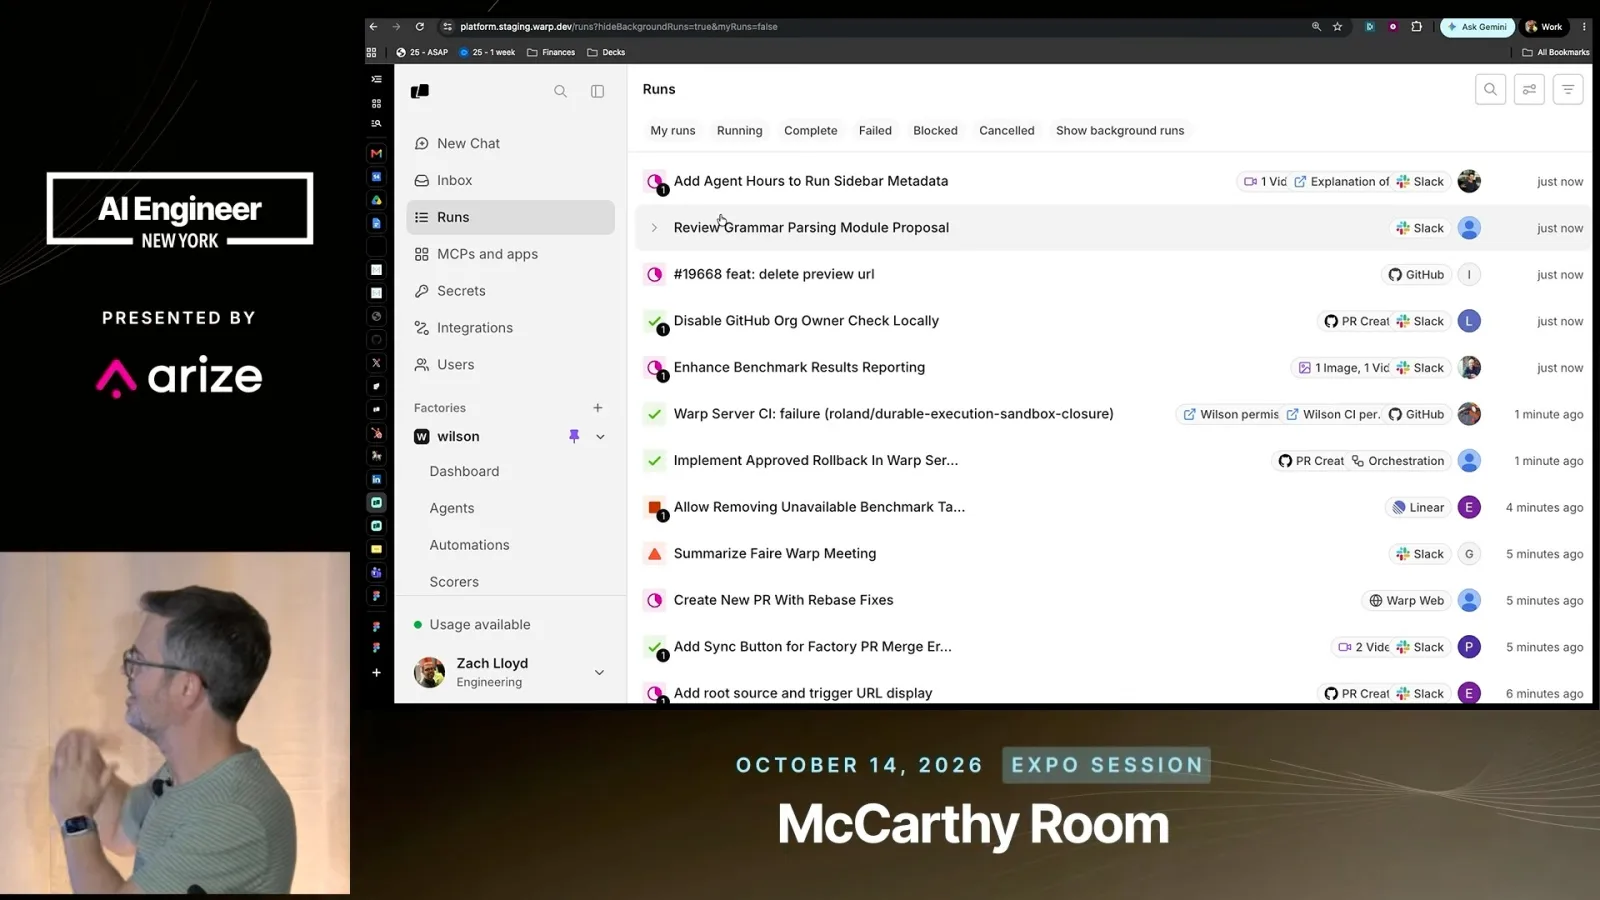
Engineers can submit work from tools they already use, such as Slack, Linear or GitHub. Lloyd says the factory collects the work centrally while preserving its context. An orchestrator routes work through steps such as triage, specifications, implementation and review.
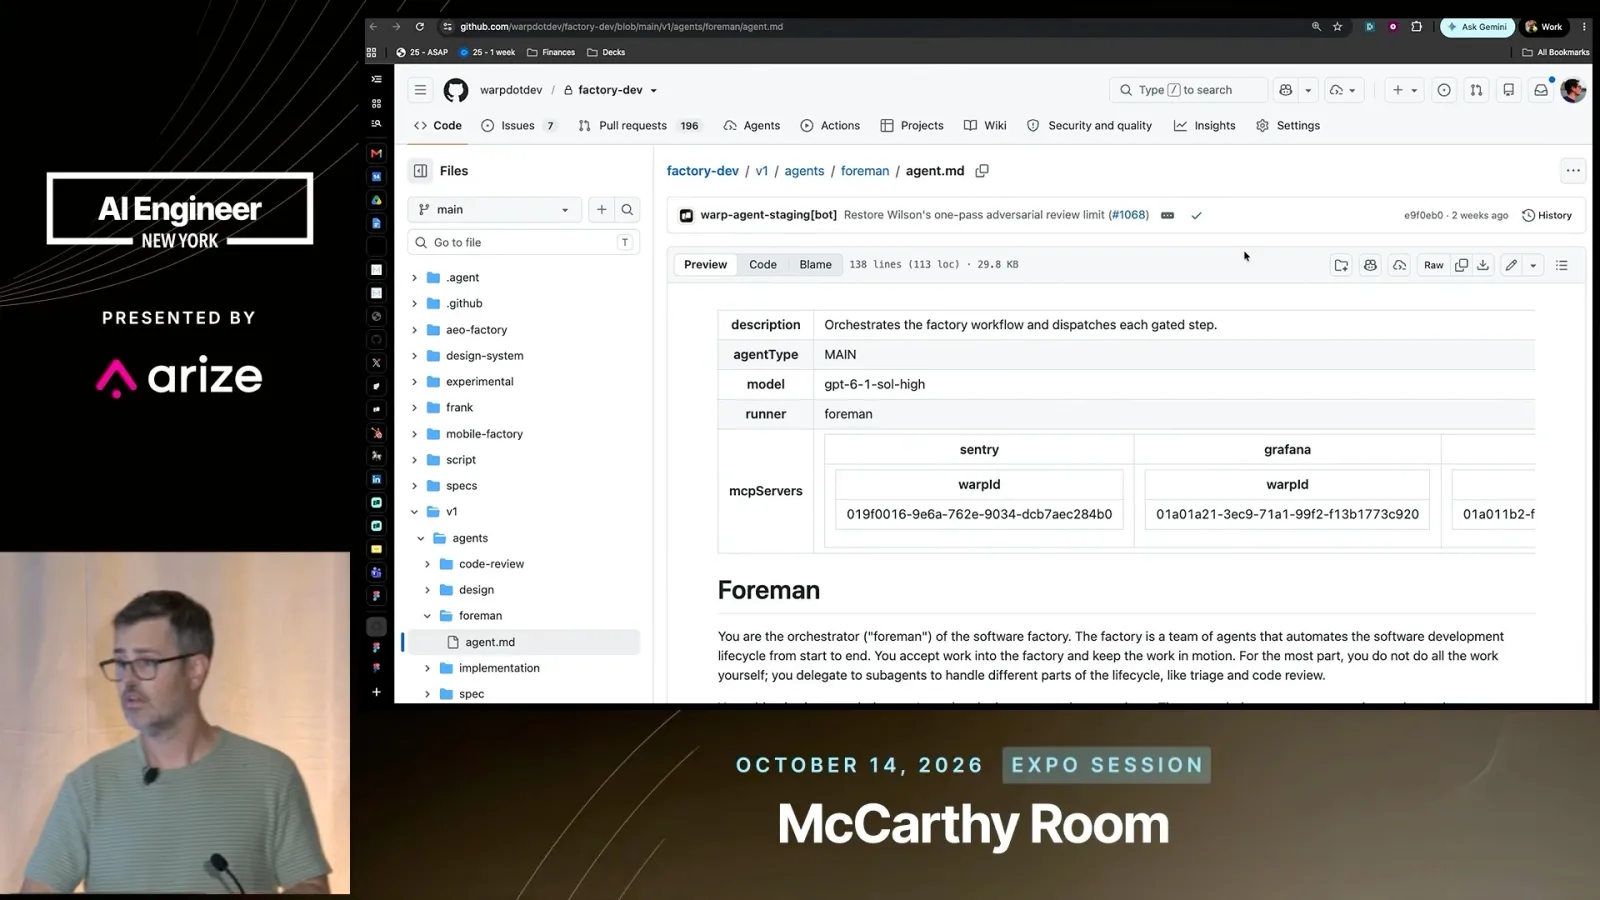
The factory's repository contains agent definitions, automations, benchmarks, execution settings, skills and webhooks. Lloyd says versioning this definition makes the system itself available for testing and automation.
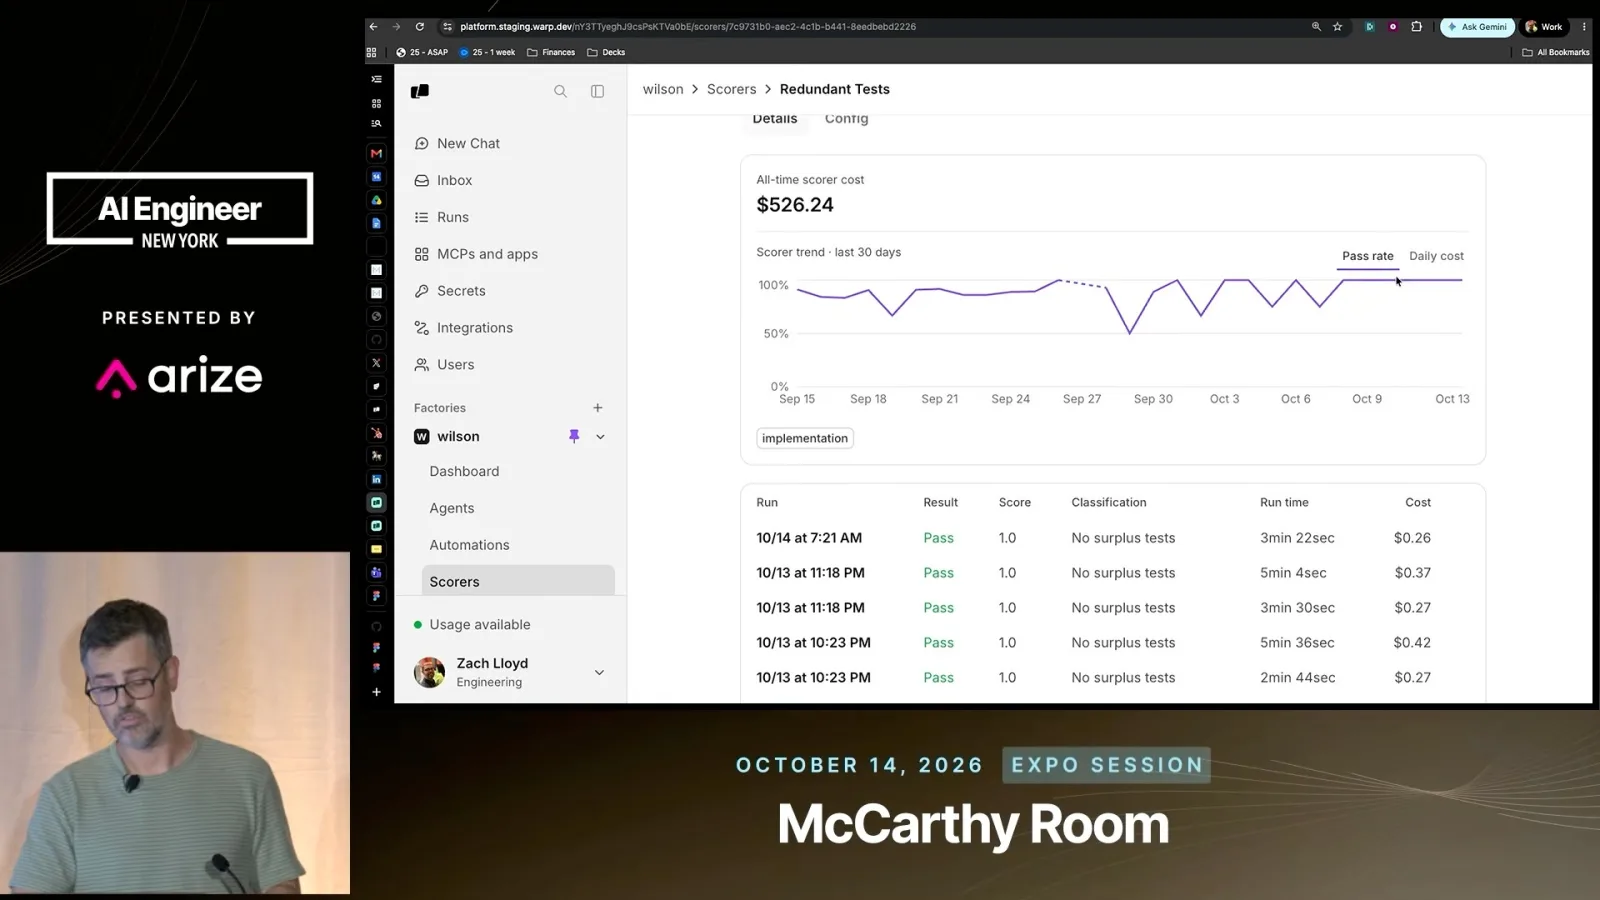
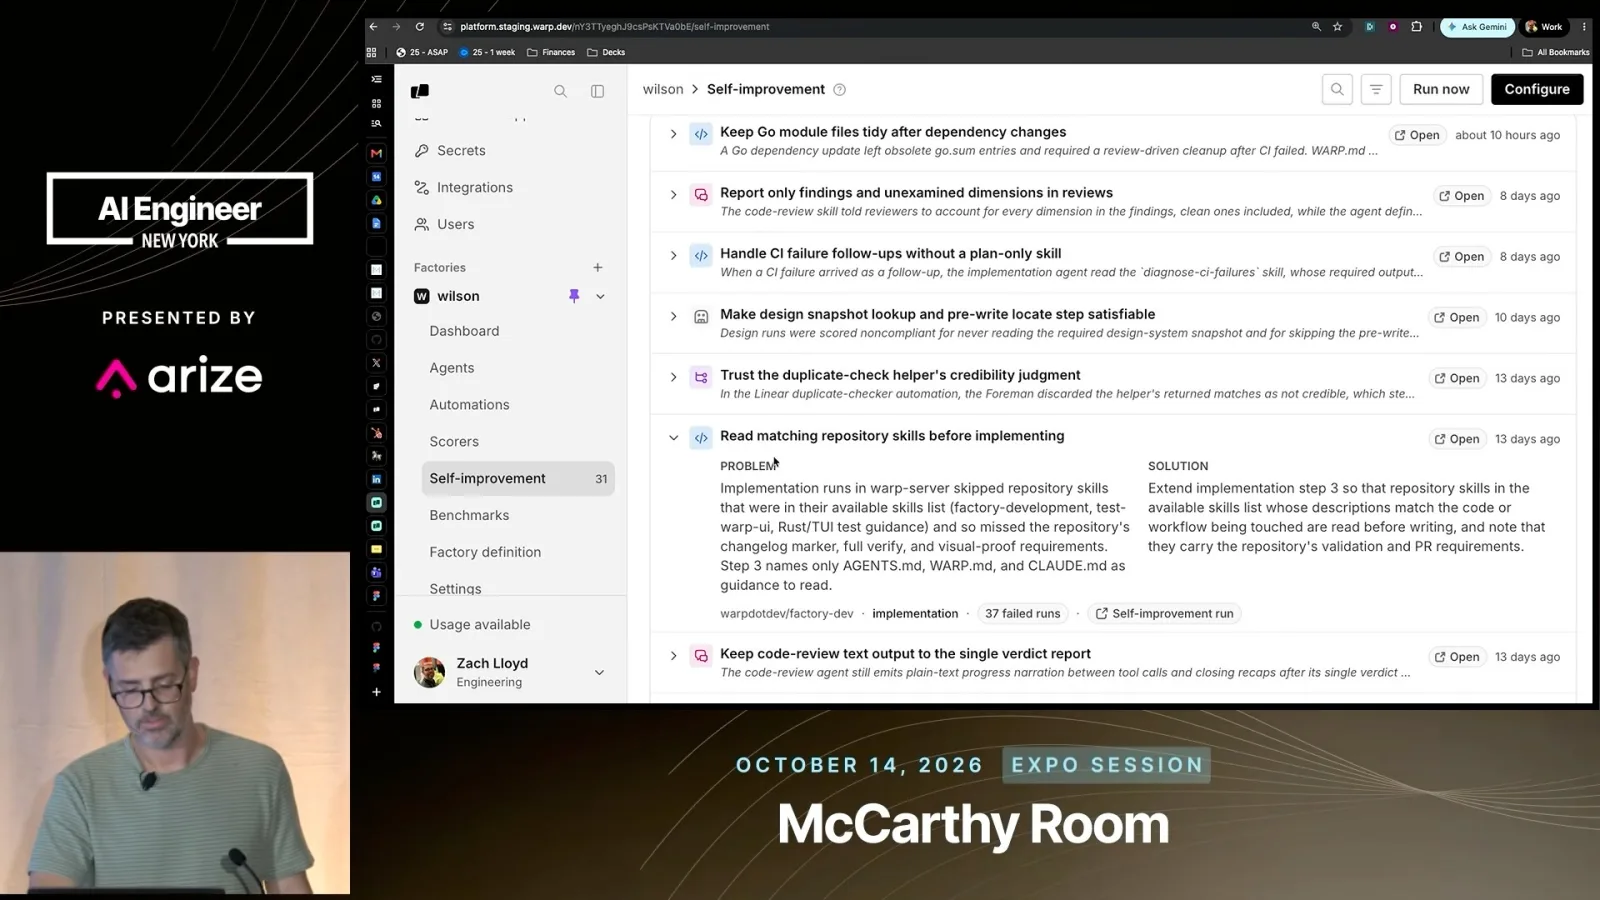
Warp uses scoring agents to inspect completed runs, including a check for redundant tests. Lloyd describes this as an online evaluation: identified failures become candidates for improving the process. The scoring shown in the demo relies on a language model as judge.
A self-improvement loop aggregates recurring failures, looks for patterns and proposes changes to the factory definition. In one example, the system reports 37 failures associated with agents not reading relevant skills and proposes a pull request to address the pattern.
Compare model cost and quality on internal tasks
Lloyd demonstrates replaying prior tasks and comparing model-judged results.
Lloyd recommends building a benchmark from representative past tasks, then replaying them with different model configurations. Rather than relying only on public leaderboards, a team can compare quality and cost for its own code and workflows.
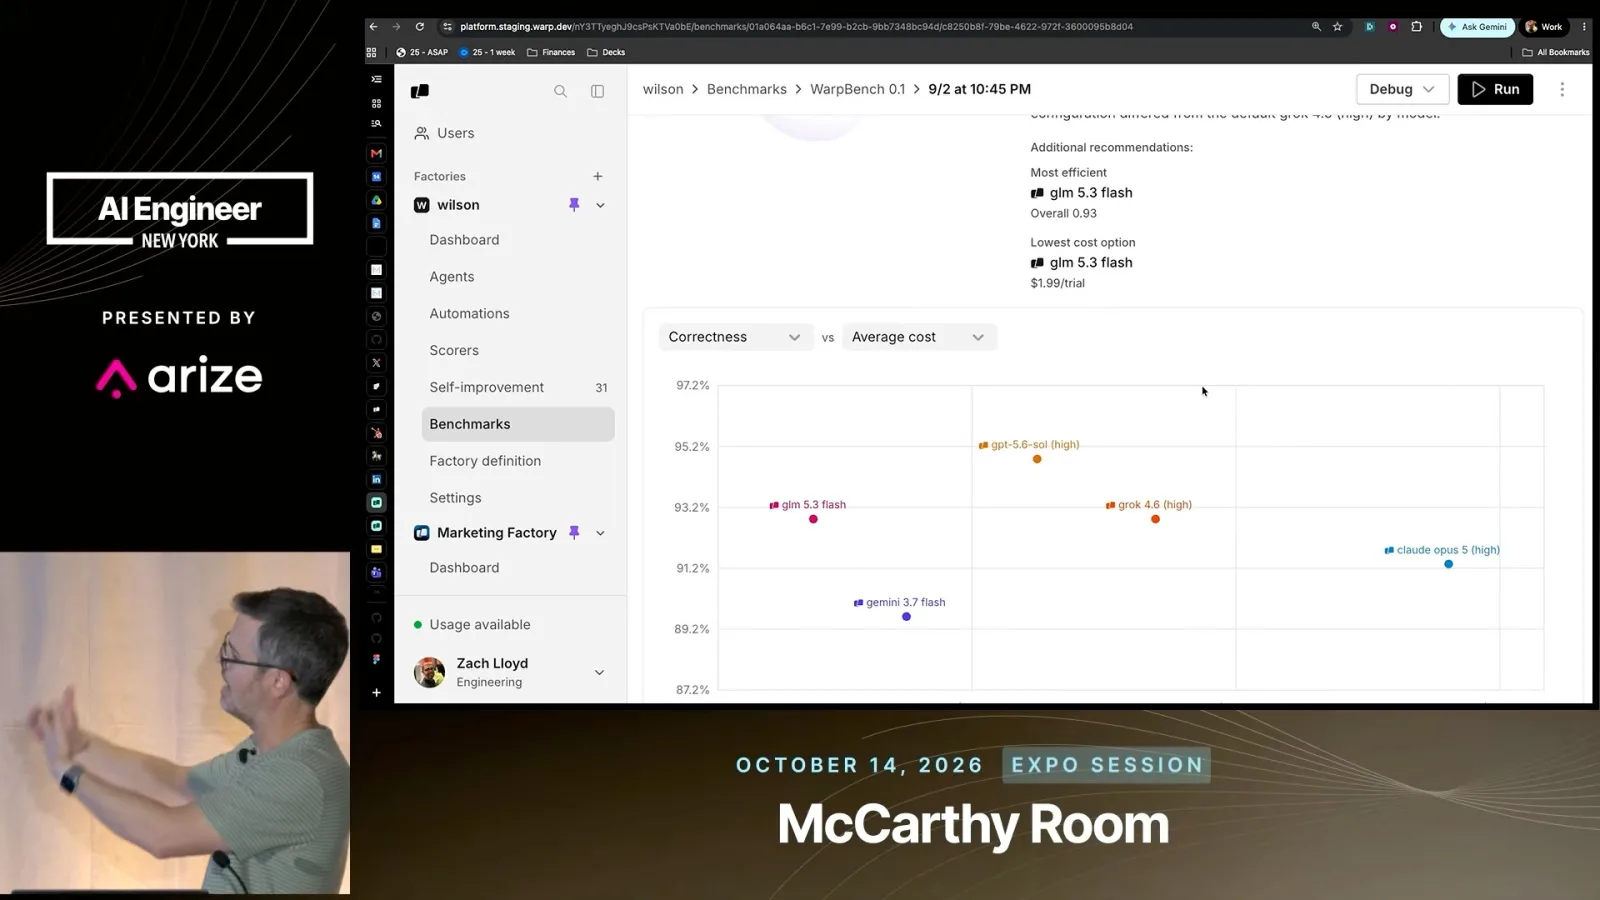
In his example, GLM 5.3 Flash scores about 93% at roughly $2, while GPT 5.6 Sol scores around 95% at roughly three times the cost. These are scores on the displayed internal task set, not a general comparison; Lloyd later explains they use a model as judge.
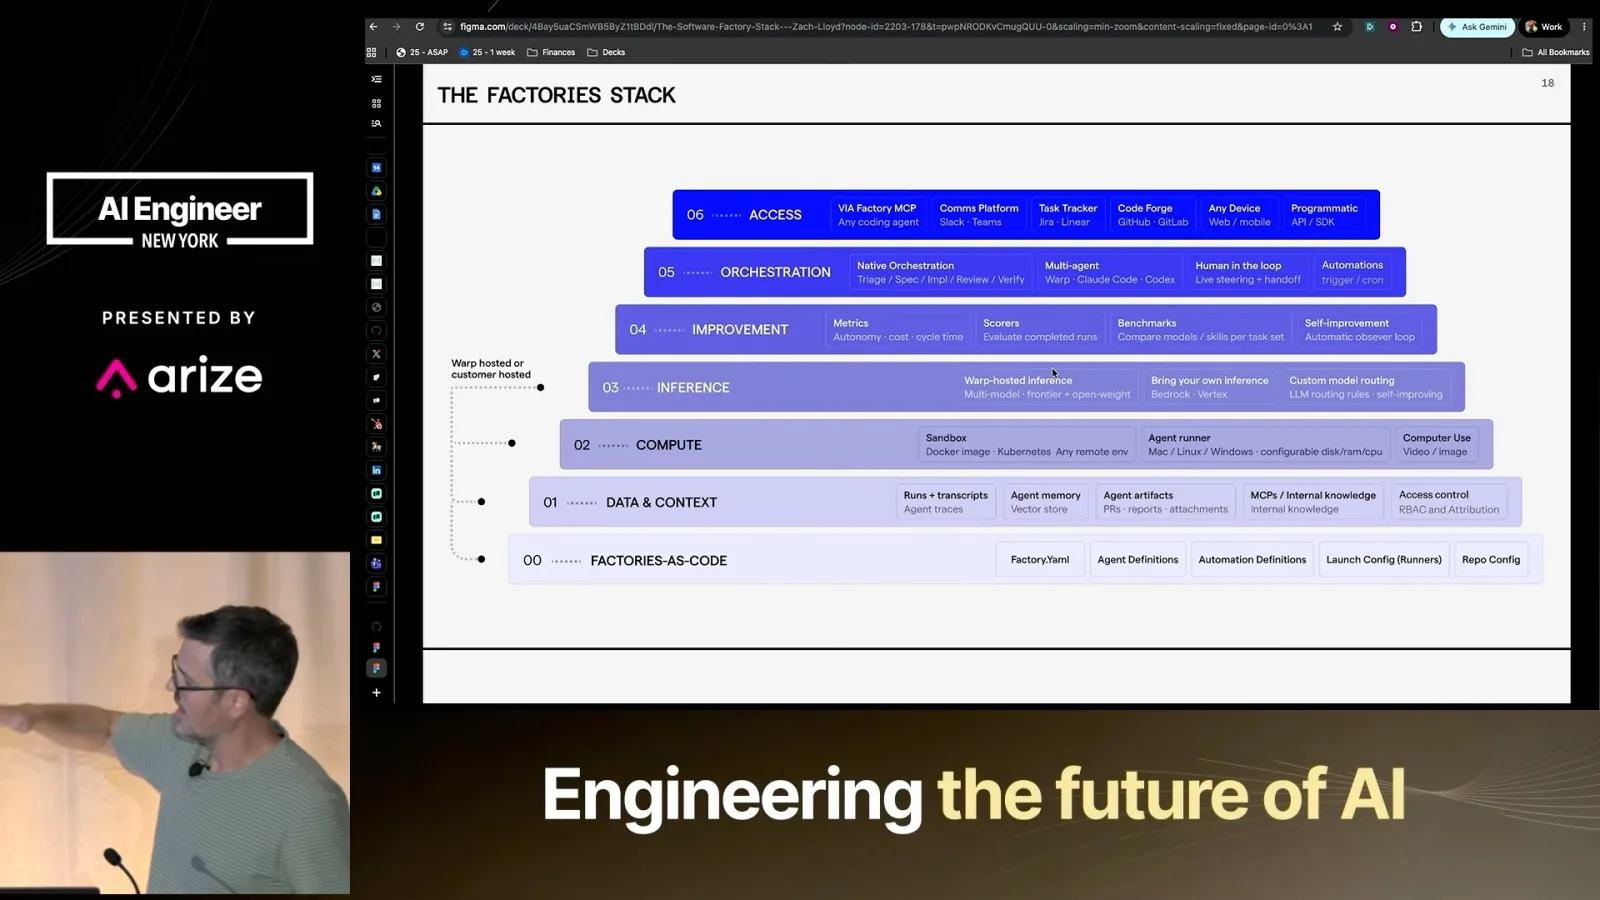
Lloyd summarizes the stack as factory definitions in code, data and context, sandboxed compute, flexible inference, measurement and improvement, orchestration and access through existing tools.
Verification, cost and benchmark questions
He answers questions on specifications, cost accounting, benchmark curation, judging and product availability.
Asked about verification, Lloyd recommends specifications that changes can be checked against and computer-use verification that produces evidence from the user's perspective. He suggests these can reduce the burden of reviewing a pile of generated pull requests.
On budget planning, he suggests measuring cost per pull request and separating the share spent on scoring and benchmarking, then estimating project costs. His main recommendation is to build a process that can be measured and improved.
For benchmark curation, Lloyd recommends starting with a hand-picked representative mix of small, medium and hard tasks. A factory with stored sessions can also suggest past runs to include. He says the demonstrated correctness chart uses an LLM judge; human grading would also make sense but was not yet added.
Asked whether Warp Factories is open source, Lloyd says it is not, though it accepts existing tools and is not restricted to enterprises. He thinks the platform is most useful for teams and may be excessive for an individual.
같은 채널의 다른 글
 19:41EN
 AI Engineer· 2026년 11월 9일A high-reliability automation starts by routing the hard cases awayMatthew Jewkes · Standard CyberneticsMatthew Jewkes describes separating critical errors, ambiguous decisions and unusual exceptions in a biopharma indexing workflow.
 27:35ENAI Engineer· 2026년 11월 9일Uber traded an always-green trunk for faster AI-scale mergesPreetam Dwivedi, Manjari Akella · UberIts merge queue now relaxes some conflicts and validates the combined state after landing, with a verified-good fallback.
 15:25ENAI Engineer· 2026년 11월 9일Hassan and Omar El Mghari: When an AI financial forecast is right for the wrong reasonsHassan El Mghari, Omar El Mghari · Together AIA Costco membership-fee model passed basic checks and landed close to reported results, but an audit uncovered offsetting assumptions.
 14:38ENAI Engineer· 2026년 11월 9일Jemima Abu: Give coding agents accessibility rules from the startJemima Abu · CAISA product engineer shows how semantic HTML, reusable components and explicit agent skills can help teams build more usable interfaces.
 21:12ENAI Engineer· 2026년 11월 9일Tom Moor: Give coding agents the product context that code cannot showTom Moor · LinearLinear’s workflow carries customer requests, past decisions, review history and human feedback from intake through implementation and review.
 15:35ENAI Engineer· 2026년 11월 9일Mislav Ivanda: Choose an execution boundary before an agent frameworkMislav Ivanda · DaytonaThe Daytona engineer compares local approvals, embedded runtimes and sandboxed machines for running agent-generated code.