30초 요약
Matthew Berman explains DeepSeek-OCR’s encoder, decoder and reported reconstruction results, then discusses ideas for image-based language-model input. The paper tests a limited OCR benchmark; the claimed expansion of other models’ context windows is an extrapolation. The video includes a Dell Technologies sponsorship.
- 1Text as a visual representationThe proposed compression ratio compares tokenized reference text with the encoder’s vision tokens.
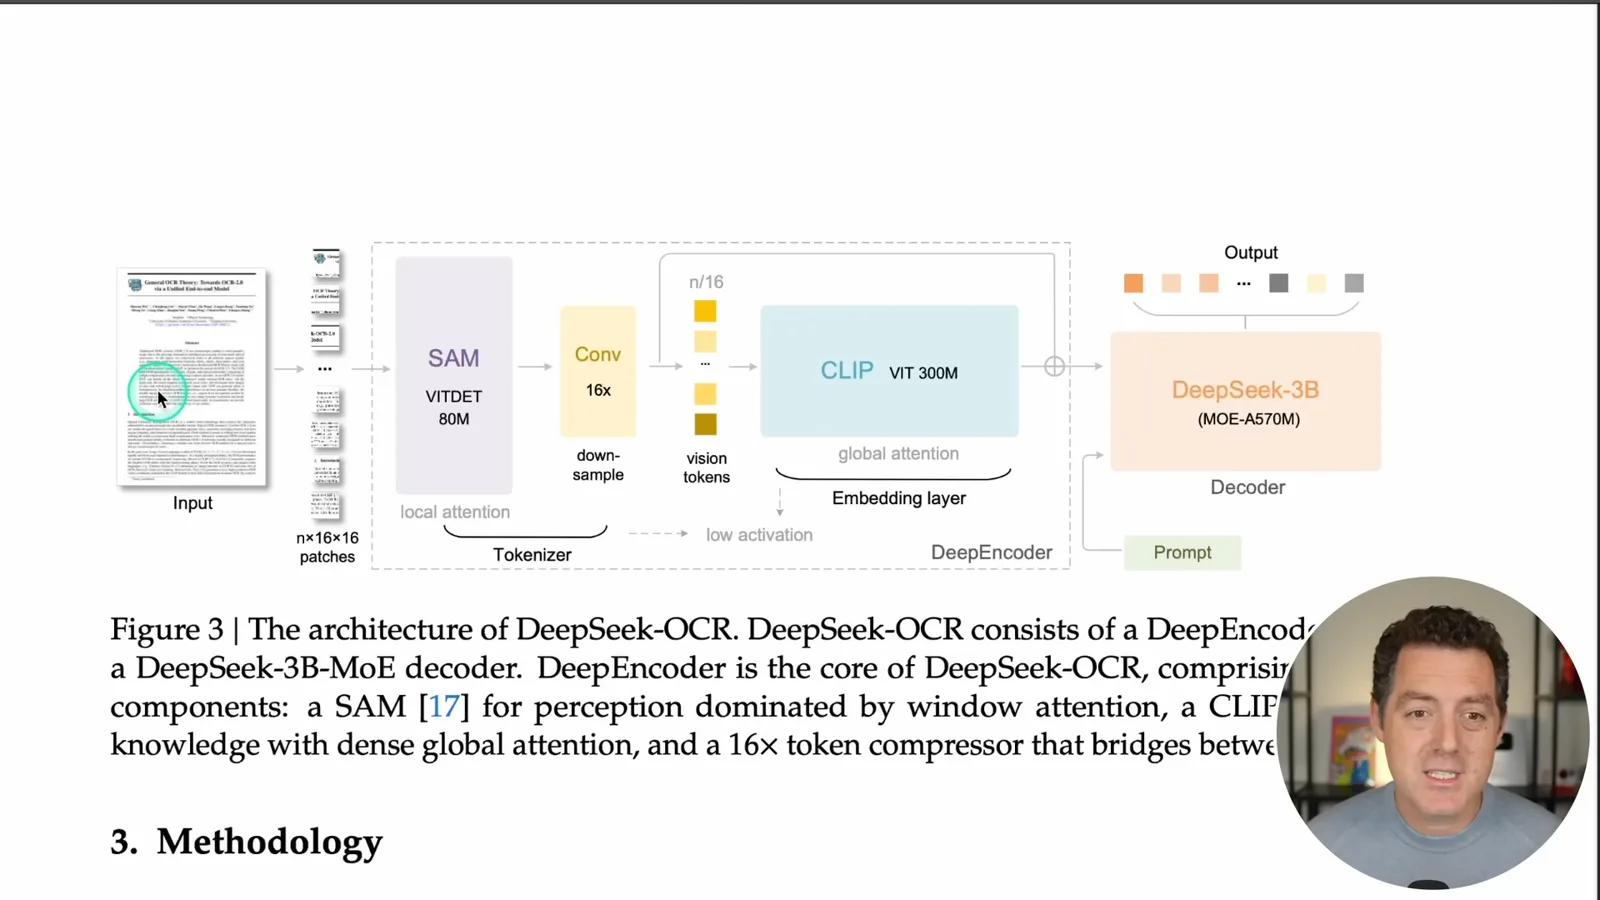
- 2Encoder and decoderDeepEncoder compresses image features before a mixture-of-experts decoder reconstructs text.
- 3An accuracy trade-offThe authors’ OCR precision falls as the measured compression ratio rises in their Fox benchmark experiment.
- 4A broader research questionKarpathy speculates about image-based inputs for language models; the paper does not establish those wider benefits.
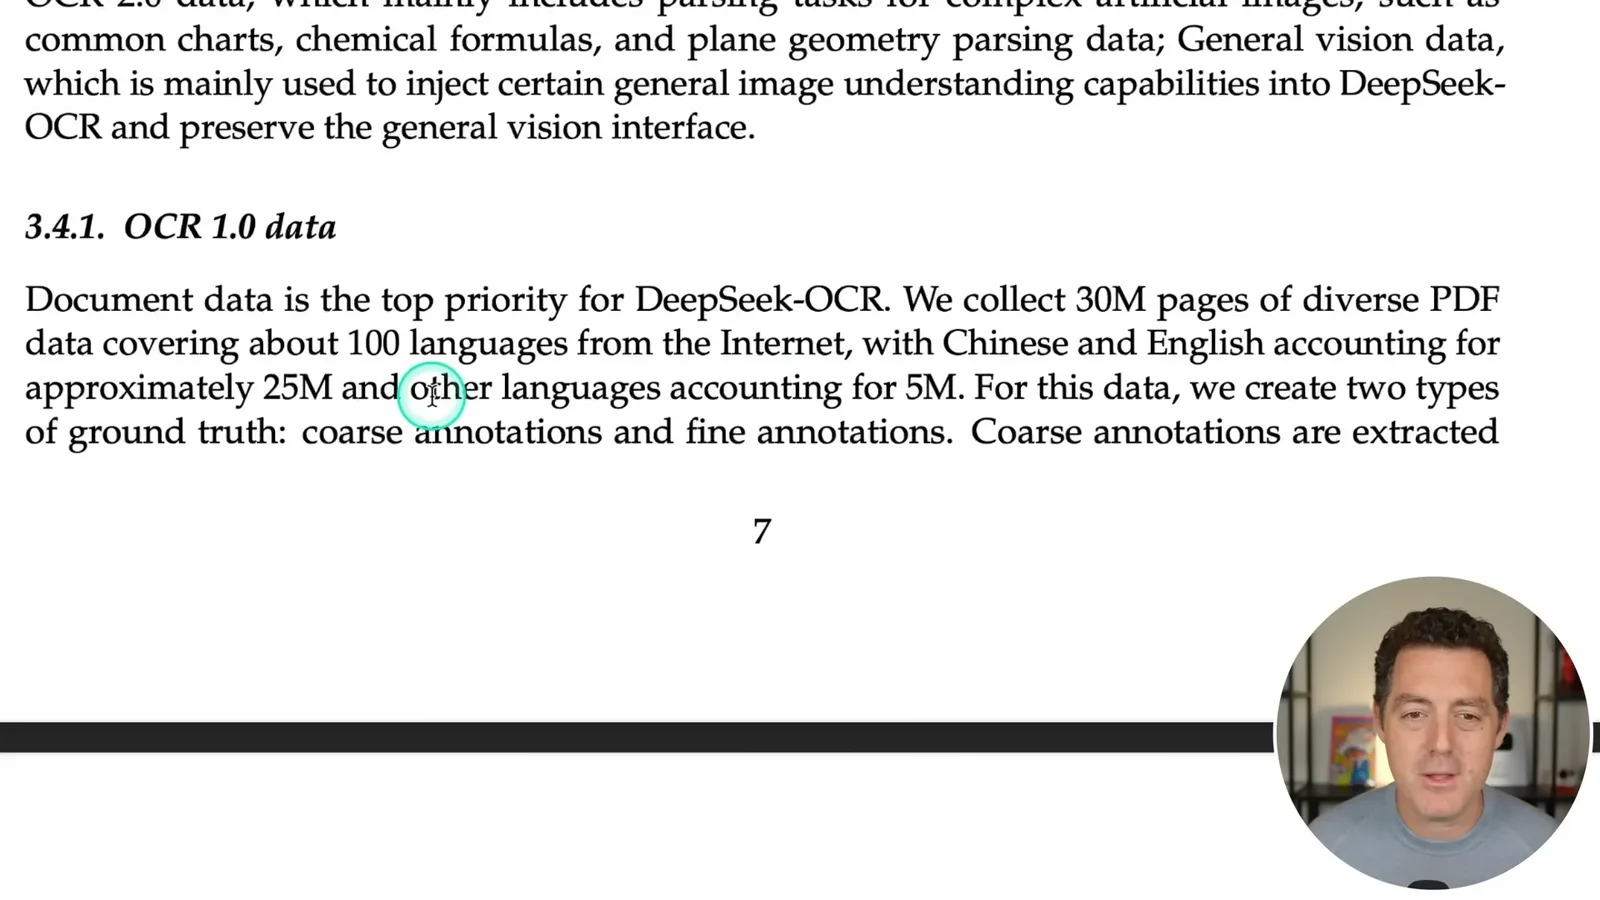
- 5Training dataThe authors report collecting 30 million PDF pages, mostly in Chinese and English.
핵심 정리
- DeepSeek-OCR reconstructs text from document images using a compressed visual representation.
- The paper reports approximately 97% OCR precision below 10× compression on a specific 100-page English test set.
- Higher compression produced lower reported precision, including around 60% near 20× in the experiment.
- Token ratios do not demonstrate a tenfold increase in usable context or establish latency and total-compute savings.
- The video includes a Dell Technologies-sponsored hardware segment.
챕터별로 다듬은 전문 읽기
Why visual compression interests Berman
Berman introduces DeepSeek-OCR and the concept of representing document text with fewer vision tokens. The result is a proof of concept, not a proven extension of every model’s context.
DeepSeek-OCR is a vision-language model for optical character recognition: extracting text from images. What interests me is not just reading a document, but the researchers' proposal to represent text visually with fewer input tokens. Their October 2025 paper treats this as an initial proof of concept, not a demonstrated tenfold expansion of existing chat models' usable context.
The intuition is that a page image can carry text whose conventional tokenized form would be longer than the vision-token representation of that image. The researchers report roughly 97% OCR decoding precision at compression ratios below 10 to 1 in their experiment. That ratio compares ground-truth text tokens with the encoder's vision tokens; it is not a lossless compression guarantee.
Context windows limit how much input a language model can consider at once. Longer sequences can be costly, and conventional dense attention has a quadratic sequence-length component, although total cost depends on architecture and inference method. I see a possible benefit in representing documents more compactly, but the OCR experiment does not by itself prove that any particular model can use ten times more context effectively.
How DeepSeek-OCR works
The system encodes image patches and decodes a compressed representation into text. Its internal feature compression is distinct from the measured text-to-vision ratio.
The [paper](https://arxiv.org/abs/2510.18234) frames OCR as a test of encoding text visually and reconstructing it. Rendering very small text can make it unreadable after resizing, so the amount packed into an image has a limit. The test assesses reconstruction of documents, rather than performance on long-context question answering or other downstream tasks.
The architecture divides an input image into patches and uses DeepEncoder, which combines a SAM-based local-attention encoder, a convolutional 16-fold token compressor and a CLIP-based global-attention encoder. The compressed representation goes to a DeepSeek 3B mixture-of-experts decoder, with approximately 570 million active parameters, to produce text. The internal 16-fold compression of vision tokens is distinct from the measured text-to-vision token ratio.
Reconstruction results and limits
Berman extrapolates to longer context windows and reviews the authors’ OCR figures. The experiment used a limited English document set and did not measure the proposed end-to-end integration.
I imagine a future system using this idea to fit far more information into the same token budget. In the video I suggest that a one- or two-million-token model might effectively handle ten or twenty million tokens with little added latency. That is an extrapolation: the paper does not demonstrate that integration, its end-to-end accuracy, latency or total compute costs in those models.
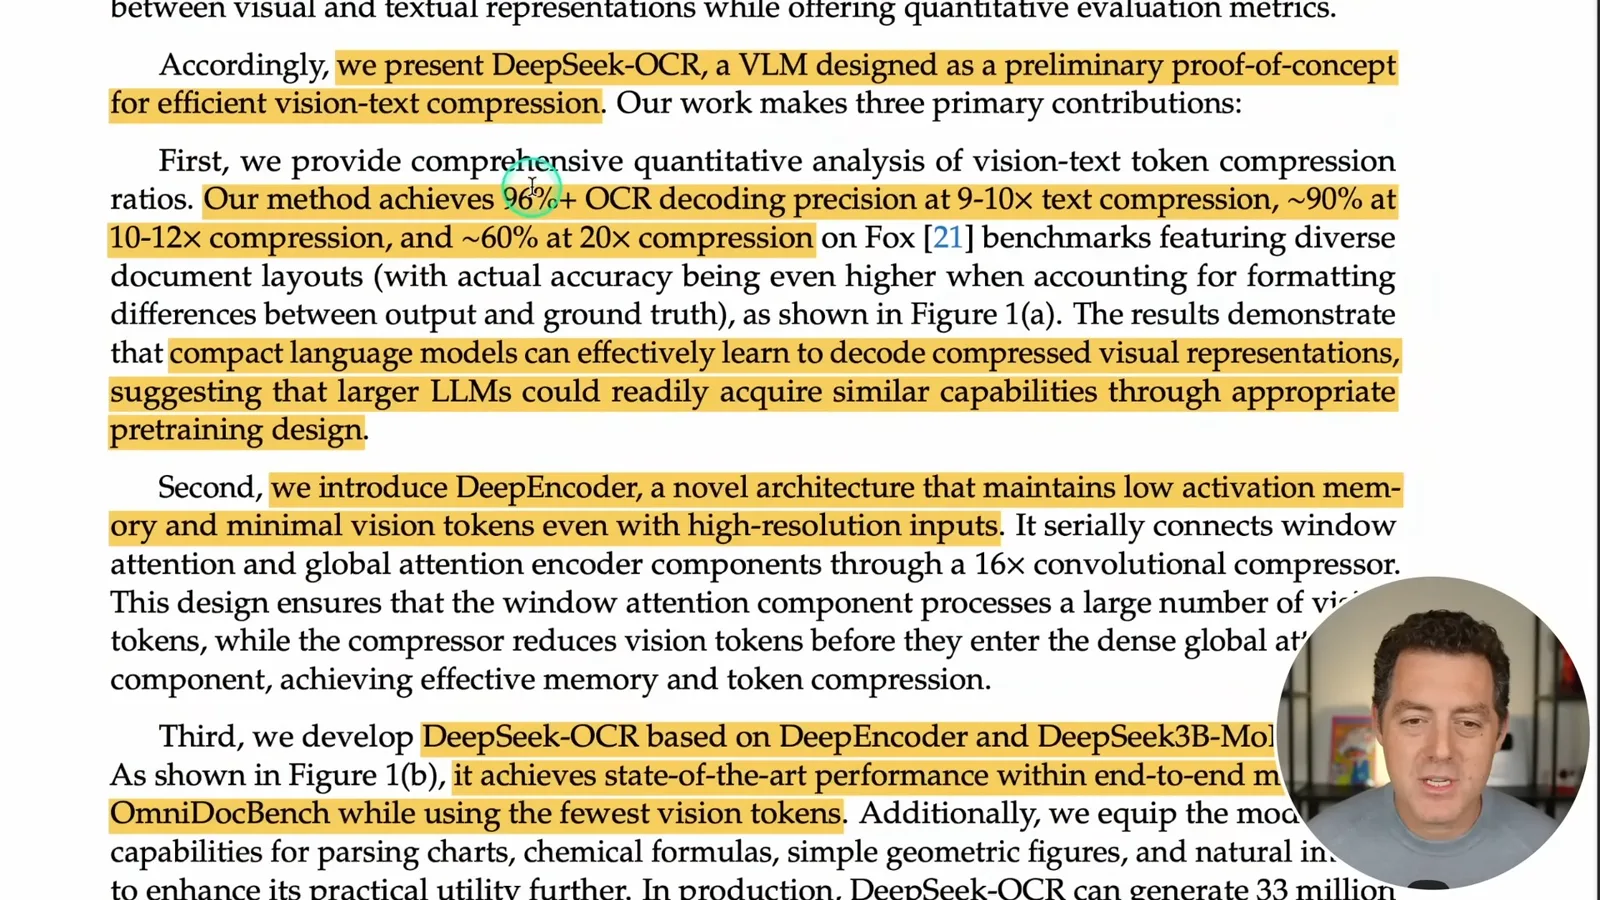
The authors report over 96% OCR decoding precision at roughly 9–10 times compression, about 90% at 10–12 times and around 60% near 20 times. Their compression experiment used 100 English Fox benchmark pages containing 600–1,300 text tokens, with images resized to 512 or 640 pixels. The figures are specific to this dataset, tokenizer, model and metric, and show that more compression can lose information.
The video includes a Dell Technologies-sponsored segment presenting Dell Pro Max laptops with NVIDIA RTX Pro Blackwell hardware for local AI workloads. The paper's compression findings do not depend on that sponsorship, and the device specifications and product availability described in the video are historical.
Reactions and training data
Berman discusses Karpathy’s image-input ideas and another speculative compression example. He closes with the authors’ description of the training data.
Andrej Karpathy reacted positively to the OCR model and asked a broader question: could rendering text as images make a better input for language models? He suggested potential advantages such as denser representation, formatting and images in one stream, bidirectional input processing and less dependence on a text tokenizer at input. These are research ideas and possible trade-offs, not results established by the OCR experiment.
A tokenizer converts text into units a model can process; the number of tokens per word varies with the text and tokenizer. Karpathy also mentioned the temptation to try an image-input version of NanoChat. I find the possibility exciting, but visual processing has its own computational costs and compression errors, so a shorter token sequence alone does not establish an end-to-end speedup.
I also mention Brian Roemmele's suggestion of compressing an encyclopedia into one high-resolution image. That is an illustrative claim, not an experiment in the paper showing faithful reconstruction or retrieval of an entire encyclopedia. Resolution, layout and the information lost under compression would all matter.
For training data, the authors say they collected 30 million PDF pages across about 100 languages: roughly 25 million in Chinese and English and 5 million in other languages. They show document images alongside layout annotations. I am excited by the potential for more efficient document processing, while the practical long-context applications still need direct testing.
같은 채널의 다른 글
 34:21EN
 Matthew Berman· 2026년 10월 27일Matthew Berman Examines Anthropic’s IPO Filing, AI Growth and GovernanceMatthew Berman, Sam Altman · Forward FutureThe presenter reviews the S-1’s financial metrics, compute strategy and voting structure while questioning the tension between rapid AI development and safety.
 0:26ENMatthew Berman· 2026년 10월 25일Sam Altman on Human Values and Problem-Solving in an AI WorldSam Altman · OpenAIIn a short interview excerpt, Altman considers the enjoyment of solving hard problems and the human role in interpreting results.
 0:36ENMatthew Berman· 2026년 10월 25일Kimi K3.1 and a Rubik’s Cube Solver DemonstrationMatthew Berman · Forward FutureMatthew Berman shows a scrambled virtual cube being solved and gives the Kimi K3.1 test a favorable assessment.
 0:21ENMatthew Berman· 2026년 10월 24일An AI-Generated Kimi Benchmark Chart Used Invented ScoresMatthew Berman · Forward FutureMatthew Berman asks for a graph of Kimi K3.1 Pro benchmarks, then discovers that the displayed figures are illustrative placeholders.
 25:50ENMatthew Berman· 2026년 10월 24일Kimi K3.1 Pro Tested: Strong 3D Demos, Uneven Results and Competitive PricingMatthew Berman · Forward FutureMatthew Berman tests the open-weight model on coding, 3D rendering and visual explanations, then compares benchmark results and prices.
 32:20ENMatthew Berman· 2026년 10월 23일Who Is Local AI For? The Costs, Trade-offs and a Hybrid FutureMatthew Berman · Forward FutureMatthew Berman weighs data control and independence against hardware cost, setup complexity and inference speed.