30초 요약
In June 2023, Matthew Berman reviews Falcon 40B’s then-leading Open LLM Leaderboard position and demonstrates a hosted GPTQ setup. A Chinese translation appears reasonable, but the simple Python answer includes an extra zero and the run is too slow for the broader test he planned. The video’s QLoRA terminology and pretraining extrapolation need qualification.
- 1A historical leaderboard leaderFalcon 40B and its instruction-tuned version ranked highly on the 2023 Open LLM Leaderboard.
- 2Fine-tuning is not pretrainingQLoRA reduces fine-tuning memory requirements; it does not establish a few-day reproduction of Falcon pretraining.
- 3The demonstrated checkpointThe linked model is TheBloke’s GPTQ-quantized Falcon 40B Instruct, not a QLoRA checkpoint.
- 4Quality versus speedBerman liked the visible outputs but stopped testing because generation was slow; the shown Python loop also prints an extra zero.
핵심 정리
- A 2023 leaderboard ranking reflects its selected benchmarks and does not measure latency in every deployment.
- Falcon 40B’s training used filtered web data and other sources, with data quality and scale both relevant.
- The demonstrated checkpoint is GPTQ-quantized; QLoRA is a separate fine-tuning technique.
- Berman’s hosted test yielded a plausible translation but slow output; the visible Python code also included an extra zero.
- Apache 2.0 licensing permits commercial use under its terms, while hosted GPU usage can have costs.
챕터별로 다듬은 전문 읽기
Falcon 40B and its training
Berman discusses the model’s 2023 ranking, dataset and training. The model’s license changed before the video was published.
In June 2023, I test Falcon 40B, a 40-billion-parameter model from the UAE's Technology Innovation Institute. Its base and instruction-tuned versions had appeared at the top of the Open LLM Leaderboard at the time. That ranking covers a particular set of evaluations and models, not every task, model or measure of usefulness.
The model card describes training Falcon 40B on one trillion tokens and highlights data filtering and deduplication. I discuss the developers' claims about using less training compute than some earlier models. Data quality is important, but my suggestion that it always outweighs dataset size is too broad to establish from these results alone.
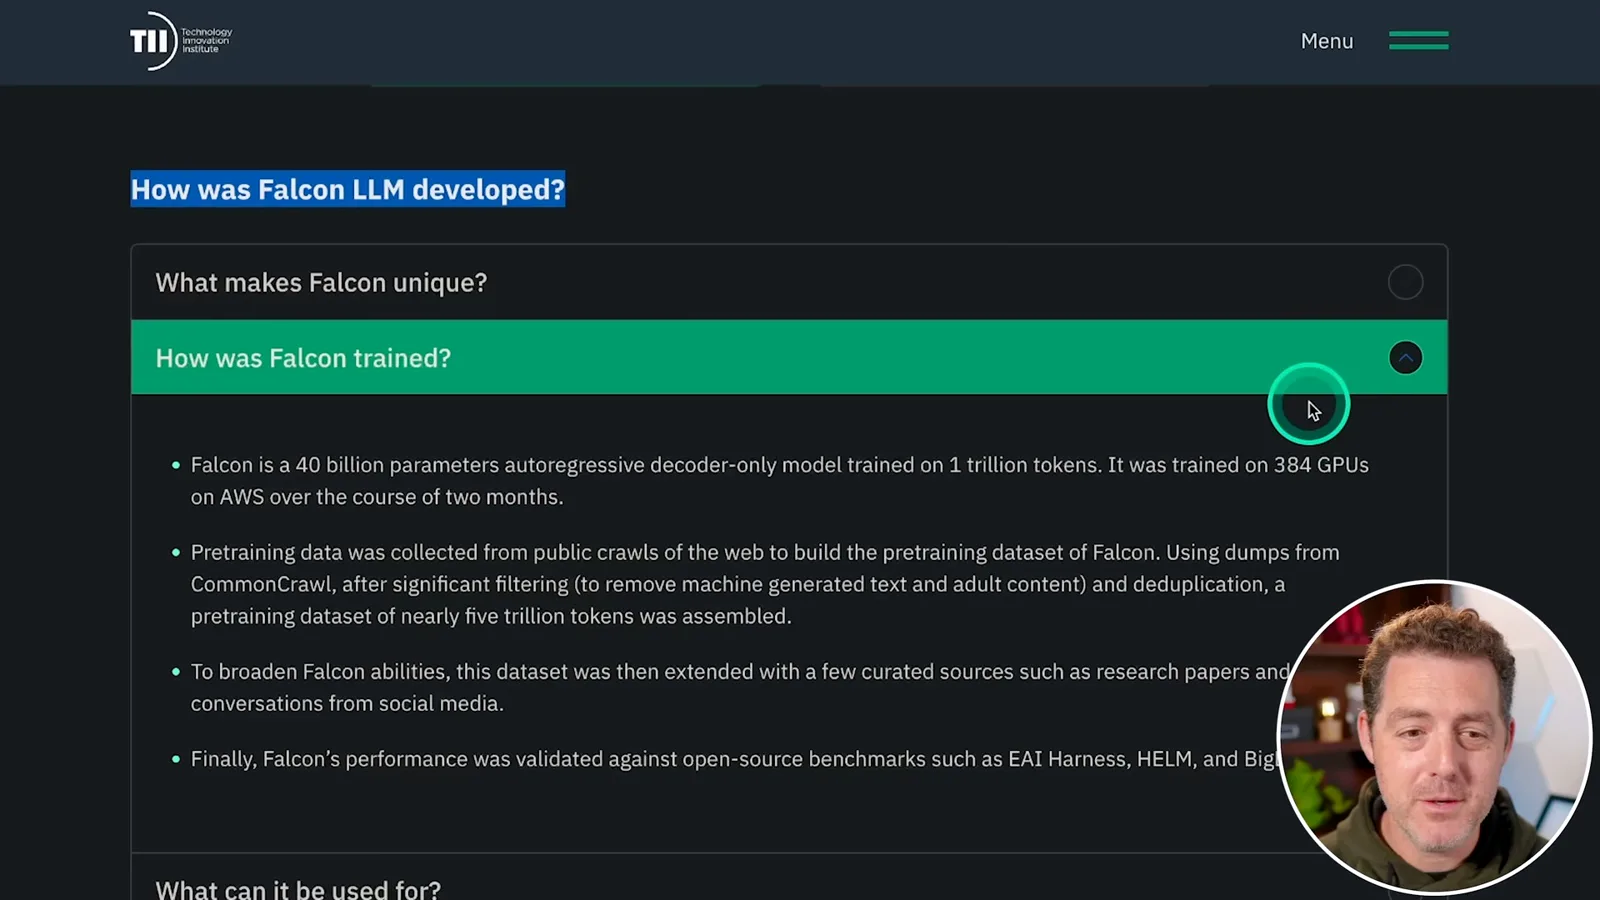
I describe training on hundreds of AWS GPUs and mention QLoRA as a way to make adaptation more memory-efficient. QLoRA is a fine-tuning method, not evidence that Falcon's original pretraining can be reproduced in a few days. The checkpoint I later demonstrate is labeled GPTQ, a different quantization method.
The training material included filtered web data and other curated sources. I discuss possible uses such as chat, translation and coding and note that the training data was primarily English with some other European languages. The model card cautions that performance is not uniform across languages and tasks.
I choose a hosted GPU because running the 40B model exceeds the resources available on my own computer. A smaller Falcon 7B model was also available, although what runs locally depends on memory, hardware and format rather than parameter count alone.
Before publishing, I add an update that Falcon's license had changed to Apache 2.0. The Falcon 40B and instruction-tuned model cards list that license; commercial use remains subject to its terms and the terms of any other components used.
A hosted GPTQ setup
He edits a RunPod template and loads an instruction-tuned checkpoint. The historical setup uses repository code that must be trusted.
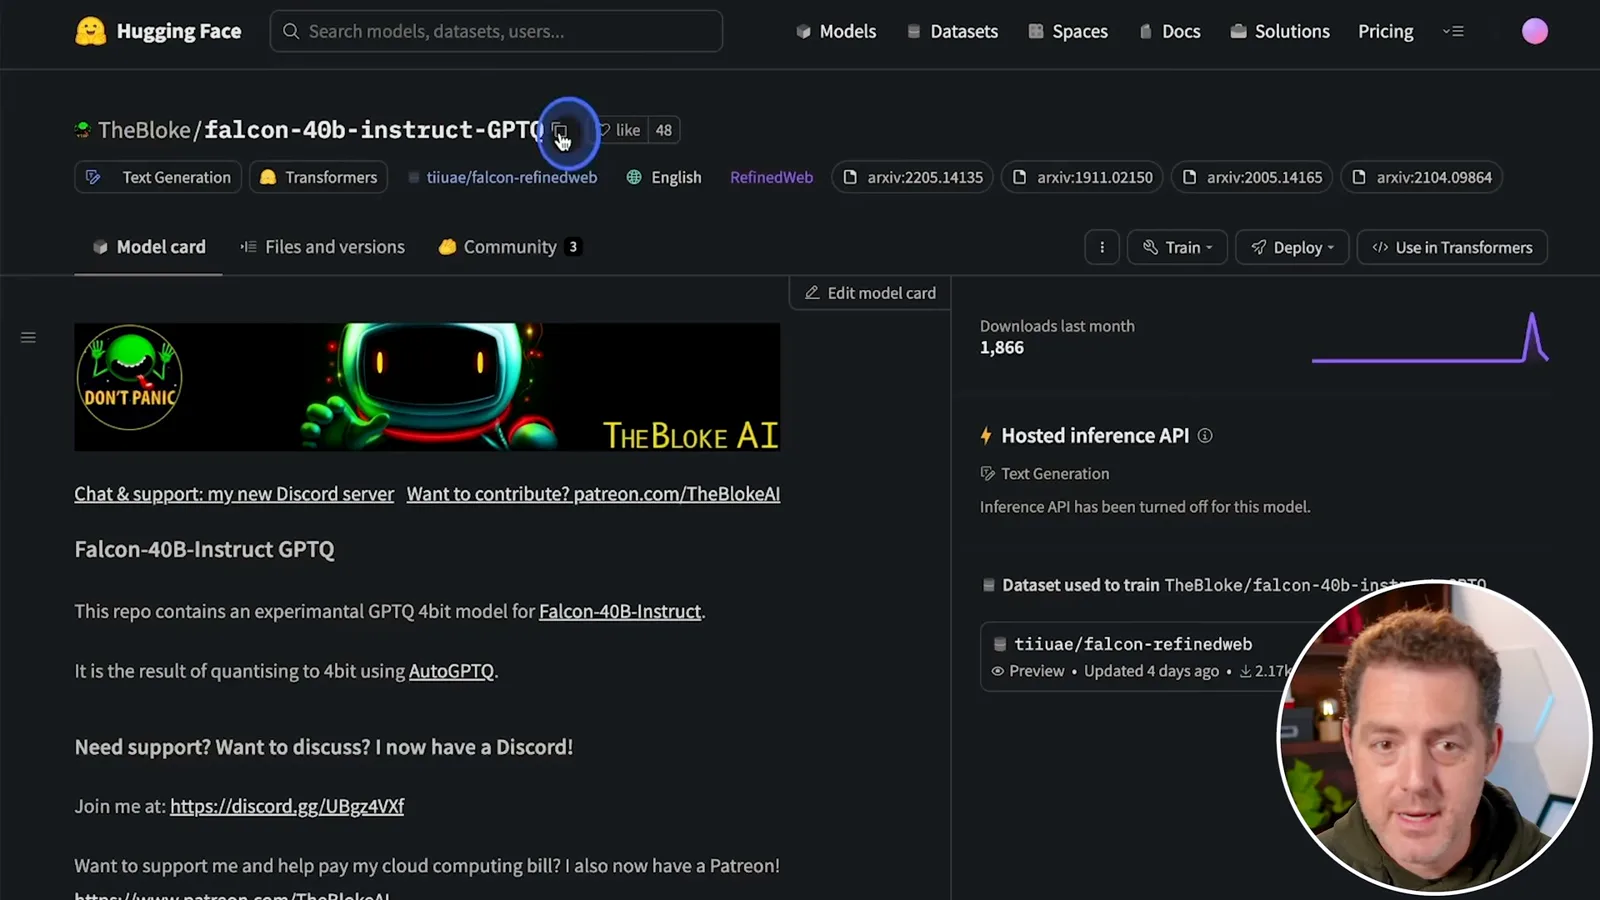
For the historical setup, I use a RunPod template and an RTX A6000 instance, open a web terminal, edit the text-generation-webui launch script and add AutoGPTQ and remote-code options. Enabling remote code permits code from the model repository to run, so the repository and its code need to be trusted and reviewed. Hosted GPU time may also incur charges.
After restarting the process, I open the web interface and download TheBloke's Falcon 40B Instruct GPTQ checkpoint. I call the variant QLoRA in the video, but the linked checkpoint is a GPTQ quantization; those terms are not interchangeable. The installation procedure and software versions are specific to this 2023 demonstration.
Translation, code and latency
A translation and simple coding prompt produce plausible visible output. Slow generation leads him to end the test early.
My first prompt asks for a Chinese translation of a sentence about wanting to learn more about AI. I paste the output into Google Translate and find that the translated meaning matches my original sentence. This is one informal back-translation, not a systematic evaluation of Chinese translation quality.
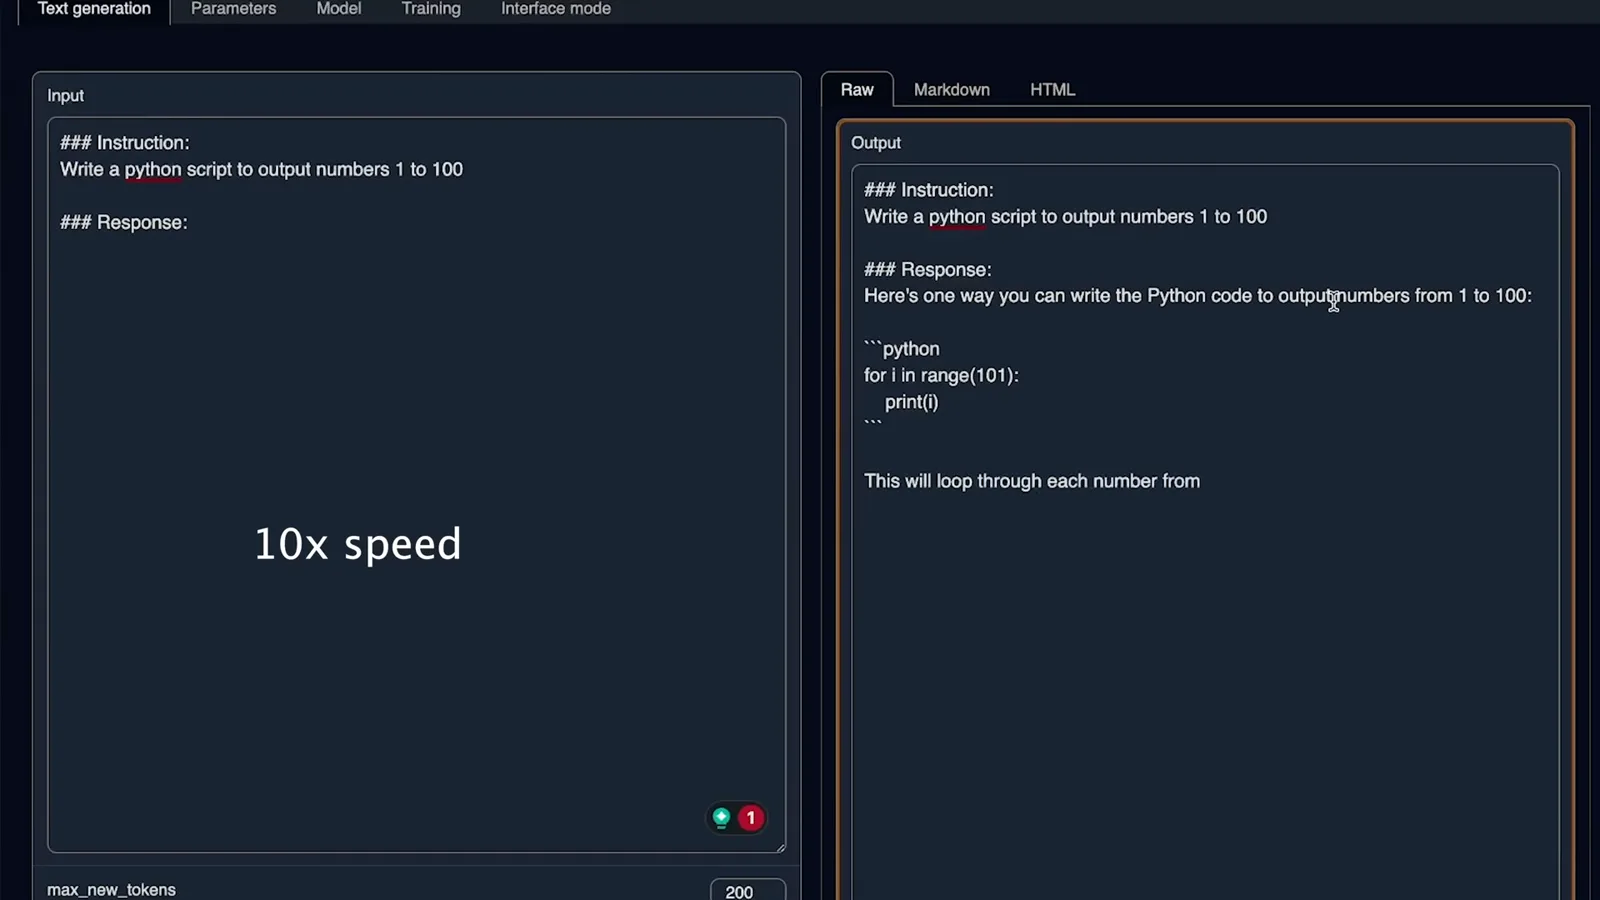
The practical problem in my setup is speed: the short translation took about a minute. I ask for a Python script to output the numbers 1 through 100 and wait while the answer appears. I say the visible code looks correct, but it uses range(101), which also outputs 0; the response does not exactly satisfy the prompt. The slow output prevents broader testing.
I explain that the leaderboard I am looking at measures quality on selected benchmarks rather than the latency of this particular deployment. A leading benchmark result and a frustrating user experience can therefore coexist. My single run does not prove that Falcon is universally the slowest model, or that quantization alone caused the slowdown.
I stop the test early and say I will revisit faster implementations or fine-tuned versions. The experience suggests that model quality, hardware, quantization and serving software all matter when choosing a system; the leaderboard and my two small prompts leave many capabilities untested.
같은 채널의 다른 글
 34:21EN
 Matthew Berman· 2026년 10월 27일Matthew Berman Examines Anthropic’s IPO Filing, AI Growth and GovernanceMatthew Berman, Sam Altman · Forward FutureThe presenter reviews the S-1’s financial metrics, compute strategy and voting structure while questioning the tension between rapid AI development and safety.
 0:36ENMatthew Berman· 2026년 10월 25일Kimi K3.1 and a Rubik’s Cube Solver DemonstrationMatthew Berman · Forward FutureMatthew Berman shows a scrambled virtual cube being solved and gives the Kimi K3.1 test a favorable assessment.
 25:50ENMatthew Berman· 2026년 10월 24일Kimi K3.1 Pro Tested: Strong 3D Demos, Uneven Results and Competitive PricingMatthew Berman · Forward FutureMatthew Berman tests the open-weight model on coding, 3D rendering and visual explanations, then compares benchmark results and prices.
 32:20ENMatthew Berman· 2026년 10월 23일Who Is Local AI For? The Costs, Trade-offs and a Hybrid FutureMatthew Berman · Forward FutureMatthew Berman weighs data control and independence against hardware cost, setup complexity and inference speed.
 1:03:37ENMatthew Berman· 2026년 10월 23일Matthew Berman’s Team Tests Kimi K3.1 on Animation, Games, and ChartsMatthew Berman, Alex, Brian · Forward FutureA live team AMA turns into an informal test of Kimi K3.1, from personal-agent workflows to motion graphics, a browser game, and a benchmark chart.
 0:53ENMatthew Berman· 2026년 10월 22일Sam Altman on AI and the Discovery of New KnowledgeSam Altman · OpenAIAltman expects progress in mathematical discovery to extend to biology, materials and energy.