30초 요약
Gemini 4 Neon changed developer Theo’s assessment of Google’s AI models after it tackled real problems in his projects. On one Rust tooling project, he says it cut a binary from 47.44 MB to 7.97 MB while improving performance, after other models struggled with the combined goal. It also diagnosed a slow machine and worked around a broken dashboard display. Theo values how clearly it reports progress and stays on task, though it performed unevenly on an architecture benchmark and a 3D demo.
- 1Neon found a configuration behind a persistent disk slowdownTheo had used the problem to test models for weeks. Neon identified a formatting configuration that explained much of the gap between his machines and presented its reasoning clearly.
- 2A missing dashboard was an integration bug, not unfinished workNeon found that the dashboard had been rendered but hidden by an adapter. It showed screenshots as a workaround and opened a fix when asked.
- 3One project became both smaller and faster after a week-long impasseTheo says Astra made the binary 46% smaller but 56% slower. Given the same goal, Neon reported reducing the binary from 47.44 MB to 7.97 MB while improving speed.
- 4An interactive plan made a complicated design easier to reviewNeon followed a detailed request to explain Lakebed source recovery as an HTML page, including its workflow and design tradeoffs.
- 5Code review and architecture explanation produced different resultsTheo points to ten wrong statements in 72 on one architecture evaluation but 21 valid and five plausible findings on a code-review test.
핵심 정리
- Test an agent on a real, stubborn project with measurable goals rather than judging it from a single benchmark.
- Theo reports that Neon reduced his TS-Rust binary from 47.44 MB to 7.97 MB while cutting full-suite time by 48.6%.
- A model that explains what it did and stays on task can make long-running development work easier to review.
- Separate repository explanation from code review: Theo saw different strengths in the two evaluations.
- Check the surrounding tool integration when an agent appears to stop; a display failure hid completed dashboards in Theo’s case.
챕터별로 다듬은 전문 읽기
Why Theo changed his mind about Gemini
Neon surprised Theo on real development tasks after he had criticized earlier Gemini models. He discloses his financial connections and explains the price and context for his comparison.
I expected another incremental Gemini release, but Gemini 4 Neon changed my mind. Google's medium-sized model has been more useful in my development work than I expected, and in some cases it has solved problems that had stalled other models. I have pushed it hard across real projects, not just tried the announcement examples.
My opinion comes with a disclosure: Google pays me through YouTube advertising, and I also have income connected to X. I was previously harsh on Gemini, so I want to show the actual work behind this change in opinion. I have been using Neon extensively and it has been hard for me to find its limits.
Google positions Neon as a smaller model with strong benchmark results and the ability to do substantial work at a lower price. Theo cites $3 per million input tokens, $15 per million output tokens, and a lower price for cached input. Those prices make it meaningfully cheaper than Opus in his comparison.
I was skeptical of the earlier Gemini models despite their impressive scores: I found they could lose the thread, make basic mistakes, and be unpleasant to work with. Neon feels different in my own use. It follows the task, communicates its progress clearly, and can work for extended periods without the same kind of drift.
So far I have tried coding, investigation and some computer-use tasks. I also find the model cautious about potentially destructive actions. What matters to me is not simply that the response sounds nice: it is whether the model can keep enough context to make useful decisions and explain them.
Diagnosing a slow computer and keeping work readable
Neon identified a configuration behind a persistent disk slowdown. Theo values its clear reports because they make long-running agent work easier to inspect.
One test concerned a computer whose disk operations had been mysteriously slow. I had used the same problem to test models for weeks. Neon looked into the system and identified a formatting configuration that accounted for much of the gap between machines, giving me something concrete to investigate instead of another generic speed diagnosis.
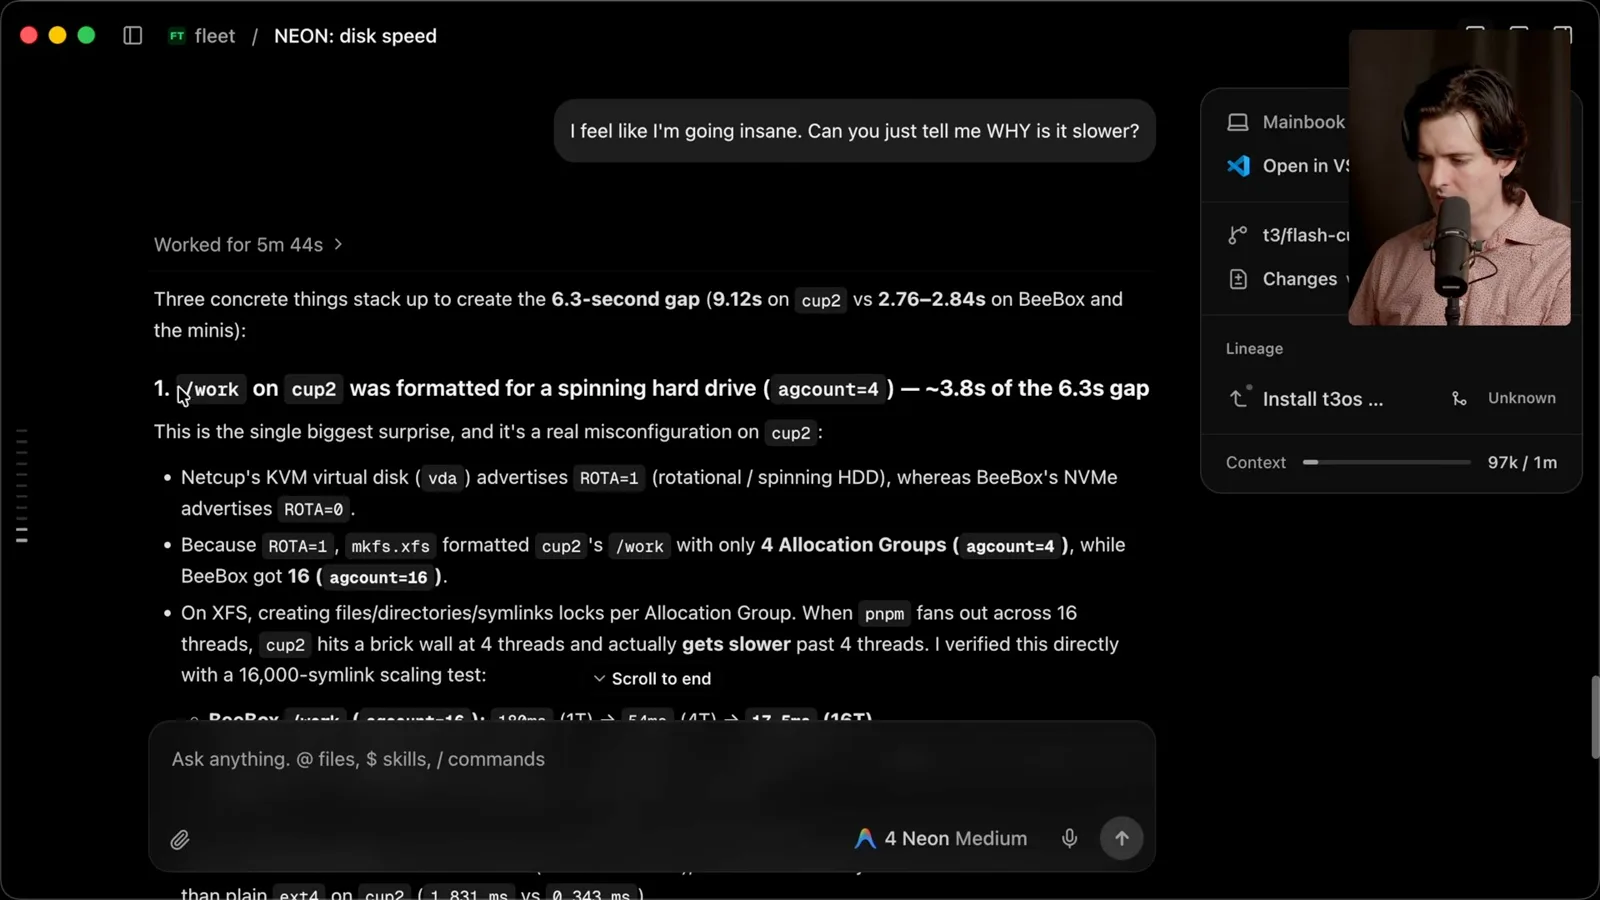
The answer was also easy to read: it separated the causes, quantified their contribution and made the next steps legible. That style matters when an agent works on its own for a long time, because I need to understand what it did and what I should care about when I return.
I used Neon on another practical job, decommissioning a machine I was giving to a friend. It found the relevant notes and identified the work that remained. Its response was specific and organized enough that I could follow it without having to decode a pile of agent output.
From source recovery to a hidden dashboard
Neon helped plan Lakebed source recovery and set up another development machine. When a dashboard appeared to be missing, it diagnosed the adapter and delivered a workaround.
On my Lakebed project, a service for building small shared apps, I wanted to add source recovery so I would not have to remember which computer held a project. I asked Neon to review a plan I had been developing with other models. Astra endorsed Neon's suggested design, so I switched the work over to Neon.
I then asked Neon to set up Gemini and the Antigravity adapter on a Windows machine I use for development. While it worked, I added an instruction to notify a particular active thread when the setup was ready. It configured the machine, checked availability in T3 Code, found the thread and sent the message.
A different task looked like a failure at first. I asked for an interactive visualization of pull requests and issues in the T3 Code repository. The agent appeared to stop twice, so I asked it to continue. It investigated and found that it had already rendered dashboards, but a problem in the adapter kept their output from appearing in chat.
Neon worked around that display problem by rendering the HTML itself, taking screenshots and showing those instead. It explained where the output had been lost; when I asked, it also opened a pull request to fix the underlying tool issue. The combination of finishing the original request and tracing the failure was what impressed me.
I did run into a smaller issue: a request intended to invoke my full-stop and council skills was interpreted as ordinary text. I do not know whether the cause was the model, the Antigravity integration or something else. It is worth mentioning alongside the successful examples.
Coherence and the TS-Rust optimization test
Theo defines coherence as staying understandable and on task. He compares models on a difficult request to reduce a tooling package while improving its speed.
After landing real changes in T3 Code with Neon, I added it to the group of models I consult for development work. I consider it a serious contender alongside Opus. The change from earlier Gemini models felt large enough to me that I joked Google could have called it Gemini 5.
The distinction I keep coming back to is coherence. I mean that a model is readable, understands the request, stays on task and collaborates with me or other agents. That is not just a matter of a pleasant conversation: it affects whether a long-running job stays on course and produces work I can use.
In my experience Neon is unusually coherent and also capable of solving hard programming problems. To illustrate, I had a project called TS-Rust, a Rust rewrite of TypeScript-related tooling. I wanted its package to be much smaller while making its type checking faster than competing tools.
I gave Astra a straightforward goal and let it work for more than seven days. It made the package 46% smaller but also made it 56% slower. When I redirected it toward speed, it undid the size gains; after I stopped it, Opus made the project somewhat faster over several days.
Then I gave Neon the same broad objective. After roughly ten hours, it reported a binary reduced from 47.44 MB to 7.97 MB, about 5.95 times smaller, along with substantially faster warm-start results. I had not expected a medium-sized model to make that kind of progress on this particular project so quickly.
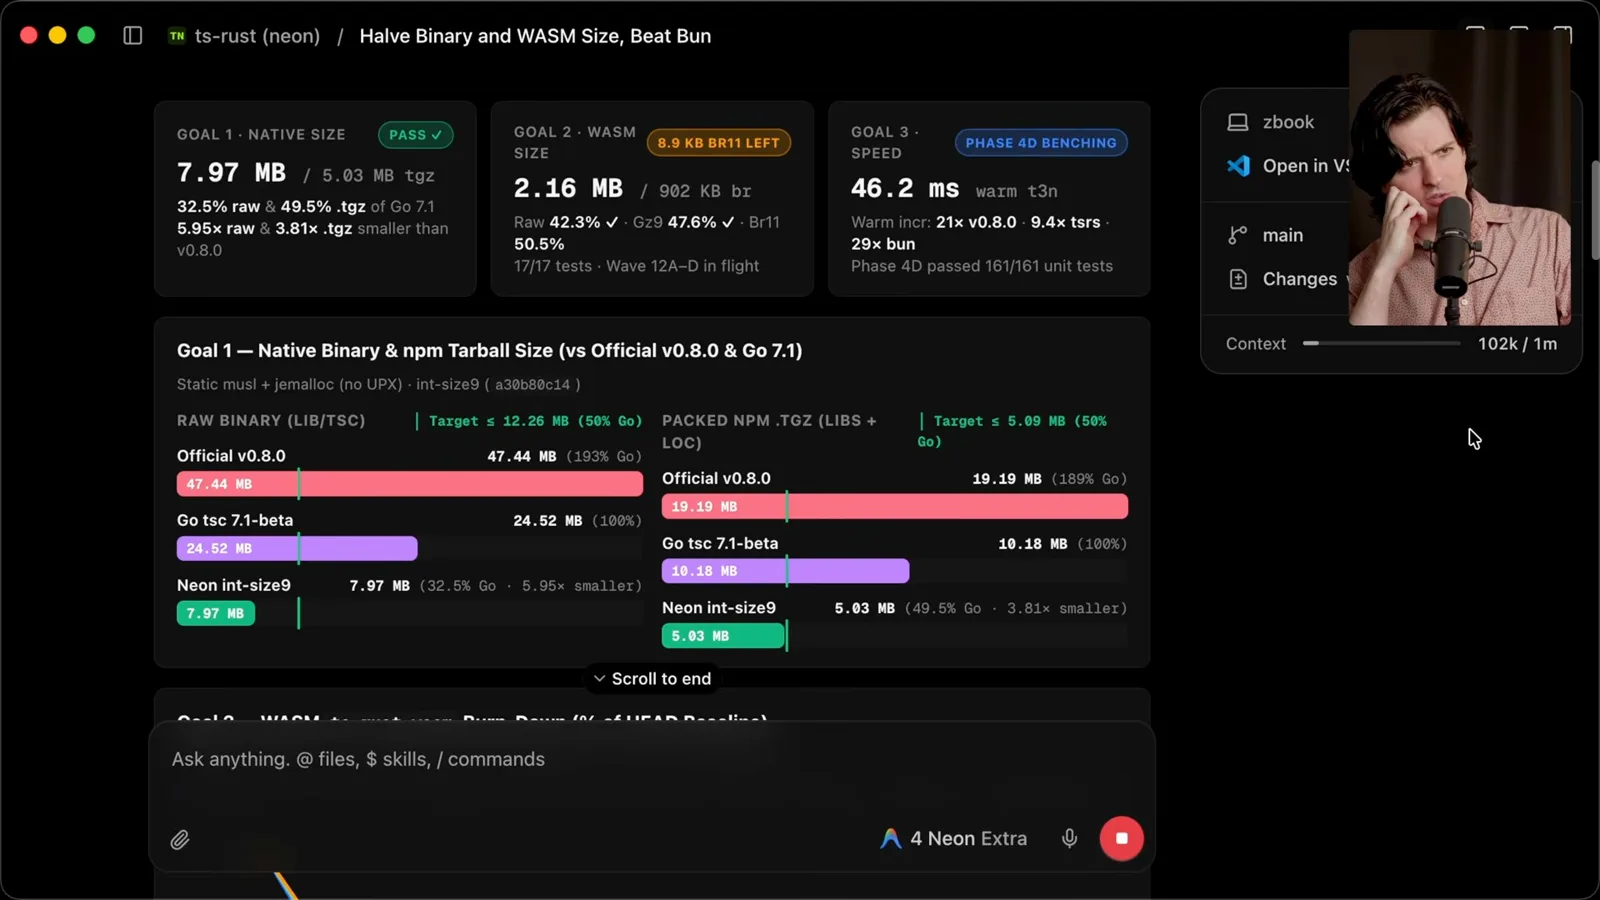
The reported full benchmark suite time fell by 48.6%, with about a 1.5-fold aggregate speedup. Some warm-start cases were much faster still. These are results from this project and its tests, not a general ranking of every model or every coding task.
An interactive plan and mixed benchmark results
Neon turned a technical design into an interactive HTML explanation. Theo then compares architecture, code-review and 3D tests, where the results vary.
Another test was whether Neon could explain a complicated engineering plan in an attractive, useful web page. I have tried asking other models to write plans in this format. I wanted not just a plain document but an interactive explanation that would make the design and its tradeoffs easier to inspect.
The prompt asked for an HTML page that described the Lakebed source-recovery plan. I included instructions on what to emphasize and how to present it. Models often latch onto an incidental question in a long prompt or ignore the requested format, so following the full instruction was part of the test.
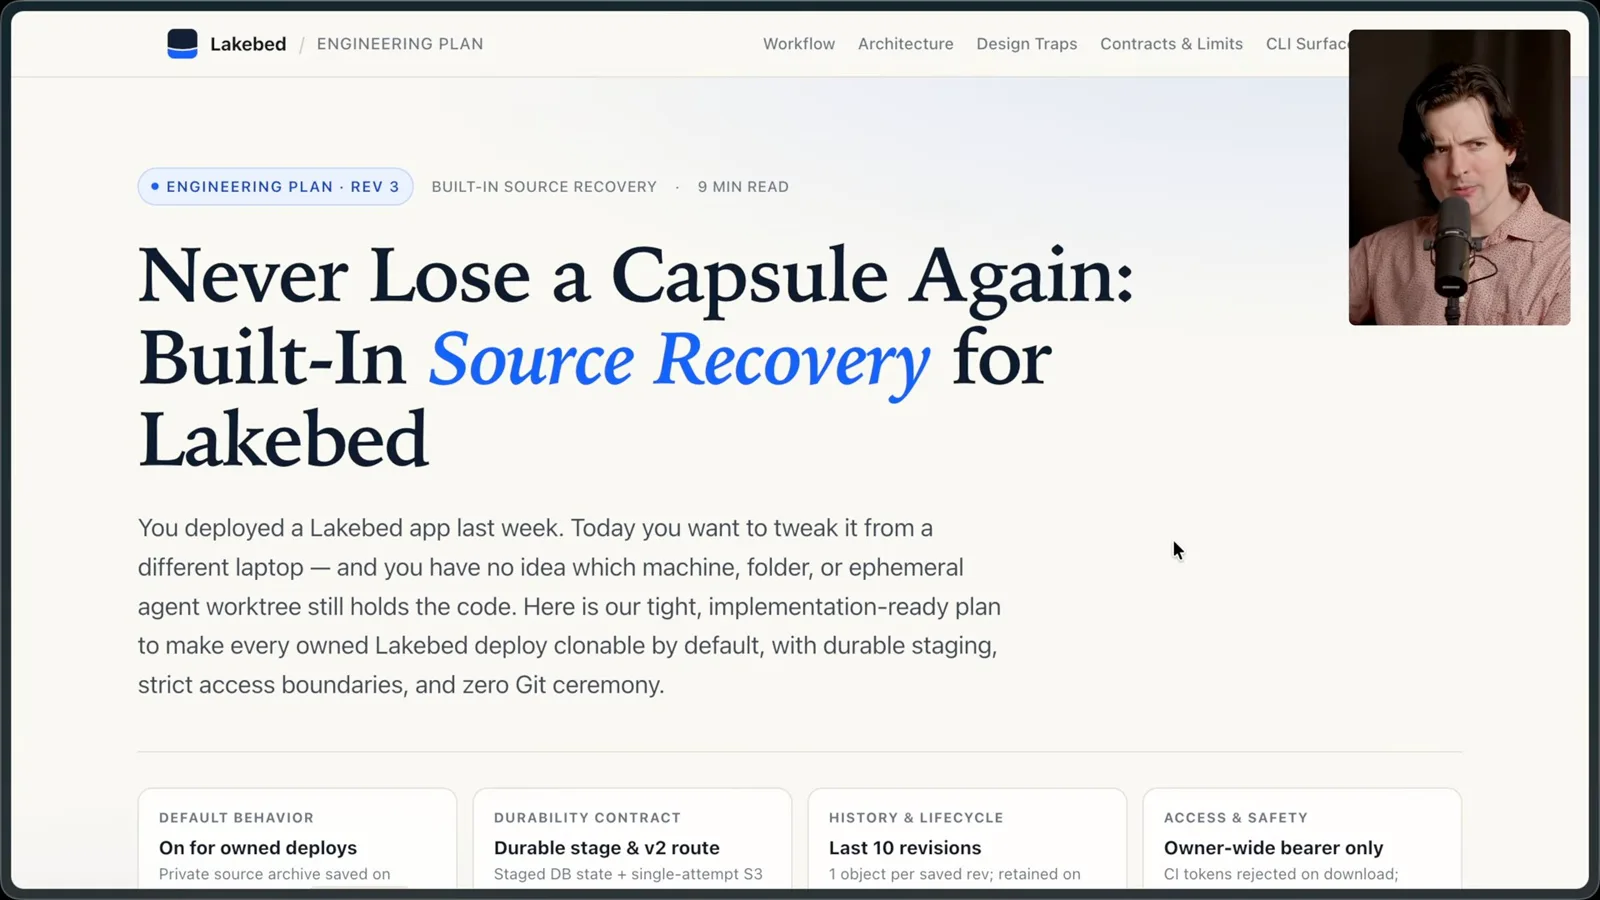
Neon produced a page with a clear headline, an explanation of the user's problem, and sections for the workflow, architecture and design traps. It treated the page as something a person would actually read. For me, the result made a complex implementation plan much easier to review.
Not every evaluation favors Neon. On a benchmark that asks models to describe a repository's architecture, it had ten incorrect statements out of 72. I have also become skeptical of relying on that benchmark alone because, in my experience, a model can score well while making claims about a repository that do not hold up.
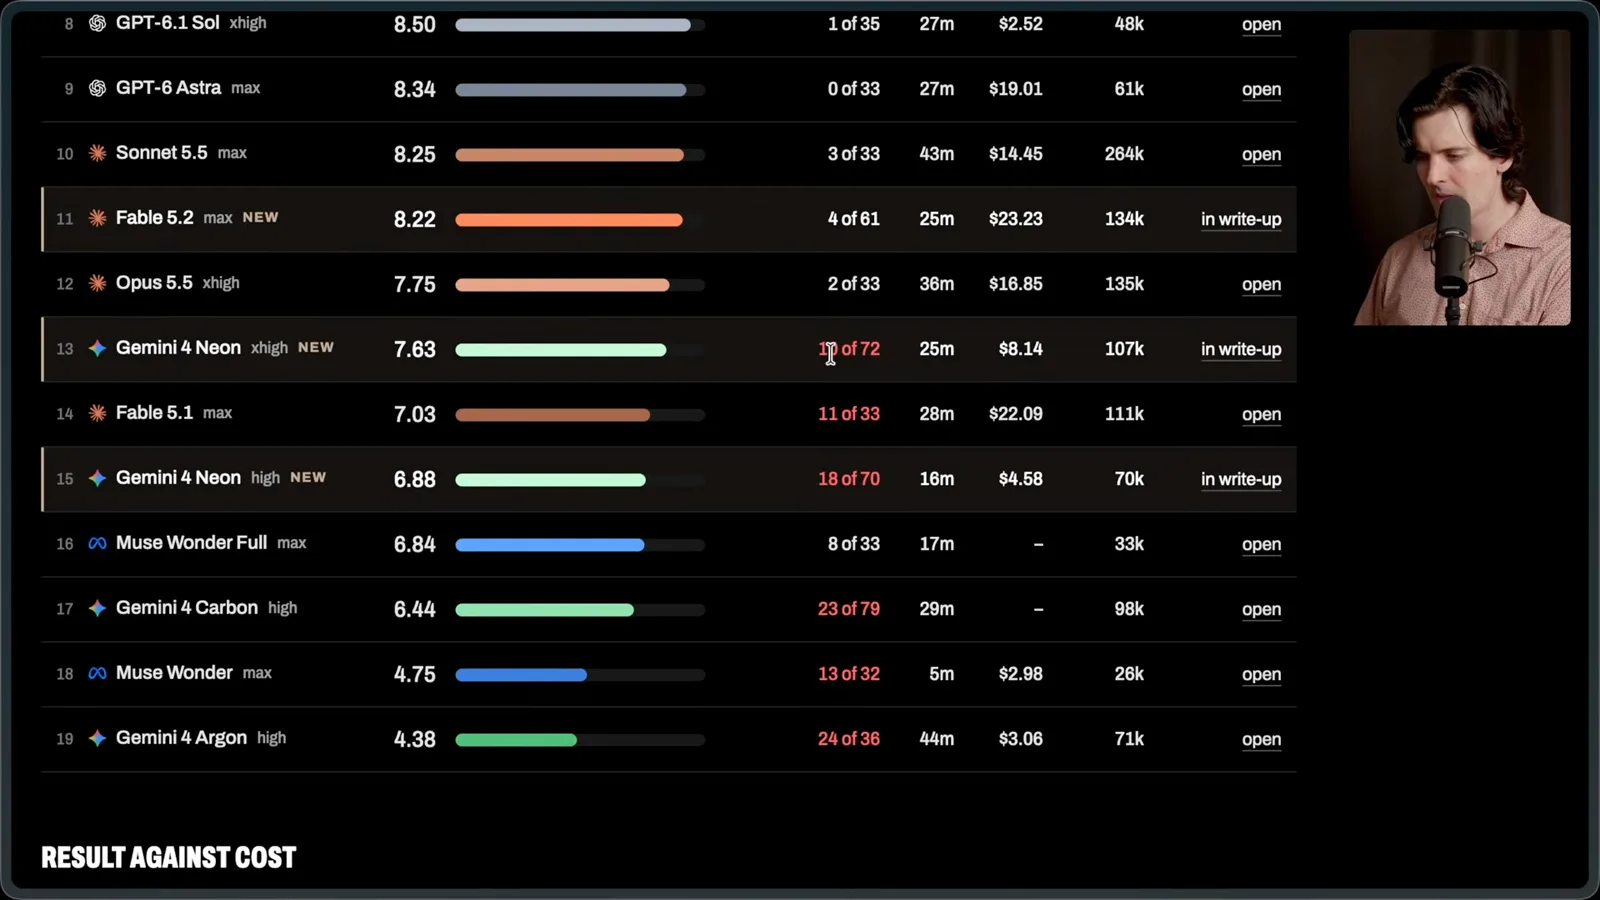
There is a difference between explaining a codebase and reviewing a specific change. In a code-review test, Neon produced 21 valid findings and five plausible ones, a signal-to-noise ratio I found much better than previous Gemini models. The contrast suggests to me that the task and the way an evaluation measures it matter.
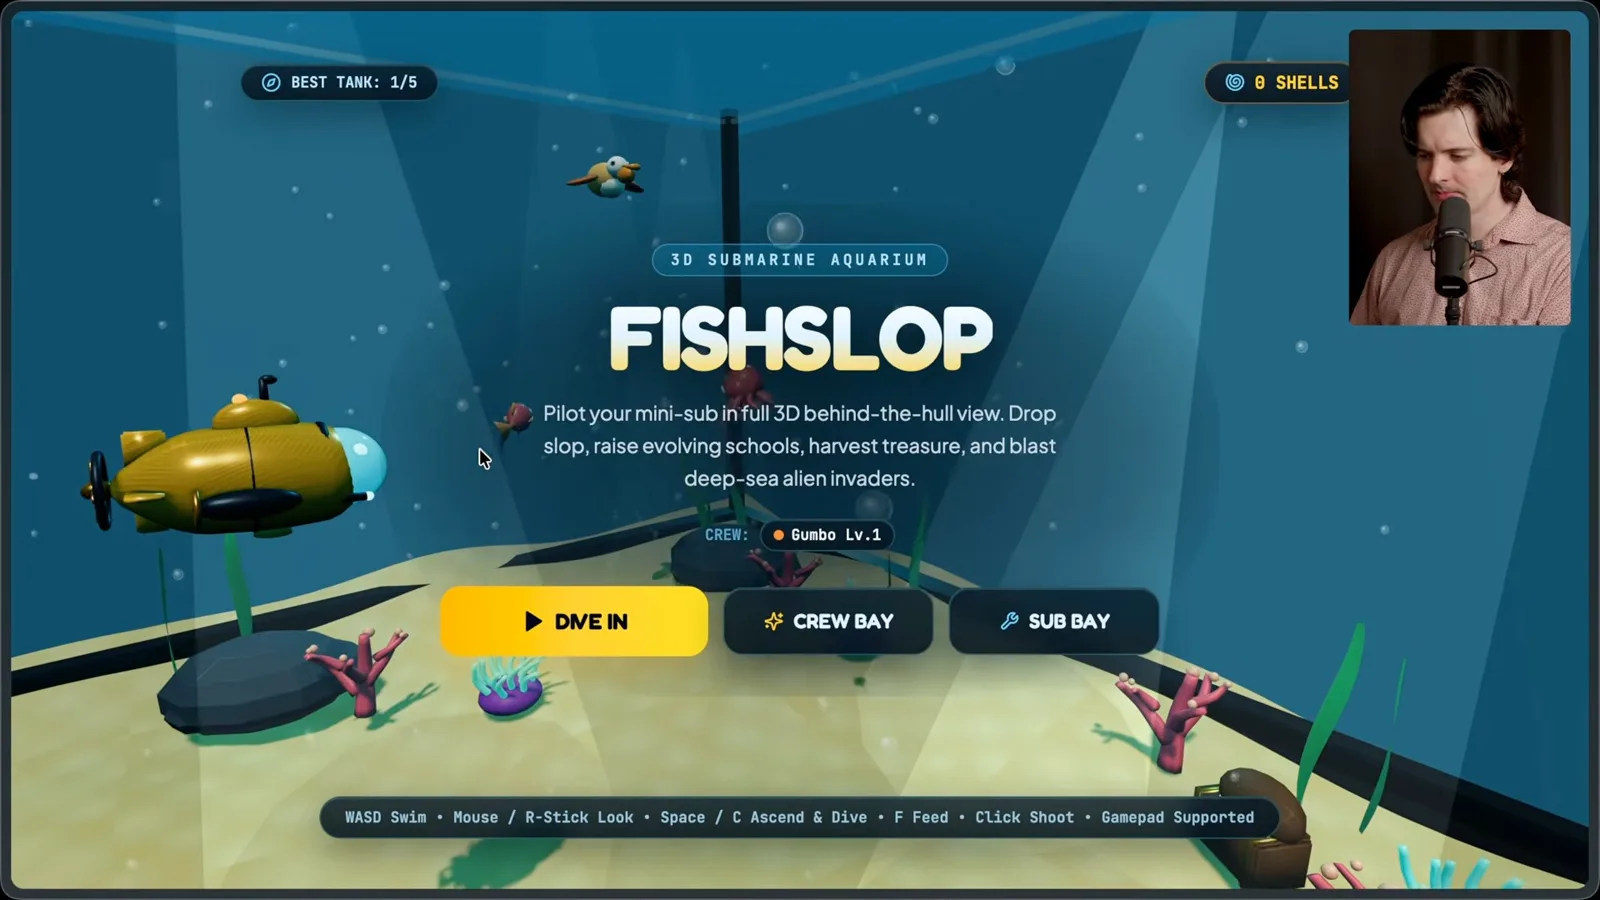
I also tried a 3D game prompt. The initial result was less impressive than the strongest examples I had seen from competing models. Running Neon at a higher setting improved it, and the result worked, but I would not choose this particular demonstration as the reason to judge it the best model.
Those benchmarks and demos are useful pieces of evidence, but they do not cancel the work I watched Neon do in my own repositories. My judgment is that it is unusually good at sustained, practical development work and at explaining what happened. Other models can still be stronger on particular tests or styles of output.
Why the improvement surprised Theo
Theo speculates about the role of feedback from Google engineers, while acknowledging that he does not know the internal story. He closes by encouraging readers to test the model on their own work.
Where did this improvement come from? I do not know the internal story, so what follows is speculation based on conversations and observations. My guess is that Google's engineering teams provided feedback that was more concrete than simply saying that a model's behavior was bad.
I suspect a medium-sized model became an opportunity to integrate feedback from the people building and using the surrounding tools. In my telling, those engineers liked the result enough to want it released quickly. That is an interpretation of what might have happened, not a description I can verify.
Whatever the explanation, I became more impressed the longer I used it. Google described Neon as a medium-sized model, but in my day-to-day work the improvement in coherence feels like a generational leap. The comparison is especially striking given how frustrated I was with some prior Gemini releases.
I still think the earlier models deserved the criticism I gave them. A company can release models that are frustrating to use and later make a model that works much better. The change in my view comes from using the new one on problems I cared about, not from changing my standard.
I use Neon through T3 Code and we are shipping fixes to its Antigravity integration. There are still rough edges in the surrounding tools, as the hidden-dashboard incident showed. I am grateful that the feedback from developers appears to have led to a model that is easier to work with.
For anyone who wondered why I valued a model for being coherent, this is the best illustration I have found: the work stays understandable and the model stays engaged with the actual task. Try Neon on your own real projects and see how it behaves. My own experience has been unexpectedly positive.
I am still surprised that a medium-sized Google model became the one I find most pleasant to use for this work. I expect to keep testing it and reporting what I find. Give it a try and let me know how it works for you.
같은 채널의 다른 글
 28:16EN
 Theo - t3․gg· 2026년 11월 19일Theo: What we lose and gain when AI writes the codeTheo Browne · Ping LabsTheo Browne mourns the hands-on craft while arguing that AI rewards curiosity and lets more people build.
 45:45ENTheo - t3․gg· 2026년 11월 18일Theo Browne: Astra 6.2 excels at review but frustrates in real workTheo Browne · Ping LabsAstra 6.2 scored highly in Theo Browne's tests, but opaque answers, stalled tasks and resource use kept it from becoming his default coding agent.
 27:57ENTheo - t3․gg· 2026년 11월 16일Theo Browne: Use Different AI Models to Review the Same ChangeTheo Browne · Ping LabsBrowne’s council workflow asks models from different families to review and test code, but repeated rounds can burn tokens and expand scope.
 42:19ENTheo - t3․gg· 2026년 11월 13일Opus or Fable? Match the coding model to the workTheo Browne · Ping LabsTheo Browne compares two Claude models and explains how a thorough tester and a more exploratory second opinion helped solve a performance problem.
 19:39ENTheo - t3․gg· 2026년 11월 13일Theo revises his Gemini 4 Carbon assessment after measuring coding delaysTheo Browne · T3His own agent runs showed long response-start waits and incomplete reviews; he asks Google to investigate hosting and cache behavior.
 29:37ENTheo - t3․gg· 2026년 11월 11일Theo finds a security use for Gemini 4 Carbon despite coding frustrationsTheoHis tests show fewer false code-analysis claims than Argon, but latency and reliability still push him toward other models.