30초 요약
Matthew Berman says Claude Fable 5.2 feels more capable in his tests than its benchmark lead over Gemini 4 Carbon suggests, but notes its higher cost and Carbon’s useful demos. He reviews smaller open-weight and delegated-work models, image and video releases, and the tradeoff between model quality and task cost. He also discusses Nvidia’s independent investigation following reports concerning CEO Jensen Huang.
- 1Nvidia’s board is investigating reports involving its CEOBerman discusses the potential impact and says the facts require investigation.
- 2Berman sees a wider practical gap than the index suggestsHe compares Fable 5.2 and Carbon on scores, decisions and his own use.
- 3The best benchmark score comes with a higher task costHe says Carbon may be suitable for work that does not need the most expensive model.
- 4Smaller models can handle delegated tasks at lower costHe compares Muse Ember with other small models and describes a planning-and-worker approach.
핵심 정리
- Compare benchmark results with performance on your own tasks.
- Consider cost per completed task, not only a model’s headline score.
- Use cheaper models for suitable delegated work when the strongest model is unnecessary.
- Treat reports of an intelligence effort as subject to Nvidia’s independent investigation.
챕터별로 다듬은 전문 읽기
Nvidia investigation and model comparisons
Berman discusses the company’s investigation before comparing Fable 5.2 and Gemini Carbon.
Nvidia’s board is investigating reports that CEO Jensen Huang was targeted by a foreign intelligence effort, after Huang acknowledged an extramarital relationship. I discuss the possible implications for the company and say an investigation is needed to establish what happened.
Claude Fable 5.2 and Gemini 4 Carbon arrived close together. Independent benchmark results put Fable ahead, but in my own use I perceive a wider quality gap than the aggregate scores suggest.
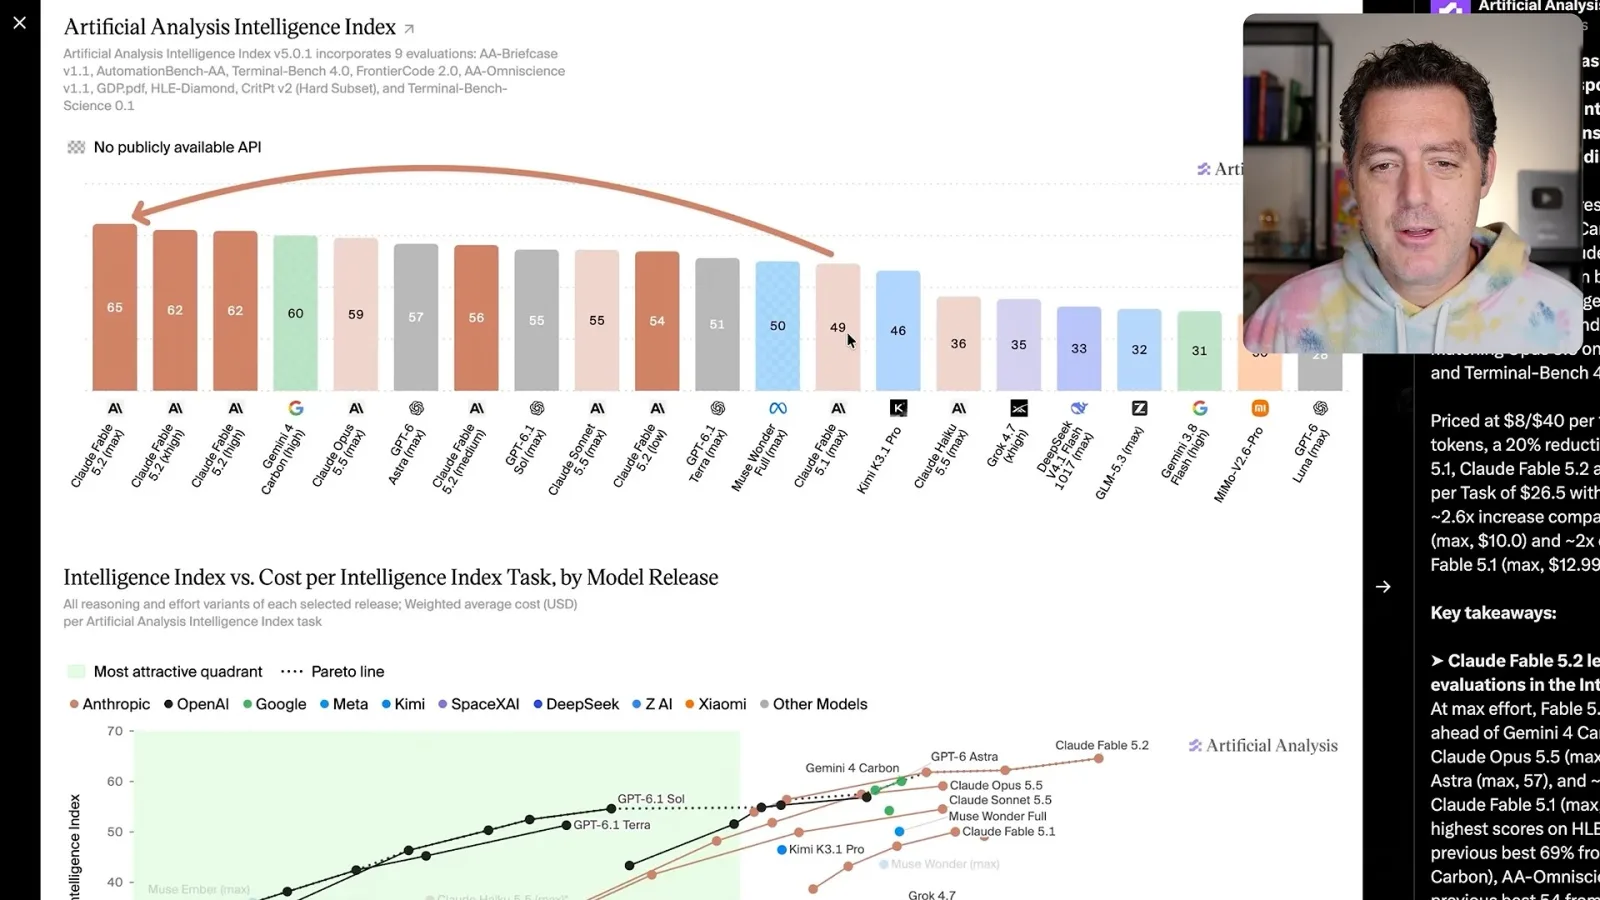
The Artificial Analysis index places Fable variants at the top, with Carbon close behind. I question whether the benchmark reflects the differences I see in decisions, assumptions and task execution.
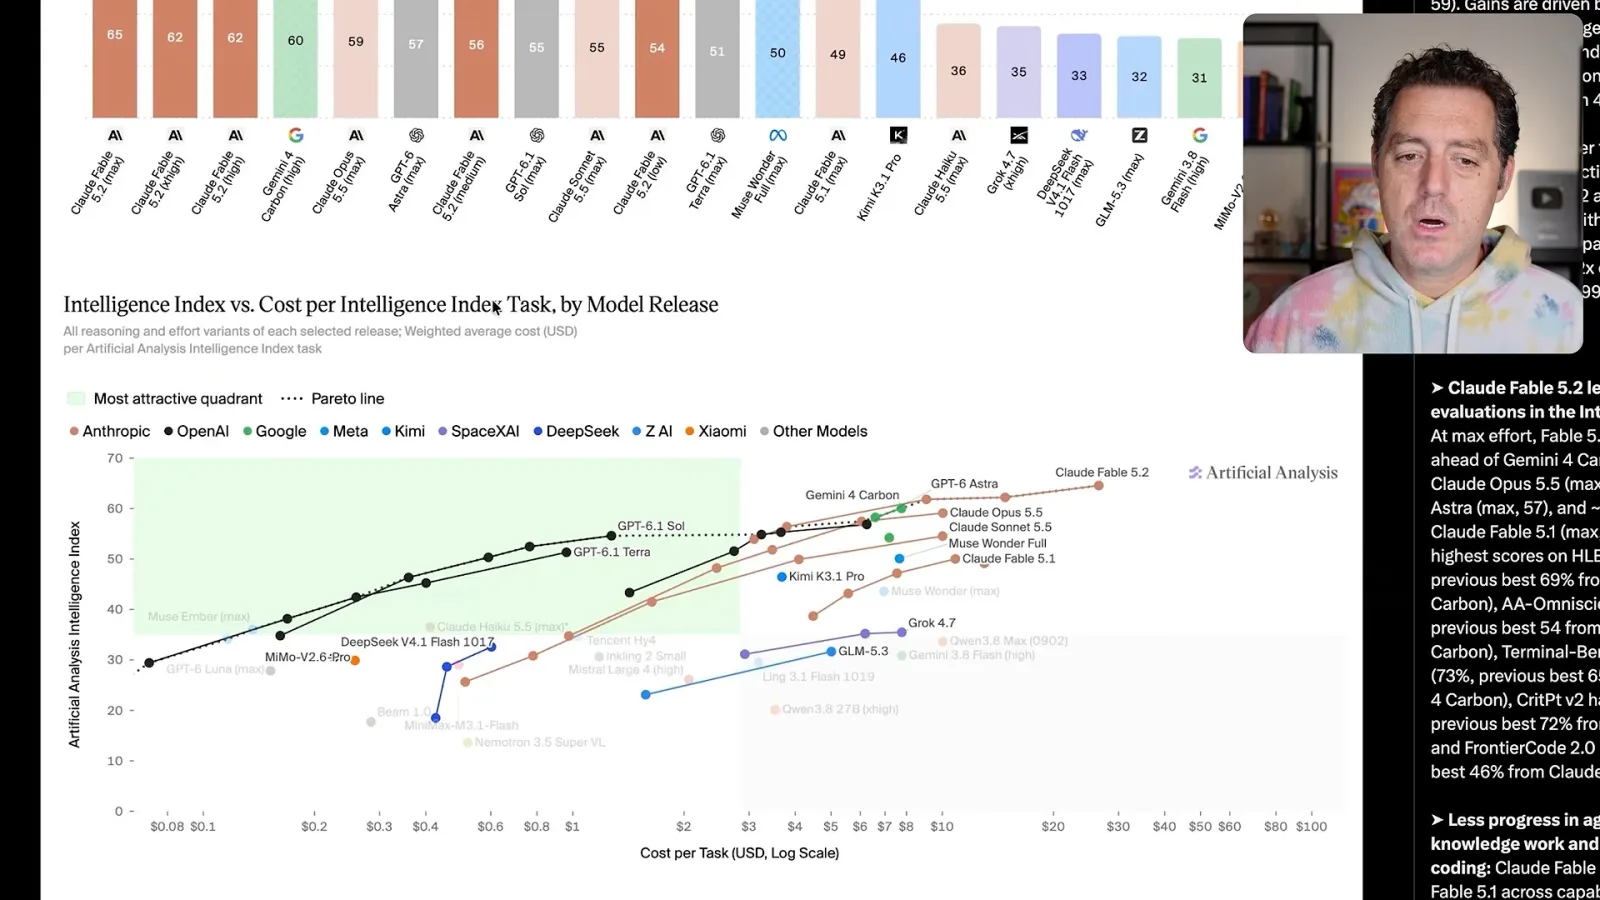
Cost changes the choice: Fable 5.2 is expensive, while Carbon costs a fraction as much per benchmark task. Not every job requires the most capable model, even if I prefer Fable for my own work.
Benchmarks, cost and practical demos
He questions aggregate scores and shows Carbon’s spreadsheet and game examples.
I look at individual benchmark exceptions, including knowledge-work, automation and coding tests. My experience with these models has made me less confident that a single set of scores captures their differences.
I describe what I see as Anthropic’s cycle of coding-model demand, revenue, data and compute, and speculate about how previous models may help build successors. My comments about unreleased models are speculation.
I find Carbon useful and comparatively inexpensive, although in my tests I prefer Fable. One example is a browser-based spreadsheet application that resembles Excel.
The model reported that the spreadsheet demo took roughly three agent-hours, about one hour and forty minutes elapsed, and 26 million tokens. I present those as the model’s own reported figures.
In a Fall Guys-style game I notice clipping, imperfect collisions and physics, though the result compares favorably with some other models I tried. A Rube Goldberg-style animation is another example.
Open-weight and smaller models
He reviews LongCat, Ripple, Inkling and Muse Ember, including size and cost tradeoffs.
I turn to open-weight releases, starting with LongCat 2.5: I report 1.6 trillion total parameters, 48 billion active parameters and multimodal capability. Its size makes local use difficult for most people.
Recursive Intelligence’s Ripple 65B preview is a smaller dense model. I cite its reported Terminal-Bench 2.1 score and million-token context, while distinguishing its open-weight comparisons from the full model market.
Thinking Machines’ Inkling 2 Small is another compact open-weight model. I show examples including a city-building game and a Python PC emulator, along with comparisons to a larger DeepSeek model.
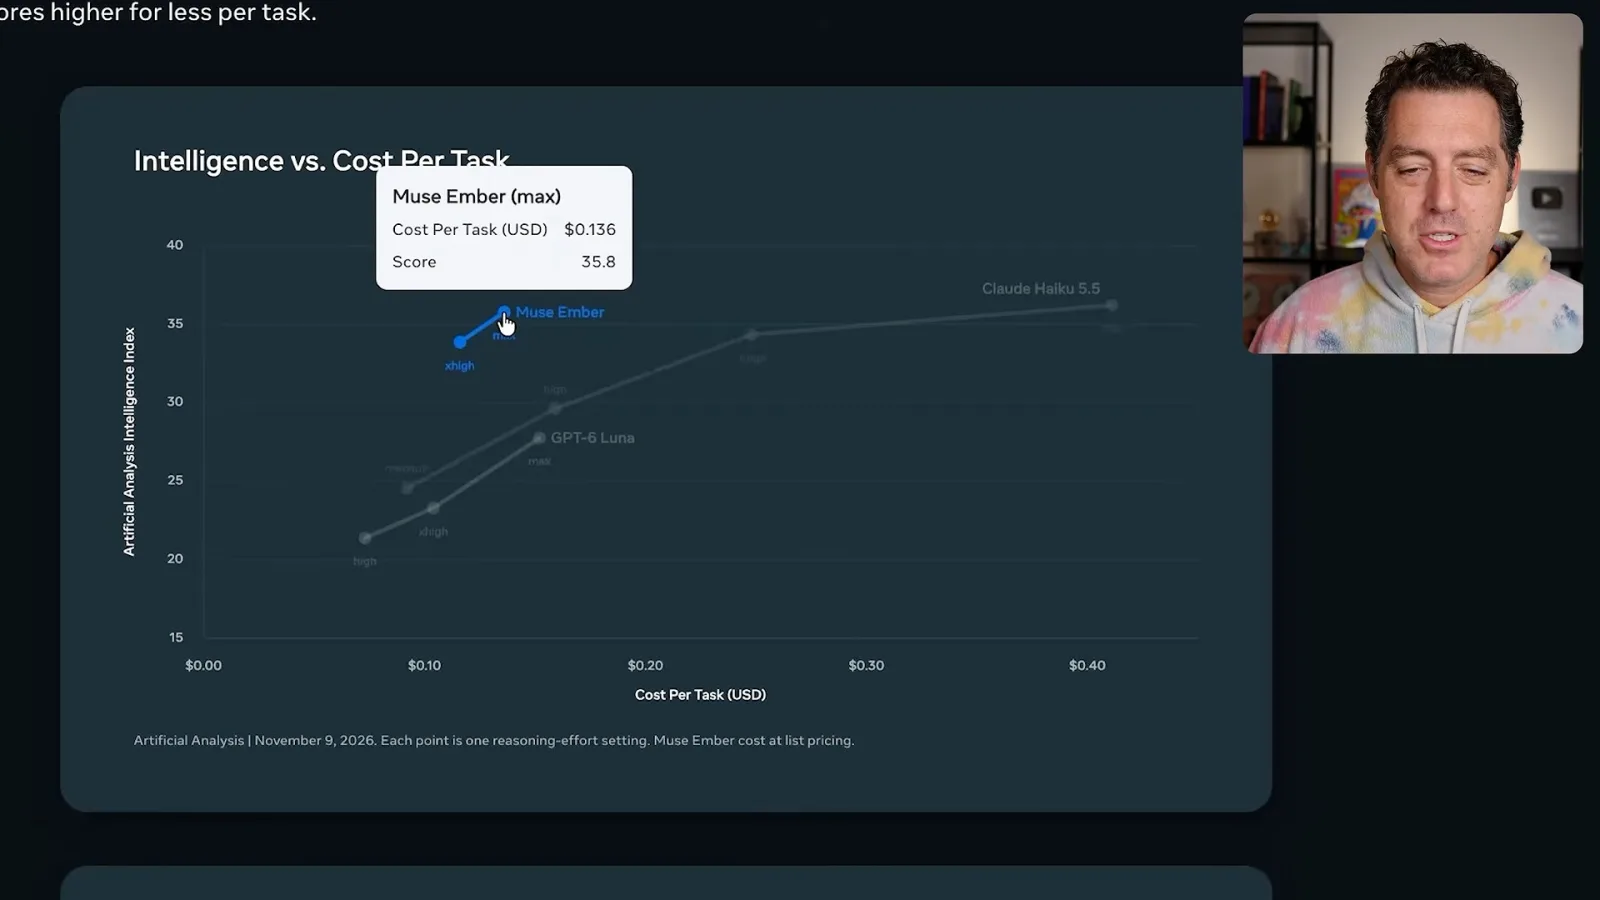
Meta’s Muse Ember targets smaller-model workloads. I compare the displayed cost and scores with Claude Haiku and GPT-6 Luna and suggest pairing a stronger planning model with cheaper delegated workers.
Image, video and coding releases
Berman reviews image and video generation and smaller coding models.
OpenAI’s GPT Image 2.6 introduces animated GIF generation and faster image generation, with variants intended for quality and speed. I show pricing and note uncertainty about how its input pricing works.
I describe Gemini Omni 1.2 Flash as a faster, cheaper video-generation option with longer clips and conversational editing, then show examples attributed to ByteDance’s Seedream 5.5.
Cognition’s SWE 2 Flash builds on Inkling Small for efficient coding work, according to the presentation I discuss. I again recommend considering smaller models for delegated tasks when preserving quota matters.
MiniMax H3 Image is presented as an open-weight image model. I mention the size of the full download and a smaller quantized option, and close by returning to my preference for Fable 5.2.
같은 채널의 다른 글
 24:18EN
 Matthew Berman· 2026년 11월 9일Fable 5.2 built playable demos—but several cost thousandsMatthew Berman · Forward FutureMatthew Berman shows games, creative software and simulations, with estimated API costs from $25 to $15,000.
 20:08ENMatthew Berman· 2026년 11월 7일METR Finds Faster AI Research at Anthropic, With Major UncertaintyMatthew Berman · Forward FutureMatthew Berman examines an independent assessment of AI-assisted R&D and the limits on its access to evidence.
 19:53ENMatthew Berman· 2026년 11월 5일AI News: Kimi K3.1 Weights, Computer Use and Specialized Open ModelsMatthew Berman · Forward FutureMatthew Berman reviews a week of model releases, from desktop agents and scientific workflows to image, video and speech tools.
 26:47ENMatthew Berman· 2026년 11월 4일What Weight-Space Programming Experiments Show—and Their LimitsMatthew Berman · Forward FutureMatthew Berman reviews experiments in which a frontier model reads, repairs and writes other networks’ weights, from small game policies to a targeted language-model edit.
 12:58ENMatthew Berman· 2026년 11월 3일Matthew Berman on Building Personal Software With AIMatthew Berman · Forward FutureA homemade PDF reader leads Berman to argue that coding agents could make customized consumer software more accessible.
 14:45ENMatthew Berman· 2026년 10월 29일Matthew Berman Examines Google’s Gemini 4 Carbon AnnouncementMatthew Berman · Forward FutureMatthew Berman reviews Google’s reported benchmark results, staged rollout and pricing for Gemini 4 Carbon, while noting he has not yet used the model.