30초 요약
Matthew Berman introduces WizardCoder 15B, a code-focused fine-tune of StarCoder, and demonstrates a local GPTQ version in text-generation-webui. He runs a handful of Python challenges and attempts to generate a Snake game. The small functions pass the exercise site’s checks in the examples he shows, while the generated game does not run. His benchmark comparisons and setup reflect June 2023 and should not be read as current rankings or universal limits.
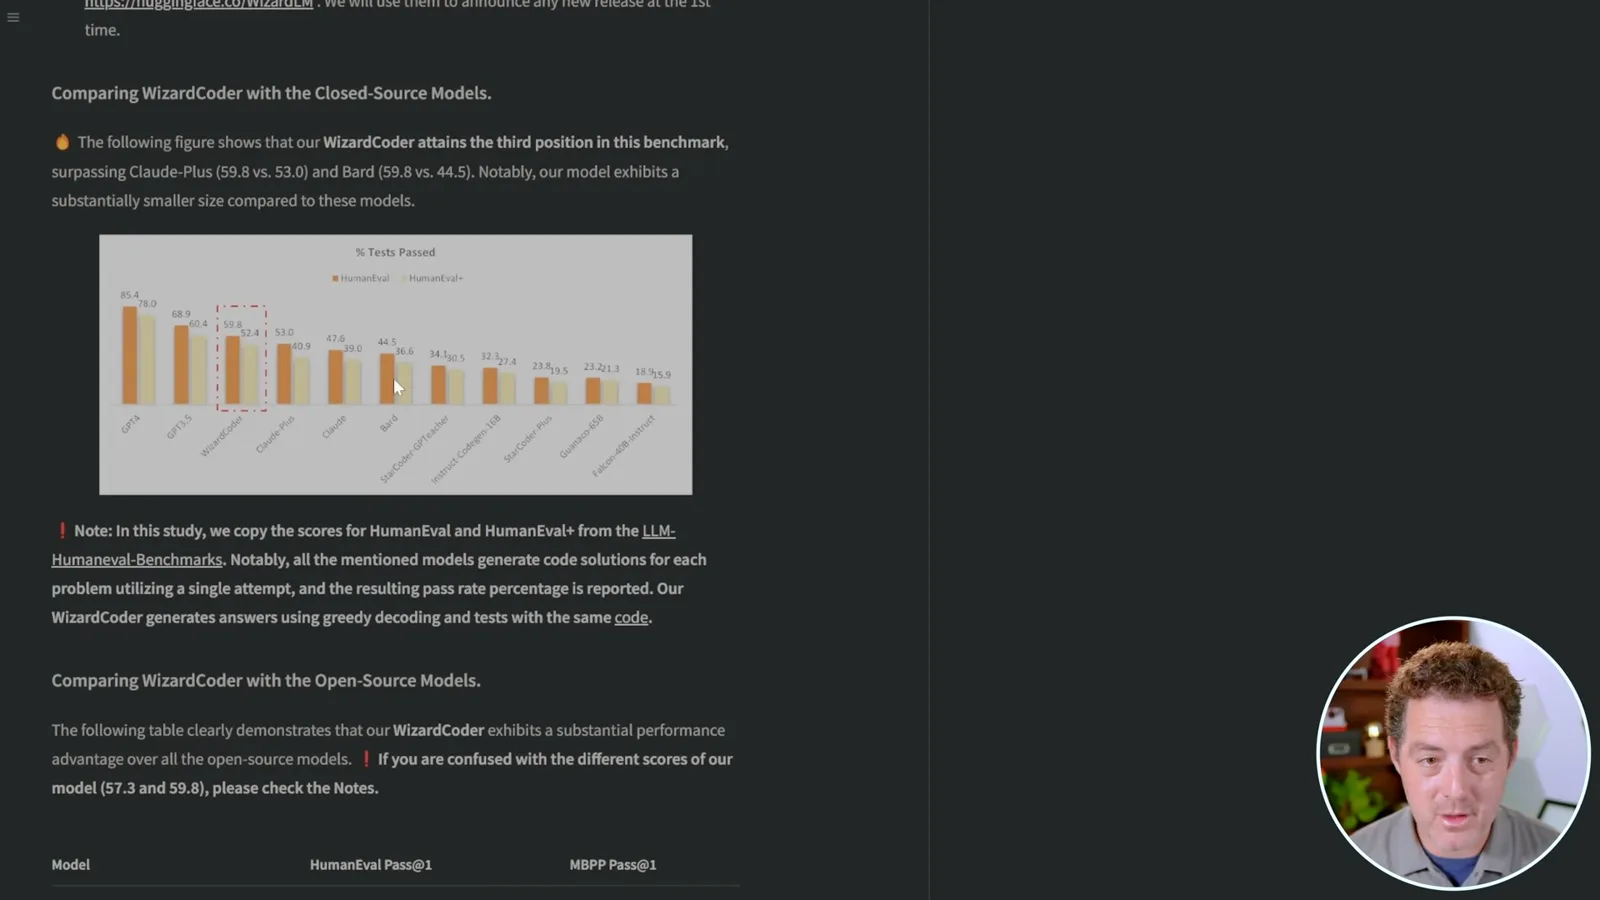
- 1Code-oriented fine-tuningThe model description says the team adapted Evol-Instruct for code instructions and fine-tuned StarCoder. Its benchmark chart represents the authors’ comparisons at the time.
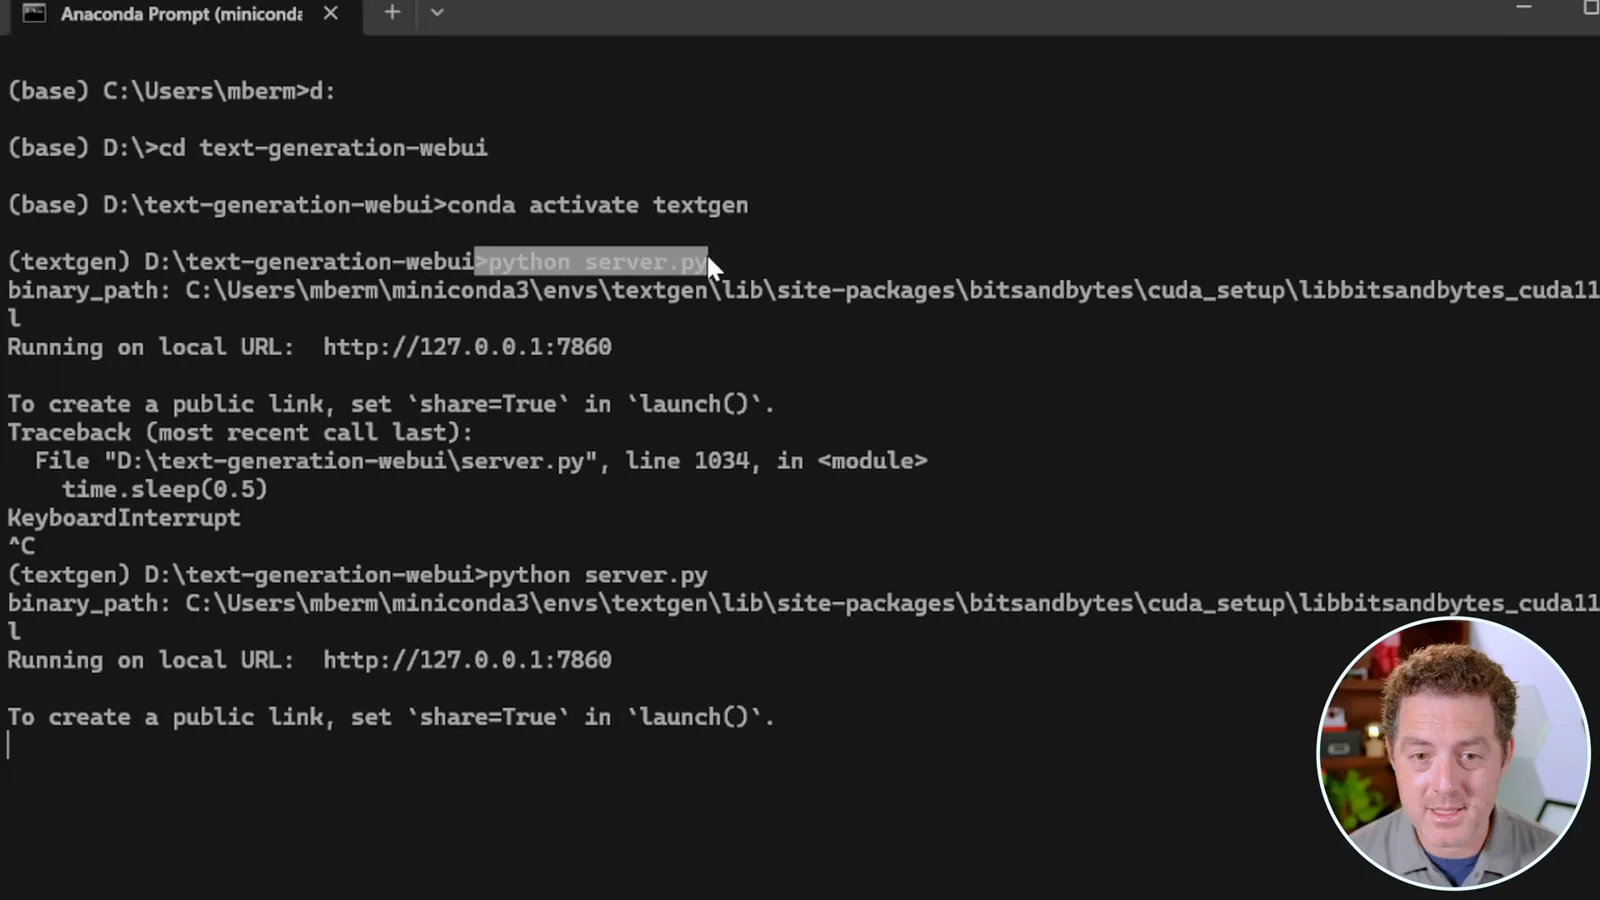
- 2Running the model locallyBerman starts an existing text-generation-webui setup and selects TheBloke’s GPTQ version of WizardCoder 15B.
- 3Prompt sensitivityAn output ends with an unexpected token marker; Berman says removing the example sometimes resolves this in his tests.
- 4Small Python exercisesSolutions for divisibility, argument counting, and formatting numbers are shown, with successful checks on some examples.
- 5The longer game failsA Snake program requires continued generation and does not run when tested; Berman does not debug it further.
핵심 정리
- WizardCoder 15B builds on StarCoder and uses code-oriented Evol-Instruct training data, according to its model description.
- Berman runs a GPTQ version locally using an existing text-generation-webui installation.
- Several small Python exercises pass the website’s checks, while a generated Snake program fails to run.
- Removing an example helped in Berman’s tests, though that does not establish a universal prompting rule.
- The displayed model comparisons and interface settings reflect the 2023 demonstration.
챕터별로 다듬은 전문 읽기
WizardCoder and its training
Berman introduces a locally runnable 15-billion-parameter coding model. He discusses its StarCoder base, training approach, and 2023 comparisons.
WizardCoder is a coding assistant that can run locally. In this June 2023 demonstration, I show the model’s background, load a local version, and try it on Python coding challenges. The results are an informal snapshot of one setup, not a current ranking of coding models.
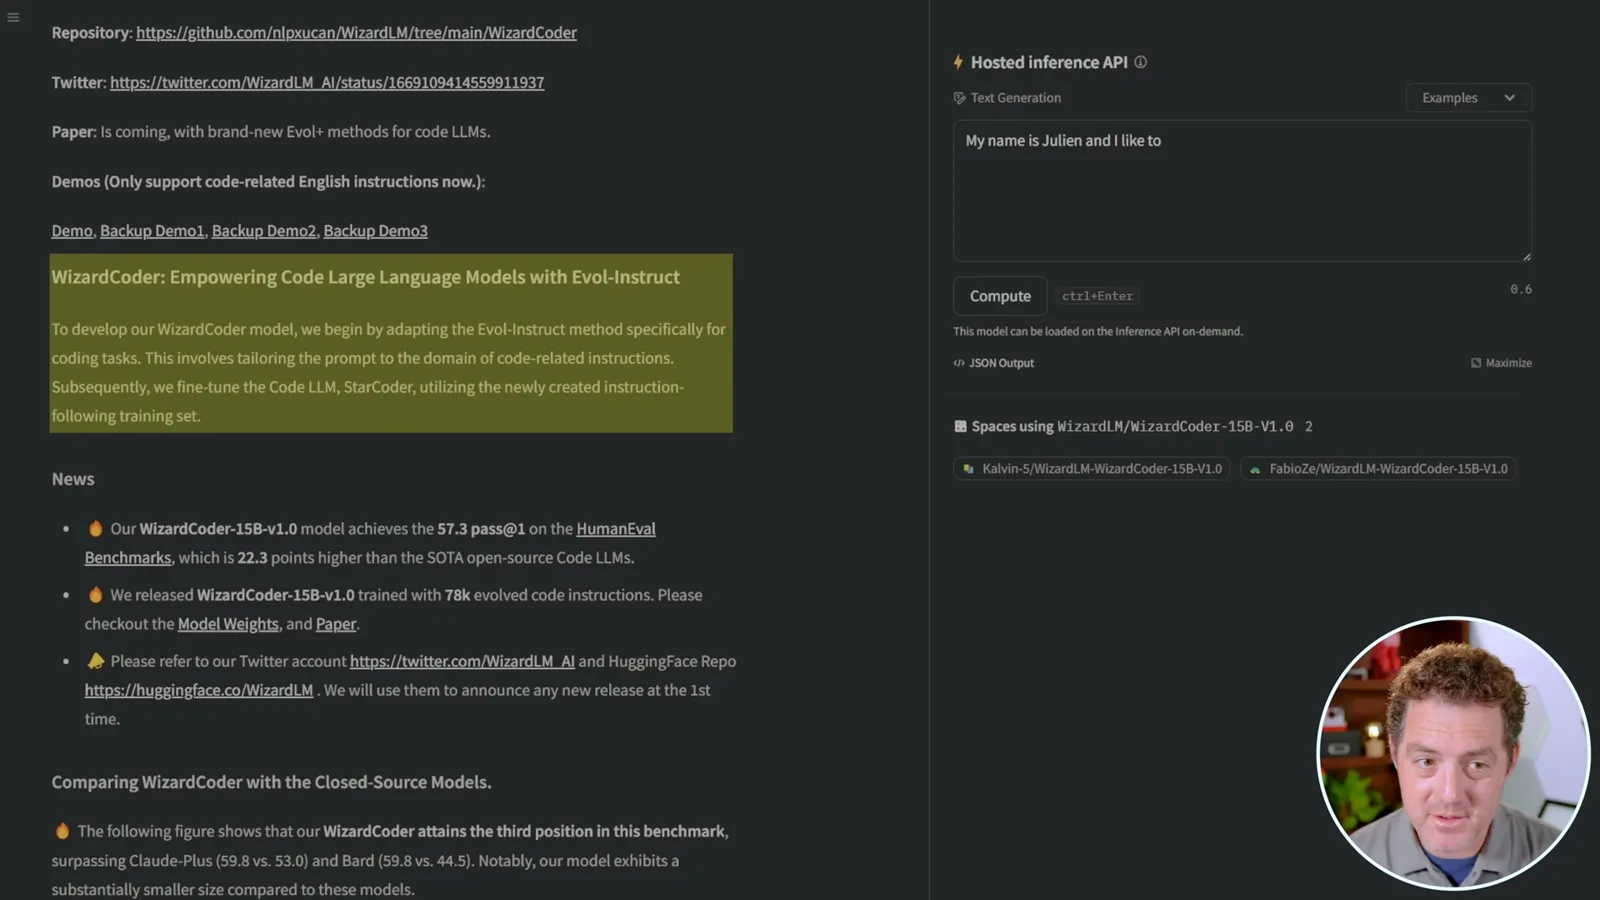
The WizardLM team describes adapting its Evol-Instruct method to code-related instructions, then fine-tuning StarCoder using the resulting instruction-following dataset. The model has 15 billion parameters. The authors’ displayed benchmark compares it favorably with other models available at the time, while placing it below GPT-3.5 and GPT-4 on the shown test; such results depend on the benchmark and settings.
I use a GPTQ version supplied by TheBloke. This quick tutorial assumes text-generation-webui has already been installed: in my conda environment, I start the server with `python server.py`, then select the WizardCoder 15B model from the interface. Exact commands and hardware requirements depend on the installation and model format.
Loading a local model
He starts a preinstalled text-generation-webui server and selects a GPTQ version. He then introduces the Python Principles exercises used for his informal tests.
For tests I use Python Principles, which lists programming exercises by difficulty. The first asks for the indexes of capital letters in a string. I copy the instruction into the model and set the maximum new tokens to 2,000. The generation is fast on my setup, though speed will depend on the machine.
Small coding challenges
The demonstration includes a strange output marker, a divisibility test, argument counting, and a thousands-separator function. Results differ depending on the prompt and the exercise.
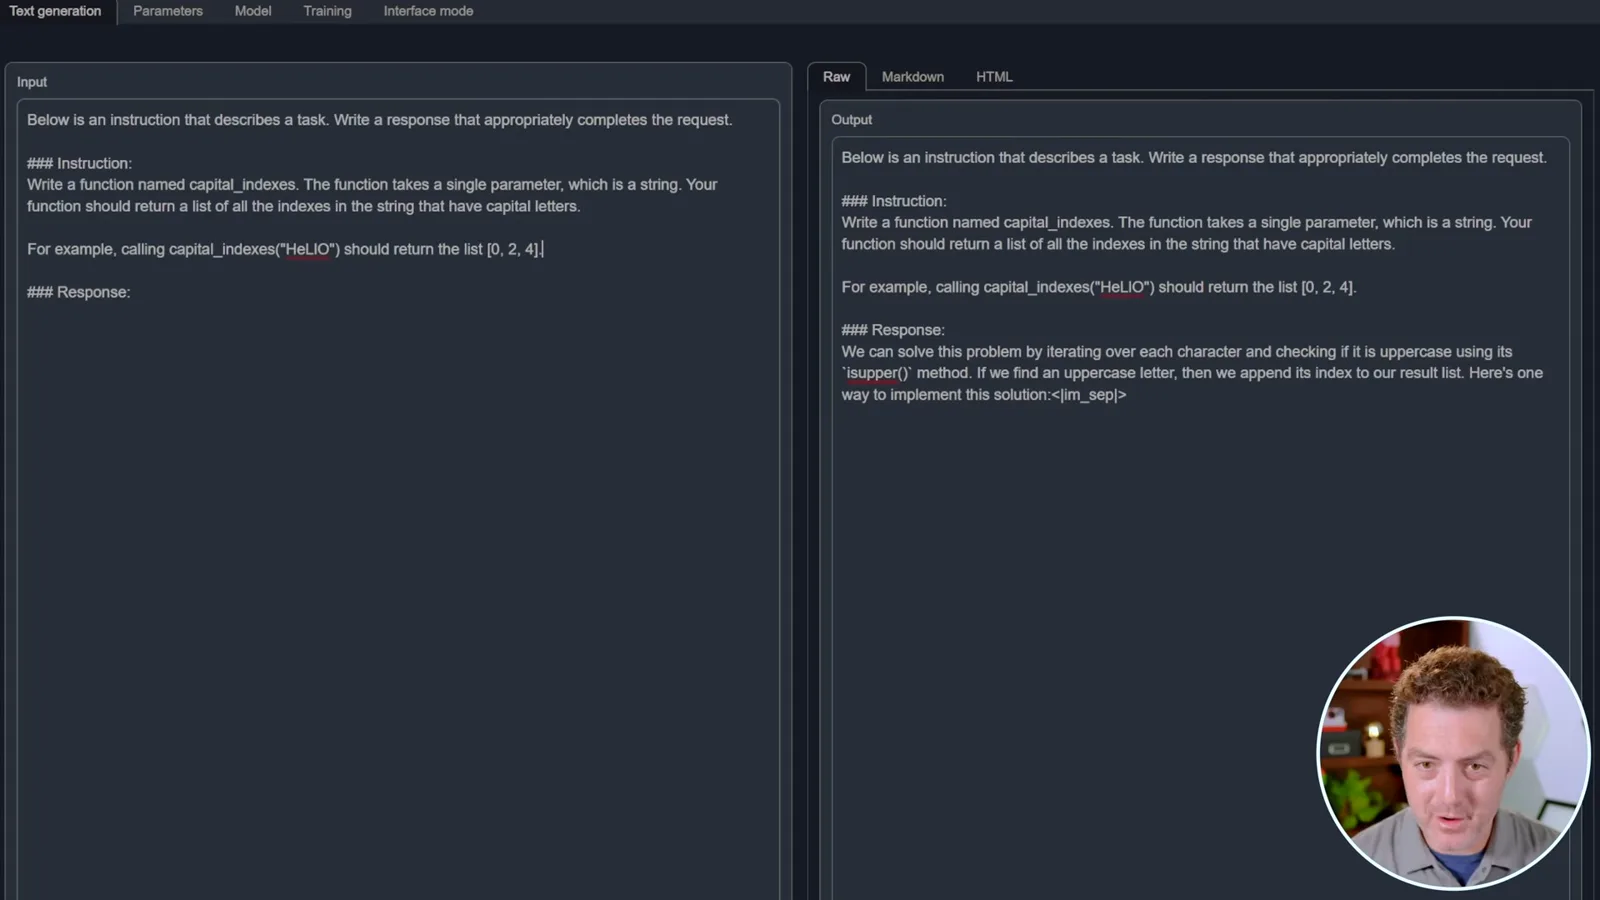
Sometimes the response ends unexpectedly with a special marker instead of the code. In my experiments, removing the example from the prompt and running it again can help. That is a workaround I observed in this setup, not a guarantee that examples should always be omitted.
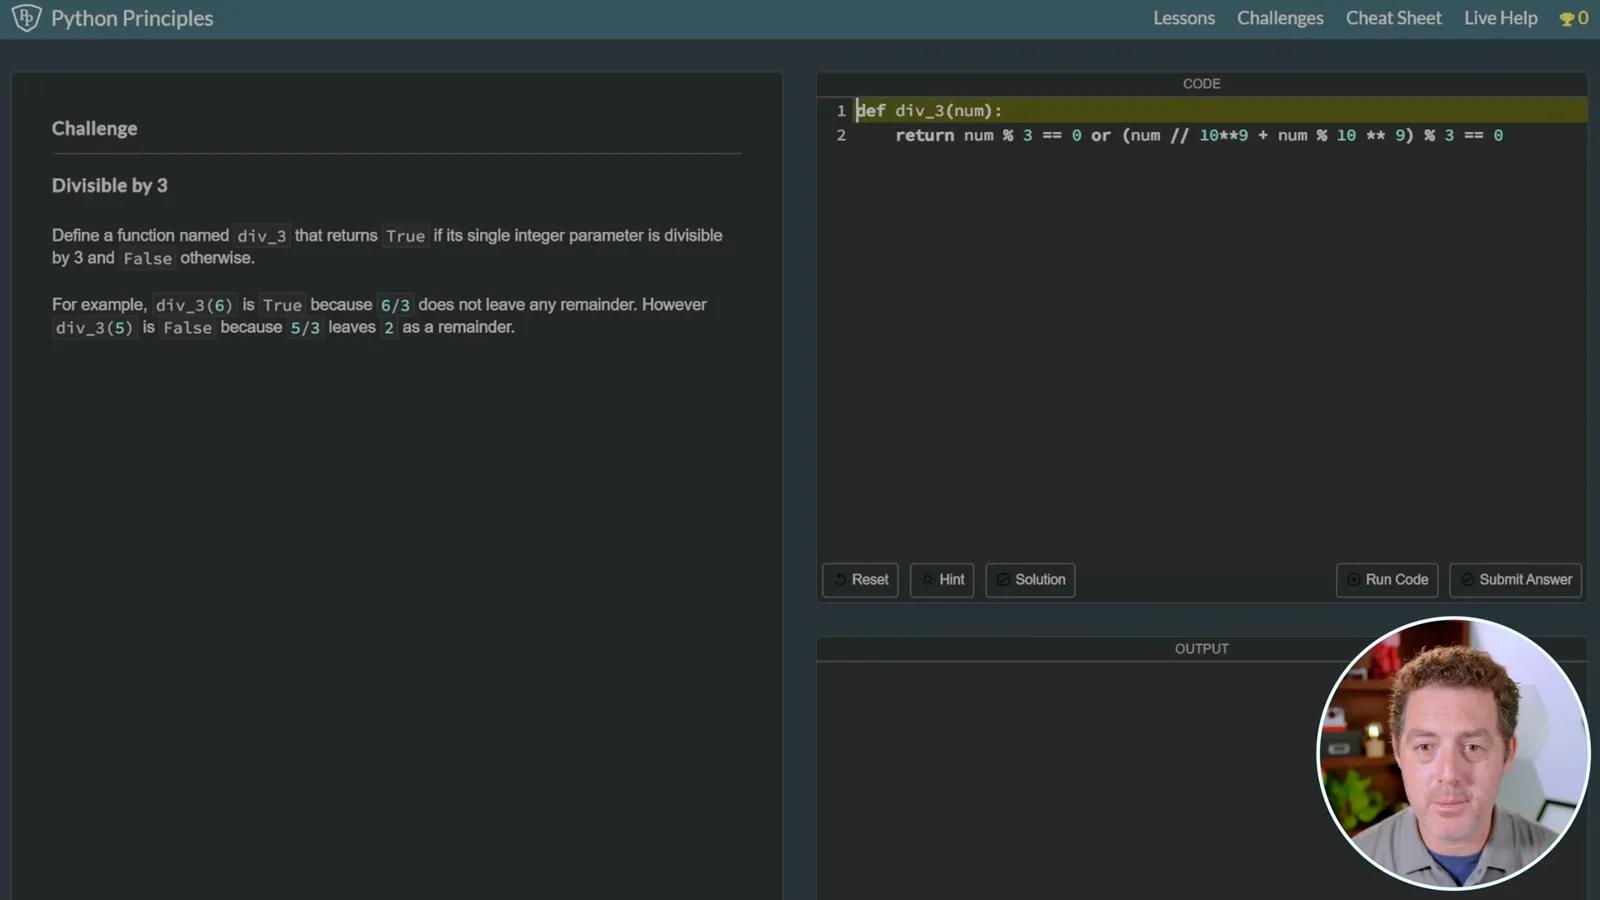
The next problem asks for a `div_3` function that returns whether an integer is divisible by three. The exercise site marks the generated answer correct. I also show an argument-counting problem, where a function accepts a variable number of arguments and returns how many it received.
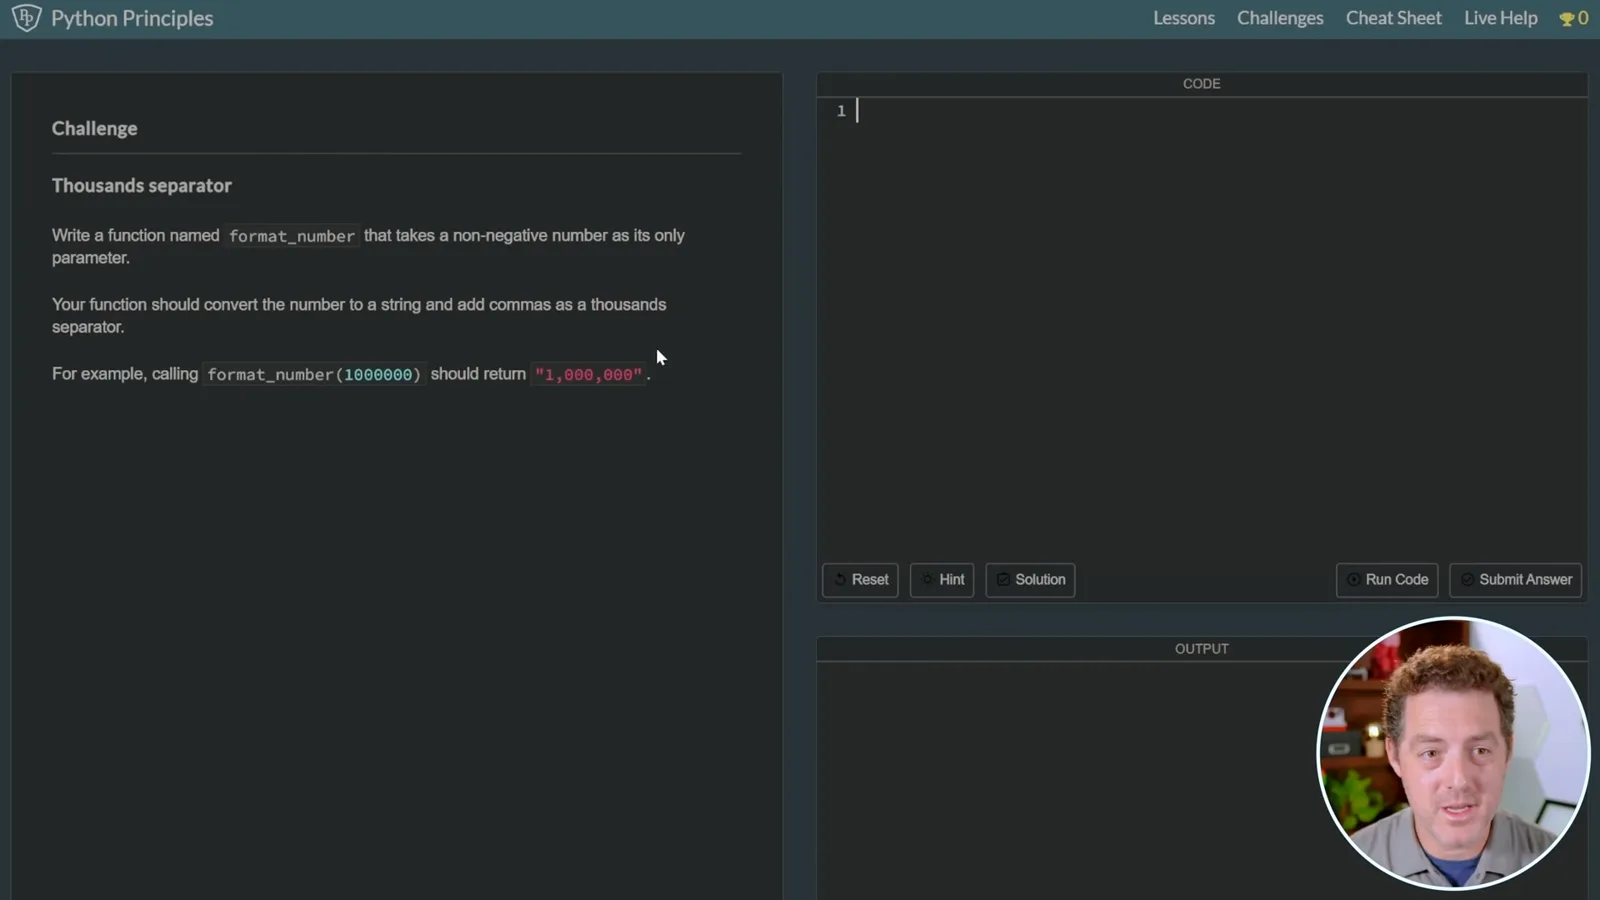
For a harder exercise, `format_number` must convert a non-negative number to a string with commas as thousands separators. I omit the example from the prompt, paste the generated function back into the challenge, and the site marks it correct. When I include the example in another attempt, the response is more complicated and produces an error.
A longer Snake program
Berman tries to generate a Python Snake game using the interface’s continuation feature. The resulting program does not work, informing his assessment of the model’s limits.
Next I ask for a Python version of Snake. In this interface I have a 2,000-token generation setting and can sometimes use the Continue button to extend the output; that setting is a feature of the demonstration, not a universal limit on local models. Continuation appears to work, but after I save the code in VS Code, the program does not run.
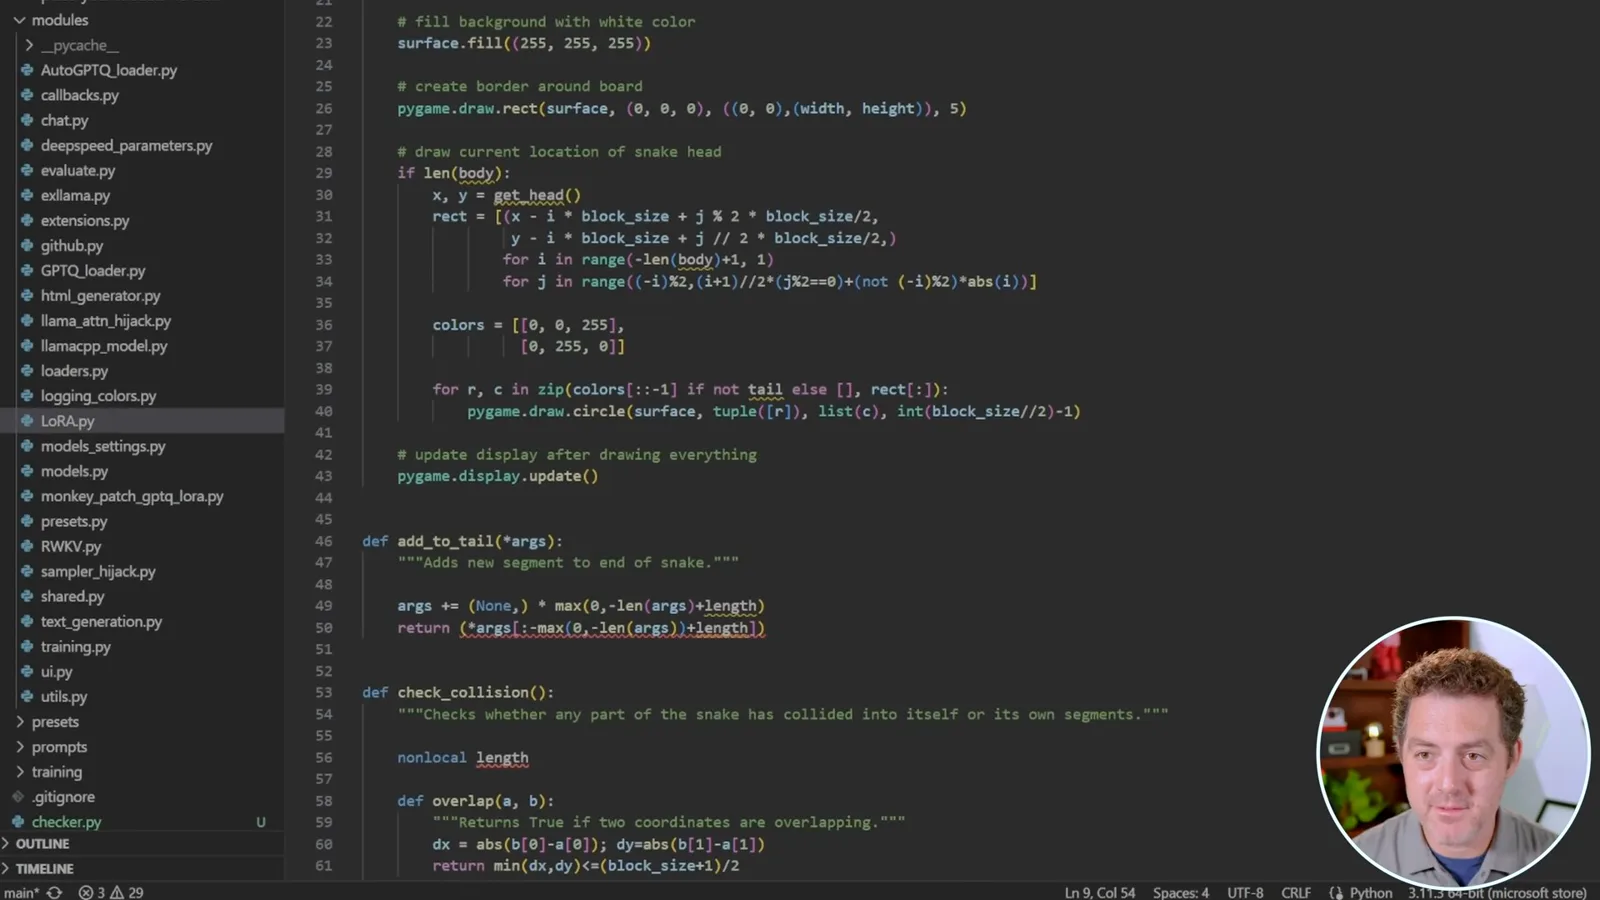
I decide not to debug the game further. From these limited tests, I think the model is useful for relatively small functions, including some more complex ones, but it is not at the level of GPT-3.5 or GPT-4 in my assessment at the time. The practical attraction is that it can run locally.
같은 채널의 다른 글
 14:45EN
 Matthew Berman· 2026년 10월 29일Matthew Berman Examines Google’s Gemini 4 Carbon AnnouncementMatthew Berman · Forward FutureMatthew Berman reviews Google’s reported benchmark results, staged rollout and pricing for Gemini 4 Carbon, while noting he has not yet used the model.
 34:21ENMatthew Berman· 2026년 10월 27일Matthew Berman Examines Anthropic’s IPO Filing, AI Growth and GovernanceMatthew Berman, Sam Altman · Forward FutureThe presenter reviews the S-1’s financial metrics, compute strategy and voting structure while questioning the tension between rapid AI development and safety.
 0:26ENMatthew Berman· 2026년 10월 25일Sam Altman on Human Values and Problem-Solving in an AI WorldSam Altman · OpenAIIn a short interview excerpt, Altman considers the enjoyment of solving hard problems and the human role in interpreting results.
 0:36ENMatthew Berman· 2026년 10월 25일Kimi K3.1 and a Rubik’s Cube Solver DemonstrationMatthew Berman · Forward FutureMatthew Berman shows a scrambled virtual cube being solved and gives the Kimi K3.1 test a favorable assessment.
 0:21ENMatthew Berman· 2026년 10월 24일An AI-Generated Kimi Benchmark Chart Used Invented ScoresMatthew Berman · Forward FutureMatthew Berman asks for a graph of Kimi K3.1 Pro benchmarks, then discovers that the displayed figures are illustrative placeholders.
 25:50ENMatthew Berman· 2026년 10월 24일Kimi K3.1 Pro Tested: Strong 3D Demos, Uneven Results and Competitive PricingMatthew Berman · Forward FutureMatthew Berman tests the open-weight model on coding, 3D rendering and visual explanations, then compares benchmark results and prices.