30초 요약
In this February 2026 short, Matthew Berman briefly reacts to Gemini 3.1 Pro, its rollout and a benchmark comparison. He highlights Humanity’s Last Exam scores under two different test conditions and says he wants to try the model in OpenClaw.
- 1Playful openingBerman jokes about unusual generated images and calls them important benchmarks.
- 2Rollout and testingHe says Gemini 3.1 Pro is shipping across consumer and developer products and wants to test it in OpenClaw.
- 3Humanity’s Last ExamThe displayed table reports 44.4% without tools and 51.4% with blocklisted search and code; Berman highlights the increase over Gemini 3 Pro.
핵심 정리
- Berman says Gemini 3.1 Pro is being rolled out across consumer and developer products.
- The displayed comparison reports 44.4% on Humanity’s Last Exam without tools and 51.4% with blocklisted search and code.
- The same table reports lower Gemini 3 Pro scores under both conditions.
챕터별로 다듬은 전문 읽기
Gemini 3.1 Pro and the rollout
Berman opens with a joke about unusual images. He says the model is coming to consumer and developer products and hopes to test it in OpenClaw.
Here’s an ostrich on roller skates, followed by a dachshund driving a stretch limousine. These are incredibly important benchmarks—this is basically AGI. Google is shipping Gemini 3.1 Pro across consumer and developer products, and I can’t wait to test it in OpenClaw.
The benchmark comparison
He highlights Humanity’s Last Exam scores under no-tool and tool-assisted conditions. He notes that the displayed results exceed those for Gemini 3 Pro.
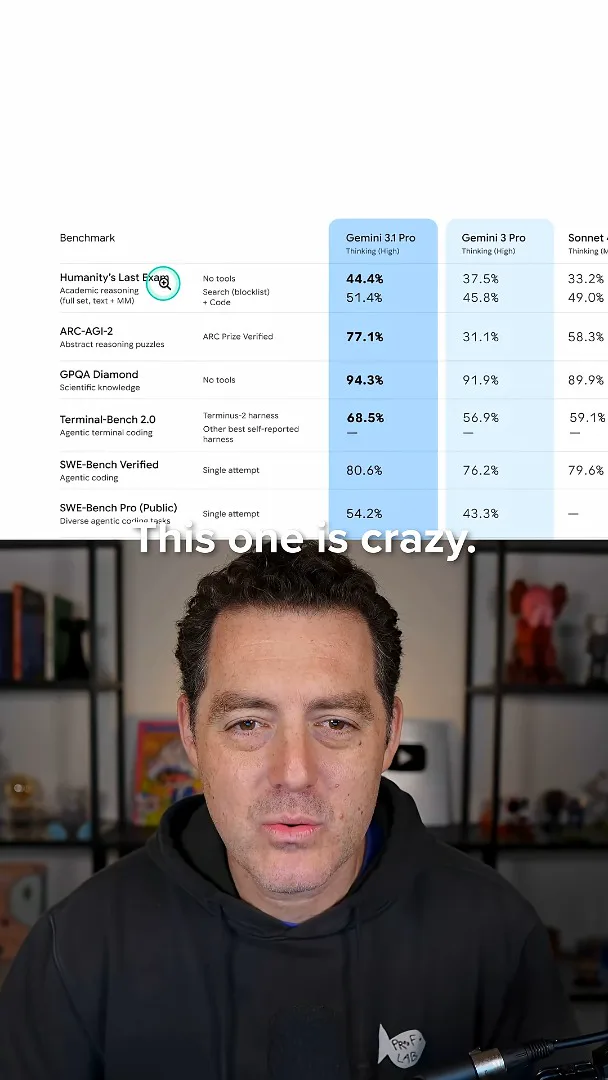
Look at the Humanity’s Last Exam comparison. The table reports 44.4% for Gemini 3.1 Pro without tools and 51.4% with search using a blocklist and a coding environment. That is a substantial increase from Gemini 3 Pro, which the displayed table lists at 37.5% and 45.8% respectively.
같은 채널의 다른 글
 34:21EN
 Matthew Berman· 2026년 10월 27일Matthew Berman Examines Anthropic’s IPO Filing, AI Growth and GovernanceMatthew Berman, Sam Altman · Forward FutureThe presenter reviews the S-1’s financial metrics, compute strategy and voting structure while questioning the tension between rapid AI development and safety.
 0:36ENMatthew Berman· 2026년 10월 25일Kimi K3.1 and a Rubik’s Cube Solver DemonstrationMatthew Berman · Forward FutureMatthew Berman shows a scrambled virtual cube being solved and gives the Kimi K3.1 test a favorable assessment.
 25:50ENMatthew Berman· 2026년 10월 24일Kimi K3.1 Pro Tested: Strong 3D Demos, Uneven Results and Competitive PricingMatthew Berman · Forward FutureMatthew Berman tests the open-weight model on coding, 3D rendering and visual explanations, then compares benchmark results and prices.
 32:20ENMatthew Berman· 2026년 10월 23일Who Is Local AI For? The Costs, Trade-offs and a Hybrid FutureMatthew Berman · Forward FutureMatthew Berman weighs data control and independence against hardware cost, setup complexity and inference speed.
 1:03:37ENMatthew Berman· 2026년 10월 23일Matthew Berman’s Team Tests Kimi K3.1 on Animation, Games, and ChartsMatthew Berman, Alex, Brian · Forward FutureA live team AMA turns into an informal test of Kimi K3.1, from personal-agent workflows to motion graphics, a browser game, and a benchmark chart.
 0:53ENMatthew Berman· 2026년 10월 22일Sam Altman on AI and the Discovery of New KnowledgeSam Altman · OpenAIAltman expects progress in mathematical discovery to extend to biology, materials and energy.