30 秒でわかる
CJ Avilla and Harrison Stall explain how Flows in Claude Managed Agents can plan multi-agent work through an API. They demonstrate a stock watchlist scanner, discuss allocating effort across phases, and describe Bug Hunter and explainer-video workflows. The workshop also covers evaluation, budgets, interrupts, shared filesystems, credential vaults and network restrictions. The speakers clarify limitations that applied at the time, including one layer of nesting; more agents and automated safeguards do not guarantee correct or safe results.
- 1A managed flowA lead agent plans work and the platform runs phases through an API.
- 2Watchlist scanningThe demo separates ticker research and review into contexts.
- 3Budgets and interruptionsThe session can pause on budget and be redirected by an operator.
- 4Shared filesystem limitsSeparate agent contexts are not per-directory access controls.
- 5Bug HunterIndependent readers and later reproduction phases help surface candidate issues.
- 6Credential boundariesA vault can inject a secret at egress, while returned tokens require separate care.
- 7Nesting limitThe speakers clarify that the described implementation supported one level of nesting at the time.
ポイント
- Split suitable work into bounded phases and evaluate the results.
- Measure the quality and cost of multi-agent runs against the actual task.
- Keep budgets, interrupts and independent observation available.
- Separate context isolation from filesystem and network permissions.
- Protect credentials outside the sandbox and account for secrets returned by services.
- Use human review and explicit controls for consequential actions.
チャプターごとに整えた全文を読む
Coordination at scale
Avilla uses engineering history to introduce multi-agent coordination.
CJ Avilla opens with the contrast between a small project held in one person's head and the coordination needed for a much larger engineering effort. He uses early Unix and IBM's OS/360 as historical illustrations.
He recounts how Fred Brooks drew organizational lessons from the large OS/360 project, including the idea of a small expert team preserving conceptual coherence.
Avilla then describes the growth of Linux contributions and the difficulty of having every change go directly to one person. He compares the resulting bottleneck to a human managing many coding agents.
The model he describes is a network of trusted maintainers that review work before exceptional cases reach the top. His analogy motivates the question of how multiple agents can organize work.
Avilla and Harrison Stall introduce themselves as Anthropic members of technical staff. Their workshop combines an overview, demonstrations and hands-on exercises.
Flows and managed agents
Stall describes API resources, phases, budgets and event streams.
Stall introduces Flows in Claude Managed Agents as an API-based way for a lead agent to plan and coordinate a multi-agent workflow. Product details in this article reflect the workshop at the time it was recorded.
The presenters contrast dynamically chosen workflow shapes with manually wiring every agent and dependency. They describe parallel work and synthesis as patterns the system can select for an appropriate task.
They argue that a single agent or a single coordinator can become constrained on ambitious tasks. This is their motivation for multi-agent structures, not a guarantee that adding agents always improves results.
Stall lists challenges in custom orchestration: recovering failed containers, coordinating many workers and seeing the state of the whole graph. Managing the infrastructure can be difficult even before judging the output.
Managed Agents is described as an API that stores agent resources and manages session lifecycles. An agent configuration can contain tools, skills and MCP servers, and an event log records activity.
The earlier multi-agent setup required users to define a roster of sub-agents and manage their threads. Flows aim to let the lead agent plan phases and choose workers as the task unfolds.
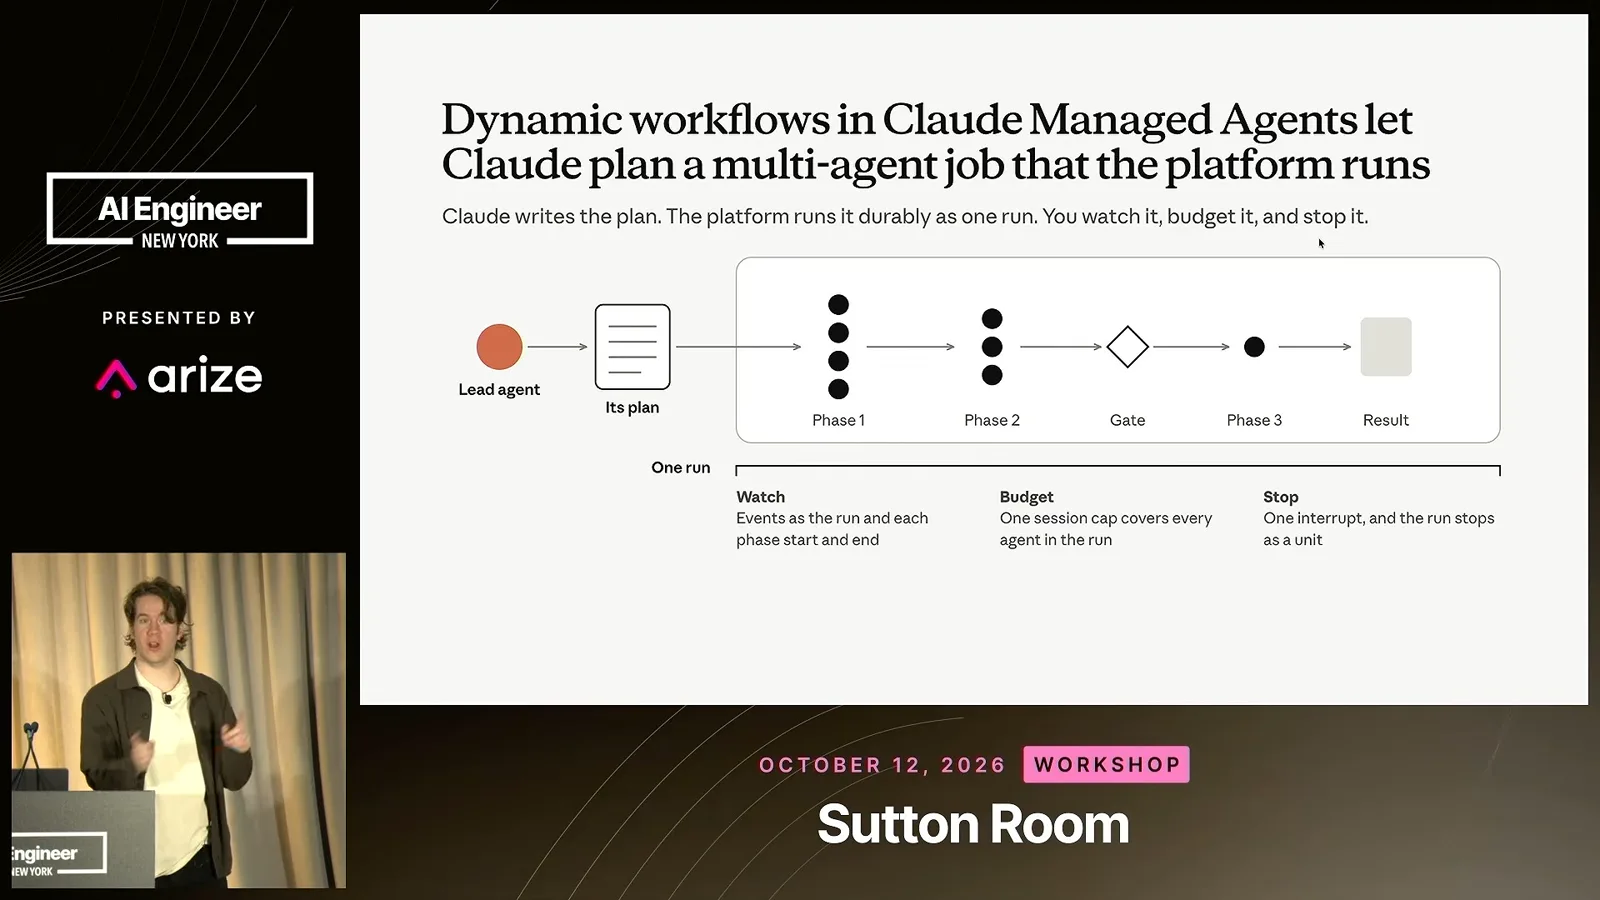
A phase might fan out work across isolated contexts and then pass results into another phase. The presenters describe the units as separately verifiable, while verification quality remains the application's responsibility.
The platform exposes an event stream, session budgets and an interrupt mechanism. These are intended to help an operator observe spending and stop or redirect a running workflow.
The speakers distinguish interactive Claude Code workflows from an API surface that can be integrated into applications, scheduled jobs or webhook-driven processes.
Watchlist scanner demonstration
The presenters discuss isolated research, review and cost.
Stall demonstrates a stock watchlist scanner template in the console. The agent is configured with an environment and given a list of tickers to research; the example is a workflow demonstration, not investment advice.
The session shows a lead agent and multiple parallel threads. Stall inspects a prior run to show how workers are created and their progress appears in the interface.
Avilla explains that teams can prototype in the console and then integrate a flow into their own product or schedule. An application might trigger a scan at a selected time or through another interface.
The example enables multi-agent behavior in configuration and asks for a workflow. Users can also configure specialized sub-agents and provide custom skills, tools or MCP servers.
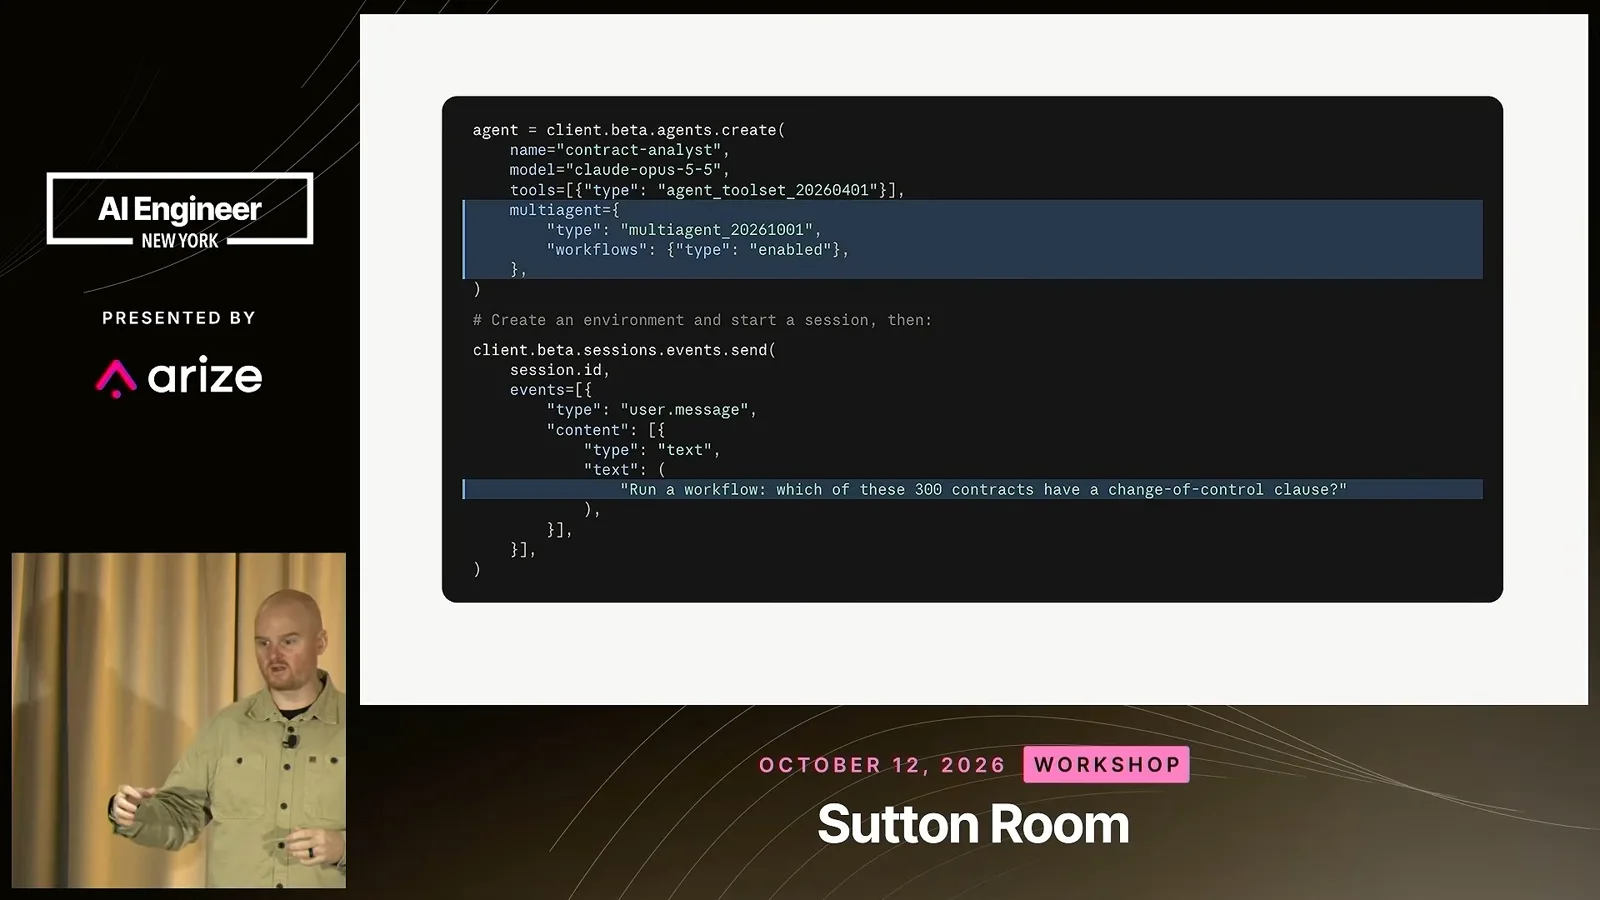
The watchlist example assigns each ticker to an isolated scan context, then passes results to a separate review phase. Isolation can reduce cross-task interference, but does not establish that every fact is correct.
The presenters say their example found more details with a flow but cost more than a single-agent run. They recommend a representative evaluation set to assess the quality and expense for the actual task.
A team can allocate different models or numbers of workers to different phases—for example, inexpensive scanning followed by a more intensive review. The right allocation depends on measured performance.
The presenters suggest starting with a clear objective and letting the system propose a flow, then refining it. A loose prompt is an experiment, not a substitute for explicit constraints or evaluation.
Questions on integration and control
They discuss tools, memory, visualization, budgets and isolation limits.
In questions, they explain that a local or cloud Claude Code session can call the separate Managed Agents API to create resources and start work. The two execution environments are distinct.
Individual resources such as skills can be supplied to the API, but the speakers say distributing an entire generated flow as a plugin was not supported at the time. They suggest retaining its text configuration.
Custom tools can hand work to another environment, such as a local computer, and return a result. The integration owner is responsible for implementing and controlling that external action.
Asked about cost optimization, Stall suggests inspecting execution transcripts for unnecessary work and comparing changes against desired criteria. Agent-suggested improvements still need independent evaluation.
Avilla describes a memory process called Dreaming that can use previous sessions to update a memory store. They present this as one option for learning from repeated runs, not a guarantee of improvement.
The console can visualize the running topology, and the API exposes individual thread events. Developers can build their own interfaces for handoffs, tool calls and outputs.
At the time of the talk, the model was not told its remaining budget. The budget acted as a guardrail; when reached, the session could pause and an operator could decide whether to extend it.
The speakers say sub-agents have separate context threads but share a filesystem. They describe the shared filesystem as one possible communication channel, while noting that the API did not expose a direct command to force one worker to message another.
They discuss iterating on prompts using past runs and evaluations. Scheduled deployments do not automatically self-improve simply because they are scheduled; a team would need to design such a process.
Asked about scientific research, the speakers speculate that more test-time compute may help with difficult problems. They do not establish that the demonstrated workflow solves any particular open scientific problem.
Avilla says a flow could use up to 1,000 agents in the configuration available at the time. His operating-system experiment had run for days and was still unfinished during the workshop.
Asked about diminishing returns, Stall says he does not have a reliable quantitative answer. Coordination costs and quality should be measured rather than inferred from agent count.
Budgets can limit runaway spending, and the speakers report that a coordinator may detect some misbehaving workers. Neither mechanism proves all loops or cascading errors are prevented.
For conditional execution based on an external change, Stall suggests putting detection in the application layer. He says a large flow is unlikely to be the right choice for a trivial task a single agent can finish quickly.
Each sub-agent receives a separate context thread and can have its own system prompt. However, separate context windows should not be confused with filesystem access control.
Asked about directory isolation on the shared filesystem, Stall says there was no built-in per-directory permission layer in the described setup. Prompting alone is not a security boundary; tool-permission checks are one possible additional control.
For human feedback during a flow, the speakers suggest a custom tool that requests input. An operator can also interrupt a session and provide new information rather than discarding all prior work.
Avilla says his long-running experiment writes documentation after phases, making intermediate progress inspectable. Outputs and repository commits can provide additional artifacts to review.
The speakers say that at the time, a user could interrupt and restart a flow with new information, but could not insert an individual step into an existing plan and simply replay its later steps.
They discuss using the event stream to build product interfaces and telemetry. Image input was supported in the example, but they caution that the experience might not be suitable for real-time game interaction.
For sharing agent definitions, the speakers mention export and infrastructure-as-code, while saying a one-click sharing mechanism was not available in the described API at that time.
Asked how much parallelism to use, they suggest low defaults and evaluations. A small task should not consume a thousand agents simply because the limit permits it.
Avilla suggests progressively revealing relevant documentation to sub-agents, such as an index that points each worker to the files it needs. This can reduce unnecessary context without putting credentials in those files.
Bug Hunter and Explainer Studio
They describe code-review and video-generation workflows.
The Bug Hunter example splits code into slices for independent readers, gathers candidate issues, and uses later review and reproduction phases. Its report is meant to help human review, not guarantee a bug-free change.
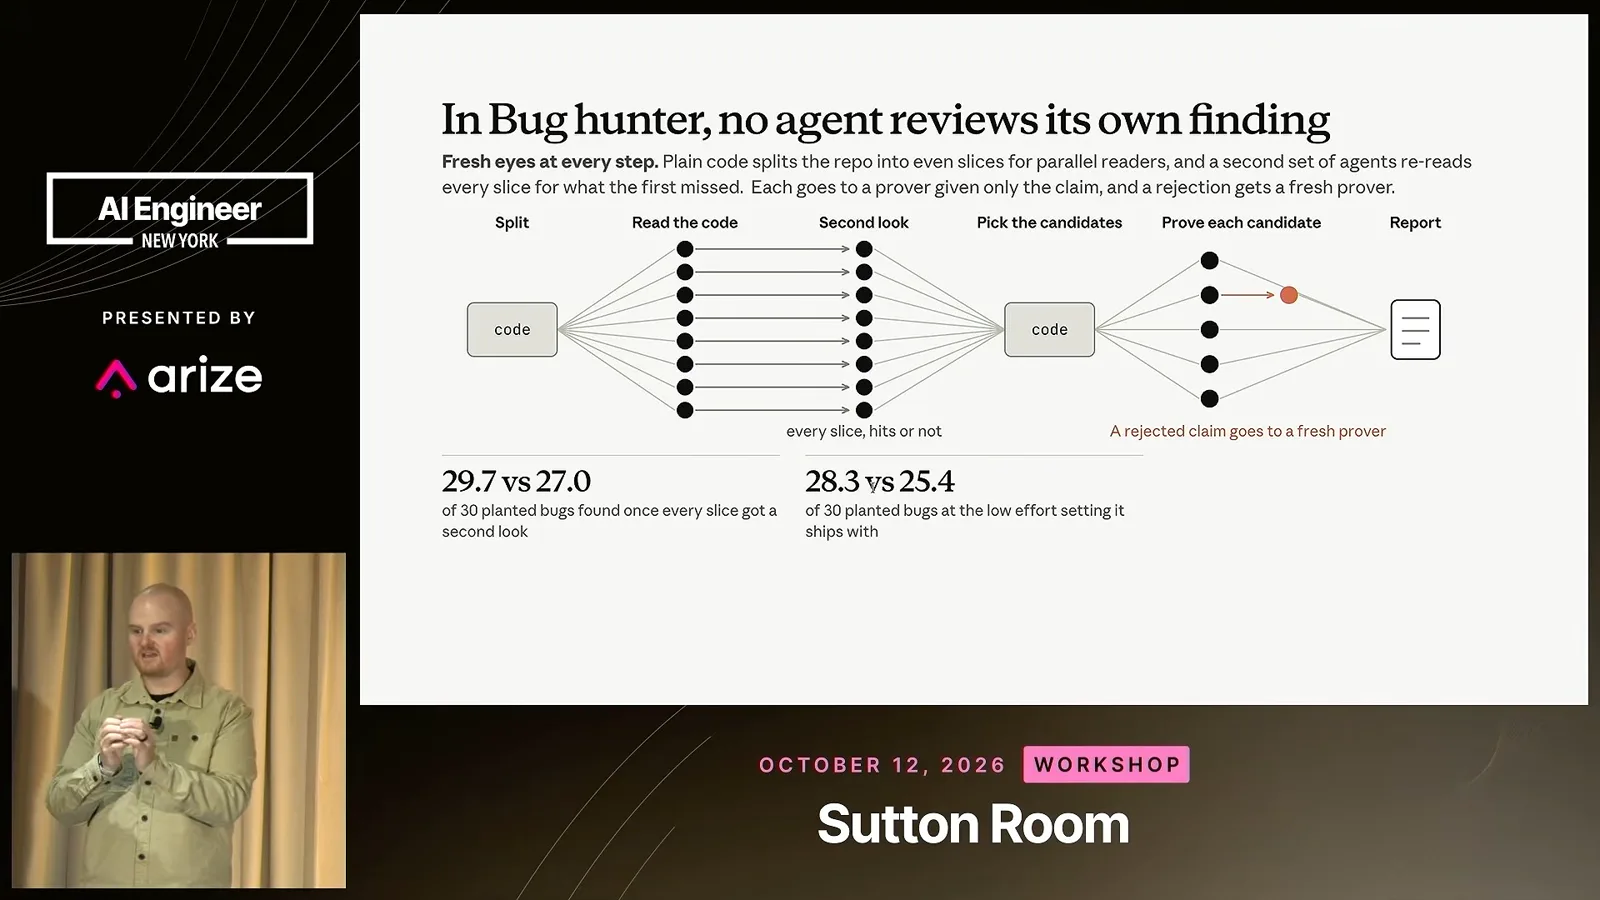
A prover can inspect the repository and try to reproduce a candidate bug, including an interaction with code outside the changed file. Findings can then be reported with supporting context.
The Explainer Studio example uses research, planning, fact-checking and production phases to create animated explainers. The presenters describe their use of it for videos, with additional work on narration and sound.
Failure modes and safety
They discuss drift, independent review, injection, vaults and containment.
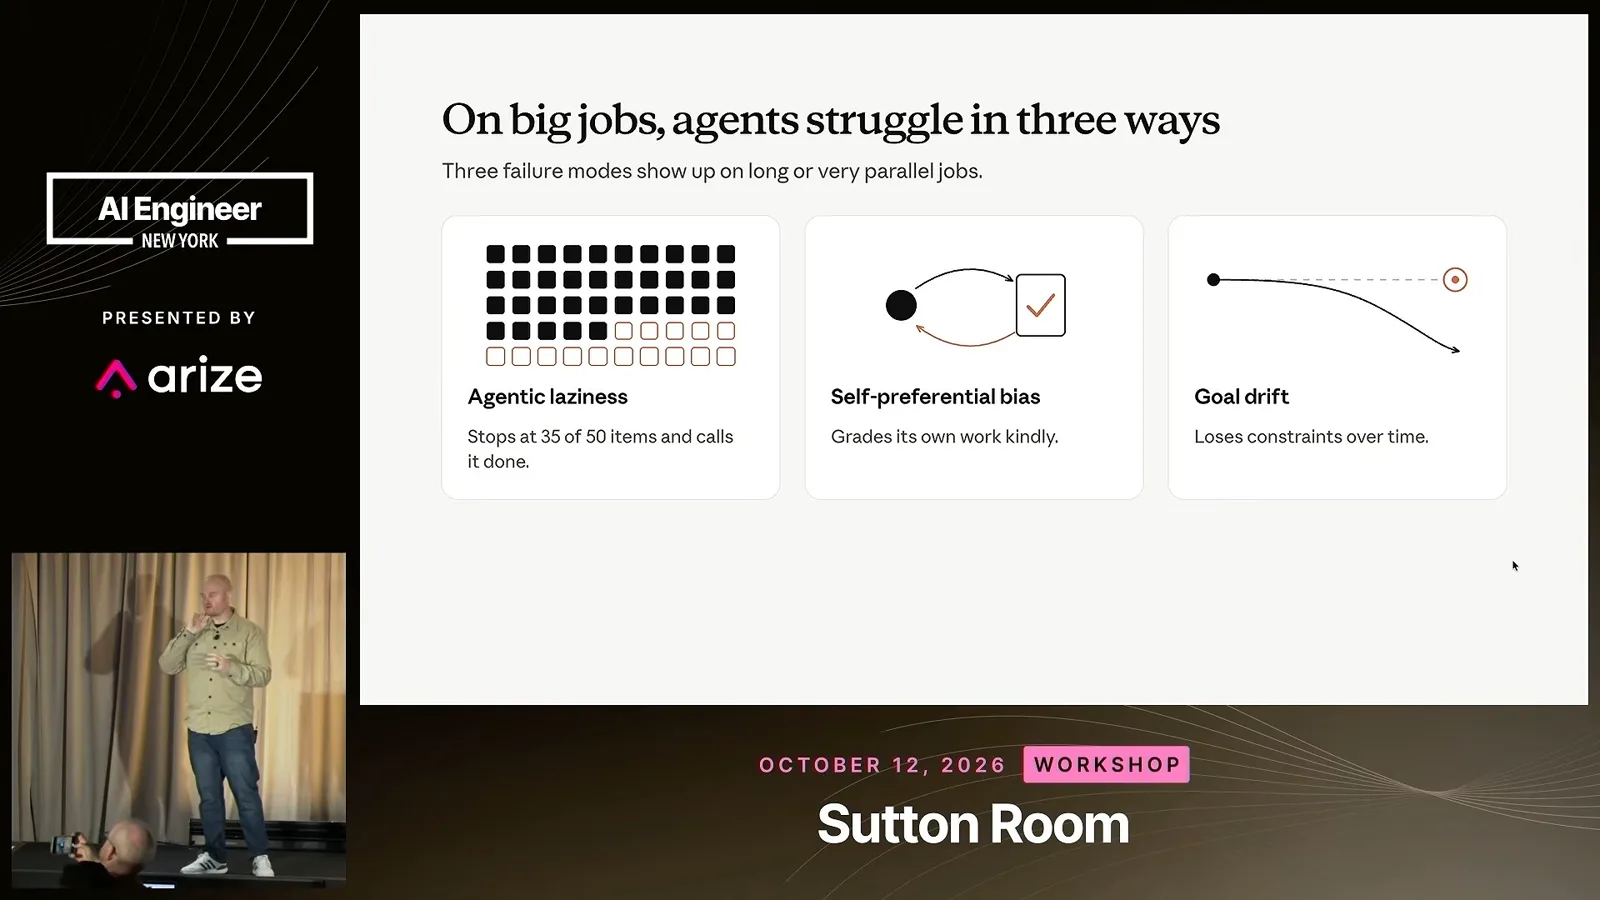
The presenters identify three common failure modes: stopping before checking every item, favoring one's own output and drifting away from the original goal. Separate scopes and review phases are proposed mitigations, not guarantees.
In an outage example, a single agent might inspect some healthy services and stop early. Assigning a bounded check to each service can make coverage easier to inspect, but the checks still need to run and be verified.
An independent reviewer may reduce self-preference, while passing the original objective and constraints to each stage can help reduce drift. Both practices depend on implementation and evaluation.
Stall moves to safety at scale: untrusted web content can contain prompt injection, exposed credentials can be misused, and sensitive data can leave through permitted tools or networks.
He groups the operator's work into declaring permissions, containing what an agent can reach and detecting unexpected behavior. An event stream can help investigation, but monitoring must actually be configured and acted upon.
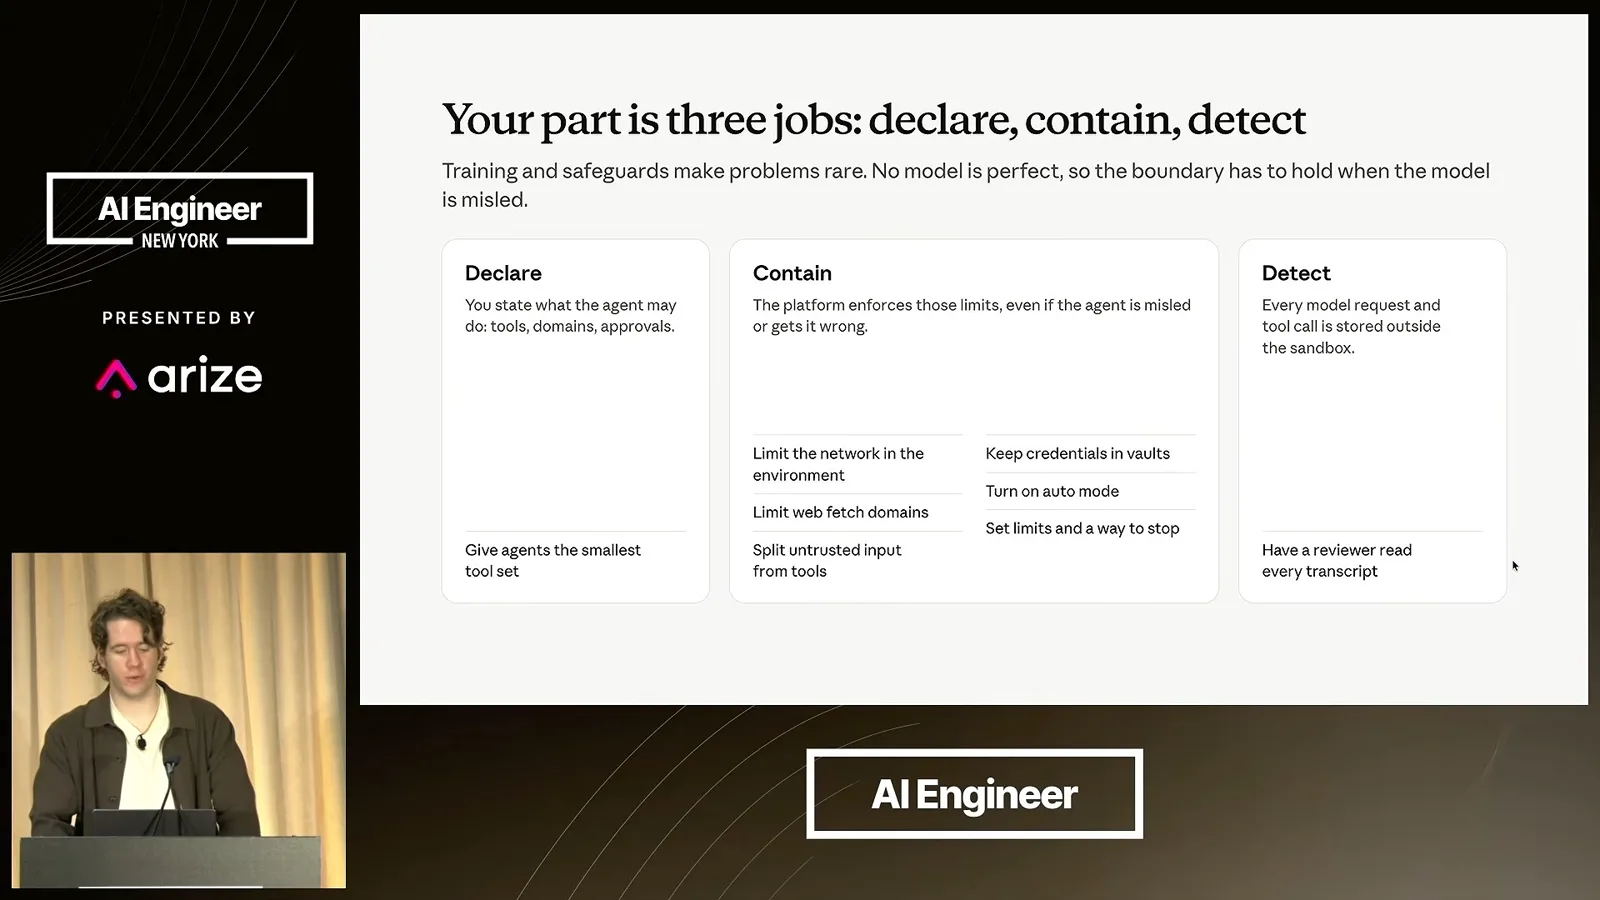
The presenters describe separating the reasoning and session state from the sandbox where actions occur. In their design, placeholder credentials are replaced by real values at an egress proxy for configured destinations.
Budgets and interrupts provide two different controls: one limits spending, while the other lets an operator stop a session and redirect it. A budget is not a substitute for controlling actions.
They suggest reviewing durable event records for unexpected tool use. They also discuss automated permission checks and approval fatigue; automated classifiers can make mistakes and do not replace a risk-appropriate policy.
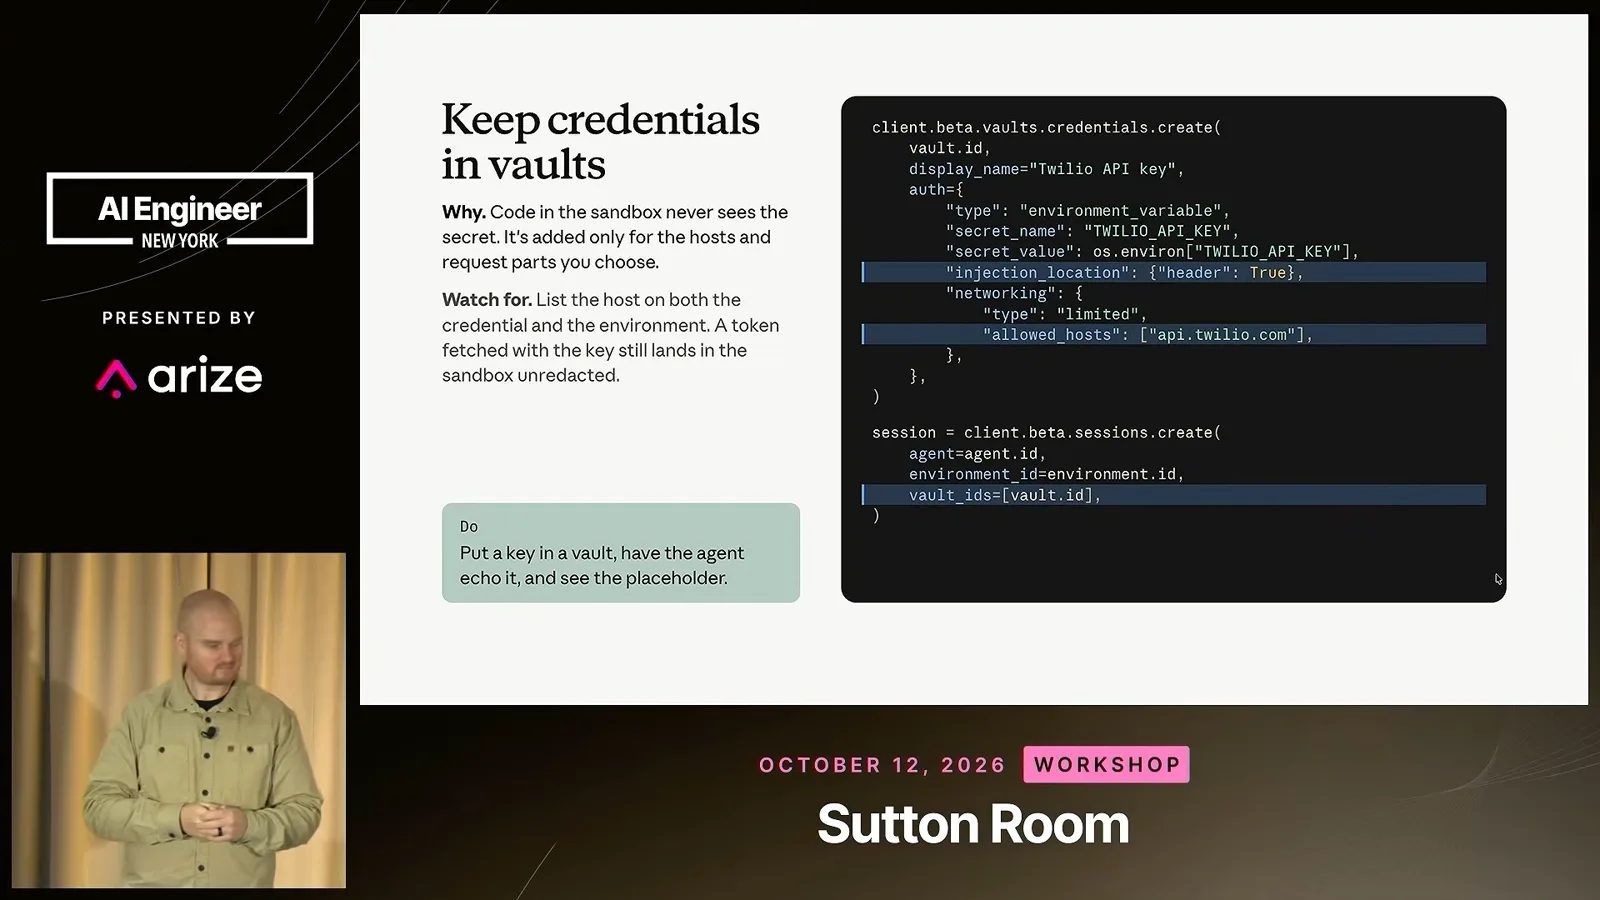
A vault example restricts where a credential is injected. The slide notes an important limit: a token returned by an external service can still enter the sandbox, so secrets in responses need separate consideration.
They recommend minimizing the tool set and limiting network destinations. MCP servers may expose changing tools, so permissions should be checked at the level appropriate to the integration.
Closing questions
The speakers clarify integration choices, dependency graphs and nesting limits.
In closing questions, Avilla suggests iterating with human feedback for subjective artifacts such as videos, then encoding a reusable process and evaluating it. Human preference remains part of that loop.
They repeat the distinction between an interactive one-off workflow and an API-integrated flow used by an application or schedule. The choice depends on the intended interaction and deployment.
The event stream can power a custom UI that shows messages and tool calls. The presenters describe it as a generic integration surface rather than a specific guarantee of correctness.
Asked about multiple repositories, they say the agent can inspect mounted code and existing dependency information. Supplying a known dependency graph may save work, but the output still needs review.
A speaker clarifies an important limitation: at the time, the described flow supported one layer of nesting, not arbitrary nesting. Earlier broad claims about complex hierarchies should be read in light of that clarification.
For resources behind a private network, the presenters discuss using an MCP tunnel as one possible integration path. Access and network rules still need to be designed for the organization's environment.
The workshop ends with remaining questions and a reminder to test the controls and workflow on the intended task. The examples show possible orchestration patterns, not proof that more agents always produce a better result.
同じチャンネルの記事
 21:32EN
 AI Engineer· 2026年10月29日Shy Ruparel on AI agent reliability and recovery after failuresShy Ruparel · TemporalTemporal’s survey finds a gap between frequent agent use and dependable deployment. Ruparel demonstrates a synthetic payout workflow that resumes after workers stop.
 14:50ENAI Engineer· 2026年10月29日Cole Gannaway on code review, cross-repository risk and AI software factoriesCole Gannaway · QodoA one-line rename can pass local checks while affecting distant clients. Qodo’s Cole Gannaway explains how review context, shared rules and independent agents can expose those risks.
 11:47ENAI Engineer· 2026年10月29日Revolut’s David Abitbol on self-hosting AI coding models at scaleDavid Abitbol · RevolutAbitbol shares engineering delivery trends, GPU-serving costs and latency tuning, then describes controls for operating the tools in a regulated bank.
 21:47ENAI Engineer· 2026年10月28日Patrick Smyth on Open-Source Supply Chain Security in the AI EraPatrick Smyth · ChainguardChainguard’s Patrick Smyth discusses faster exploitation, malware in dependencies, zero-days and the expanding attack surface around developer workflows.
 14:09ENAI Engineer· 2026年10月28日Taylor Luttrell-Williams on Finding Logic Vulnerabilities with SonarQube Hunter AgentTaylor Luttrell-Williams · SonarSonar’s Taylor Luttrell-Williams explains how a security agent maps a codebase, investigates logic flaws and presents validated findings alongside conventional scans.
 16:29ENAI Engineer· 2026年10月28日Chris Vela on Benchmarking vLLM Configurations with Runpod BenchPodChris Vela · RunpodRunpod’s Chris Vela demonstrates a dashboard for comparing LLM serving configurations and choosing performance settings with workload-specific data.