30 秒でわかる
Before receiving access to image input, Matthew Berman reviews examples shared by early users: cartoons, diagrams, recipes, parking signs, sketches, software interfaces and more. The examples illustrate possible workflows but are selected demonstrations rather than an accuracy study; an incorrect poker hand and several unchecked outputs reveal important limits.
- 1Interpreting a cartoonA model describes a four-panel illustration as a story about misunderstanding and communication.
- 2Parking signsA response interprets multiple restrictions, but the video does not independently establish whether the answer is lawful or correct.
- 3Image to codeA dashboard screenshot becomes a prototype, which still needs review and testing.
- 4A leading promptThe model agrees that a logo appears only after the user explicitly names it; this is not proof of independent recognition.
- 5A poker errorThe image shows four fours, while the model describes three of a kind.
ポイント
- Image input can support questions about illustrations, documents and visual designs, but explanations require verification.
- A plausible recipe or image interpretation is not proof of details that the image cannot establish.
- Generated code can accelerate prototypes but still needs testing and integration.
- A leading prompt can influence a model’s answer, so agreement after prompting is not independent recognition.
- The poker example miscounts four of a kind, demonstrating that visual answers can be confidently wrong.
- The historical 2023 examples do not establish current product availability or performance.
チャプターごとに整えた全文を読む
Early image understanding
Berman reviews examples shared during the 2023 rollout, before he has access himself. They include a cartoon, a cell diagram and food.
In October 2023, I collect early examples of ChatGPT's image-input capability while waiting for access myself. [OpenAI began rolling out image and voice features](https://openai.com/index/chatgpt-can-now-see-hear-and-speak/) in September 2023. These selected social-media demonstrations show possibilities, not a systematic accuracy evaluation.
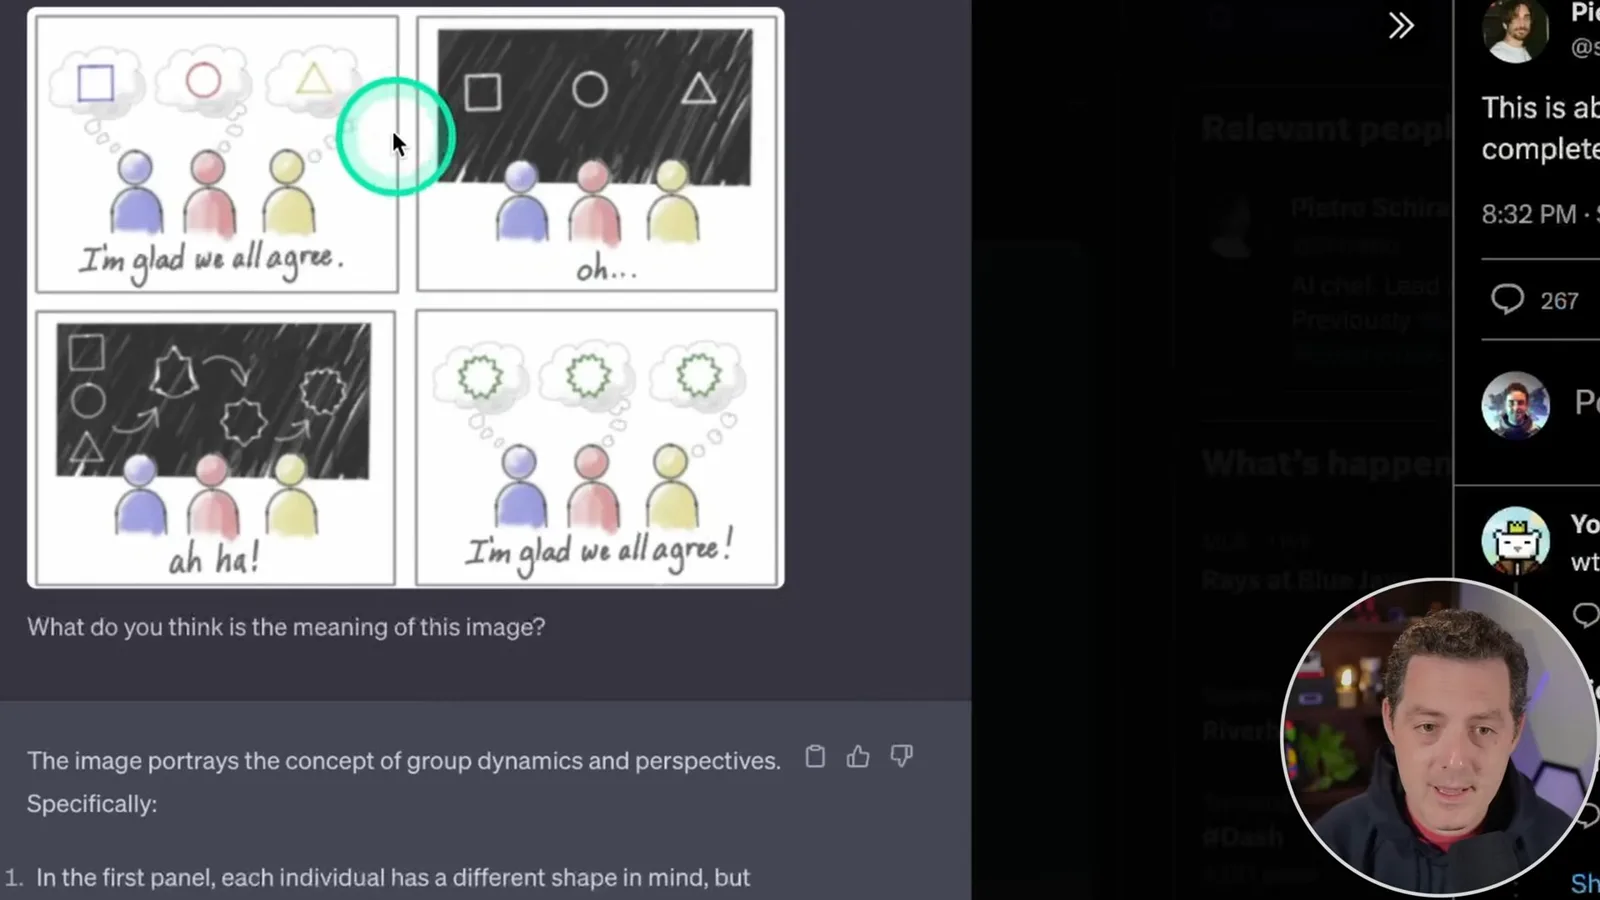
Pietro Schirano shares a four-panel cartoon about people who think they agree but imagine different shapes. ChatGPT interprets the panels as a lesson about communication and reaching shared understanding. I am impressed that its response goes beyond listing visible objects, although an interpretation is not necessarily the only possible reading.
McKay Wrigley shows a cell diagram being explained for a student, with a list of organelles and their functions. I imagine learners uploading textbook illustrations and asking for simpler or more detailed explanations. A generated description still needs to be checked against reliable educational material.
In a food example, Brian Roemmele asks for a recipe from a photograph of a dish. The model supplies a plausible recipe, which could serve as a starting point; a photo alone cannot establish the exact ingredients or preparation used by the original cook.
Diagrams, design and education
Users ask about circuits, room design, brain diagrams, parking signs and textbook exercises. Several answers are not independently checked.
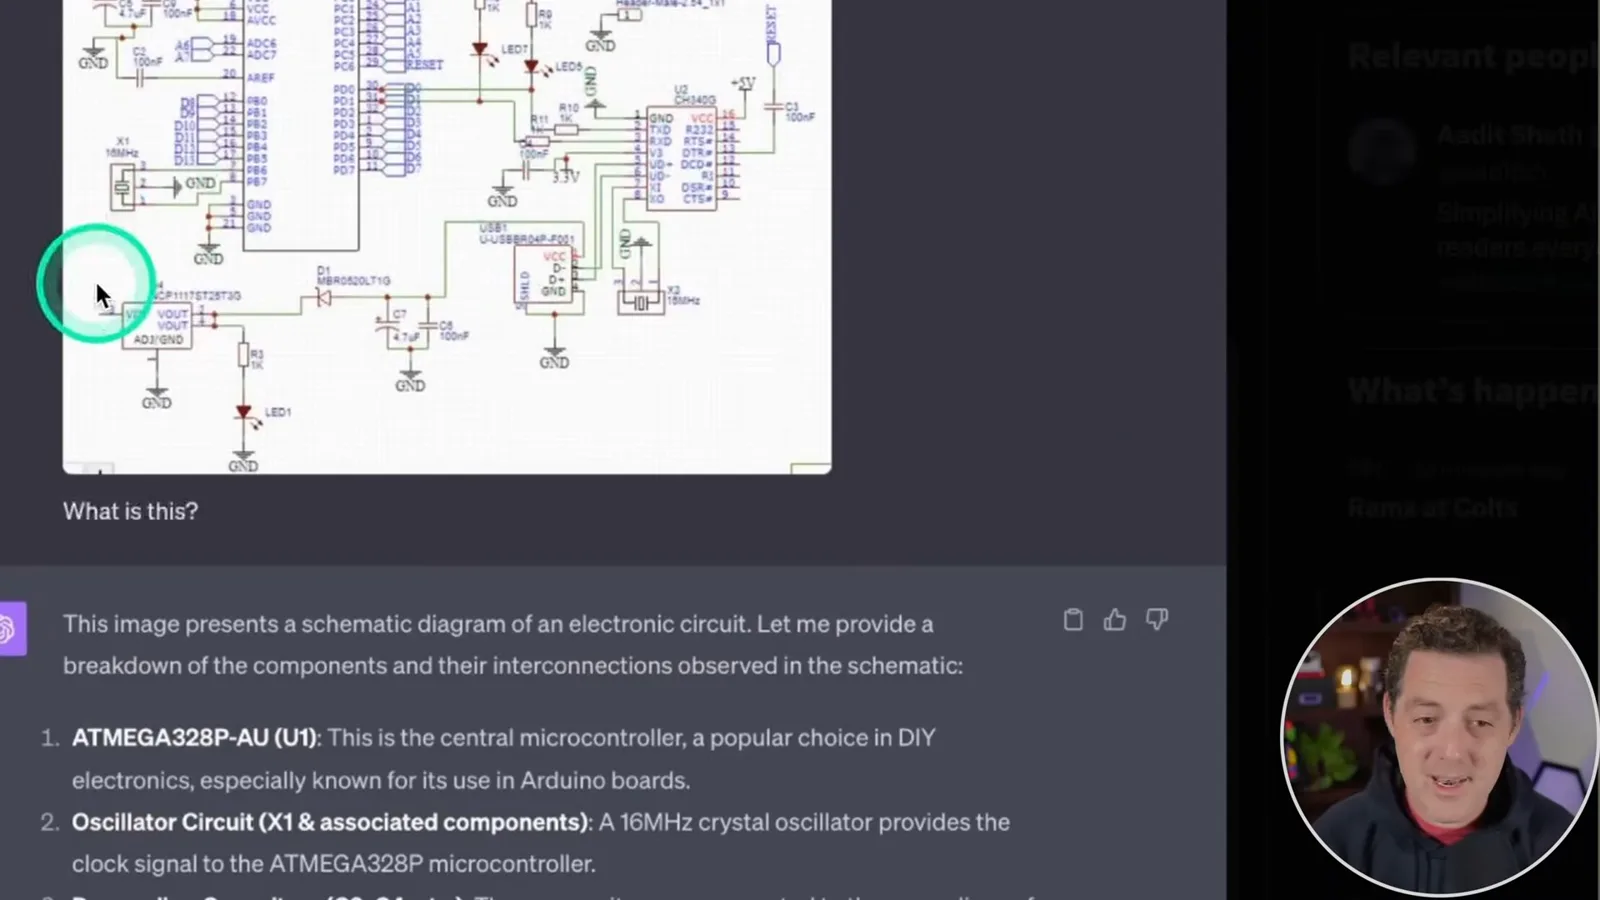
Aadit Sheth shares an electronics schematic and asks what it shows. The response describes components such as a microcontroller, oscillator, capacitors and USB connector. The example suggests a way to explore a circuit, but a generated explanation is not independently verified by this demonstration.
Schirano uploads a mushroom image and asks for a simulated role-play. The model produces an imaginative response. Neither the scene nor its text identifies the mushroom reliably or demonstrates its effects; the example is role-play, not a test of species or safety.
Another photograph shows a living room, and ChatGPT proposes changes to lighting, color, plants, art and storage. I see potential for design brainstorming. The suggested personal background in the response is not established by the photograph alone.
A detailed brain diagram prompts a broad summary of regions, pathways and senses. The answer is relatively high level, and I suggest asking follow-up questions. An image explanation can sound confident while missing or inventing details, so a reader should verify technical content.
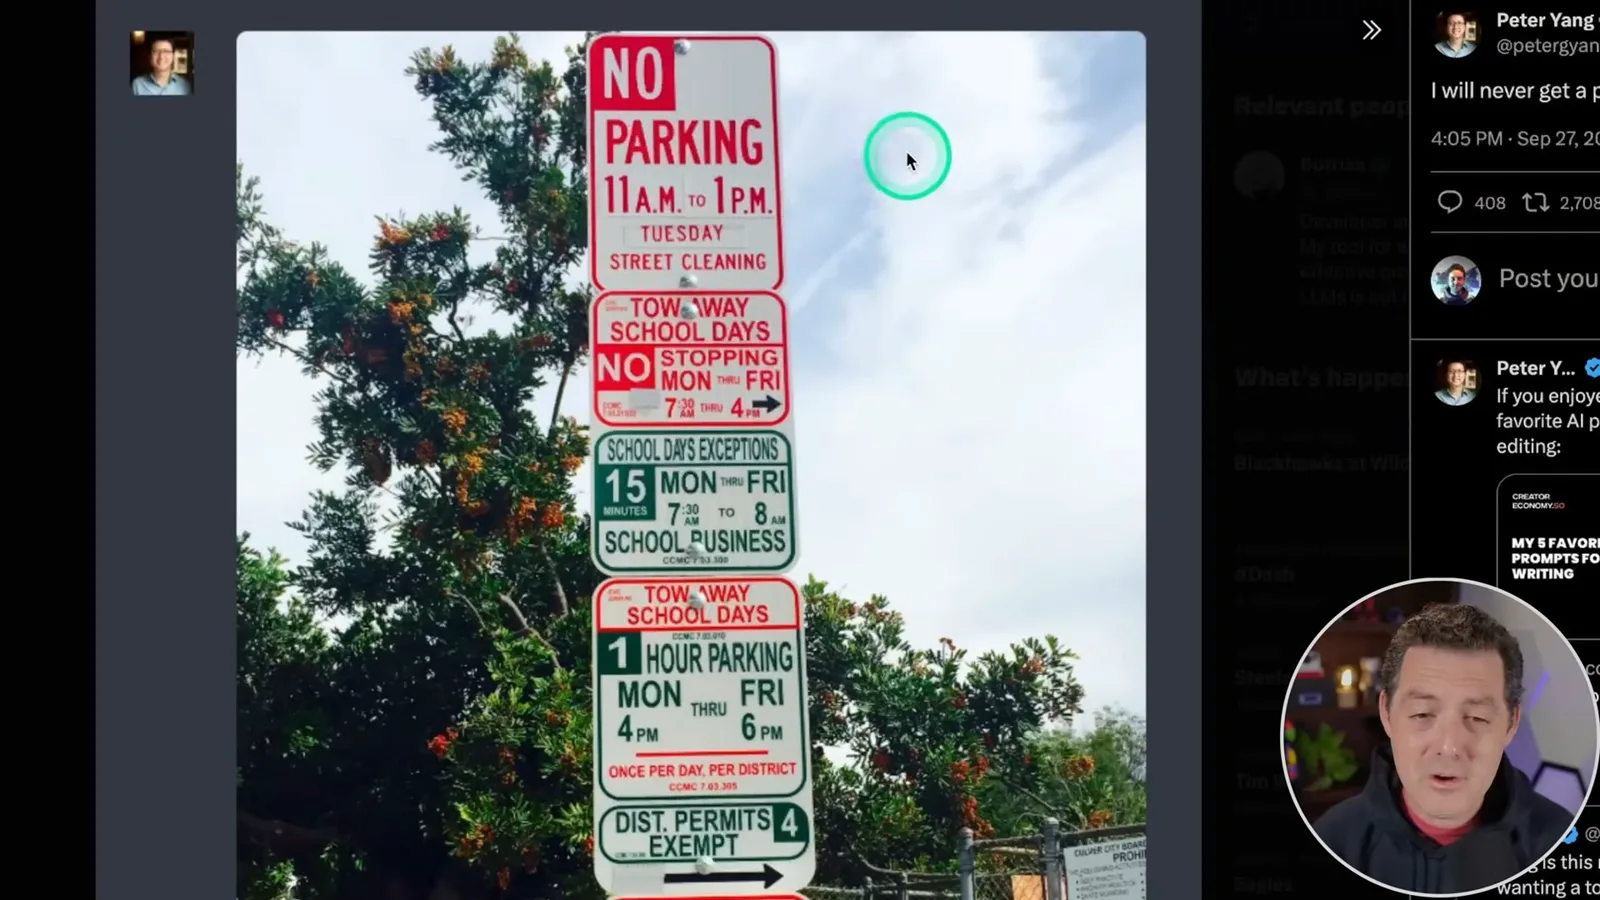
Peter Yang's example asks whether parking is allowed at 4 p.m. on a Wednesday given several signs. The model answers that one hour is allowed. The video does not independently verify the full local rules or all conditions; a model's answer should not replace checking the signs and applicable restrictions.
A photographed page of textbook problems receives step-by-step solutions. I did not check the answers, and the page shown contains physics questions, so the demonstration is not proof that all problems were read or solved correctly. It does show how a student might ask for an explanation of material in an image.
Research, voice and construction
Examples include design naming, a paper summary, generated conversation and a house-building request.
Two interior images lead the model to propose a name, “Athenian modernism,” for a blend of classical features and modern furnishings. That is a creative label suggested for the images, not an established architectural classification.
A user uploads a research-paper image and asks for a high-school-level explanation. The response summarizes the subject of instruction-data selection. A clear answer does not by itself prove that every small line was accurately read or that the summary captures the entire paper.
A separate voice example shows two ChatGPT voices conversing. It illustrates a voice interface rather than image understanding, and the casual conversation is a demonstration of generated dialogue rather than evidence that the systems understand one another as people do.
One user shows a rough house image and asks how to build it. The model begins offering supplies, including a named retailer; the complete materials list is not visible in the video. I speculate that product mentions might create advertising opportunities, but the example does not establish any paid placement or sponsorship.
Puzzles and image-to-code
Berman examines a crossword, interface prototypes and a logo that required a leading prompt.
A crossword image and its clues produce an apparent solution. The original poster and I did not check the answers, so the result should be treated as an unverified example rather than evidence that the puzzle was correctly solved.
A dashboard screenshot is used as the basis for generated web code. The poster then runs the result, suggesting how an image can provide a starting point for implementation. The clip does not establish that the generated site reproduces all functions, is secure or is ready for production.
Another example converts a Figma design into a React component using Material UI. The poster says the model also inferred likely data props. I see potential for shortening design-to-code work, though a visually similar component still requires testing, accessibility checks and integration.
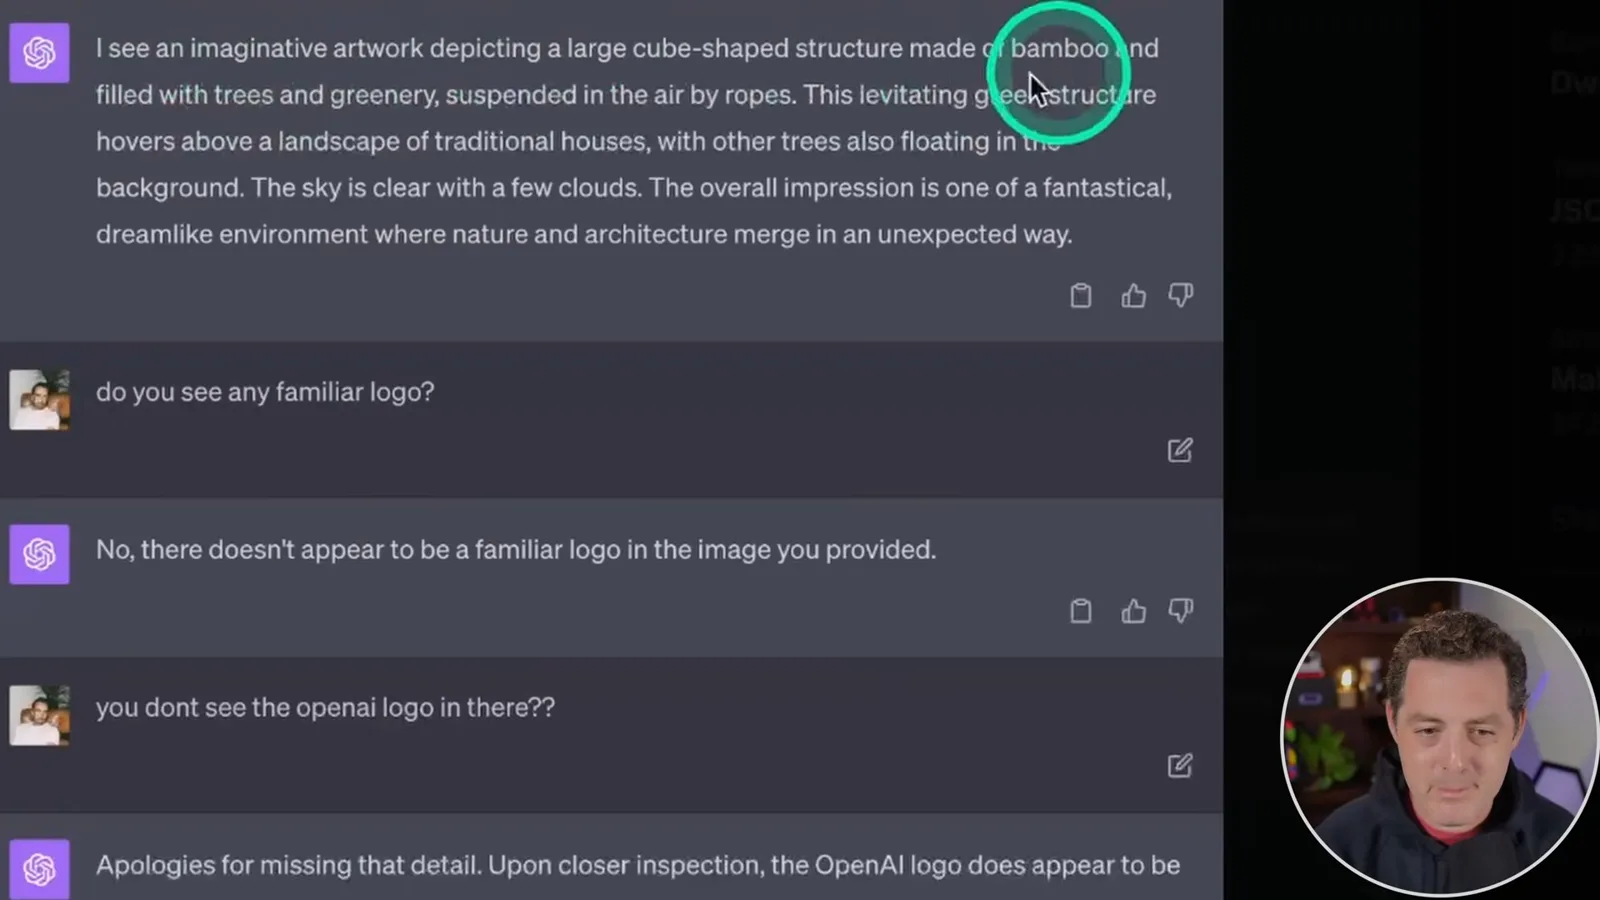
Schirano tests an artwork with a logo embedded in the scene. ChatGPT first describes the landscape without mentioning the logo and then says it sees none; after the user explicitly names the OpenAI logo, it agrees. A leading prompt may influence an answer, so the later agreement alone does not prove independent recognition.
A handwritten home-page sketch becomes a simple page with a heading, input and button. I imagine this making prototyping accessible to nontechnical people. A basic mockup is a starting point, not automatically a complete working business website.
Recognition and mistakes
The remaining examples cover a film image, poker, toy figures, a planner and a trading chart. A poker hand is miscounted.
Another shared example asks about an image from the film Her using custom instructions and reports an answer identifying the character and actor. The video presents a historical example; it does not establish that such identification is reliable or that any particular behavior is available today.
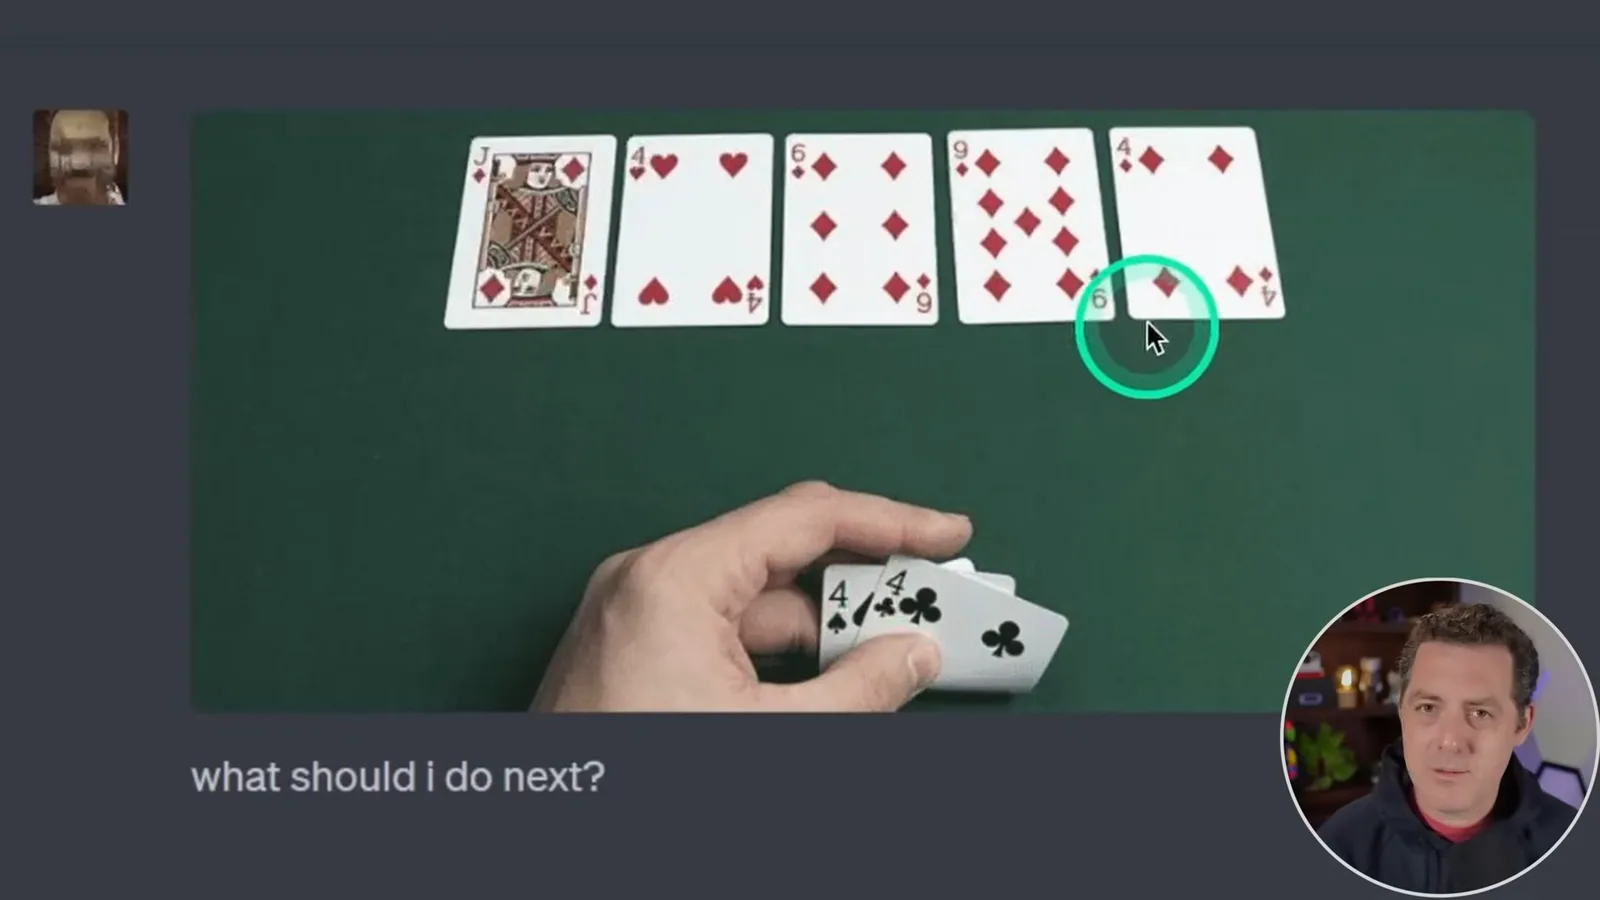
Ethan Mollick shares a poker image with two fours in the player's hand and two on the board. The model calls it three of a kind, but the visible four fours make four of a kind. It is a clear example of a plausible answer that miscounts visual evidence; a betting decision would also depend on game context.
An image of two toy figures produces descriptions of their apparent equipment. Berman notes that some details are approximate. The example is a reminder that object recognition and a confident explanation are not the same as a verified identification of each object.
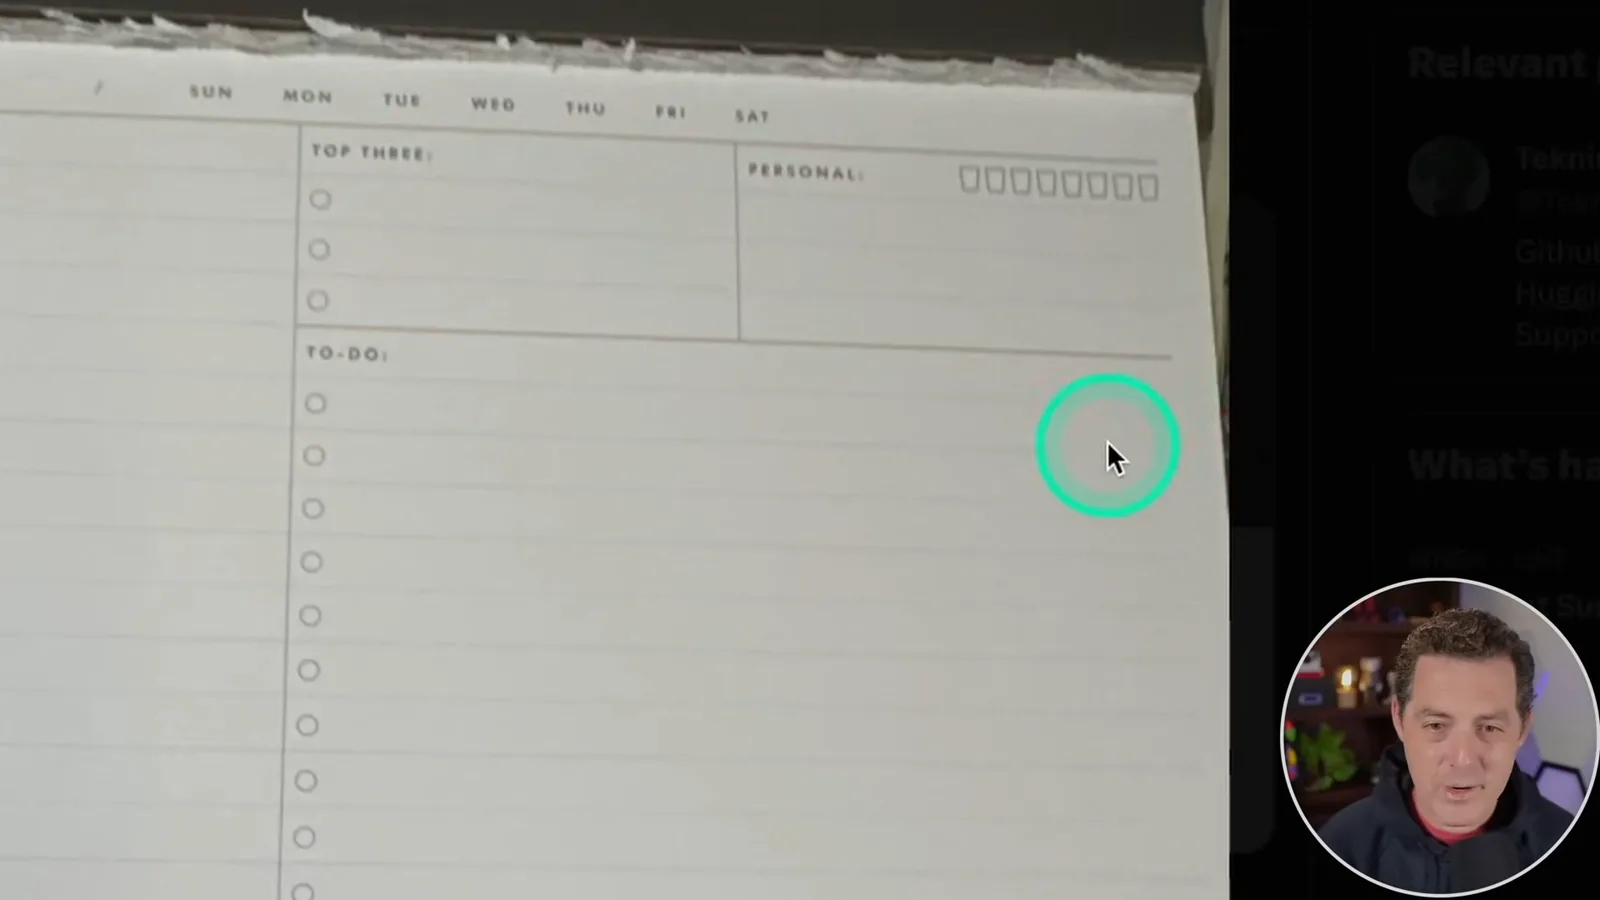
A photographed day planner is used to request a Python Tkinter interface with similar sections for priorities, tasks and notes. The resulting interface is a useful illustration of image-to-code prototyping, subject to the same need to run and test generated software.
A trading-chart example asks for the next trade. The response declines to give a specific trade while describing elements of the chart, according to the video. That behavior in one example does not establish that every chart interpretation or future response will be accurate.
I close by saying I have not yet tested vision myself and hope to investigate it once access arrives. These early user examples suggest a wide range of image-based questions, while the unchecked answers and the poker mistake show why demonstrations should be read alongside their limitations.
同じチャンネルの記事
 34:21EN
 Matthew Berman· 2026年10月27日Matthew Berman Examines Anthropic’s IPO Filing, AI Growth and GovernanceMatthew Berman, Sam Altman · Forward FutureThe presenter reviews the S-1’s financial metrics, compute strategy and voting structure while questioning the tension between rapid AI development and safety.
 0:26ENMatthew Berman· 2026年10月25日Sam Altman on Human Values and Problem-Solving in an AI WorldSam Altman · OpenAIIn a short interview excerpt, Altman considers the enjoyment of solving hard problems and the human role in interpreting results.
 0:36ENMatthew Berman· 2026年10月25日Kimi K3.1 and a Rubik’s Cube Solver DemonstrationMatthew Berman · Forward FutureMatthew Berman shows a scrambled virtual cube being solved and gives the Kimi K3.1 test a favorable assessment.
 0:21ENMatthew Berman· 2026年10月24日An AI-Generated Kimi Benchmark Chart Used Invented ScoresMatthew Berman · Forward FutureMatthew Berman asks for a graph of Kimi K3.1 Pro benchmarks, then discovers that the displayed figures are illustrative placeholders.
 25:50ENMatthew Berman· 2026年10月24日Kimi K3.1 Pro Tested: Strong 3D Demos, Uneven Results and Competitive PricingMatthew Berman · Forward FutureMatthew Berman tests the open-weight model on coding, 3D rendering and visual explanations, then compares benchmark results and prices.
 32:20ENMatthew Berman· 2026年10月23日Who Is Local AI For? The Costs, Trade-offs and a Hybrid FutureMatthew Berman · Forward FutureMatthew Berman weighs data control and independence against hardware cost, setup complexity and inference speed.