30 秒でわかる
Eugene Cheah, whose company sells inference, presents four steps for managing large AI workloads: measure spending, select models for the task, buy capacity deliberately and examine organizational processes. He contrasts long-running agents with high-volume automation and discusses latency, batching and utilization. His customer examples and model comparisons reflect specific conditions at the time of the workshop. He stresses task-specific evaluations and warns that more tokens or generated code do not automatically mean more useful work.
- 1Measure firstShared accounting makes it hard to know which workloads drive spending.
- 2Two workload shapesLong-running agents and high-volume automation have different cost profiles.
- 3Match models to stagesPlanning, implementation and review can be tested with different models.
- 4Latency versus throughputBatching trades individual speed for aggregate capacity in the example.
- 5Base load and burstsCapacity decisions depend on utilization, traffic and contracts.
- 6Own the handoffGenerated work still needs human responsibility and review.
ポイント
- Attribute usage and cost to teams and use cases.
- Evaluate model quality on representative tasks before switching.
- Separate interactive latency requirements from background throughput.
- Size dedicated capacity against measured base load and spikes.
- Keep responsibility for generated work with the person handing it over.
- Measure outcomes as well as token consumption.
チャプターごとに整えた全文を読む
Measure the workload
Cheah introduces cost attribution and different workload shapes.
Eugene Cheah introduces a workshop on AI inference economics. He is founder and CEO of Featherless AI and discloses that his company sells inference services, so his examples reflect that experience.
He says large-scale optimization is the focus. For organizations with modest spending, he suggests first finding valuable use cases; his spending threshold is a rule of thumb, not a universal cutoff.
The four steps are measuring usage, right-sizing models, buying capacity and checking the surrounding process. Start by understanding what the organization actually spends.
Cheah describes customers who used a single shared API key, making it difficult to attribute costs. Separate accounting by team and use case can show where the spending occurs; keys also need appropriate security controls.
With that visibility, compare workload needs. An interactive user may need a fast response, while a background task may tolerate slower throughput and a lower price.
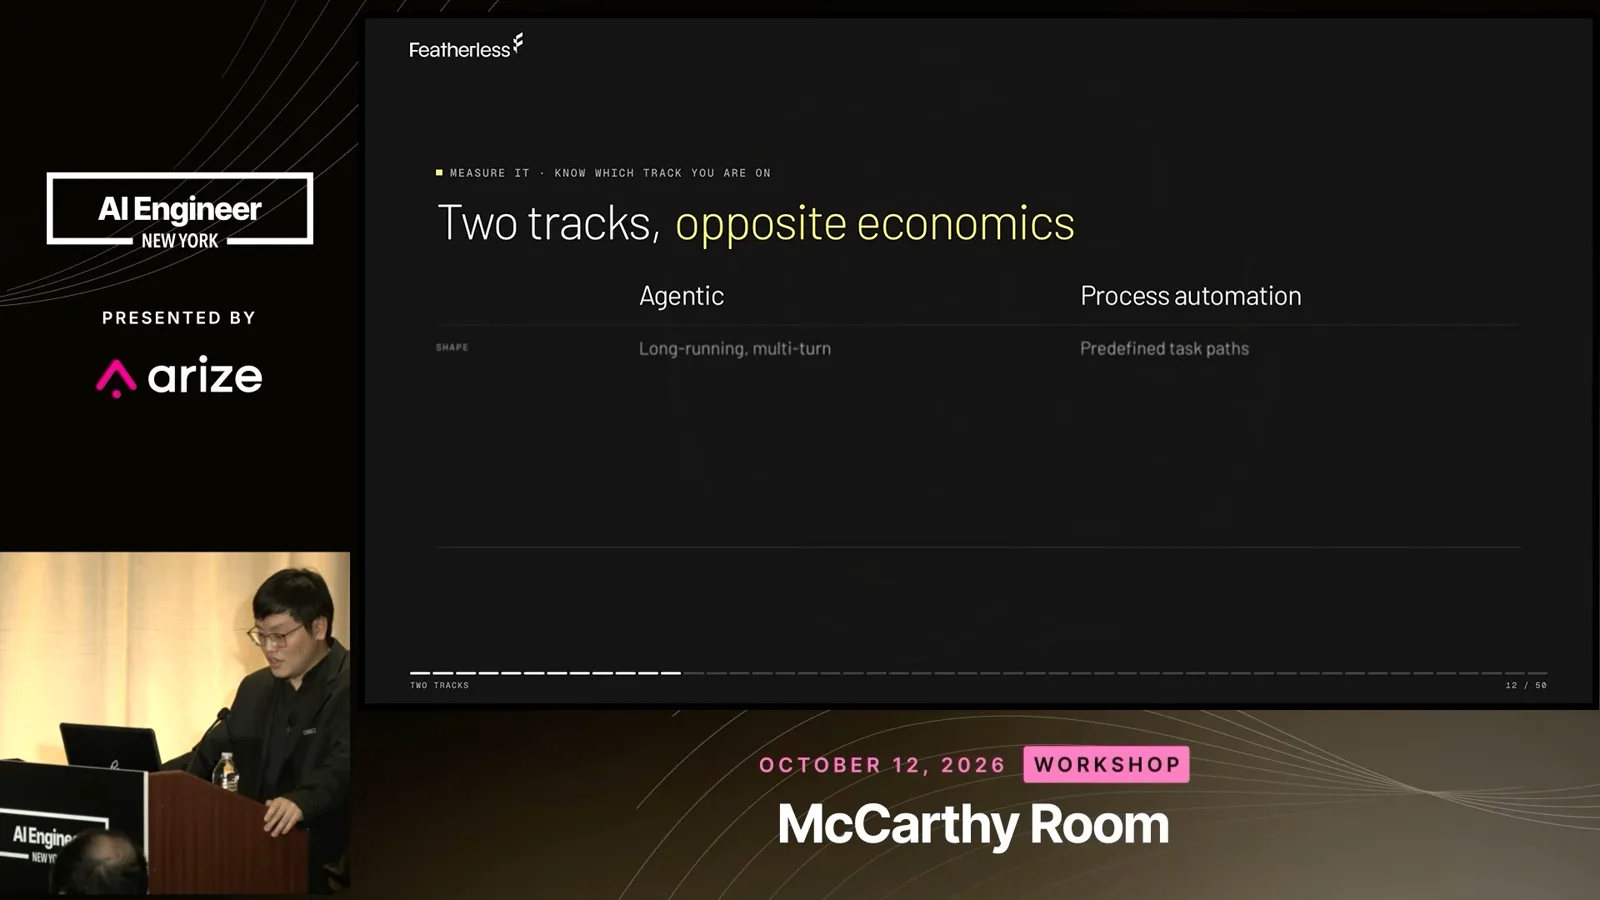
He contrasts long-running, multi-turn agents with high-volume process automation such as routing or document handling. Real workloads can fall between these categories, but the distinction helps identify different cost drivers.
Cheah describes a customer team that switched an agent workload from a costly hosted model to a dedicated open-model setup and reported a much lower bill. This is his company’s case study, not a controlled comparison or a guarantee that another team will retain quality.
Scheduling work when people are away can improve use of available capacity. The choice depends on deadlines, utilization and what the background agent is authorized to do.
For high-volume automation, examples include customer support, message classification, document processing and transaction screening. Even small per-request costs can matter when multiplied by large volumes.
Right-size models
He discusses evaluations, model selection and organizational incentives.
Once usage is measured, right-sizing means matching the model and service level to the task. Cheah says organizations sometimes apply an expensive general model where a narrower solution would suffice.
He presents model examples as a snapshot that could become outdated quickly. A model that performs well in one benchmark or domain may not be the best choice for another; test the actual workload.
Cheah reports that some specialized open models performed well on customer tasks relative to larger models. Those claims depend on the specific evaluation, prompt and serving setup.
He highlights classification-only models as another option for decisions with a limited set of outputs. They may be cheaper or faster for a suitable task, but cannot simply replace a system that must generate rich answers.
Long agent runs often repeatedly process input and cached context across many turns. Cheah says teams should measure input, cached input and output rather than comparing only the published output-token price.
One observed coding pattern uses a stronger model for planning and review and a faster, cheaper model for implementation. This division is worth testing against the team's quality criteria rather than assuming equivalence.
People may not switch models merely to reduce an employer's bill. Cheah says speed, available budgets and automatic routing all influence the choice, and organizations should examine those incentives.
Interactive workloads and CI jobs can use different service levels if their latency requirements differ. A slower background path is useful only if it still meets the job's deadline and quality requirements.
For nontechnical departments, he proposes task-oriented labels such as fast or finance instead of requiring every user to understand model names. Changing a model behind a label still requires testing and communication when behavior changes.
High-volume processes and tuning
He presents customer examples and a possible model-distillation workflow.
In embedded process automation, the high volume often forces teams to evaluate cost and quality early. Cheah recommends building representative examples and searching for the least expensive model that meets the task's requirements.
He cites a customer-support case where his company reports a large monthly cost reduction after splitting workloads and selecting models. The result is specific to that customer and does not establish general savings.
Some support tasks can be classified and routed to predefined responses rather than generated from scratch. This only works where the predefined response and escalation path actually cover the user's need.
At sufficient volume, a smaller model fine-tuned for a domain can be economical. Cheah describes telecommunications and commerce examples, but says teams should evaluate their own specialized tasks.
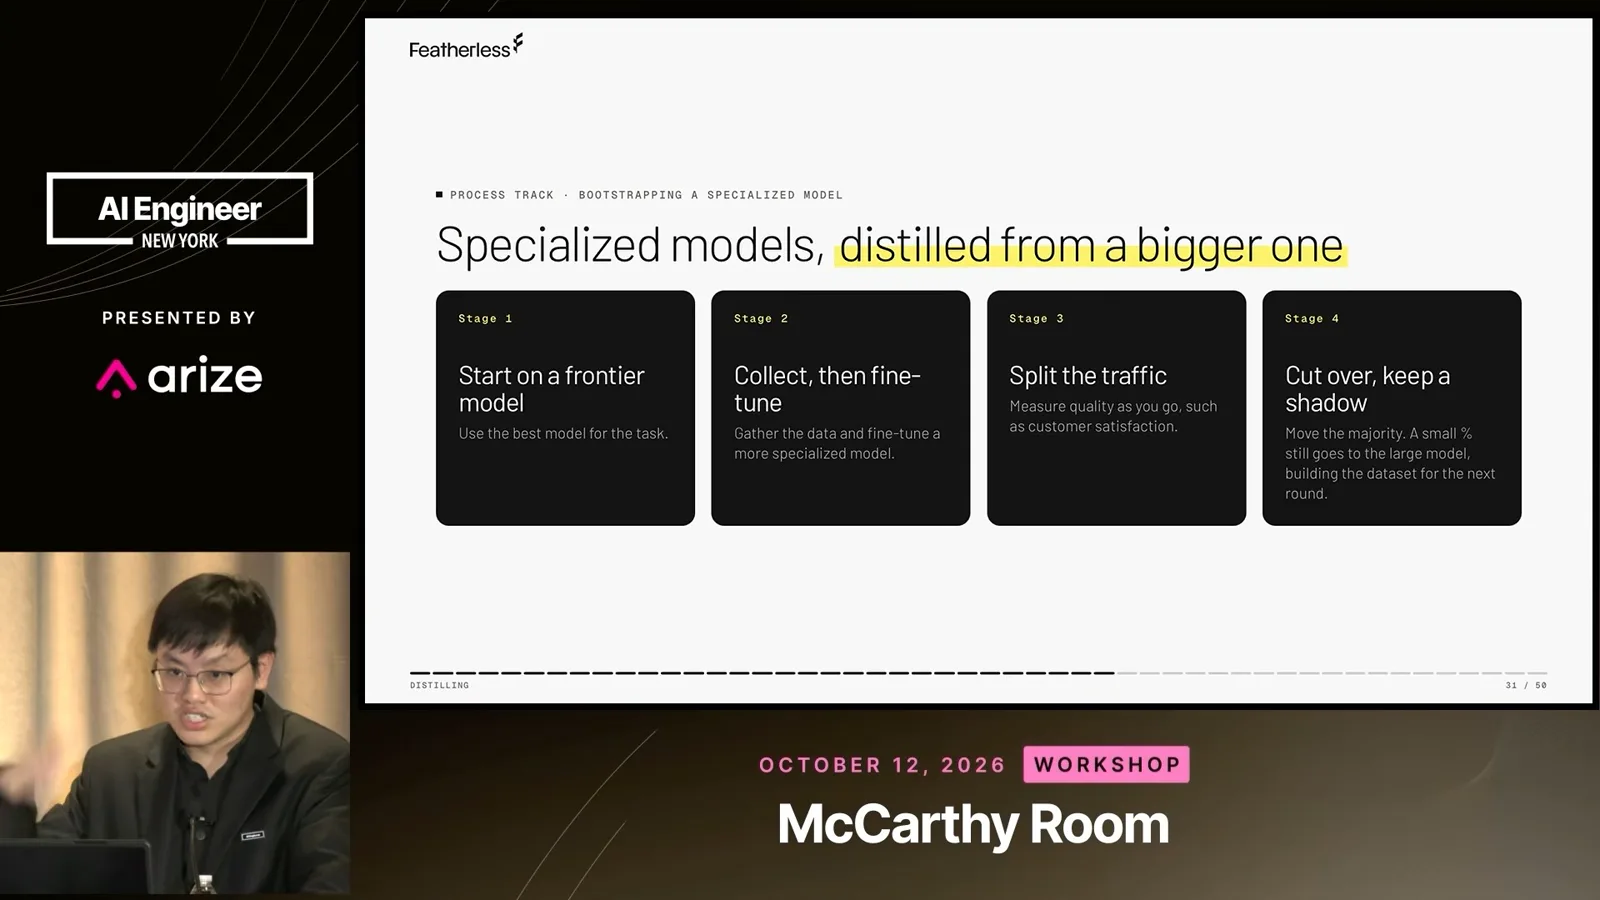
One proposed process starts with a capable model, collects examples, then trains and evaluates a smaller model. He notes that data-use terms vary by provider, so the organization must check the applicable terms.
Traffic can be split gradually between models, with quality monitored during the transition. A small shadow workload on a stronger model can help collect further comparisons when allowed.
Buy capacity deliberately
He explains latency, batching, base load and bursts.
Cheah moves to capacity. For a fixed model and hardware, optimizing for the fastest individual response can reduce the number of requests served together and raise cost per request.
In his illustrative configuration, batching more requests lowers individual speed but increases aggregate throughput substantially. The ratio depends on model, hardware, input and output sizes, and the serving stack.
Paying for low latency can make sense when a person is waiting. Background jobs may accept lower speed, but the right target must account for the complete task and its service-level objectives.
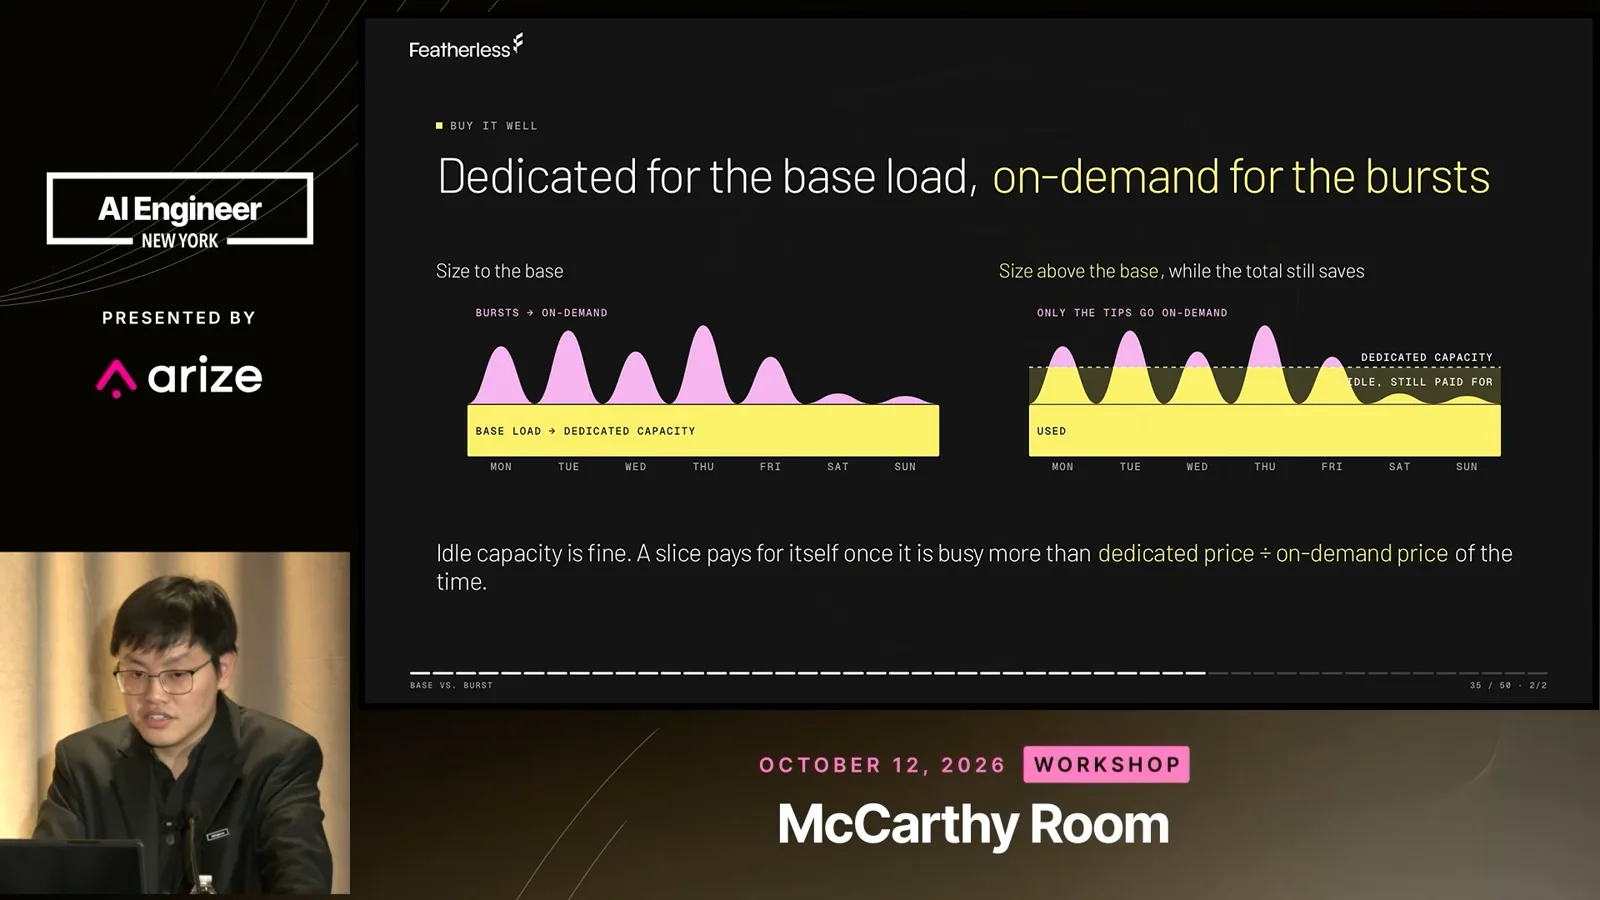
Measure the base load and spikes before buying dedicated capacity. A mix of reserved capacity for steady demand and on-demand capacity for bursts may be useful where security and contracts allow it.
Dedicated capacity can be underused, and the breakeven depends on prices and utilization. Cheah advises validating a deployment proposal against the organization's actual traffic rather than assuming that a dedicated node is always cheaper.
Check the surrounding process
He discusses review bottlenecks, accountability and outcomes.
He then asks teams to inspect processes, not only inference bills. More generated material does not automatically create more useful work or faster delivery.
If review, CI or organizational decisions become the bottleneck, generating changes faster may just move the queue. Trustworthy tests and review practices can help, but an unsafe agent should not be trusted merely for speed.
Cheah describes a pattern where agents produce huge changes that reviewers cannot easily process. Reviewers may discard and rebuild the work, so the same task consumes resources twice.
He recommends smaller, more modular changes and better testing. The same problem occurs with AI-generated slides or reports when the sender leaves the verification burden to others.
His rule is to take responsibility for what you hand over. A person sending code, slides or a report should inspect and stand behind it rather than blaming the generating model for errors.
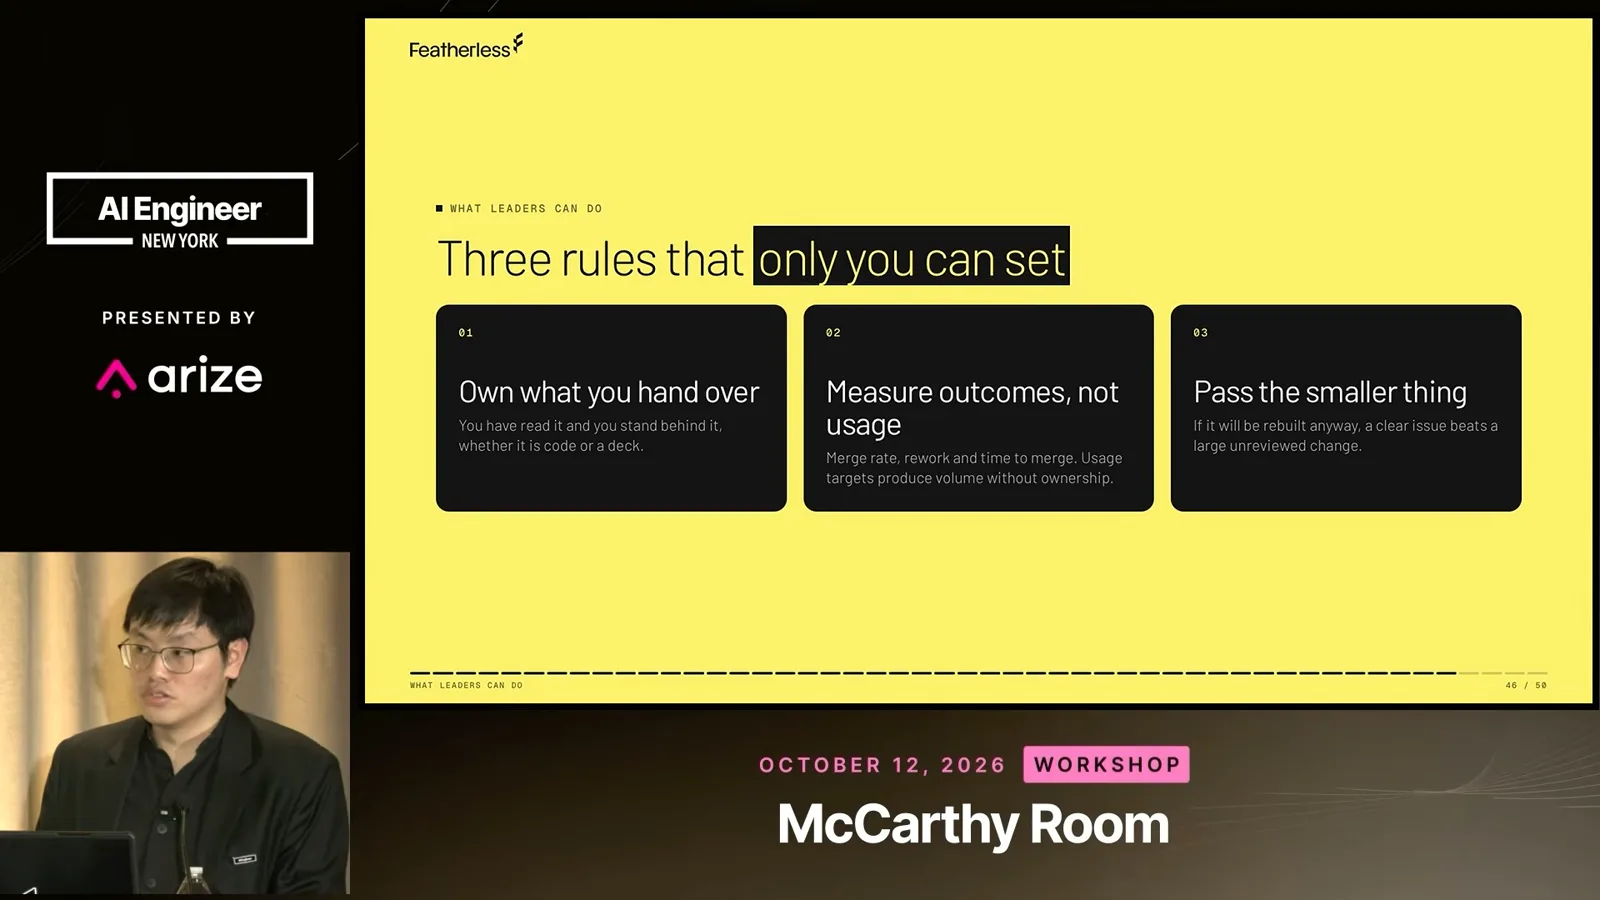
Measure outcomes as well as usage, he says, while recognizing that outcomes are difficult to compare across teams. Token count alone does not measure completed work.
He suggests asking which teams spend what, which tests establish that a cheaper model is adequate, what the base load is, where a person waits, and how much generated work is actually useful.
Questions on tuning and routing
He answers questions on training data, harnesses, caching and routing.
Asked about tuning, Cheah says his company's work often uses supervised fine-tuning, while methods vary. He emphasizes evaluating results rather than choosing a technique by name alone.
He describes a classifier experiment in which a prompt-tuned model did well on a particular benchmark. The example illustrates the need to compare approaches on the target task, not a general ranking.
On training data, he values human-checked examples and discusses experimenting with different mixtures. Whether imperfect traces help depends on the task and must be tested against held-out evaluation data.
A participant asks about a coding tool tied to a particular model ecosystem. Cheah suggests that a more flexible harness or a planner-and-worker split can make comparison possible, though changing developer workflows has costs.
On caching, he says some large customers use dedicated caches. Cache design, privacy, prompt formatting and actual hit rates all affect the outcome.
Cheah prefers routing by task or department in many cases. He cautions that changing among many models every turn can reduce cache reuse; the effect depends on the implementation.
He closes by encouraging participants to bring specific questions to the team. The central practice is to measure the workload, validate quality and then compare the full cost of serving it.
同じチャンネルの記事
 21:32EN
 AI Engineer· 2026年10月29日Shy Ruparel on AI agent reliability and recovery after failuresShy Ruparel · TemporalTemporal’s survey finds a gap between frequent agent use and dependable deployment. Ruparel demonstrates a synthetic payout workflow that resumes after workers stop.
 14:50ENAI Engineer· 2026年10月29日Cole Gannaway on code review, cross-repository risk and AI software factoriesCole Gannaway · QodoA one-line rename can pass local checks while affecting distant clients. Qodo’s Cole Gannaway explains how review context, shared rules and independent agents can expose those risks.
 11:47ENAI Engineer· 2026年10月29日Revolut’s David Abitbol on self-hosting AI coding models at scaleDavid Abitbol · RevolutAbitbol shares engineering delivery trends, GPU-serving costs and latency tuning, then describes controls for operating the tools in a regulated bank.
 21:47ENAI Engineer· 2026年10月28日Patrick Smyth on Open-Source Supply Chain Security in the AI EraPatrick Smyth · ChainguardChainguard’s Patrick Smyth discusses faster exploitation, malware in dependencies, zero-days and the expanding attack surface around developer workflows.
 14:09ENAI Engineer· 2026年10月28日Taylor Luttrell-Williams on Finding Logic Vulnerabilities with SonarQube Hunter AgentTaylor Luttrell-Williams · SonarSonar’s Taylor Luttrell-Williams explains how a security agent maps a codebase, investigates logic flaws and presents validated findings alongside conventional scans.
 16:29ENAI Engineer· 2026年10月28日Chris Vela on Benchmarking vLLM Configurations with Runpod BenchPodChris Vela · RunpodRunpod’s Chris Vela demonstrates a dashboard for comparing LLM serving configurations and choosing performance settings with workload-specific data.