30 秒でわかる
In August 2026, Matthew Berman examines GLM-5.3-Flash, the Z.ai model previewed as Ox Alpha. He highlights its mixture-of-experts architecture, reported benchmark performance, historical API cost comparisons and reports of Chinese-chip inference, then shows coding and presentation examples. His demos yield mixed results, and comparisons depend on different tools and access to the web. Benchmark figures, prices and infrastructure claims are time-bound and do not establish universal model quality. The video is sponsored by Higgsfield.
- 1Ox Alpha identifiedBerman says Z.ai’s GLM-5.3-Flash was the anonymously previewed model and highlights its 320B total and 18B active parameters.
- 2Benchmark claimsThe displayed vendor chart reports 84.3 on Terminal-Bench 2.1 and 63.4 on DeepSWE v1.1. These are test-specific results.
- 3Cost per benchmark taskBerman reads an Artificial Analysis chart showing approximately $0.09 per index task for GLM and $3.14 for Claude Fable 5 under the displayed settings.
- 4Chinese-chip inferenceBerman cites a report of 100 trillion tokens per day and a Z.ai statement about a Chinese-chip cluster. The throughput and economic comparisons are reported claims with workload-specific conditions.
- 5Mixed practical testsThe cube demo works to his satisfaction, while comparative design tests produce different winners and use unequal tool access.
ポイント
- GLM-5.3-Flash is an open-weight mixture-of-experts model reported to have 320 billion total parameters and 18 billion active per token.
- A large total model may still require substantial memory to run locally, even when only a fraction of parameters activates per token.
- Vendor benchmarks and Artificial Analysis’s index and cost figures compare specific workloads, not all real-world tasks.
- Berman liked GLM’s Rubik’s Cube, some website designs and a presentation, but preferred GPT-5.6 Sol’s biome scene and disliked both models’ outputs on other sites.
- The models used different coding environments and internet access, limiting the strength of the head-to-head comparison.
- Higgsfield sponsored the video; pricing and availability discussed are historical.
チャプターごとに整えた全文を読む
The model behind Ox Alpha
Berman introduces GLM-5.3-Flash, its open weights and mixture-of-experts design. He reviews vendor-reported benchmarks and a paid sponsor.
A mystery model named Ox Alpha appeared on OpenRouter and attracted attention before Z.ai identified it as GLM-5.3-Flash. Matthew Berman is excited by a comparatively inexpensive open-weight model that he says performs well against larger systems. His video was published in August 2026; prices, rankings and model availability can change.
Z.ai describes a mixture-of-experts model with 320 billion total parameters, of which 18 billion activate per token. Open weights allow users to inspect, adapt or host the model under its license, but do not by themselves imply that all training data and processes are public. Active parameter count is not the same as memory needed to store the full model; self-hosting still requires substantial resources.
Berman reports that the Flash model improves on GLM-5.2 in several tests while costing a fraction of the older model, and he compares it with more expensive models. He says it is not at Fable’s level overall. His estimate of a competing proprietary model’s parameter count is not established in the video and should not be treated as a confirmed specification.
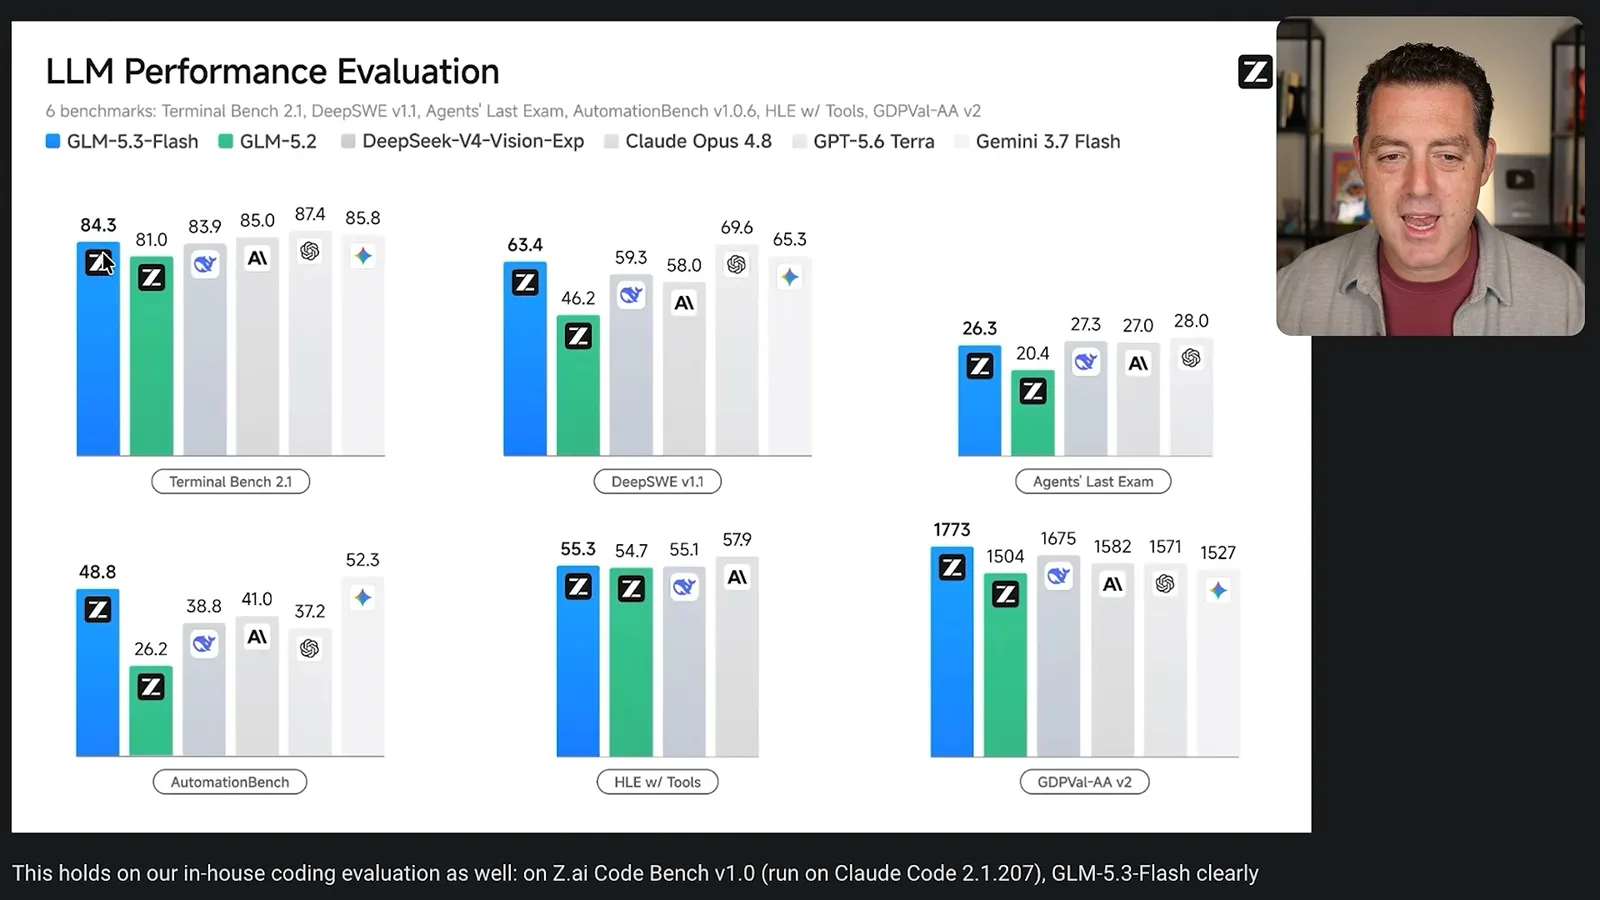
The Z.ai chart shown in the video reports 84.3 on Terminal-Bench 2.1 and 63.4 on DeepSWE v1.1, plus a high GDPVal-AA v2 result. These are vendor-displayed comparisons on named benchmarks, not proof of superiority across all tasks. Berman sees the improvement over GLM-5.2 as especially notable.
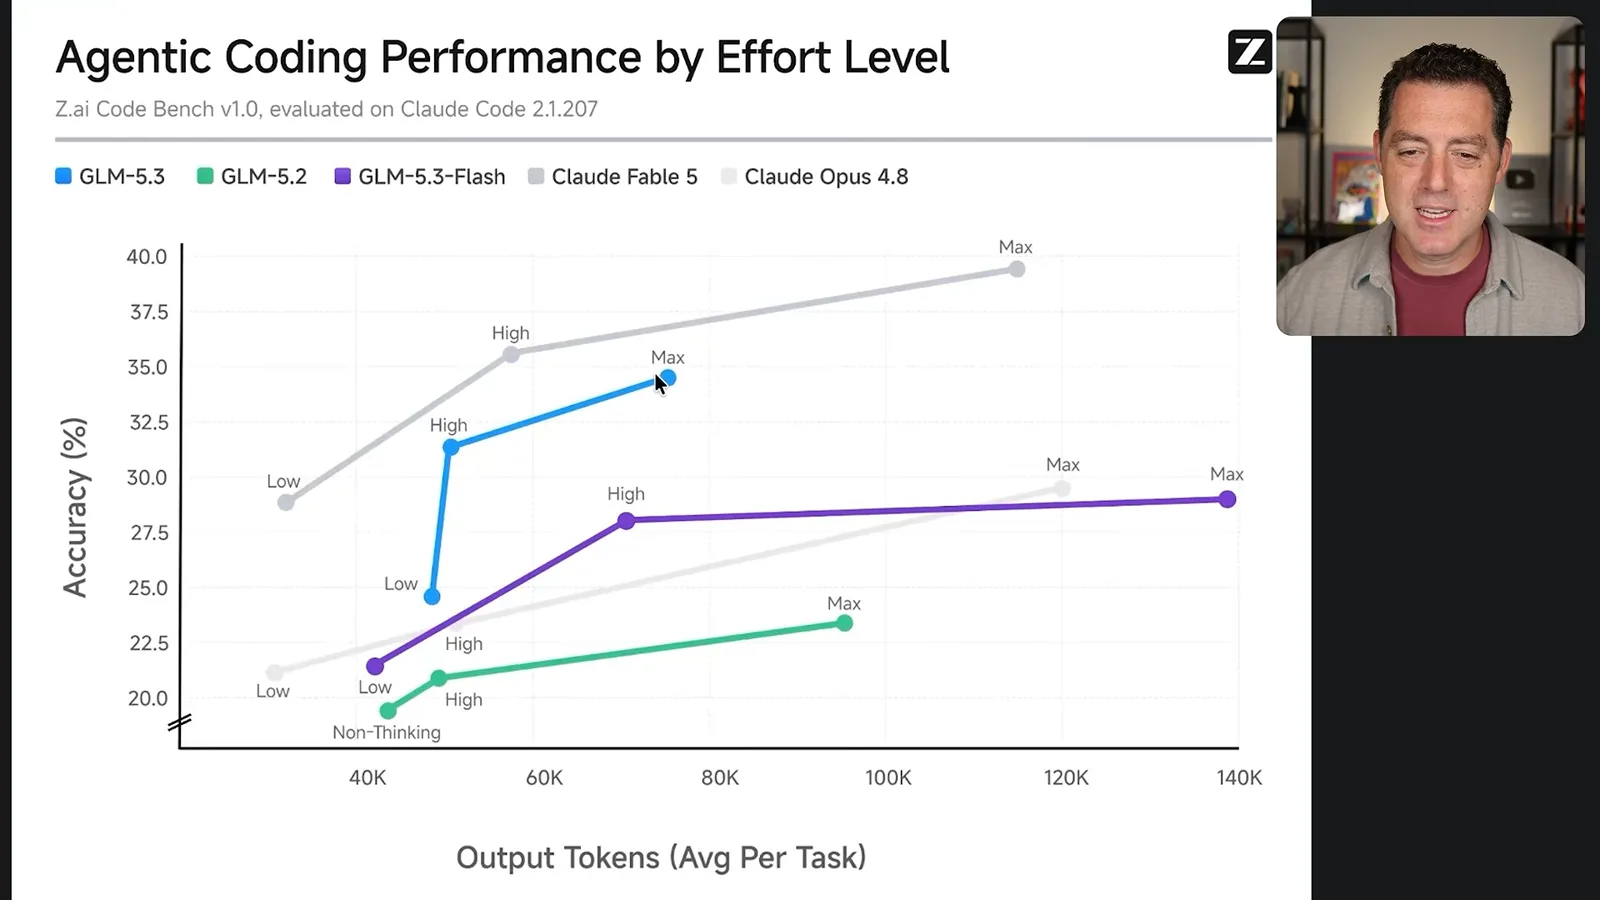
A separate Z.ai coding chart plots accuracy against average output tokens for different effort levels. Berman notes that full-size GLM-5.3 at maximum effort approaches Fable at high effort on that chart, while Fable at maximum scores higher. The blue full-size GLM-5.3 line is distinct from the purple GLM-5.3-Flash line; that particular comparison should not be attributed to Flash.
Berman cites an Artificial Analysis Intelligence Index score of 57 for GLM-5.3-Flash versus 62 for Claude Fable 5 in the snapshot he shows. An index aggregates selected evaluations and does not mean the model has a precisely measurable percentage of another model’s general intelligence. The video includes a paid Higgsfield sponsorship promoting its image and video API.
Cost, tokens and infrastructure
He compares benchmark costs and token use, then discusses a report about serving on Chinese AI chips. He describes ways to access the model through providers.
The displayed Artificial Analysis cost chart estimates a weighted average of about $0.09 per Intelligence Index task for GLM-5.3-Flash, versus $0.95 for GPT-5.6 Sol and $3.14 for Claude Fable 5 under the settings shown. Berman finds the combination of score and cost striking. These are benchmark-task averages based on then-current token usage and prices, not the price of every successful real-world task.
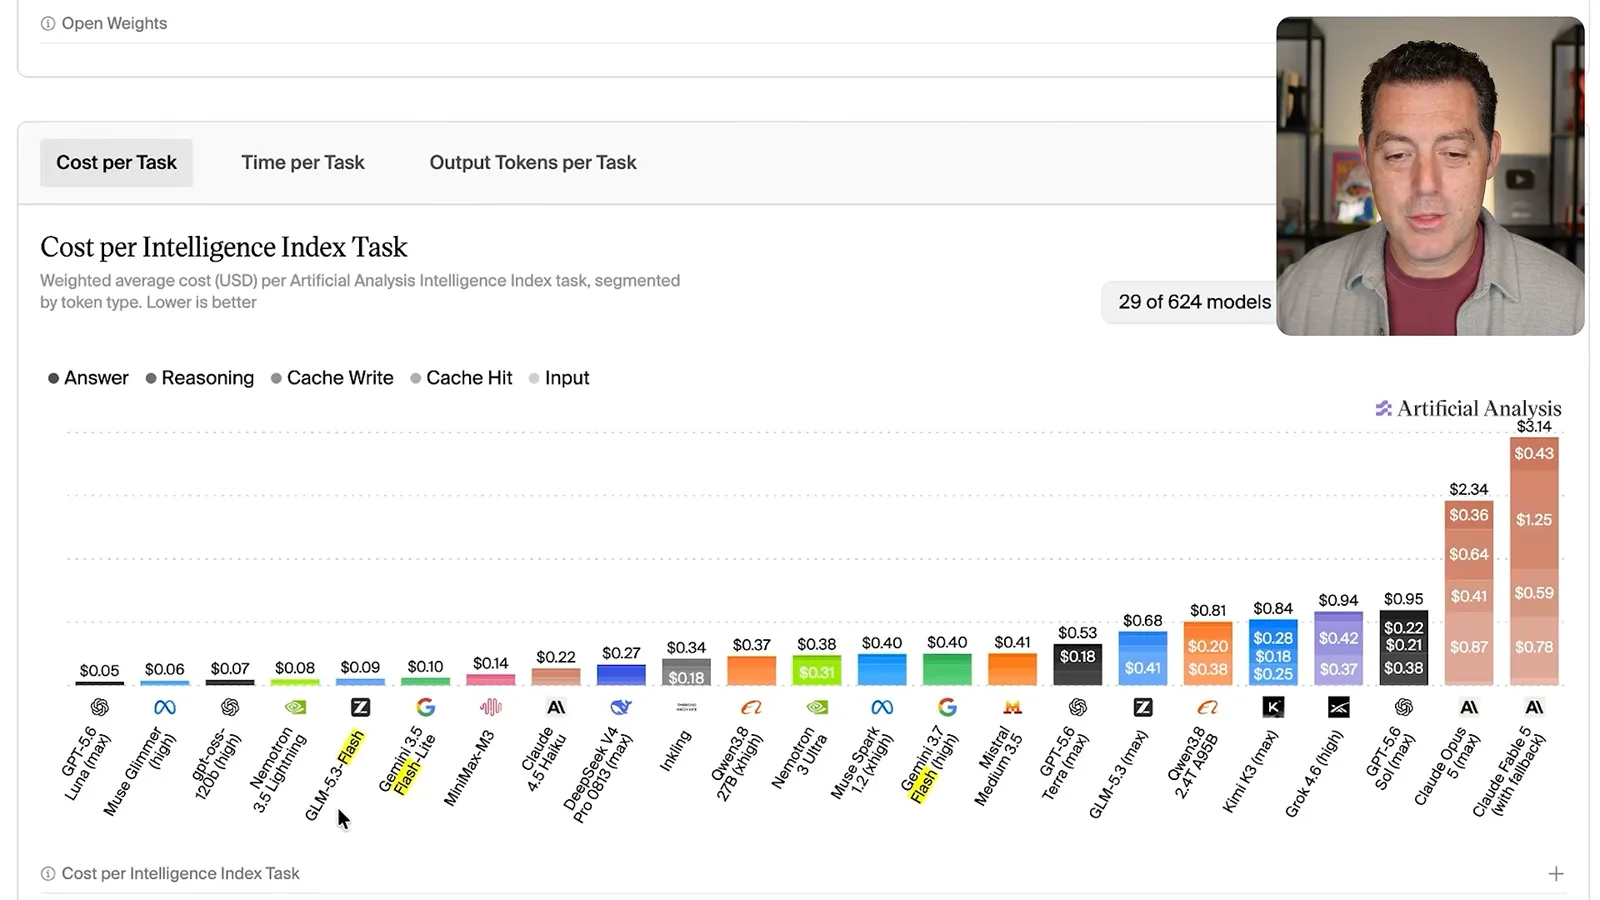
He compares GPT-5.6 Luna at roughly $0.05 per index task with Flash at $0.09, observing that Flash scores higher on that snapshot and offers open weights. The difference between those rounded costs is about 80% relative to $0.05, not the 40% he later says. Which is better value depends on the task, provider, settings and requirements.
The chart reports roughly 20,000 output tokens per index task for Luna and 47,000 for Flash. Berman uses this to explain how token volume affects total cost, even for a low-priced model. These are averages on the index, not proof that the models produce the same answer or solve each task equally well.
Berman speculates that an open-weight community could improve efficiency faster through experimentation, while acknowledging this is conjecture. He reports a one-million-token context window, a 131,000-token maximum output and a low cached-input rate as presented at launch. Actual context, limits, caching and prices can differ by provider and change over time.
Berman cites SemiAnalysis reporting a figure of 100 trillion tokens per day served on Chinese chips, and reads Z.ai’s statement describing a large Chinese-chip cluster with optimized interconnect and serving software. These are reported claims, not independently verified measurements in the video. The figure should not be conflated with the OpenRouter graphic’s 23.2 trillion tokens across six days, or assumed to describe all providers.
Berman tests a Z.ai API endpoint and notes that its service is hosted in China, so he avoids sending sensitive information. He says open weights can also be served through other inference providers and connected to compatible coding tools. Provider location, retention policies, cost and security can differ; self-hosting is another option for appropriately equipped users.
Coding and design experiments
Berman demonstrates a Rubik’s Cube and compares a biome scene and five websites with GPT-5.6 Sol. Results are mixed and the environments have different internet access.
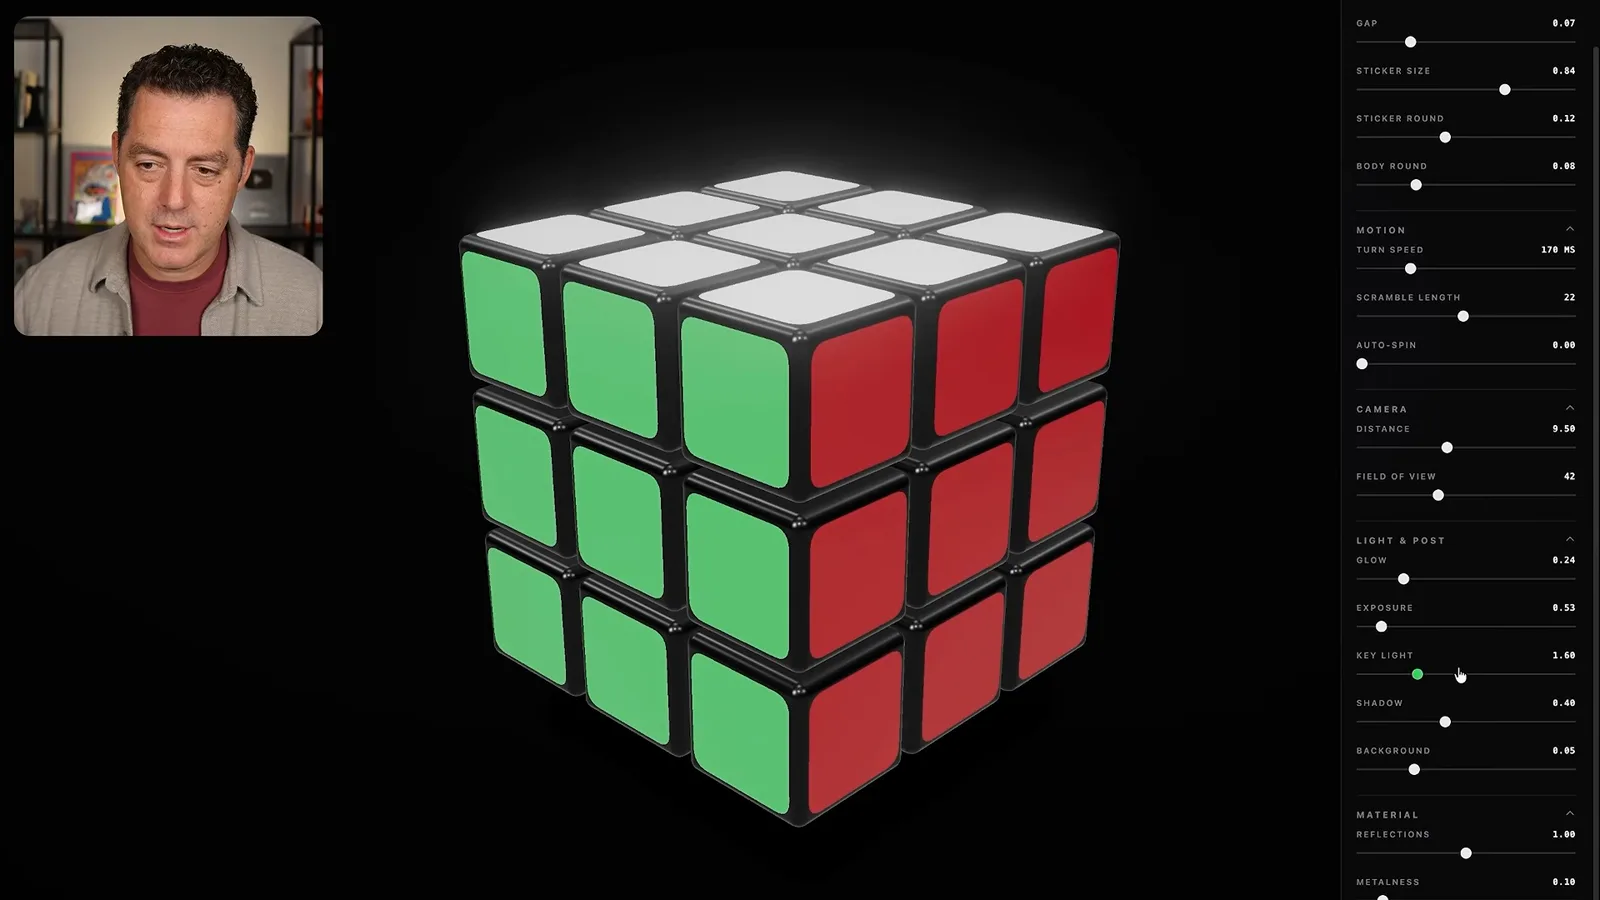
His first demonstration is a Rubik’s Cube simulation. He turns faces, scrambles and solves the cube, changes its size to 5×5 and adjusts rotation, lighting and materials. He considers it smooth and convincing, while noting that other recent models can also build similar demos. The video does not independently test every possible cube state or physical behavior.
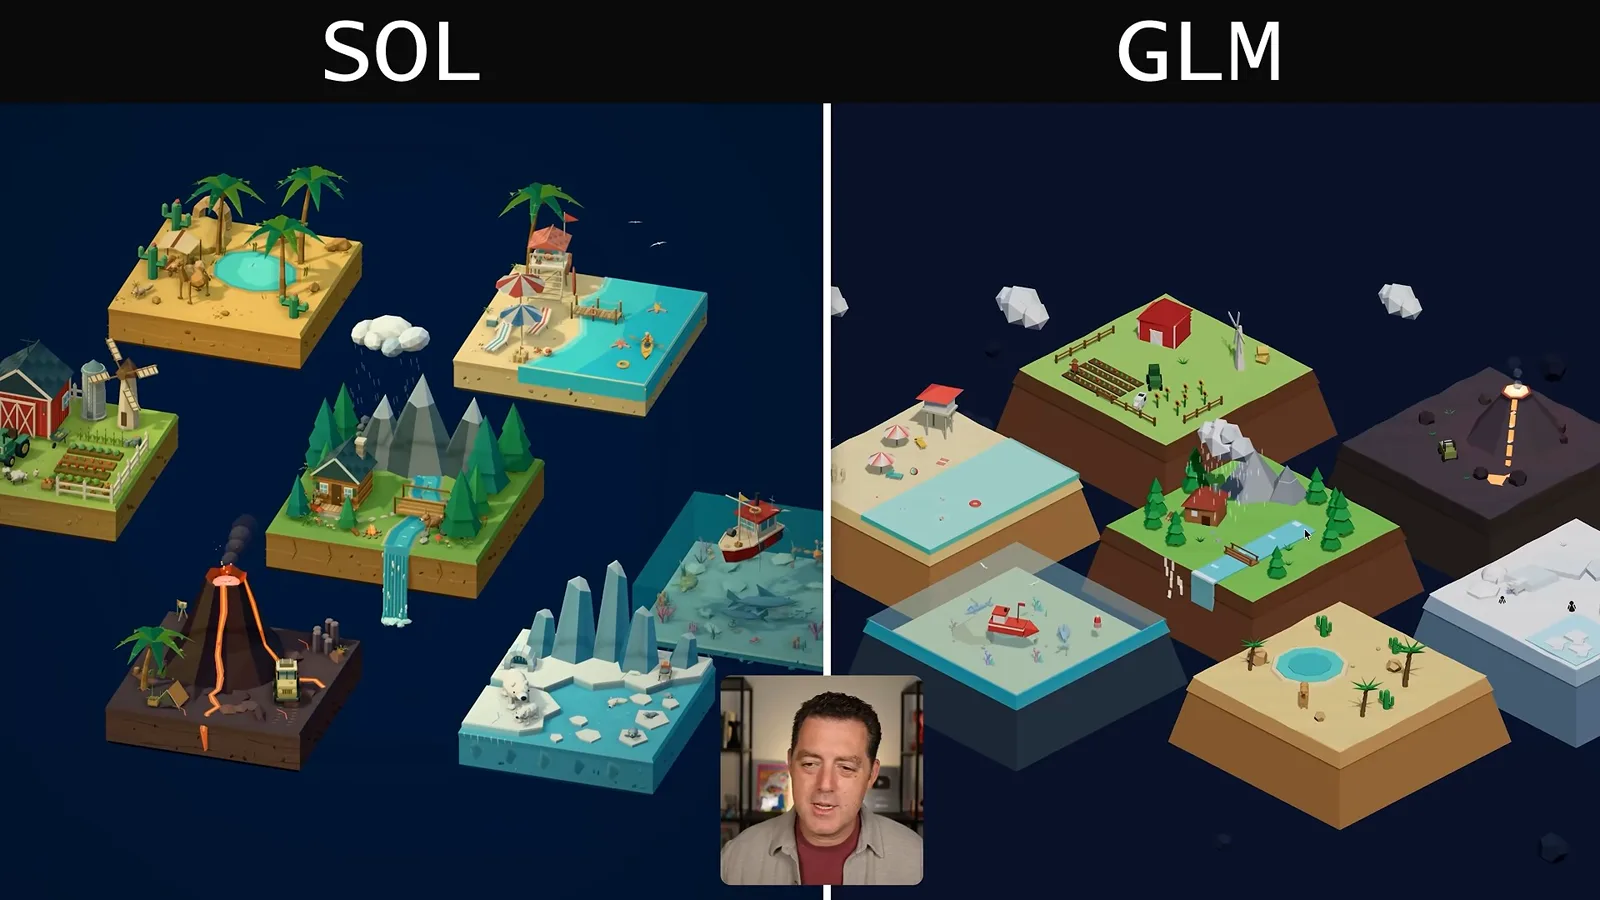
Berman gives GLM-5.3-Flash and GPT-5.6 Sol the same prompt for seven small floating biome dioramas. He prefers Sol’s result by a wide margin for its detail and coherence. This is his visual judgment on one prompt, not a controlled evaluation of overall coding skill.
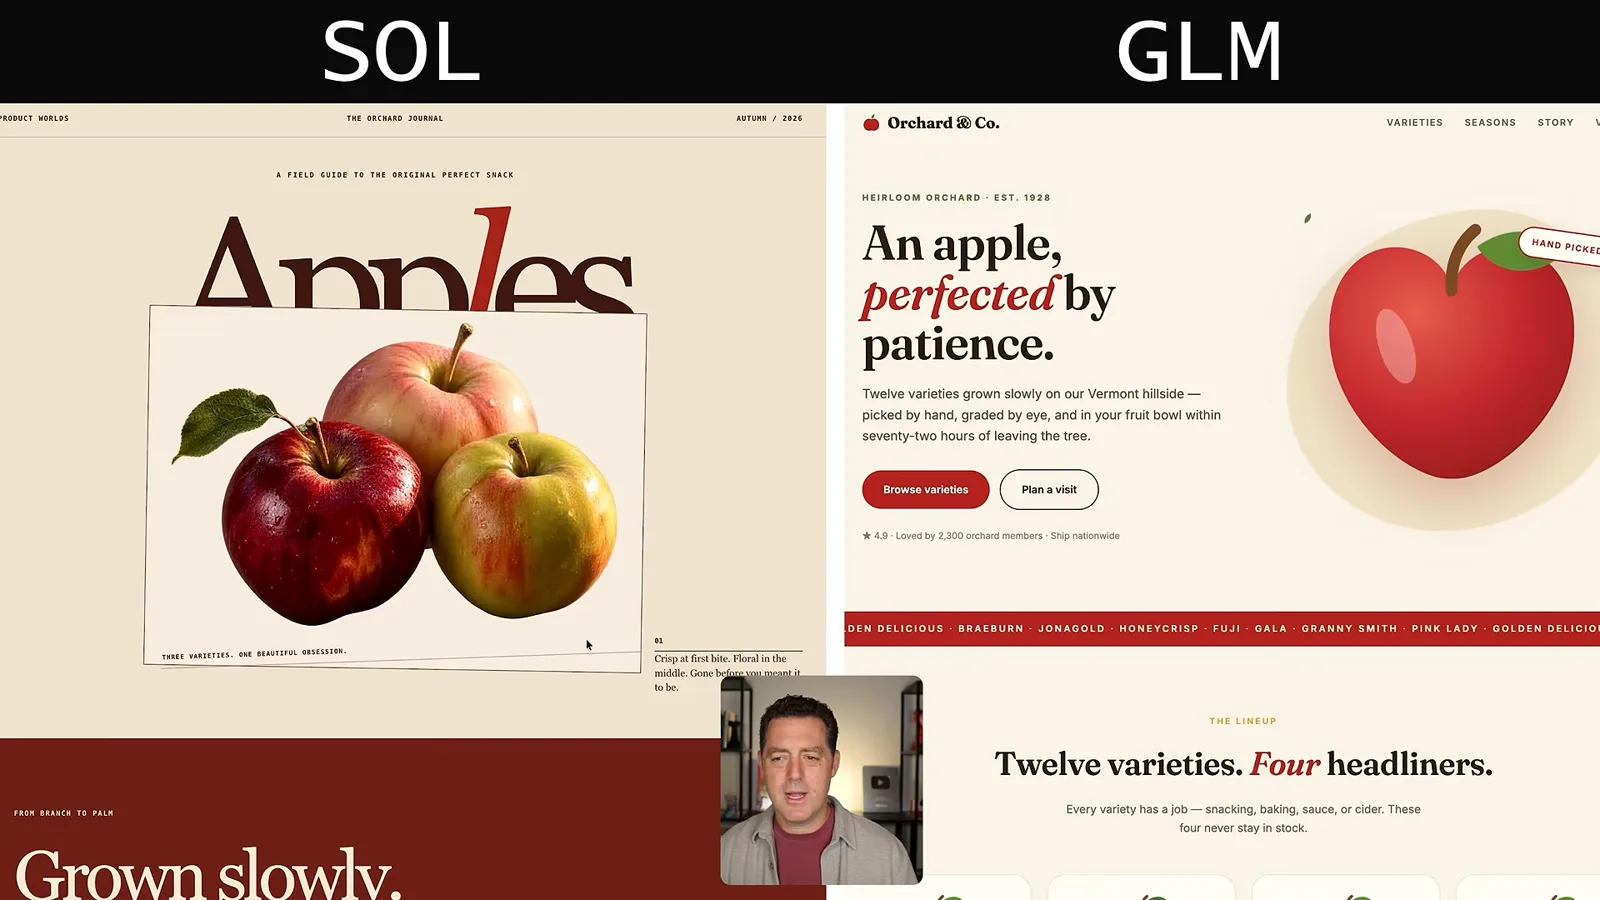
He next compares five websites. For an apple-themed page he prefers GLM’s design; he dislikes the large image overlapping text in Sol’s version. He notes that Sol in Codex had internet access while his OpenCode setup did not, so the environments were not equivalent. A plausible-looking address in the GLM output also prompts him to check it, but he cannot establish that it is an orchard.
For an NVIDIA DGX Spark page he prefers GLM’s terminal-like interface and criticizes Sol’s invented hardware image. He also gives GLM a narrow win on rubber ducks, though he finds both designs reasonable. These are subjective judgments of individual samples and do not verify the product details on the pages.
For the Galaxy Z Fold page he considers both results poor and questions the accuracy of some specifications. On the Tesla Model Y page he criticizes GLM’s close resemblance to Tesla’s site and an unconvincing vehicle illustration; he does not select a clear winner. Both examples show that polished pages can still contain misleading or derivative content.
A data-center presentation
He reviews a branded slide deck and praises its design. He closes by emphasizing the value he sees in open-weight models.
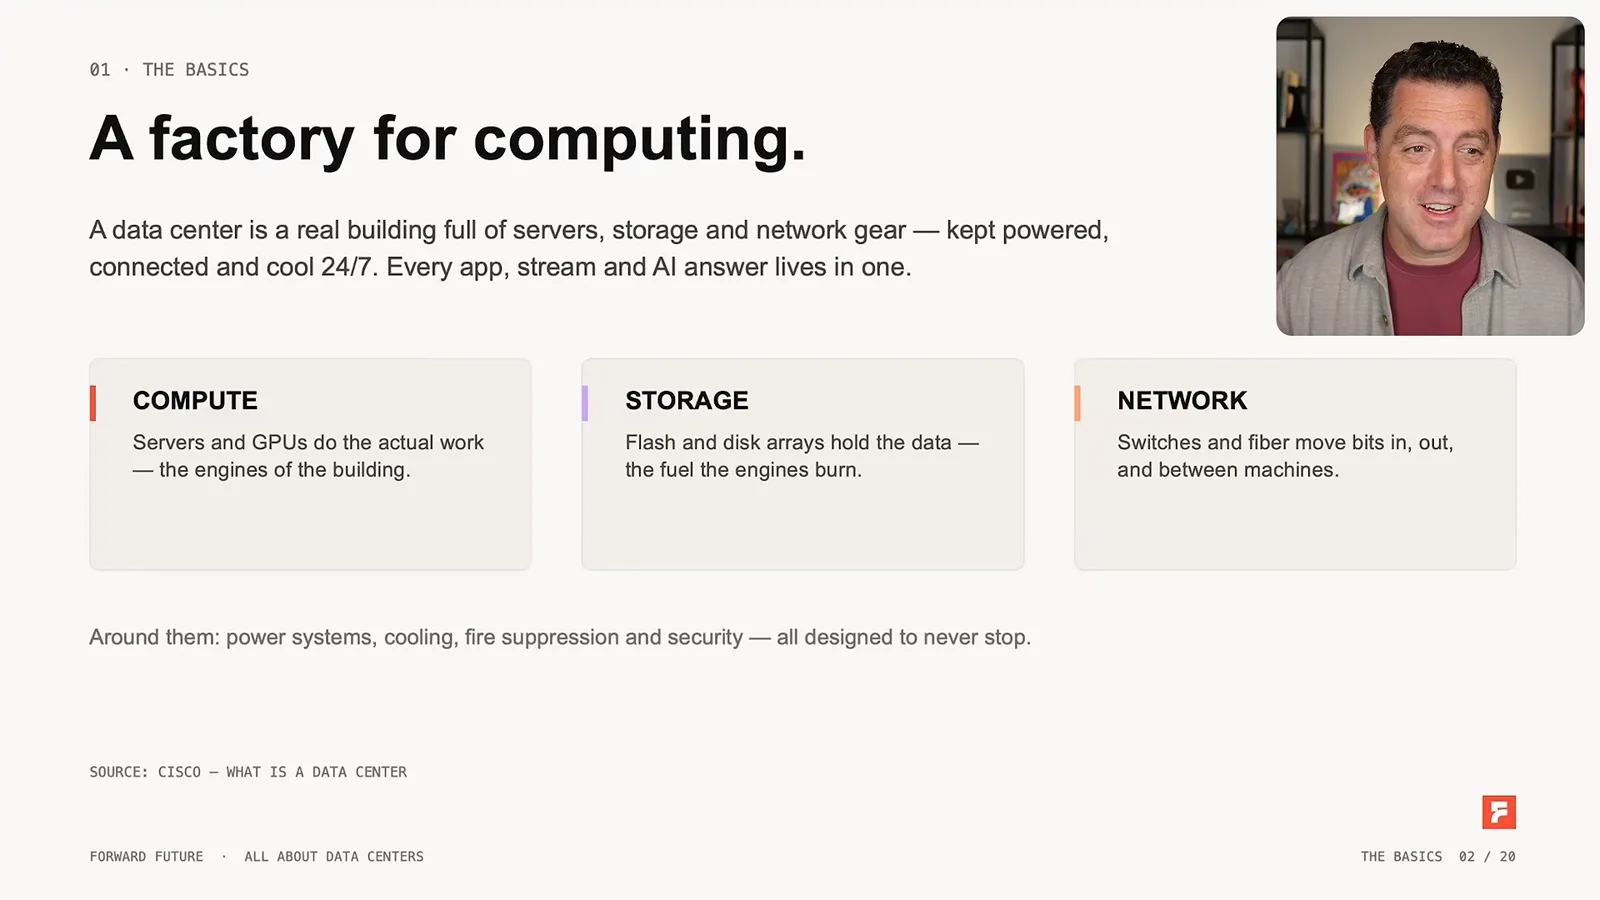
Finally, Berman reviews a PowerPoint deck about data centers using Forward Future branding. He says it retrieved the organization’s logo and colors and praises the visual result. That successful example does not resolve factual accuracy across the full deck. He closes by reiterating his enthusiasm for open-weight models and thanks sponsor Higgsfield.
同じチャンネルの記事
 34:21EN
 Matthew Berman· 2026年10月27日Matthew Berman Examines Anthropic’s IPO Filing, AI Growth and GovernanceMatthew Berman, Sam Altman · Forward FutureThe presenter reviews the S-1’s financial metrics, compute strategy and voting structure while questioning the tension between rapid AI development and safety.
 0:36ENMatthew Berman· 2026年10月25日Kimi K3.1 and a Rubik’s Cube Solver DemonstrationMatthew Berman · Forward FutureMatthew Berman shows a scrambled virtual cube being solved and gives the Kimi K3.1 test a favorable assessment.
 25:50ENMatthew Berman· 2026年10月24日Kimi K3.1 Pro Tested: Strong 3D Demos, Uneven Results and Competitive PricingMatthew Berman · Forward FutureMatthew Berman tests the open-weight model on coding, 3D rendering and visual explanations, then compares benchmark results and prices.
 32:20ENMatthew Berman· 2026年10月23日Who Is Local AI For? The Costs, Trade-offs and a Hybrid FutureMatthew Berman · Forward FutureMatthew Berman weighs data control and independence against hardware cost, setup complexity and inference speed.
 1:03:37ENMatthew Berman· 2026年10月23日Matthew Berman’s Team Tests Kimi K3.1 on Animation, Games, and ChartsMatthew Berman, Alex, Brian · Forward FutureA live team AMA turns into an informal test of Kimi K3.1, from personal-agent workflows to motion graphics, a browser game, and a benchmark chart.
 0:53ENMatthew Berman· 2026年10月22日Sam Altman on AI and the Discovery of New KnowledgeSam Altman · OpenAIAltman expects progress in mathematical discovery to extend to biology, materials and energy.