30 秒でわかる
Matthew Berman describes Cognition's AI Productivity Guarantee and its effort to measure useful work rather than token consumption. Cognition says the offer applies to enterprise deployments: if estimated engineering value falls short of consumption, it issues usage credits up to $10 million. The estimator is a proxy for productive hours, not a complete measure of business return.
- 1A productivity promiseBerman introduces Cognition's offer as a response to uncertain AI spending. The company's announcement specifies enterprise terms and usage credits.
- 2A capped guaranteeCognition says it compares estimated value and actual consumption near the end of an annual contract and issues credits up to $10 million if value falls short.
- 3Estimating useful workA separate agent estimates whether output is useful and how long a human engineer might take. That estimate is not a complete measure of ROI.
ポイント
- Cognition's guarantee compares estimated engineering value with actual Devin consumption for enterprise customers.
- The company says it will issue usage credits up to $10 million if the value falls short; this is not an unconditional cash payment for every failed task.
- An estimator judges whether each session produced useful output and estimates equivalent human engineering time.
- The company itself notes that estimated engineering hours do not replace a full ROI assessment.
チャプターごとに整えた全文を読む
The productivity guarantee
Berman introduces Cognition's enterprise offer in the context of AI spending. The company specifies a capped usage-credit mechanism.
Matthew Berman introduces Cognition's AI Productivity Guarantee, arguing that companies need to know whether AI coding tools produce value rather than merely consume tokens. He cites a claim about Uber spending its annual budget in three months; the brief clip does not provide its source or scope.
Berman says Cognition will pay when AI does not earn its keep. The company's June 2026 announcement is more specific: for enterprise deployments of Devin, estimated productive engineering hours are converted to a dollar value and compared with actual consumption near the end of the annual contract. If value falls short, Cognition says it issues usage credits up to $10 million; it is not an unconditional cash payout for any failed AI task.
Measuring output
He describes a system for estimating useful output and equivalent human time. Cognition acknowledges that this is not a full ROI measure.
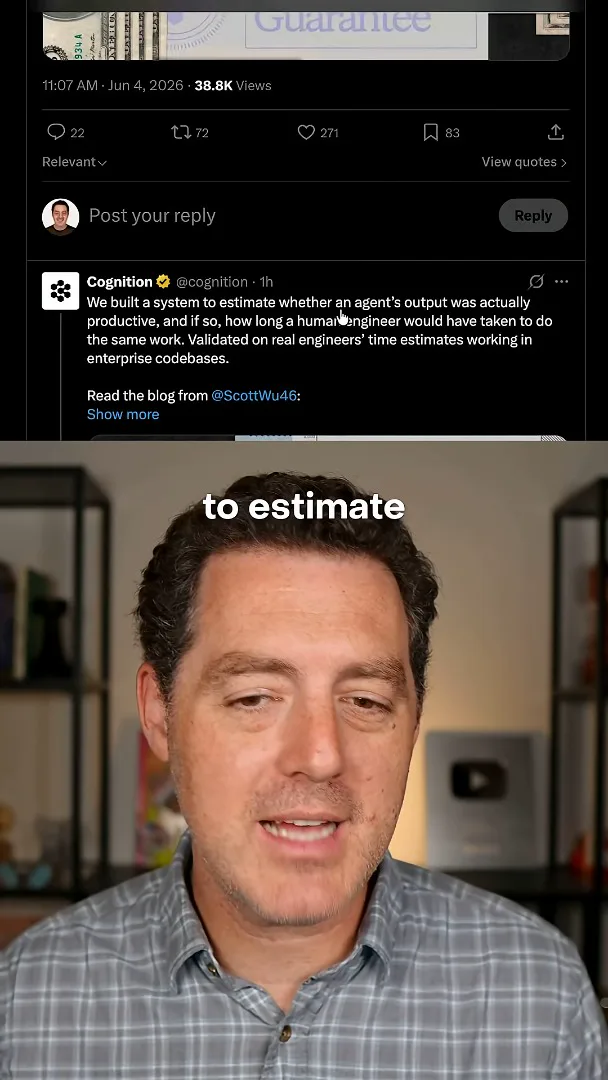
The proposal shifts attention from maximizing token use to measuring useful work. Cognition says an agent reviews completed sessions to assess whether their output was useful and estimate how long a human engineer would have taken. Berman observes that the measurement problem is difficult; Cognition also says estimated productive hours are not a substitute for measuring full business ROI.
同じチャンネルの記事
 34:21EN
 Matthew Berman· 2026年10月27日Matthew Berman Examines Anthropic’s IPO Filing, AI Growth and GovernanceMatthew Berman, Sam Altman · Forward FutureThe presenter reviews the S-1’s financial metrics, compute strategy and voting structure while questioning the tension between rapid AI development and safety.
 0:26ENMatthew Berman· 2026年10月25日Sam Altman on Human Values and Problem-Solving in an AI WorldSam Altman · OpenAIIn a short interview excerpt, Altman considers the enjoyment of solving hard problems and the human role in interpreting results.
 0:36ENMatthew Berman· 2026年10月25日Kimi K3.1 and a Rubik’s Cube Solver DemonstrationMatthew Berman · Forward FutureMatthew Berman shows a scrambled virtual cube being solved and gives the Kimi K3.1 test a favorable assessment.
 0:21ENMatthew Berman· 2026年10月24日An AI-Generated Kimi Benchmark Chart Used Invented ScoresMatthew Berman · Forward FutureMatthew Berman asks for a graph of Kimi K3.1 Pro benchmarks, then discovers that the displayed figures are illustrative placeholders.
 25:50ENMatthew Berman· 2026年10月24日Kimi K3.1 Pro Tested: Strong 3D Demos, Uneven Results and Competitive PricingMatthew Berman · Forward FutureMatthew Berman tests the open-weight model on coding, 3D rendering and visual explanations, then compares benchmark results and prices.
 32:20ENMatthew Berman· 2026年10月23日Who Is Local AI For? The Costs, Trade-offs and a Hybrid FutureMatthew Berman · Forward FutureMatthew Berman weighs data control and independence against hardware cost, setup complexity and inference speed.